English translation is being prepared.
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
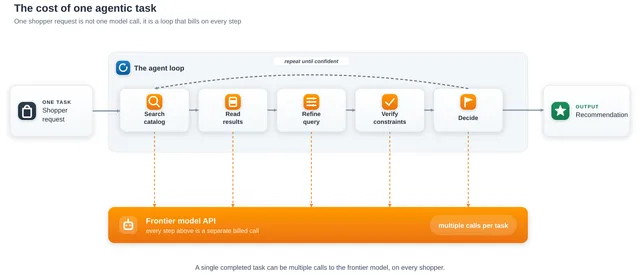
An AWS official blog post explains how to fine-tune a shopping agent on Amazon SageMaker AI using sequence-level knowledge distillation (SeqKD): using GLM-5.3 on Amazon Bedrock as the teacher model to generate trajectories, using the ShoppingBench scorer to retain only trajectories that solve the task, and then performing serverless SFT on the Qwen3.5-4B student model. On 324 held-out test questions, the distilled 4B student's average absolute success rate increased from 0.297 to 0.541, essentially on par with the teacher model and mid-sized frontier models; when the teacher's reasoning process was removed and only tool calls were learned, the average success rate dropped to 0.415.
An AWS official blog post explains how to fine-tune a shopping agent on Amazon SageMaker AI using sequence-level knowledge distillation (SeqKD): using GLM-5.3 on Amazon Bedrock as the teacher model to generate trajectories, using the ShoppingBench scorer to retain only trajectories that solve the task, and then performing serverless SFT on the Qwen3.5-4B student model. On 324 held-out test questions, the distilled 4B student's average absolute success rate increased from 0.297 to 0.541, essentia
Matched fieldsBody
Baseten Base Labs' toy experiments show that at the same number of steps, the PPO critic performs on par with or behind GRPO, while a "perfect critic" can eliminate at most 40-60% of the advantage variance. The authors argue that a value function is only worthwhile when the gradient noise it eliminates exceeds its training cost; the only scenario where it might help is with a small value head, but even then the gains are only marginal.

Matched fieldsBody
Arena analyzed 26,225 Agent sessions, 30 agents, and 13 labs from September 12 to October 23, 2026, and found that if billed at the full input price, the typical task cost for the top ten agents would be 3.6 times higher, and 592% higher on MiMo V2.6 Pro. For agents, 86% to 96% of tokens are repeatedly read context, while their own output accounts for only 1% to 2%. Cache invalidation increases the typical task cost by about 5%, and on Claude Fable 5.1, 1 in every 10 sessions sees an increase of more than 18%.
Arena analyzed 26,225 Agent sessions, 30 agents, and 13 labs from September 12 to October 23, 2026, and found that if billed at the full input price, the typical task cost for the top ten agents would be 3.6 times higher, and 592% higher on MiMo V2.6 Pro. For agents, 86% to 96% of tokens are repeatedly read context, while their own output accounts for only 1% to 2%. Cache invalidation increases the typical task cost by about 5%, and on Claude Fable 5.1, 1 in every 10 sessions sees an increase of
Matched fieldsBody
Anthropic's revenue in the second quarter of this year was 11.555 billion US dollars, achieving an operating profit of 974 million US dollars for the first time, with about 80% of revenue coming from pay-as-you-go billing. IDC data shows that in the first half of 2026, China's public cloud MaaS market revenue reached 10.63 billion yuan, up 889.4% year on year, and its share of public cloud PaaS revenue rose from 5.2% in the second half of last year to 21.0%. Zhipu's open platform and API revenue was 825 million yuan, accounting for 86.5% of total revenue; Volcano Engine ranked first with a 45.1% share. The article argues that model services can now generate gross profit, and the unit of competition has shifted to inference optimization and delivery capability.
Anthropic's revenue in the second quarter of this year was 11.555 billion US dollars, achieving an operating profit of 974 million US dollars for the first time, with about 80% of revenue coming from pay-as-you-go billing. IDC data shows that in the first half of 2026, China's public cloud MaaS market revenue reached 10.63 billion yuan, up 889.4% year on year, and its share of public cloud PaaS revenue rose from 5.2% in the second half of last year to 21.0%. Zhipu's open platform and API revenue
Matched fieldsBody
Latent Space host swyx introduces the curation approach for the annual flagship conference AIE CODE, which is single-track, invitation-only, and aimed at about 1,000 agent engineers. This year's three themes are Scaling without Slop, System One models, and Increasing Ambition, among which Jarred Sumner will share Bun's rewrite in Rust and a Bun AOT preview. The article also rounds up that day's AI news, including Mistral's open-weight release and OpenAI's frontier model monitoring.
Matched fieldsBody
The author used Cursor together with Claude Opus 5.5 to build a zero-dependency local web tool called "EQ plugin," which rewrites emotionally charged drafts according to the four elements of Nonviolent Communication, and includes seven types of communication targets and three tone levels: gentle, firm, and direct. The tool runs on the local machine at 127.0.0.1:8787, and the UUMit client generates a fixed HTTPS link to distribute to colleagues, with no need to buy a server or file for registration, and permissions can be granted and revoked per person. The article also provides an 800-character limit per input, default rate limits of 10 times per minute and 200 times per day, as well as the source code and System Prompt for two GitHub repositories.
The author used Cursor together with Claude Opus 5.5 to build a zero-dependency local web tool called "EQ plugin," which rewrites emotionally charged drafts according to the four elements of Nonviolent Communication, and includes seven types of communication targets and three tone levels: gentle, firm, and direct. The tool runs on the local machine at 127.0.0.1:8787, and the UUMit client generates a fixed HTTPS link to distribute to colleagues, with no need to buy a server or file for registrati
Matched fieldsBody
Tencent, Tencent Cloud, and WorkBuddy have jointly released the 78-page "2026 AI Agent Enterprise Solutions and Implementation Practice Handbook," which uses WorkBuddy as the entry point to advance personal assistants into "digital employees" that enter business systems, with ClawPro, Agent Runtime, and TokenHub responsible for provisioning, isolation, models, and governance. The handbook proposes a three-stage framework of "able to converse → able to work → able to take a post," and presents case data including Yozoo's Agent penetration rate exceeding 75%, Youka's MTTR of 5–15 minutes, and operations and maintenance costs of approximately -40% (all as self-reported in the text).
Tencent, Tencent Cloud, and WorkBuddy have jointly released the 78-page "2026 AI Agent Enterprise Solutions and Implementation Practice Handbook," which uses WorkBuddy as the entry point to advance personal assistants into "digital employees" that enter business systems, with ClawPro, Agent Runtime, and TokenHub responsible for provisioning, isolation, models, and governance. The handbook proposes a three-stage framework of "able to converse → able to work → able to take a post," and presents ca
Matched fieldsBody
Mistral AI updated and opened the weights of its flagship model Mistral Large 4, with 1.05T total parameters and 52B activated parameters. It scores 26 on the Artificial Analysis Intelligence Index v5, 1 point higher than the Preview version, and leads the US open-source model Muse Spark Open (25) by 1 point. The model outputs 82K tokens per task, 39% fewer than the Preview's 135K, and its hallucination rate on AA-Omniscience v1.1 dropped from 41% to 28%, though accuracy remains 26%. Pricing is $0.70/$2.10 per 1M input/output tokens, about 50% lower than the Preview, under the MEOW license; operating a Model-as-a-Service business requires a separate commercial license.
Mistral AI updated and opened the weights of its flagship model Mistral Large 4, with 1.05T total parameters and 52B activated parameters. It scores 26 on the Artificial Analysis Intelligence Index v5, 1 point higher than the Preview version, and leads the US open-source model Muse Spark Open (25) by 1 point. The model outputs 82K tokens per task, 39% fewer than the Preview's 135K, and its hallucination rate on AA-Omniscience v1.1 dropped from 41% to 28%, though accuracy remains 26%. Pricing is
Matched fieldsBody
At the 2026 Tencent Global Digital Ecosystem Summit, Tencent Cloud announced upgrades to four core capabilities of its WorkBuddy enterprise-grade service, including open platform capabilities, enterprise-grade security solutions, an observability center, and WorkBuddy Managed Agent (WMA), with the underlying Agent Runtime upgraded as well. After the upgrade, WorkBuddy can connect to WeCom, Tencent Docs, and systems such as ERP and CRM through MCP and connectors; in addition to Hunyuan, it also supports third-party open-source models and enterprise self-deployed models. Wang Huixing revealed that since its launch in March this year, WorkBuddy has cumulatively completed 9 billion user task requests, with Token consumption growing 50-fold compared with the initial launch; Liu Yi said that in 2027 the focus will be on strengthening Agent proactivity.
At the 2026 Tencent Global Digital Ecosystem Summit, Tencent Cloud announced upgrades to four core capabilities of its WorkBuddy enterprise-grade service, including open platform capabilities, enterprise-grade security solutions, an observability center, and WorkBuddy Managed Agent (WMA), with the underlying Agent Runtime upgraded as well. After the upgrade, WorkBuddy can connect to WeCom, Tencent Docs, and systems such as ERP and CRM through MCP and connectors; in addition to Hunyuan, it also s
Matched fieldsBody
Dowson Tong, Senior Executive Vice President of Tencent Group, announced at the 2026 Tencent Global Digital Ecosystem Summit that the official version of the Hunyuan large model Hy4 will be released soon. Compared with the Hy4 Preview open-sourced on August 28, it is comprehensively upgraded, strengthens long-horizon tasks and real productivity task capabilities, significantly improves chain-of-thought efficiency, and adds visual understanding for the first time; Hy4 Flash, which focuses on cost-effectiveness, will also be launched soon. Tencent also released the cross-application AI collaboration system Buddy One and Tencent Drive for the Agent era, and upgraded Agent Runtime, making systematic enhancements around context management, tool calling, secure sandboxes, observability, and evaluation. Dowson Tong also disclosed that over the past year, the number of active overseas customers of Tencent Cloud grew about threefold, and overseas AI demand achieved triple-digit growth.
Dowson Tong, Senior Executive Vice President of Tencent Group, announced at the 2026 Tencent Global Digital Ecosystem Summit that the official version of the Hunyuan large model Hy4 will be released soon. Compared with the Hy4 Preview open-sourced on August 28, it is comprehensively upgraded, strengthens long-horizon tasks and real productivity task capabilities, significantly improves chain-of-thought efficiency, and adds visual understanding for the first time; Hy4 Flash, which focuses on cost
Matched fieldsBody
Iluvatar CoreX held the first live demonstration of its general-purpose GPU TianGai 300 and the on-device compute terminal TY1200, and previewed the next-generation on-device product TY2000 with a nominal compute of 600T. The TianGai 300 has 144GB of memory, delivering Attention performance 1.05 times that of the H200 under a 64K long context and MoE throughput 1.15 times that of the H200 on the GLM-5.3 model; the TY1200 offers 300 TOPS INT8 dense compute, with measured TPS surpassing NVIDIA's Thor T5000. The TianGai 300 IXL144 supernode integrates 144 GPUs in a single rack and aggregates about 10.1TB of memory, reducing the cost per million effective tokens by about 40% compared with mainstream international solutions.
Iluvatar CoreX held the first live demonstration of its general-purpose GPU TianGai 300 and the on-device compute terminal TY1200, and previewed the next-generation on-device product TY2000 with a nominal compute of 600T. The TianGai 300 has 144GB of memory, delivering Attention performance 1.05 times that of the H200 under a 64K long context and MoE throughput 1.15 times that of the H200 on the GLM-5.3 model; the TY1200 offers 300 TOPS INT8 dense compute, with measured TPS surpassing NVIDIA's T
Matched fieldsBody