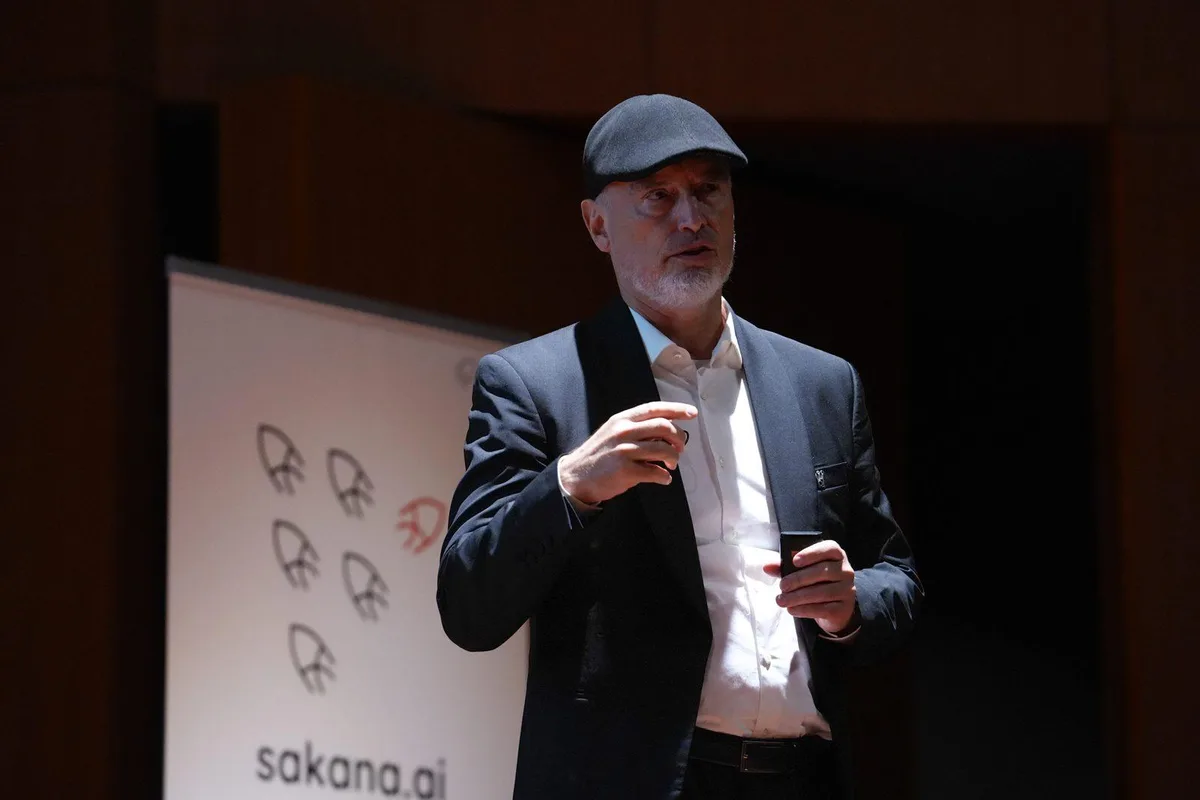
Professor Jürgen Schmidhuber, Chief Scientific Advisor of Sakana AI, delivering the keynote lecture more
On October 26, 2026, Sakana AI held the symposium "From World Models to Real-World AI — A New Era of AI Pioneered from Japan" at Hitotsubashi Hall in Tokyo. In September,we welcomed him as Chief Scientific AdvisorProfessor Jürgen Schmidhuber is a researcher who, since the 1980s, has pioneered numerous ideas that form the foundation of today's deep learning and generative AI, including the first Transformer (a linear Transformer without normalization), pretraining and distillation of deep neural networks, modern world models, artificial curiosity through generative and adversarial networks, and recursive self-improvement. He is also a co-author of the 1997 LSTM paper, which became the most-cited AI paper of the 20th century. More than 400 people from across Japan attended the professor's keynote lecture and his dialogue with co-founder and CEO David Ha, who co-authored the 2018 paper "World Models" with the professor.
At this symposium, Sakana AI revealed that it will embark on the development of its own pretrained models. Chief Scientist Takuya Akiba announced "Sakana Sawara (tentative name)," a language model series to be developed in-house from the pretraining stage. The first model, a small-scale "Sawara Small (tentative name)," is scheduled for release in spring 2027 if all goes smoothly.
This symposium was planned to convey Sakana AI's enthusiasm in welcoming Professor Schmidhuber and to serve as a starting point for opening up the next era of AI together with companies and research institutions across Japan. In this article, we present the content of each lecture and dialogue in the form of a transcript (excerpted and partially reordered for readability).
Table of Contents
- Opening: From World Models to Real-World AI: David Ha
- Keynote Lecture: Jürgen Schmidhuber
- LLM Development at the RSI Lab: Takuya Akiba
- Towards Open-Ended Autonomous Discovery Systems:Robert Tjarko Lange
- World Models & Physical AI:Stefania Druga/Sebastian Risi
- Dialogue: David Ha × Jürgen Schmidhuber
- Closing
Chieko Tazuke, Chief of Staff of Sakana AI, who served as moderator
Opening: From World Models to Real-World AI: David Ha
First, co-founder and CEO David Ha took the stage.
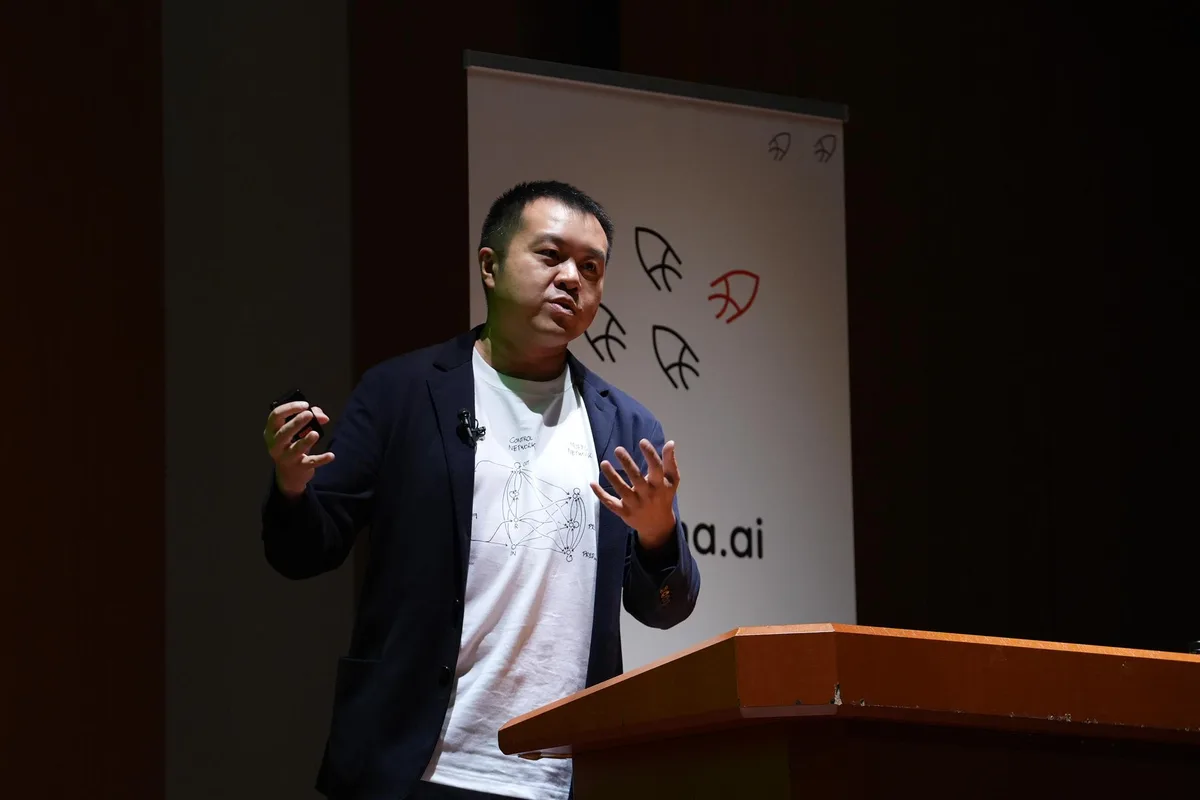
David Ha, CEO of Sakana AI
Intelligence arises from constraints
The T-shirt I'm wearing today has a diagram of a world model printed on it. Professor Schmidhuber drew it in 1990. At the time, the cost of computation was 1 million to 1 billion times higher than it is now, and figures in papers were drawn by hand and pasted in. Now we've reached an era where AI scientists write papers together with us, but I think it's good to occasionally remember that the innovations of the 1980s and 90s are connected to today.
One of the opinions I often express on social media is that "foundation models are one of the financial assets that lose value fastest in human history." For me, having started a company that builds AI models, this is a troubling problem. How should Japan fight the world in this field?
My belief is that the only path is not to keep making models larger by pouring in massive amounts of computational resources and data. Intelligence arises from constraints. Today's AI is scaling through abundance, but biological intelligence was born from scarcity. Evolution selects those that do more with fewer resources. Brains, language, and culture are all proof that constraints give rise to intelligence.
About 10 years ago, I became absorbed in AI research and took on many difficult challenges in OpenAI Gym. In the task of a bipedal walking robot, I tried imposing constraints so as to minimize not only the neural network but also the robot's body size and the energy it uses. As a result, the AI produced a small robot that walks like an insect. So what happens if you remove the constraints entirely? What the AI found was a giant robot with no brain that simply falls toward the goal. For AI to have a brain, constraints are necessary.
Encounter with Professor Schmidhuber's papers
In the car racing task of driving a car from pixels, I gave the agent a world model. I made it able to predict what would happen in the future and represent the world in a latent space.
What I did then was, as Jürgen always says, to go back through past research. That is where I encountered the professor's series of papers on world models, from the 1990 paper that made the world differentiable to the 2015 paper "On Learning to Think." Many concepts, from algorithmic information theory to artificial curiosity, were brought together there, and I was very inspired. I also learned there the idea of thinking of an agent as divided into a controller (C) and a world model (M).
After that, what I wrote jointly with Jürgen was the paper "World Models," presented at NeurIPS. In this paper, we showed that an agent can learn inside the "dream" seen by a world model. Such ideas now form the foundation of many innovations, including autonomous driving and robotics.
Sakana AI's research and Japan's AI sovereignty
In 2023, I founded Sakana AI together with Llion Jones and Ren Ito. Sakana means fish in Japanese. Intelligence is not in a single fish, but in the school. That is how we think, and we take a collective intelligence approach. And as a Japanese company with limited resources, we do not want to do the same things as other companies. We want to be a red fish that swims in a slightly different direction from the school.
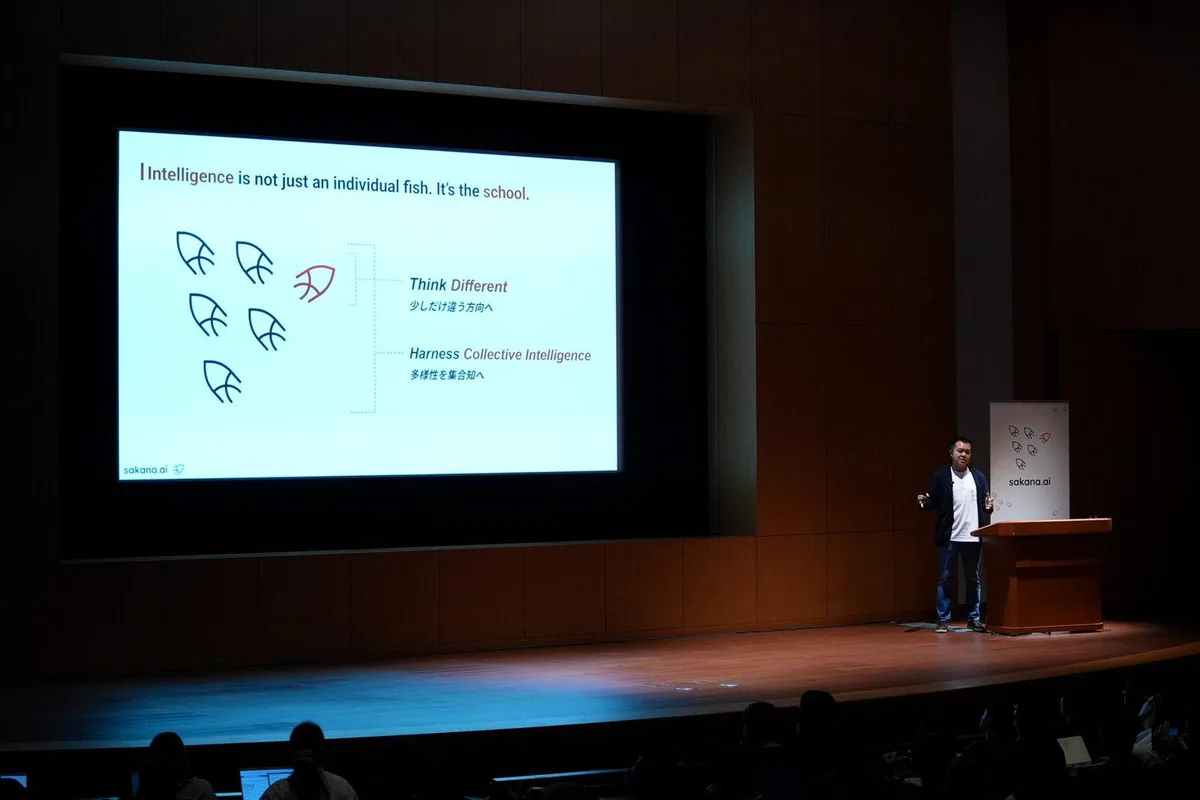
“Intelligence is not in a single fish, but in the school,” says David.
brain-inspiredContinuous Thought Machineslearning a 1,000-layer network without using backpropagationPC-ALMand this yearAn AI scientist published in Natureand implemented Professor Schmidhuber's Gödel machine idea with LLMsthe Darwin Gödel Machineand other research.
So how will Japan build AI amid global competition? I think about Japan's AI sovereignty in terms of three pillars. The first is "pre-training," which enables building technology from scratch; the second is "post-training," which aligns AI with Japanese values; and the third is "orchestration," which combines the world's frontier models with our own models to draw out performance. In orchestration,Sakana Fuguand in post-trainingSakana Namazuis provided.
And the final pillar is pre-training. We will begin working on pre-training our own models. Chief Scientist Takuya Akiba will talk about the details later.
What we are envisioning is a plan to pre-train agent-native language models and world models, have them collaborate with one another to tackle difficult tasks, and refine the models through a self-improvement loop driven by an AI scientist. This plan does not differ greatly from the controller and world model configuration in Jürgen's paper. By combining the technologies available today, we can build on past excellent ideas and push the frontier forward.
Keynote Lecture: Jürgen Schmidhuber
Next, Professor Jürgen Schmidhuber gave the keynote lecture.
Neural networks were born 230 years ago
I am very proud that David came wearing a T-shirt with a diagram I drew in 1990.
Modern AI is based on artificial neural networks. The brain has about 100 billion neurons, each with an average of around 10,000 connections. The strength of the connections is initially random, but through learning they become stronger or weaker. In this way, it becomes able to do various things, such as driving a car or translating.
So who invented the artificial neural network? Some people think it was someone in America around 1940, but that is completely wrong. It was invented 230 years ago, between 1795 and 1805. In 1795, Gauss had exactly the same mechanism as what came to be called a "two-layer linear neural network" in the 1990s: adjusting the weights connecting inputs and outputs to minimize the squared error on the training data. At the time, it was called the "method of least squares." The first to publish it was Legendre, in 1805. The core of what famous companies are working on today is the same as this Gauss–Legendre network. The main difference is that today's networks are deeper.
Incidentally, the young Gauss became famous in 1801, when he predicted the position of the asteroid Ceres. Ceres disappeared behind the Sun during observations—where would it appear next? Gauss predicted the "next token" with this method, and hit it perfectly.
The origins of deep learning born in Japan
So who invented deep learning, and where? It began in 1965 in Ukraine, then part of the Soviet Union, with Ivakhnenko and Lapa. In Ivakhnenko's 1971 paper, an 8-layer network predicts the next value from time-series data on the British economy.
In 1967, Shunichi Amari of Japan demonstrated end-to-end deep learning, in which the whole network is trained at once rather than layer by layer—a five-layer network at a time when computation was billions of times more expensive than it is today. In 1970, Linnainmaa of Finland published backpropagation, which is now used everywhere from Google to Sakana AI.
Another major contribution from Japan was the first convolutional neural network, the Neocognitron, created by Kunihiko Fukushima in 1979. In 1986, there is a famous video of it being applied to handwritten digit recognition. In 1988, Wei Zhang, who was in a Japanese laboratory, combined Fukushima's convolutional network with backpropagation and applied it to character recognition. Zhang further scaled this up in the 1990s. The convolutional neural network, the core of today's computer vision, was invented in Japan, and then further developed and scaled there.
Since I came all the way to Japan, I wanted to introduce the essential developments that have taken place in this country in the evolution of modern AI.
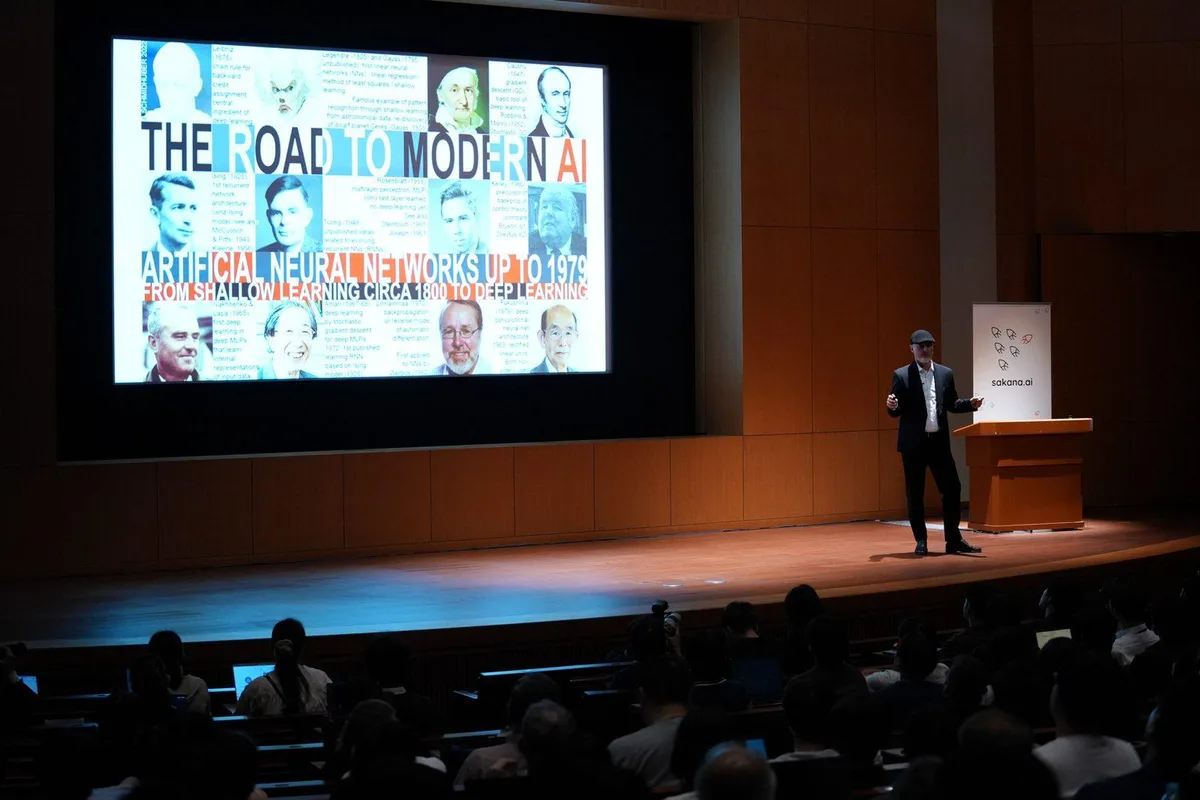
Tracing the origins of modern AI from Gauss to Kunihiko Fukushima, Jürgen
The 1990 World Model and Artificial Curiosity
Our own contribution to neural networks comes later, beginning with this diagram from 1990. There is a small robot and a control network that drives it. Among the inputs is one labeled "R." That is reward. The robot has pain sensors and receives an evaluation of its own actions as input.
This is an essential element of what is now called "recursive self-improvement (RSI)." RSI refers to a system that learns recursively—not only learning something, but improving how it learns, and then improving how it improves, and so on. To do this, evaluation signals from the environment must be fed into the network. That was already present in this diagram.
To this, we add a second network: a network that observes the robot's actions and inputs and predicts what will happen next—in other words, a world model. With a good model, you can make plans. You can try out actions in your head and choose the ones that are predicted to yield high reward and little pain.
But at first, the model knows nothing. So an "artificial scientist" is needed who comes up with experiments on its own. Babies do not download the World Wide Web to learn. When they move their hands, the images that enter their eyes change. While predicting those changes, they learn physics, they learn that apples fall, and they learn how their parents react when they cry. Through their own experiments, they select and gather the data they need.
In the simplest method I published in 1990, the world model tries to minimize the error, while the generative controller tries to maximize that same error. When the model finds places where there is still room to learn, the controller gets a reward. It is a "Eureka" reward for having devised an experiment that teaches it something it did not know about the world. Many people have implemented variants of this, and it is now called a generative adversarial network (GAN), but I called it "artificial curiosity."
In 1991, the "miracle year,"
But at the time, deep learning still didn't work well. It could not handle long time lags, where events thousands of steps earlier affect things thousands of steps later.
So in 1991, we wrote a series of papers to solve this problem. Their results connect to the "P" and "T" in today's ChatGPT. A method that compresses long sequences through pretraining to "predict the next thing." Distillation, also shown in the same paper, which transfers the knowledge of one network to another. And the first variant of the Transformer. I called it the "Fast Weight Controller," but it is exactly what is now called a linear Transformer. In 2020 it came to be called the "linear Transformer." Because it is linear, its computational cost grows only in proportion to the length of the text. With today's Transformer, whose computational cost grows quadratically, when the text becomes 1,000 times longer, the computation requires 1 million times more. This is one reason why massive investment in data centers is needed.
In that same year, 1991, my outstanding student Sepp Hochreiter demonstrated the principle of deep residual learning in his graduation thesis. Consider a very simple unit with a linear activation function and a self-connection weight of 1.0. Even when the error is propagated back through time, it is always simply multiplied by 1.0, so nothing changes no matter how many thousands of steps pass. This is what makes very deep learning via gradient descent possible, and it is the core of LSTM. This later led to the first deep residual feedforward network, which we published in May 2015 as the "Highway Network," and subsequently to "ResNet."
In 1991, no one was interested in this kind of research. When I presented it at an academic conference, the audience consisted of just one young woman. I said, "Miss, this is awkward, but it looks like today I'll be speaking only to you," and she replied, "That's fine. But please hurry—I'm the next speaker." Even so, computers have become ten times cheaper every five years, and today they are ten million times cheaper than they were then. That is precisely why the technology we presented back then is now running inside everyone's smartphones.
A plan that does not simulate the details
What David showed in his slides is a method for better planning. Naive planning uses a world model to simulate the future millisecond by millisecond. That is sufficient for chess and Go, but it is not what we should really be doing.
When planning a trip to Paris from here, nobody simulates down to the movement of the hand reaching for the phone. Call a taxi, go to the airport, check in. We make a compact plan that captures only a few key points.
What I proposed in 2015 was a method in which a controller sends queries to the hidden units of a world model (M). M may have watched every YouTube video, or it may have a huge amount of robot experience. The controller is a prompt engineer that learns. It focuses attention only on the internal representations relevant to the problem it is currently trying to solve, draws answers out of them, and changes its own behavior accordingly. Those queries are not in English or Japanese; they are sequences of numerical vectors. For simple problems, it is probably faster to solve them from scratch. But every interesting problem should benefit greatly from the algorithmic information sleeping deep inside a huge model. In 2018, I also wrote a paper that used distillation to combine the controller and the model into one. That said, the more famous 2018 paper is David's, which demonstrated through brilliant experiments that world models are actually useful.
to the AI beyond the screen
Now, let us turn our attention to a somewhat broader historical context. Much of what we discussed today took place in Germany and Japan.
In 1990, Japan looked like a country of the future. The six most valuable companies in the world were all Japanese companies. In 1995, Japan and Germany's nominal GDP combined was almost on par with the combined total of the United States and China. And as of 2002, more than half of the world's robots were made in Japan, with Germany having the second-largest number.
The AI that is truly working well right now is only the AI on the other side of the screen. Beyond the screen there are superhuman chess players, Go players, and mathematicians. However, there are still no robots that can approach the work of plumbers or electricians. They cannot even come close to what a little boy playing with a soccer ball can do.
Real-world Physical AI does not yet belong to anyone. Now, the path toward robots that can master any existing tool or machine through demonstration and reinforcement learning is beginning to come into view. If such robots are realized, the ultimate scaling will become possible, with machines reproducing themselves. What matters then is not how many people a country has, but whether it possesses such machines. I hope that countries strong in robotics, like Japan and Germany, will lead the way and regain their former brilliance.
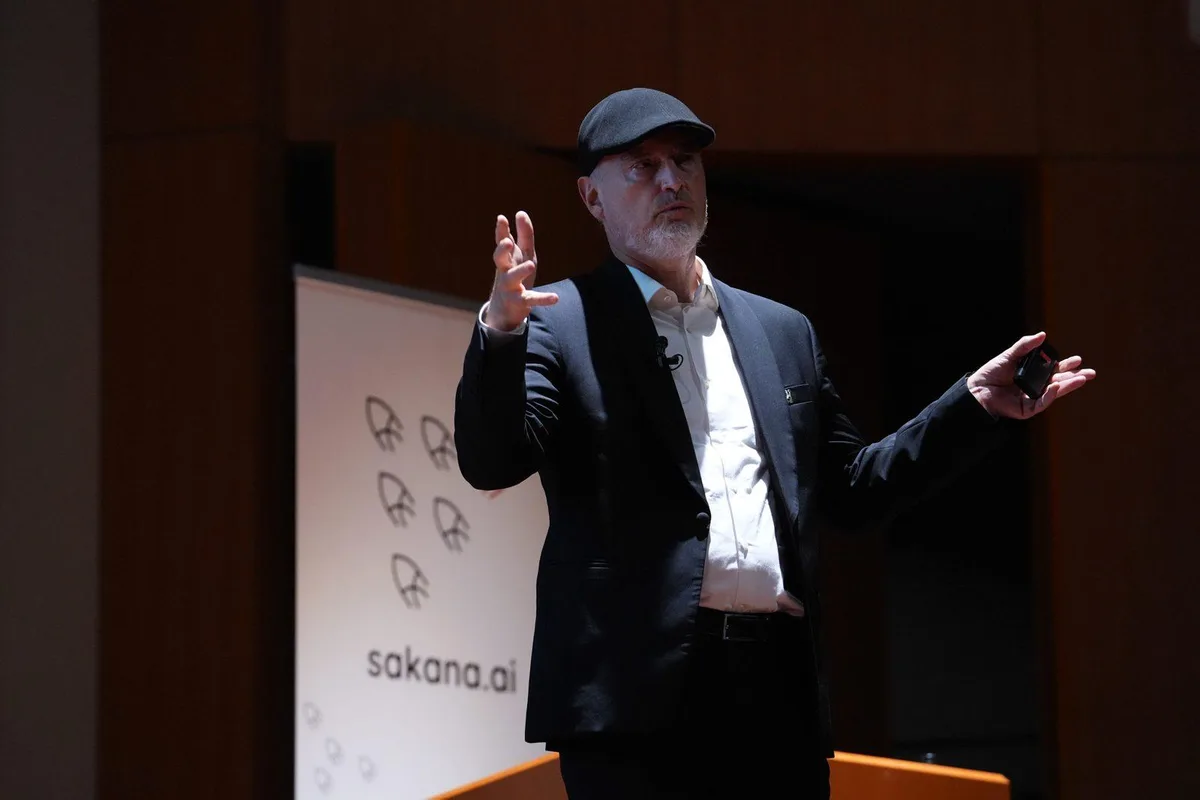
Jürgen speaking about the possibilities of Physical AI
The future is bright.
The current trend favors small players, not large corporations. Forty years ago, an wealthy acquaintance of mine had a car phone installed in his Porsche and talked via satellite with people riding in similar cars. It was extremely expensive. Today, everyone around the world has a smartphone far superior to that.
AI is the same. Every five years the price drops to one-tenth, and its physical limits are far off. Everyone will have many AIs, and those AIs will make people's lives longer, happier, and healthier. The future is bright.
LLM Development at the RSI Lab: Takuya Akiba
After a break, the second half featured three talks by researchers from RSI Lab. First, Takuya Akiba, the Chief Scientist leading the LLM team, took the stage.
Takuya Akiba, Chief Scientist of Sakana AI
From the agent layer to the model layer
Sakana AI was founded in 2023, and I joined as one of its earliest members. We have worked on a variety of things so far, but one of the central ones was the "agent layer." This is research that assumes powerful models exist and uses them to do interesting things.
One isALE-AgentIt is an agent that discovers difficult combinatorial optimization algorithms, and it has participated in real competitive programming contests in real time several times, beating human experts andWe won.The other isAB-MCTSIt is a general-purpose algorithm for inference-time scaling that repeatedly calls language models to solve difficult problems, and it has been adopted in multiple actual projects at Sakana AI.
Research on the agent layer has been very enjoyable, and we have produced results. But recently I feel that the model layer has become attractive again. Recent open models are very strong, approaching frontier models, and are now sufficiently usable in practice. Data, training recipes, and software have become easier to obtain, and the cost of building models is also falling.
And perhaps most importantly, specialization at the model layer has become a viable option. Agentic reinforcement learning enables additional training that optimizes models end-to-end for one's own tools, operations, and scaffolds. Such specialized models can sometimes outperform general-purpose models.
This year, weSakana NamazuWe have released it. It is a model post-trained primarily for Japanese users, based on an overseas open model. We reduced geopolitical biases and other issues, deepened its understanding of Japanese culture, and instilled in it communication styles and ways of thinking that feel comfortable to Japanese users.
And this summer, we launched RSI Lab. RSI Lab has three teams: the language model team, the world model team, and the RSI research team. I am in charge of the language model team.
Sakana Sawara (tentative name)
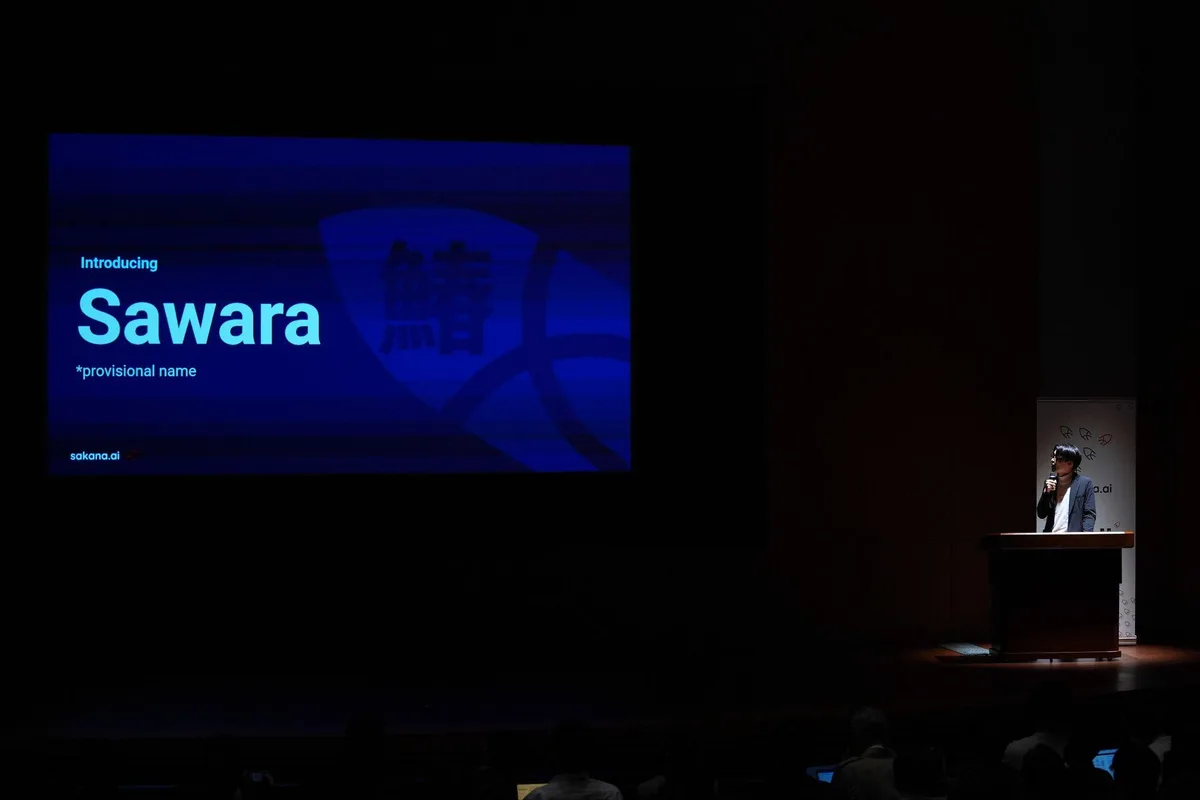
Takuya Akiba announces the new language model series "Sakana Sawara (tentative name)"
So what will RSI Lab tackle next? What we're introducing today is a new language model series, "Sakana Sawara." Please note that this is still a provisional name.
Sawara is a language model we are building from scratch. Until now, Namazu has focused on post-training existing open models, but with Sawara we are expanding our efforts to pre-training as well. Because it is not based on another model, we can manage everything about the model ourselves, including the training data and training methods. In addition, we have designed it from the start for agentic uses such as tool-based reasoning, coding, and long-running tasks. We call this an "agent-native" language model.
Sawara has two roles. One is to serve as the foundation for Sakana AI's products and solutions. The other is to serve as the foundation for RSI research. Being able to grasp everything about the models and recipes, and having every process transparent to us, enables a broader scope of RSI research.
Unfortunately, Sawara is still under development, and there is not much we can share today. So today, I will talk about how I think about language model development and our strategy for it.
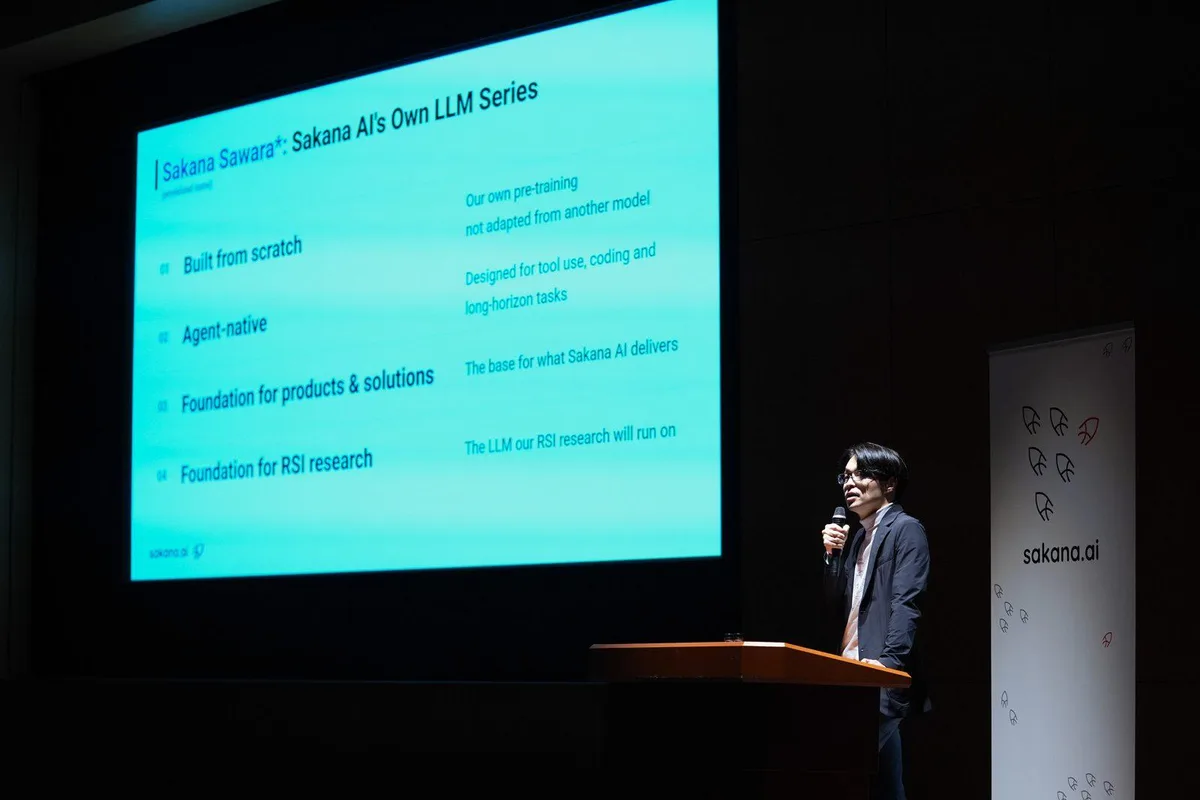
Sawara's four key features
Language model development is a "competition of research"
Many of you would agree that this competition is a competition to use more GPUs. That is 100% correct. However, GPUs are often thought to be needed mainly for "scale"—that is, for increasing the number of parameters or the number of pretraining tokens.
Actually, this is a misunderstanding.Epoch AI's analysisAccording to Epoch AI's analysis, in many organizations, the computational resources used for final training are only a tiny fraction of the total. For example, at OpenAI, it is estimated that final training accounts for about 10% of the computational resources used for R&D. The vast majority of computational resources are used for trial and error—that is, for research. Language model development can be said to be a "competition of research" more than you might imagine.
So what is the key to the research competition? I believe that progress in language models is the product of "computational resources" and "research efficiency." Computational resources are simple. The more GPUs you have, the more experiments you can run. The other factor, research efficiency, tends to be underestimated, but it is just as important. That is because the result is determined by the product of the two. Research efficiency means how much you can get out of, and learn from, a single experiment. From my experience over the past decade, I feel that there are huge differences between researchers here. There are people who can design good experiments and choose the experiments that will yield as much information as possible.
Talent density and large-scale AI tokens
So what is it that now determines a team's research capability? I believe it is "talent density" and "large-scale use of AI." It is now 2026, not 2023. Since we announced our AI Scientist in 2024, many groups have followed in this field. Everyone would now agree that research is a collaboration between humans and AI. And now, we value talent density over headcount. I have confidence in my team. Because it is the team with the highest talent density I have seen so far.
Interestingly, this idea leads directly to RSI. We already use AI, but it is probably not our own model. But next, part of that AI might be Sawara. And the next version of Sawara might be developed with Sawara's help. Depending on how you define RSI, I would like to call this "partial RSI." In the future, we aim for Sawara to handle more of this process.
Roadmap
Finally, here is the development roadmap. We are currently preparing for training, and this December we will begin pretraining Sawara Small (tentative name). If all goes smoothly, we plan to release the weights next spring. After that, we also plan to develop the larger-scale Sawara Large (tentative name).
Towards Open-Ended Autonomous Discovery Systems:Robert Tjarko Lange
Next, Robert Tjarko Lange, a Staff Research Scientist from the RSI team, took the stage.
Robert Tjarko Lange, Staff Research Scientist
AI Scientists So Far
When I began my career as a scientist, one of the things that greatly inspired me was Jürgen's doctoral thesis. It was a thesis about genetic algorithms that recursively improve themselves. That is where I began my research on meta-learning. Now, in 2026, we have at our disposal a far more powerful "mutation operator"—large language models—and we have become able to verify hypotheses autonomously.
Scientific progress is what underpins society's prosperity. However, until now, research has been conducted by humans alone, without the help of AI. So in 2024, around the time language models became able to follow instructions, weAI Scientist v1We began developing it. It is a blueprint for automating the entire research process with agents—from idea generation to novelty checks, experiments, paper writing, and peer review.
In v2 a year later, we used tree search to assemble each stage of the research. And an AI-generated paper was [accepted] at a workshop of an international machine learning conference.It passed human peer review.This experiment was conducted after obtaining prior ethics review approval and in collaboration with the workshop organizers. We always value respecting the scientific process and maintaining integrity.
And the latest v3 is also called the Agentic Scientist. It can operate fully autonomously, but it is designed with an emphasis on "co-discovery," refining hypotheses together with humans. It also has mechanisms for verifying all claims and reducing reward hacking. The paper we wrote using v3 was submitted after we had verified all of its claims, and it was accepted to the main conference of ALIFE 2026.
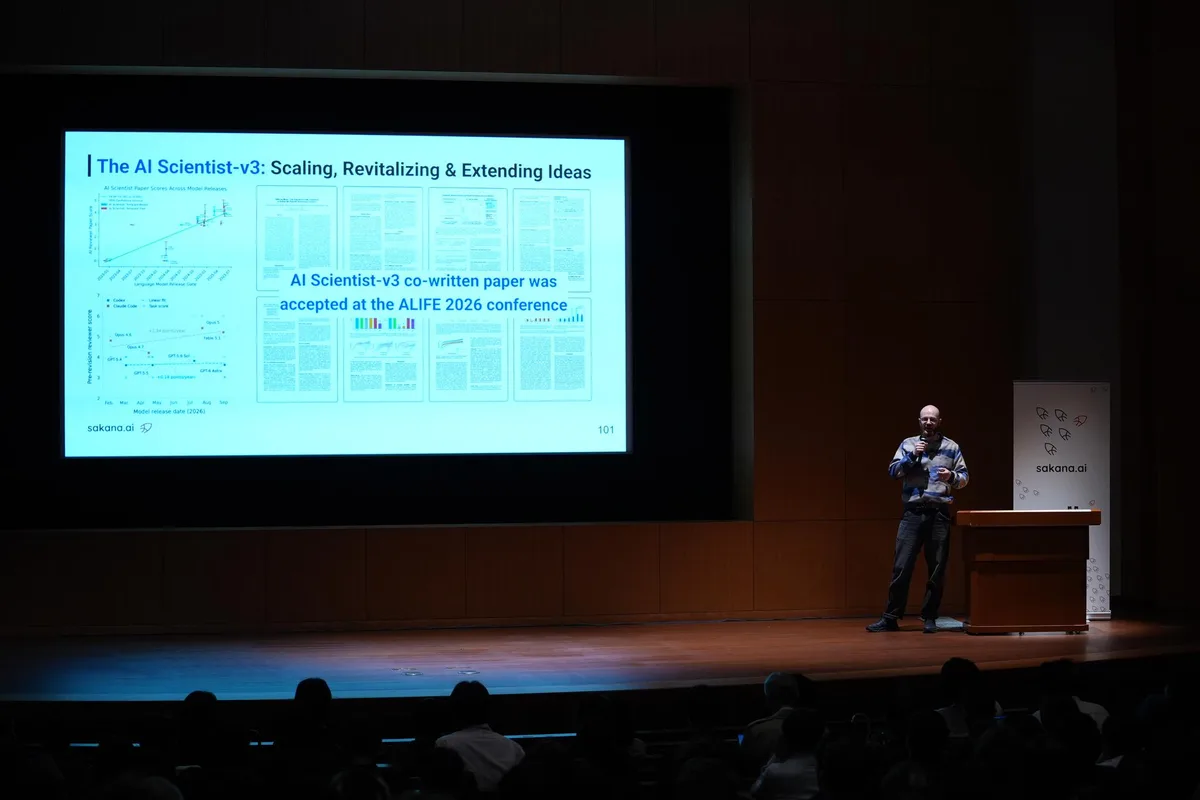
Robert discusses the history of AI scientists
Broadening the range of ideas
So what comes next? The current automated research systems are, so to speak, "hyperparameter tuning on steroids." They can rewrite code, but the range of ideas is different from human research. We believe we need to steer these systems not just to climb benchmarks, but to approach research in more diverse ways.
The clue lies within Sakana AI's own organization.Frontier Intelligence Group(FIG)At FIG, researchers pursue interesting hypotheses in an open-ended way, without being bound by short-term goals. How can we create an AI scientist with this spirit that is not biased toward mountain climbing? That is our question.
Human scientists include biologists, economists, and philosophers. To advance science as a whole, we need AI scientists that adapt to each field, acquire their own expertise, and improve themselves. Furthermore, 80% of my own research is trial and error, and much of that never makes it into the final paper. Records of such trial and error in scientific research are hardly included in LLM training data. We need to think explicitly about how to instill in AI the scientific method itself, such as Karl Popper's falsificationism.
And science is, by its very nature, not the work of a single genius but an endeavor carried forward by many people gathered together. How do we create a world in which AI scientists collaborate as a collective, with humans joining in as well? How to allocate resources and credit for scientific achievements, and how to judge the meaning of contributions—these become technical questions.
Finally, safety is extremely important. However, I believe the solution is not to halt AI progress, but to use AI to develop AI safely. For example, if we use AI scientists for mechanistic interpretability and monitoring of chains of thought, we should not only obtain better systems but also gain a deeper understanding of those systems.
World Models & Physical AI:Stefania Druga/Sebastian Risi
The third talk was given by Stefania Druga and Sebastian Risi, on the theme of world models and Physical AI.
Sebastian Risi (left) and Stefania Druga (right)
Why Physical AI in Japan (Stefania)
We are excited to conduct this research in Japan because Japan has strengths in robotics and Physical AI. At the same time, Japan also faces a major challenge: three in ten people are 65 or older. It is a problem and at the same time an opportunity. If we combine Japan's hardware strengths with the current learning capabilities of AI, we should be able to create applications for the people who need them most.
Test it with a world model before trying it on the real robot (Sebastian)
Robot learning has made great progress over the past decade. Even so, there are no robots in the home, and as Jürgen says, there are still no robot plumbers or electricians. I believe the reason for this lies in two gaps: "speed" and "safety." Using a large LLM makes inference slow, and it takes time to finish a task. Also, even when a task succeeds, 18–28% of the time it is not acting as instructed.
To close this gap, what Sakana AI is betting on is the world model. Before acting in the real world, it verifies actions in a world model. And it accepts improvements only when there is physical evidence from the real machine. For robots, trials in the real world are extremely costly. That is precisely why a world model that lets them imagine the future is needed.
In our concept, a small, fast-inference vision-language model (VLM) proposes action plans. The world model receives that plan, predicts the state several steps ahead, judges whether it is feasible and what the causes of failure would be, and evaluates how much closer it gets to the goal. We screen many plans with the world model and try only the few that remain on the real robot. We then use those results to improve the VLM.
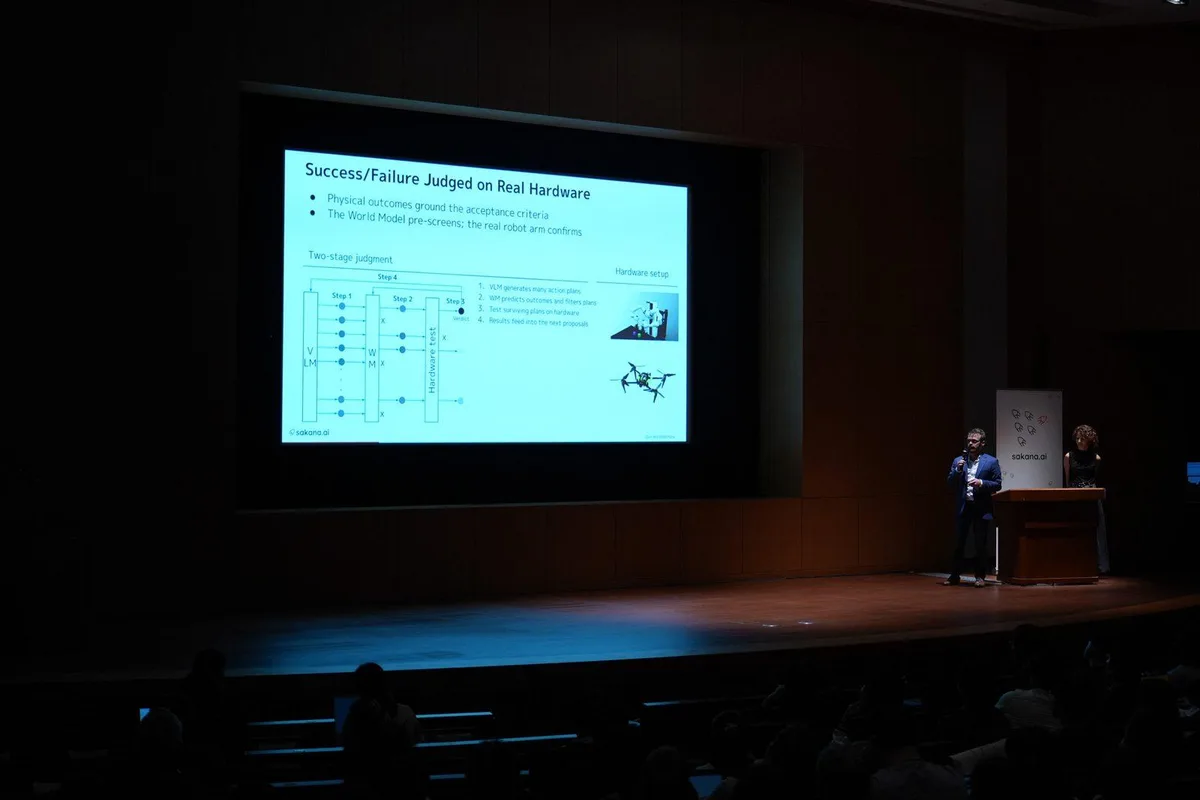
Sebastian Risi explains the improvement loop that combines world models with real machines
However, what we are aiming for is not mere self-improvement, but recursive self-improvement in which "the very way improvement is done keeps improving." By connecting Agentic Scientist with the agent-native language models we are currently developing, as well as with Physical AI, Agentic Scientist will improve the world model itself. We feed what we obtain from the real world back into Agentic Scientist, closing the loop. To prevent reward hacking, we have established strict criteria, such as whether improvement is reproducible even after repeated evaluation, whether there is statistical backing, and whether improvement occurs even on unknown tasks. In addition, using the collective intelligence that is part of Sakana AI's DNA,Research to make RSI more effective and saferWe are also advancing this.
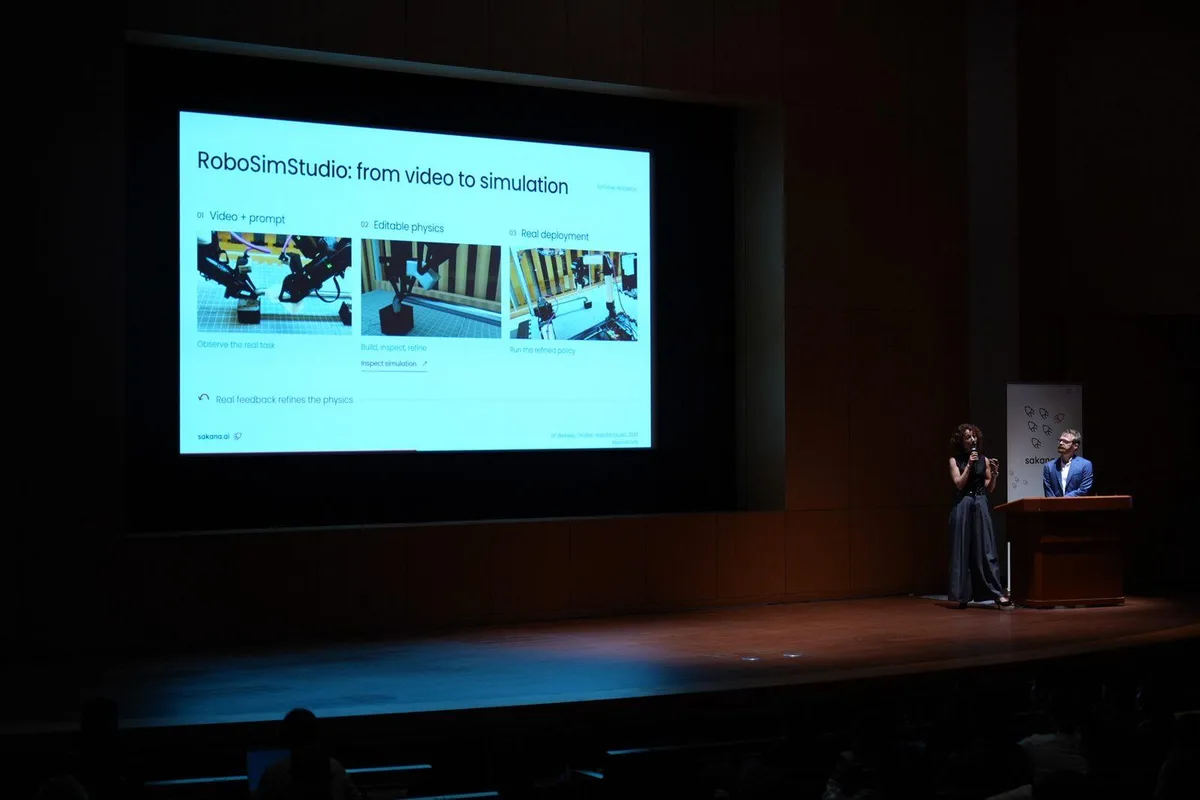
Stefania Druga, who introduces efforts in world models and Physical AI
From early experiments (Stefania)
A world model predicts what will happen next, and experiments tell us what actually happens. We want to learn recursively while closing the gap between the two.
The first example is an experiment conducted with a Franka robot in simulation, in collaboration with the AI Robot Association (AIRoA). The policy model fine-tuned from π0.5 was initially unable to open drawers or place objects inside them. By repeatedly showing the controller examples of failures, we made repeated improvements, and it became able to succeed at these tasks. Next, we will check whether the improved policy also works on the real robot.
Furthermore, we have begun research on robots that change their own form according to the task. We create a simulation from footage of the real machine, use the simulation to explore quickly, cheaply, and safely, test the discovered controller on the real machine, and then feed the results back again. We were able to run this loop all the way through with a simple example.
This way of thinking is not limited to robots. We are also attempting to connect microscopes and sensors to Sakana's Agentic Scientist, have AI predict the optimal lighting conditions for data collection, and have it change the lighting itself to prepare the experimental environment. Better experiments produce better models, and better models produce better experiments.
The world is changing. We model the world, machines adapt to that model, and humans change too. We want to create a world where humans and machines can safely and richly co-evolve.
Dialogue: David Ha × Jürgen Schmidhuber
The final session was a conversation between David Ha and Jürgen. Stefania Druga served as moderator.
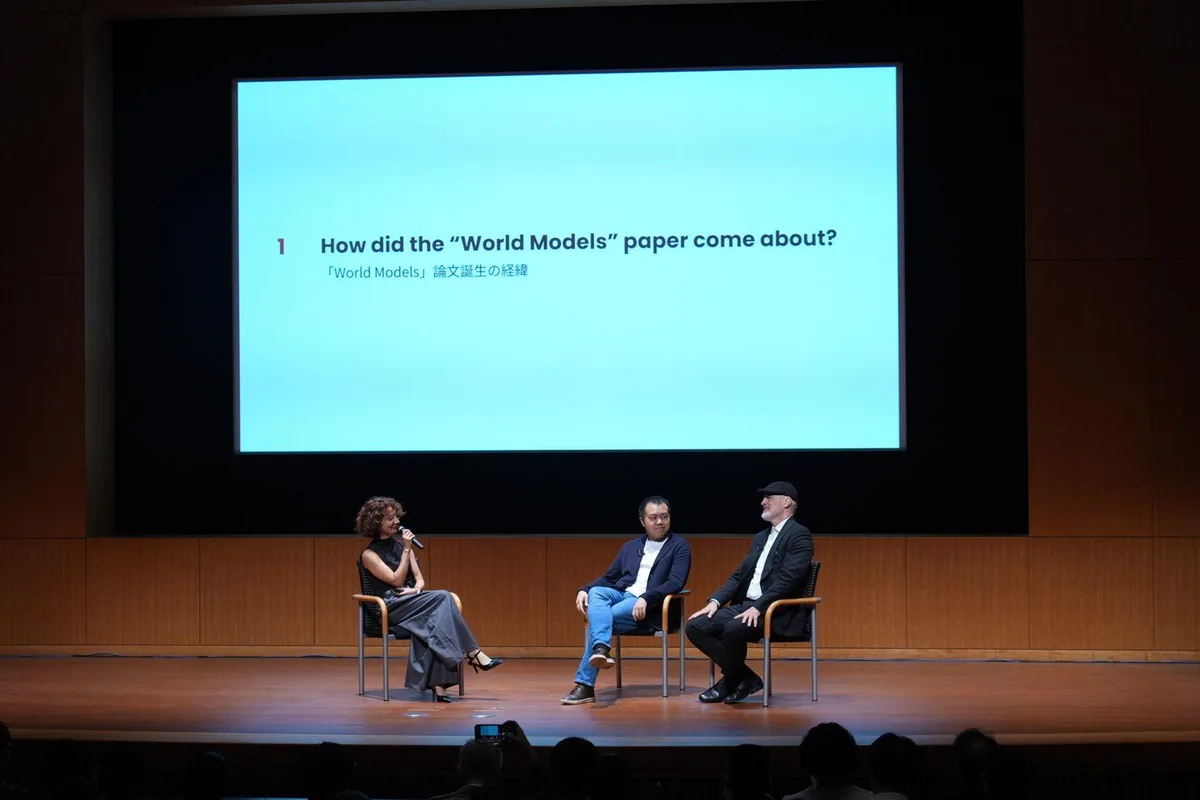
David Ha and Jürgen in conversation, with moderator Stefania Druga
From a single email
StefaniaHow did your paper "World Models" come about?
DavidAt the 2016 NeurIPS workshop, Jürgen gave a talk titled "On Learning to Think," and that was what got me started learning about world models. After that, I tackled OpenAI's car racing challenge by implementing a type of world model. When I emailed my professor about the progress along the way, we decided to turn it into a proper paper together, so we ran additional experiments and presented it as an oral presentation at NeurIPS.
JürgenI want to emphasize that all of this was research led by David. The oral presentation was selected from roughly the top 2% of accepted papers.
StefaniaWhat did you think when you received the email with that car racing animation?
JürgenIt was one of the most fascinating emails I have ever received.
What has happened in these 8 years
StefaniaIt has been eight years since the paper. How has world model research changed, and what surprised you?
DavidThe scale of world models has advanced significantly, and they are now being used in areas such as autonomous driving. On the other hand, I am surprised that there is not enough novelty. Humans can use a controller and a predictor to make intuitive, immediate judgments. In robotics, however, it is still mainstream to run Monte Carlo tree search simulations for every planning step. Using AI scientists to advance world models, especially in the field of Physical AI, is what we at Sakana AI hope to achieve through our efforts.
JürgenThe biggest lesson was to be patient no matter what. Computers become ten times cheaper every five years. In a few decades, they will become a million times cheaper still. What seems amazing today should look trivial in hindsight. On the other hand, robot hardware does not evolve as fast as computers. Thirty years ago, Japan already had fairly excellent walking robots. Today's robots are three to five times better than those of that time, but not a million times better. Physical AI takes time.
What is expected of researchers
Stefania:Agentic coding has dramatically changed what it means to be a developer, and now what it means to be a scientist is changing as well. How should we face this change?
DavidThe bar keeps rising. If I applied to any AI company now, including my own, I think I would fail the interview. Three years ago, what we asked of interns was the ability to come up with ideas, implement experiments, and summarize results. Now we can delegate that to AI agents. So what we now ask of interns is to think like professors or PIs. Scientists will think like metascientists, and metascientists will think like meta-metascientists.
Even so, I believe there are things that remain even as times change. I call that a "vision." A frequently cited Japanese example is Nintendo. Nintendo did not chase cutting-edge performance, but held fast to its vision of making fun games. Even without the best hardware, it succeeded precisely because it kept that vision. Even as technology advances, as long as we have our own vision and mission, we should be able to use technology to realize them.
JürgenIt is interesting to see which artificial scientists are working well right now. The one that has made dramatic progress is the artificial mathematician. Mathematics is a deductive science, given rules called axioms. One can stay on the other side of the screen and work on finding or disproving proofs.
Physics is different. They don't know the rules of the game. From raw pixels, they must derive new physical laws that are not yet known. It is an inductive endeavor, and far harder than deduction. I always say that the first time an artificial physicist discovers a new physical law will be at roughly the same time as the first time an artificial musician produces an entirely new melody that ranks among the top 100 songs in human history.
David Ha and Jürgen in conversation
Conclusion
Of the AI that Jürgen has envisioned, generative AI has probably realized half. The other half—artificial scientists who devise their own experiments and understand the world, and Physical AI that works in the real world—has yet to reach scale. AI research today may appear to be dominated by players in the United States and China competing over the scale of large foundation models, but the opportunities are in fact open precisely outside the giant labs. Japan is one of those promising places.
Sakana AI has aimed to create a frontier AI company in Japan where researchers from overseas and Japan's top researchers work together. Launched in June 2026,RSI LabGoing forward, we will advance all at once the next-generation language models, including Sawara, AI research conducted by AI, and research into world models and Physical AI combined with these. Jürgen will continue to provide us with knowledge and inspiration for this challenge.
I hope this symposium will serve as one of the starting points for opening up the next era of AI together with everyone from Japanese companies and research institutions.
Thank you to everyone who attended.

Sakana AI
At Sakana AI, we are recruiting colleagues to join us in taking on challenges across a range of roles, including RSI Lab, in research, engineering, and business.
-
Learn more about RSI Lab here:https://sakana.ai/rsi-lab-jp/
-
Open positions are listed here:https://sakana.ai/careers/
English Report
[Event Report] Sakana AI Symposium: Jürgen Schmidhuber on the Past and Future of AI, and Pushing the Frontier of Language Models, World Models, and Physical AI from JapanProfessor Jürgen Schmidhuber, Chief Scientific Advisor of Sakana AI, delivering the keynote
On October 26, 2026, Sakana AI hosted the symposium “From World Models to Real-World AI” at Hitotsubashi Hall in Tokyo. In September, we welcomed Professor Jürgen Schmidhuber as our Chief Scientific Advisor. Since the 1980s, he has pioneered many of the ideas underlying today’s deep learning and generative AI, including the first Transformer (the unnormalized linear Transformer), pre-training and distillation of deep neural nets, modern world models, artificial curiosity through generative and adversarial networks, and recursive self-improvement. He also co-authored the famous 1997 LSTM paper, now the most-cited AI paper of the 20th century. More than 400 people from across Japan joined us for his keynote and for a conversation with our co-founder and CEO David Ha, who co-authored the 2018 paper “World Models” with him.
At the symposium, Sakana AI announced that it is moving into pre-training its own models. Our Chief Scientist Takuya Akiba introduced “Sakana Sawara” (provisional name), a new language model series that we will build from scratch, starting with pre-training. If everything goes smoothly, the first model, a small model called “Sawara Small” (provisional name), will be released in spring 2027.
We organized this symposium to share our ambitions now that Professor Schmidhuber has joined us, and as a starting point for opening up the next era of AI together with companies and research institutions across Japan. This report presents the talks and the conversation as edited transcripts (excerpted, with some passages reordered for readability).
Contents
- Opening: From World Models to Real-World AI | David Ha
- Keynote | Jürgen Schmidhuber
- LLM Development at the RSI Lab | Takuya Akiba
- Towards Open-Ended Autonomous Discovery Systems | Robert Tjarko Lange
- World Models & Physical AI | Stefania Druga / Sebastian Risi
- Fireside Chat | David Ha × Jürgen Schmidhuber
- Closing
Chieko Tazuke, Chief of Staff at Sakana AI, who hosted the symposium
Opening: From World Models to Real-World AI | David Ha
The program opened with a talk by David Ha, co-founder and CEO of Sakana AI.
David Ha, CEO of Sakana AI
Intelligence emerges from constraints
The T-shirt I’m wearing today has a diagram of world models on it. It was drawn by Professor Jürgen Schmidhuber himself back in 1990. Back then, compute was a million to a billion times more expensive than today, and he had to hand-draw these figures and paste them into the paper. Today we have AI scientists writing papers together with us, but it’s good to be reminded of how the innovations of the 1980s and 1990s led to where we are now.
One of my hot takes on social media is that foundation models are among the fastest-depreciating financial assets in the history of mankind. As someone who started an AI company that makes these models, this is a real struggle for me. How does Japan compete with the rest of the world in this space?
One of my core beliefs is that AI development is not just about throwing more compute and data into ever-larger models. I believe intelligence emerges from constraints. Modern AI scales through abundance, but biological intelligence emerged from scarcity. Evolution selects for doing more with less. Our brains, our language, and our culture are all proof that constraints drive intelligence.
More than ten years ago, I got addicted to studying AI and took on some of the hardest tasks in OpenAI Gym. When I trained a neural network to solve the bipedal walker task, I also constrained the size of the robot and the energy it could use. With these constraints, the AI came up with a small, insect-like walker. What happens when there are no constraints at all? The AI discovered a giant robot with no brain that simply falls over toward the exit. We need constraints for our AI to actually have a brain.
Discovering Professor Schmidhuber’s papers
For the car racing task, where the agent drives from pixels, I gave the agent a world model, so that it could predict what would happen in the future and represent the world in a latent space.
As Jürgen always tells us, I went back to look at what people had done in the past. That’s how I discovered his line of papers on world models, from his 1990 paper on making the world differentiable to his 2015 paper “On Learning to Think.” I found them very inspiring. They bring together many concepts, from algorithmic information theory to artificial curiosity, and that’s where I learned to think of an agent as a controller, C, and a model, M.
I then wrote the “World Models” paper together with him, which we presented at NeurIPS. We showed that an agent can actually be trained inside the dream hallucinated by its own world model. These ideas now underpin many modern innovations, from self-driving cars to robotics.
Sakana AI’s research and AI sovereignty in Japan
In 2023, I co-founded Sakana AI with Llion Jones and Ren Ito. Sakana means fish in Japanese. We believe intelligence is not just about the individual fish; it’s the school, and we take a collective intelligence approach. As a company in Japan with limited resources, we also don’t want to do exactly what everyone else is doing. We want to be the red fish that swims a little differently from the rest.
David Ha: "Intelligence is not just an individual fish. It's the school."
Our research so far includes the brain-inspired Continuous Thought Machines, PC-ALM, which trains 1,000-layer networks without backpropagation, The AI Scientist, published in Nature this year, and the Darwin Gödel Machine, which brings Jürgen’s idea of the Gödel machine to life with LLMs.
So how should Japan build AI amid global competition? I see AI sovereignty in Japan as resting on three pillars. Pre-training: the ability to develop this technology from scratch. Post-training: aligning models with our values, especially the values of Japan. And orchestration: combining our models with the frontier models produced by the rest of the world to push performance further. For orchestration we offer Sakana Fugu, and for post-training, Sakana Namazu.
The last pillar is pre-training. We will be starting to pre-train our own models, and our Chief Scientist Takuya Akiba will talk about these efforts later today.
Our plan is to pre-train an agent-native LLM and an agent-native world model, have them work together on difficult tasks, and improve them through a self-improvement loop driven by the AI Scientist. This plan doesn’t look that different from one of Professor Schmidhuber’s papers: a controller and a world model working together. With the tools available today, we can build on these great ideas from the past and push the frontier.
Keynote | Jürgen Schmidhuber
Next, Professor Jürgen Schmidhuber delivered the keynote.
Neural networks were invented 230 years ago
I’m really proud that David chose to show up in a T-shirt based on a drawing I made back in 1990.
Modern AI is based on artificial neural networks. Your brain has about 100 billion neurons, each with maybe 10,000 connections on average. At first the strengths of these connections are random, but through learning some get stronger and some get weaker. That’s how the whole system learns to drive cars, translate languages, and do all kinds of things.
Who invented artificial neural networks? Some people think it was someone in America, maybe around 1940, but that’s totally wrong. They were invented 230 years ago, between 1795 and 1805. In 1795, Gauss had exactly what was called a 2-layer linear neural network in the 1990s: weights on the connections between input and output units, adjusted so that the mean squared error on the training set is minimized. Back then it was called the method of least squares. The first to publish it was Legendre, in 1805. This Gauss–Legendre network is the core of what everybody is doing at all the famous companies today. The main difference is that today’s networks are deeper.
By the way, the young Gauss became famous in 1801 by predicting the position of the asteroid Ceres after it had disappeared behind the sun. He predicted the next token, so to speak, and he got it right.
The roots of deep learning, and Japan
Who invented deep learning? It started in 1965 in Ukraine, then part of the Soviet Union, with Ivakhnenko and Lapa. Ivakhnenko’s 1971 paper described an eight-layer network that learned to model the British economy by predicting the next value of a time series.
Then, in 1967, a Japanese researcher, Shun-ichi Amari, introduced end-to-end deep learning, with a five-layer network, at a time when compute was billions of times more expensive than today. In 1970, Seppo Linnainmaa in Finland published what is now called backpropagation, used by everyone from Google to Sakana AI.
Another great Japanese contribution came in 1979, when Kunihiko Fukushima introduced the first convolutional neural network, which he called the Neocognitron. There is a famous video from 1986 of it recognizing handwritten digits. In 1988, Wei Zhang, working at a lab in Japan, combined Fukushima’s convolutional network with backpropagation, and applied it to character recognition. Zhang also scaled it up in the 1990s. So convolutional neural networks, central to computer vision today, were invented and further developed and scaled in Japan.
Since I’m here in Japan, I wanted to point out the essential things that happened in this country in the development of modern AI.
Jürgen tracing the roots of modern AI, from Gauss to Fukushima
World models and artificial curiosity, 1990
Our own contributions to neural nets came later, starting with this picture from 1990. There’s a little robot and a control network. One of the inputs is labeled R, for reward. The robot has pain sensors, and it receives evaluations of what it is doing as input.
This is one essential ingredient of what is now called recursive self-improvement: a system that learns not only to do something, but also learns to improve the way it learns, and to improve the way it improves the way it learns, and so on, recursively. For that, the network must see the evaluations coming from the environment. That was already present back then.
Then you add a second network, which looks at the robot’s actions and inputs and tries to predict what will happen next. That’s a model of the world. With a good model, you can plan: you can run mental experiments and choose the action sequences that lead to a lot of predicted reward and little pain.
But in the beginning, the model knows nothing. That’s why you immediately need something like an artificial scientist, one that invents its own experiments. A baby does not learn by downloading the World Wide Web. If a baby moves its hand, the incoming video changes, and it learns to predict how. That’s how it learns about physics, how apples fall to the ground, how parents react when it cries. It creates its own data through self-invented experiments.
The simplest way of doing this, which I published in 1990, is to have the world model minimize its error while the generative controller tries to maximize the same error. Whenever the controller finds a corner of the environment where the model can still learn something, it gets a reward: the eureka reward for inventing an experiment that tells you something you didn’t know. Many have implemented variants of this, and today this is called a generative adversarial network. I called it artificial curiosity.
1991, the miraculous year
Back then, deep learning didn’t really work well. You couldn’t deal with long time lags, where something that happened a thousand steps ago influences something a thousand steps later.
So in 1991 we had a whole bunch of papers to solve that problem, and funny enough, they are now the P and the T in ChatGPT. Pre-training: compressing long sequences by predicting the next thing. In the same paper, distilling the knowledge of one neural network into another. And the first Transformer variant. I called it the fast weight controller, but it is exactly what was called the linear Transformer in 2020. It scales linearly. With today’s quadratically scaling Transformer, if you have 1,000 times more text, you need a million times more compute. That is one of the reasons why data centers are so expensive.
Also in 1991, my brilliant student Sepp Hochreiter introduced the principle of deep residual learning in his diploma thesis. Consider a very simple unit with a linear activation function and a connection to itself of weight 1.0. When you propagate errors back through time, you always multiply by 1.0, so nothing changes over thousands of steps. That is what enables very deep learning through gradient descent, and it’s the core of the LSTM. Later this led to the first deep residual feedforward network which we published under the name “Highway Network” in May 2015 (and then later “ResNet”).
In 1991, nobody was interested in all of this. I once gave a talk at a conference where there was only one person in the audience, a young lady. I said, “Young lady, it’s very embarrassing, but apparently today I’m going to give this talk just to you.” She said, “Okay, but please hurry, I am the next speaker.” But every five years, computers got 10 times cheaper. Today compute is 10 million times cheaper than back then, and that’s why the techniques we published back then are now on all your smartphones.
Planning without simulating every detail
What David showed in his slide refers to a better way of planning. The naive way is to use the world model to simulate the future millisecond by millisecond. That’s good enough for chess and board games, but it’s not what you should do.
When you plan a trip from here to Paris, you don’t simulate your hand grabbing the phone. You think of a few high-level things: call a taxi, go to the airport, check in. You make a compact plan and ignore the details.
What I proposed in 2015 is to let the controller send queries into the hidden units of the world model, M. M may have seen all YouTube videos, or have lots of experience with robots. The controller is a learning prompt engineer that learns to address the few internal representations relevant to the current problem, interpret the answers, and change its own behavior. These queries are not in English or Japanese; they are just sequences of number vectors. For simple problems, it’s easier to solve them from scratch, but all interesting, complicated problems will greatly profit from the algorithmic information sitting deep in this huge model. In 2018, I also wrote a paper that collapses the model and the controller into one network through distillation. But the more famous paper of 2018 is the one by David, which showed in great experiments how world models can be really useful in practice.
AI beyond the screen
Let me put all this into a broader historical context. Much of what I mentioned today happened in Germany and Japan.
In 1990, Japan seemed like the land of the future. The six most valuable companies in the world were all Japanese. In 1995, the nominal GDP of Japan and Germany together almost equaled that of America plus China. And in 2002, more than half of the world’s robots were from Japan, and the country with the second most robots was Germany.
At the moment, the only AI that works really well is AI behind the screen. Behind the screen, there is a superhuman chess player, a superhuman Go player, a superhuman mathematician. But no robot comes close to what a plumber or an electrician can do, or to what a little boy can do with a football.
Physical AI in the real world is not owned by anybody yet. We now see an opening for a robot that can learn, by demonstration and reinforcement, to operate all the existing tools and machines. Once we have that, machines can make more of themselves, and we have an ultimate scaling machine. Then it no longer matters how many people a country has; what matters is whether it has machines like that. I hope that Japan and Germany and maybe a few other robot-oriented countries will lead there, and maybe connect to former glory in this way.
Jürgen on the promise of Physical AI
The future is bright
All the existing trends are working for the little guy, not for the big companies. Forty years ago, I knew a rich guy who had a mobile phone in his Porsche, so he could talk by satellite to another guy with a similar Porsche. Super expensive. Today, everybody all over the world has a smartphone that is much, much better.
It’s going to be the same with AI. Every five years it gets 10 times cheaper, and the physical limits of this trend are still far away. Everybody is going to have lots of AIs making their lives longer, happier, and healthier. The future is bright.
LLM Development at the RSI Lab | Takuya Akiba
After a break, three researchers from Sakana AI’s RSI Lab gave talks. The RSI Lab has three teams: language models (LLM), world models, and recursive self-improvement (RSI). First up was Chief Scientist Takuya Akiba, who leads the LLM team.
Chief Scientist, Takuya Akiba
From the agent layer to the model layer
Sakana AI was founded in 2023, and I joined as one of its earliest members. I’ve worked on a variety of things, and one of our focuses has been the agent layer: assuming strong models exist, and researching how to use them to do interesting things.
One example is ALE-Agent, an agent designed to discover strong algorithms for combinatorial optimization. We entered it in live competitive programming contests, and after a few attempts, it took first place against human experts. Another is AB-MCTS, a general algorithm for inference-time scaling that calls language models repeatedly to solve very hard problems. It has been deployed in multiple real-world projects at Sakana AI.
Working at the agent layer has been fun and successful. But recently, I think the model layer has become attractive again. Recent open models are very strong, close to frontier models, and good enough for real work. Data, training recipes, and software have become more accessible, so building these models is getting cheaper.
Perhaps more importantly, specialization at the model layer has become a very attractive option. With agentic reinforcement learning, we can optimize models end-to-end for our own tools, workloads, and scaffolds, and sometimes these specialized models outperform general ones.
This year we released Sakana Namazu, a model based on an open model and post-trained mainly for Japanese users. We reduced geopolitical bias, improved its understanding of Japanese culture, and taught it ways of communicating and thinking that feel more natural to Japanese users.
Then, this summer, we launched the RSI Lab, with three teams: language models, world models, and RSI research. I represent the language model team.
Sakana Sawara
So what’s next at the RSI Lab? Today I’d like to introduce our new language model series, Sakana Sawara. Please note that this is still a provisional name.
Takuya Akiba introducing the new language model series "Sakana Sawara" (provisional name)
Sawara will be our own language model series, built entirely by us from scratch. With Namazu we focused on post-training existing open models; with Sawara we are expanding into pre-training. It won’t be adapted from any other model, so we have full control over it. And it will be an agent-native language model, designed from the start for agentic workloads such as tool-integrated reasoning, coding, and long-horizon tasks.
Sawara will serve two purposes. One is to be the foundation of Sakana AI’s products and solutions. The other is to be the foundation of our RSI research. Because we have full control over the model and the recipes, and every process is fully transparent to us, it will enable RSI research with a broader scope.
Unfortunately, I don’t have much to share about Sawara yet, because it is still under development. So today I’d like to talk about how I think about language model development: my strategy.
The four features of Sawara
LLM development is a research competition
Many people would agree that this competition is about using more and more GPUs. That’s 100% true. But many also think GPUs are mainly for scaling, that is, for increasing the number of parameters or pre-training tokens.
That is actually a misunderstanding. According to Epoch AI, many groups use only a fraction of their compute for final training runs. At OpenAI, for example, final training runs are estimated to have accounted for only about 10% of R&D compute. A large share goes into trial and error, in other words, research. Language model development is more of a research competition than you might imagine.
So what are the key factors in this competition? I’d say progress is the product of two things: compute and research efficiency. Compute is simple. More GPUs means more experiments.
Research efficiency is underestimated, but it’s equally important, because the result is the product of the two. It’s about how much we can learn from each experiment. Over the past ten years, I’ve seen a huge difference here between researchers. Some people are very good at designing experiments that give us as much information as possible.
Talent density and AI tokens at scale
What drives a team’s research capability today? I’d say talent density and AI tokens at scale. It’s 2026, not 2023. Since we published the AI Scientist in 2024, many groups have followed, and everyone now agrees that research is a collaboration between humans and AI. We emphasize talent density over headcount, and I’m confident in my team. It’s the most talent-dense team I have ever seen.
Interestingly, this way of thinking leads continuously to RSI. We are already using AI, but it’s probably not our own models. Next time, some part of that AI could be Sawara. Then the next version of Sawara could be developed with the help of Sawara. It depends on how you define RSI, but I’d call this fractional RSI. Hopefully, in the future, Sawara will take on more and more of this process.
Roadmap
Finally, our roadmap. We are now preparing for training, and we will start pre-training Sawara Small (provisional name) this December. If everything goes smoothly, we will release the weights next spring. We also plan to develop a larger model, Sawara Large (provisional name).
Towards Open-Ended Autonomous Discovery Systems | Robert Tjarko Lange
Next, Staff Research Scientist Robert Tjarko Lange spoke on behalf of the RSI team.
Robert Tjarko Lange on Open-Ended Autonomous Discovery Systems
The AI Scientist so far
When I started my scientific career, one of my big inspirations was Jürgen’s diploma thesis, on genetic algorithms that recursively refine themselves. That’s how I started working on meta-learning. Today, in 2026, we have much more powerful mutation operators in the form of large language models, which let us autonomously test new hypotheses.
Scientific progress drives prosperity, but so far most research has been done purely by humans, without AI assistance. So in 2024, as language models began to follow instructions well, we started building the AI Scientist v1, a blueprint for automating the entire research pipeline with agents, from ideation and novelty checks to experiments, paper writing, and review.
A year later, with v2, we used tree search to orchestrate the stages of the research pipeline, and a paper it generated passed human peer review at a machine learning conference workshop. We obtained ethics approval in advance and communicated closely with the workshop organizers, because we always want to respect the scientific process and maintain integrity.
Our latest version, v3, also called the Agentic Scientist, can still run fully autonomously, but it is designed for co-discovery, so that humans can work with it to refine hypotheses. It verifies all claims, runs ablations, and aims to reduce reward hacking. We used v3 to write another paper, which we submitted after checking all the claims ourselves, and it was accepted as a main conference paper at ALIFE 2026.
Robert on the milestones of the AI Scientist
Broadening the ideation radius
So what’s next? Many auto-research systems today are a bit like hyperparameter tuning on steroids. They can rewrite code, but their ideation radius is not how humans do research. We need to move beyond hill-climbing benchmarks and push these systems to do research in a much more diverse way.
For inspiration, we can look at Sakana AI’s own structure: the Frontier Intelligence Group (FIG), where researchers explore interesting, long-horizon hypotheses in an open-ended way. How can we build AI scientists in that spirit, less hill-climbed?
Human scientists are biologists, economists, and philosophers. To advance science holistically, we need AI scientists that adapt to different disciplines, gather their own expertise, and improve themselves. Additionally, 80% of my own scientific process is trial and error that never makes it into the final paper. These scientific research traces are largely absent from the LLM training process. We need to explicitly think about how AI systems can internalize the scientific method itself, drawing on ideas like Karl Popper’s falsificationism.
Science is inherently a collective endeavor, not a lone genius in a corner. How do we build a world where AI scientists collaborate collectively, and where humans are part of that process too? The technical questions become how to allocate resources, how to assign credit to scientific results, and how to judge whether a contribution is meaningful.
Finally, safety is really important. But I think the solution is not to stop AI progress, but to use AI to develop AI safely. Applying AI scientists to areas like mechanistic interpretability or chain-of-thought monitoring can give us not only better systems, but also a better understanding of them.
World Models & Physical AI | Stefania Druga / Sebastian Risi
The third talk, on world models and Physical AI, was given by Stefania Druga and Sebastian Risi.
Why Physical AI in Japan (Stefania)
We are very excited to do this work in Japan, because Japan excels at robotics and Physical AI. At the same time, Japan faces big challenges: three out of ten people are over 65. That is both a problem and an opportunity. If we combine the hardware capabilities here with what AI can learn today, we can create better applications for the people who need them most.
Sebastian Risi (left) and Stefania Druga (right)
Check with a world model before acting in the real world (Sebastian)
Robot learning has made great progress over the past ten years. But we still don’t see robots in our households, and as Jürgen said, we don’t have robot plumbers or electricians yet. I think two gaps remain: speed and safety. Approaches that use big LLMs are slow at inference. And even when tasks succeed, 18 to 28% of episodes don’t follow the instructions exactly.
Our bet at Sakana for closing these gaps is world models. You check actions with a world model before performing them in the real world, and you only accept improvements backed by actual physical evidence. Physical trials are very costly, so robots need a world model that lets them imagine potential futures.
In our architecture, a small vision-language model (VLM), which allows fast inference, proposes plans. The world model takes these plans, predicts states several steps ahead, judges feasibility and causes of failure, and scores how close the plan gets to the goal. Many plans are filtered out by the world model, only a few are tried on real hardware, and the results are used to improve the VLM.
Sebastian explaining the improvement loop that combines world models and real hardware
But what we want is recursive self-improvement: a system that not only gets better, but gets better at getting better. We connect the Agentic Scientist, the agent-native LLM we are developing, and Physical AI, so that the Agentic Scientist can improve the world model itself, and we feed what we learn from the real world back into the Agentic Scientist to close the loop. To avoid reward hacking, we use a frozen gate with strict criteria: repeated gains across evaluations, statistical evidence, and gains on held-out tasks. And building on collective intelligence, which is in Sakana’s DNA, we are also working on making RSI more effective and safer.
Stefania presenting early experiments in world models and Physical AI
Early experiments (Stefania)
A world model predicts what’s next, but an experiment tells us what actually happens. We want to close the gap between the two and learn recursively.
In our first example, in partnership with AIRoA (AI Robot Association), we took a fine-tuned π0.5 policy and tested it in simulation on a Franka robot. At first, the robot couldn’t open a drawer or place objects in it. By repeatedly showing the controller where it failed, we improved it until the robot succeeded. The next step is to test the improved policy in the real world.
We have also started working on robots that change their own morphology depending on the task. We create simulations from real robot videos, explore in simulation, which is faster, cheaper, and safer, test the resulting controller on the physical robot, and feed the results back. In a simple example, we went through this entire loop.
This doesn’t stop at robotics. I connected a microscope and a set of sensors to Sakana’s Agentic Scientist (v3) to forecast the best lighting conditions for collecting data, and then let the system change the lighting itself. Better experiments lead to better models, and better models lead to better experiments.
The world is changing. We are modeling the world, machines are adapting to the world we are modeling, and people are changing as well. We want to design a world where people and machines co-evolve in safe and flourishing ways.
Fireside Chat | David Ha × Jürgen Schmidhuber
The final session was a conversation between David Ha and Jürgen, moderated by Stefania Druga.
David Ha and Jürgen in conversation, moderated by Stefania Druga
It started with an email
Stefania: How did your “World Models” paper come about?
David: I was at the NeurIPS 2016 Deep RL workshop, where Jürgen was giving a talk on his paper “On Learning to Think.” That inspired me to learn more about world models. Then I tried to win OpenAI’s car racing task and implemented one of the world model variants. I sent Jürgen my preliminary results, we agreed to turn it into a proper paper with additional experiments, and we presented it at NeurIPS as an oral presentation.
Jürgen: You really have to emphasize that this was all driven by David. And it was not just an oral; it was among the top 2% or so of accepted papers.
Stefania: What did you think when you received that email with the car animation?
Jürgen: It was one of the most charming emails I’ve ever gotten.
Eight years on
Stefania: It has been eight years since the paper. How has research on world models evolved, and what surprised you?
David: We’re seeing tremendous progress in scaling up world models; they’re now used in self-driving cars. But I’m surprised by the lack of novelty. Humans can arrive at a decision intuitively, with a controller working together with a predictor. Yet in robotics, everyone still seems to run Monte Carlo tree search simulations at every planning step. That’s where I hope our work at Sakana AI, leveraging AI scientists, can help advance world models, especially in Physical AI.
Jürgen: The main lesson was: just be patient. Every five years, computers get 10 times cheaper. In a couple of decades we will have another factor of a million, and everything that seems impressive today will seem trivial in hindsight. On the other hand, physical robots don’t evolve as quickly as computers. Thirty years ago, there were pretty decent walking robots in Japan. Today’s robots are maybe three to five times better, not a million times better. Physical AI is a slow game.
What it takes to be a researcher now
Stefania: Agentic coding has shifted developers’ identity, and now we’re seeing the same with scientists. How should people deal with this change?
David: The baseline keeps moving higher. If I applied for a job at any AI company today, including our own, I’d probably fail the interview. Three years ago, we looked for interns who could come up with ideas, implement experiments, and collect results. Now you can ask an AI agent to do that, so we expect interns to think like a professor or a PI. Scientists have to think like meta-scientists, and meta-scientists like meta-meta-scientists. It’s turtles all the way down.
But there’s one thing I believe will stand the test of time, and I like to call it vision. An example I often bring up in Japan is Nintendo. Nintendo didn’t chase state-of-the-art performance. They stayed true to their vision of creating fun games, and they didn’t need the best hardware to succeed. As long as we have our own vision and mission, we can use technology to achieve it as the technology improves.
Jürgen: It’s interesting to see which kinds of artificial scientists are working. The one that has improved dramatically is the artificial mathematician. Mathematics is deductive: the rules are given as axioms, and you can stay behind the screen and search for a proof or a disproof.
Physics is very different. You don’t know the rules of the game. You have to take the raw pixels coming at you and distill a new physical law that wasn’t known before. That’s induction, and it’s much harder. I always claim that the first time an artificial physicist discovers a new physical law will be roughly the same time an artificial musician first creates a melody as good as one of the 100 best melodies in human history.
David Ha and Jürgen during the fireside chat
Closing
Perhaps half of the AI Jürgen has envisioned has been realized through generative AI. The other half, such as artificial scientists that invent their own experiments to understand the world, and Physical AI that works in the real world, has yet to scale. AI research today may look dominated by US and Chinese players competing to scale ever-larger foundation models, but this opportunity is open, perhaps even more so, outside the big labs. Japan is one of the most promising places to pursue it.
Sakana AI was founded to build a frontier AI company in Japan, bringing together researchers from around the world and top researchers from Japan. At the RSI Lab, launched in June 2026, we are pursuing next-generation language models starting with Sawara, AI-driven AI research, and, combined with these, research on world models and Physical AI, all at once. Jürgen will continue to provide insight and inspiration for this challenge.
We hope this symposium will be one of the starting points for opening up the next era of AI, together with companies and research institutions across Japan.
Thank you to everyone who joined us.
Sakana AI
Sakana AI is hiring across research, engineering, and business, including at the RSI Lab.
-
Learn more about the RSI Lab: https://sakana.ai/rsi-lab/
-
Open positions: https://sakana.ai/careers/