←搜索结果

按匹配度 · 共 561 条结果 清除搜索

星期二

  1. InternLM 原创项目精选

    InternLM 发布 Intern-S2 系列科学多模态模型

    InternLM 发布 Intern-S2-397B 及其预览版 Intern-S2-Preview-397B、Intern-S2-Preview-35B 等科学多模态基础模型,覆盖预训练、强化学习任务与长程智能体三个方向。其中 Intern-S2-Preview-35B 基于 Qwen3.5 继续预训练,仅用 35B 参数在多个核心专业科学任务上达到万亿级 Intern-S1-Pro 的相当水平,并采用共享权重 MTP 与 CoT 压缩提升推理效率。系列模型支持 LMDeploy、vLLM、SGLang 部署,以 Apache 2.0 许可发布。

    iles navigation 👋 join us on Discord and WeChat Introduction We introduce Intern-S2-397B, our most capable multimodal foundation model for scientific intelligence and long-horizon agents. Intern-S2-397B scales along three critical dimensions: pre-training, reinforcement-learning task coverage, and interactive agent environments. By combining a new vision-language pre-training paradigm with large-scale multi-task reinforcement learning and long-horizon agent reinforcement learning, Intern-S2-397B

    匹配字段正文
  2. World Labs Blog精选

    World Labs 正式开放多模态世界模型 Marble

    World Labs 宣布其多模态世界模型 Marble 即日起向所有人开放,此前仅面向少量 beta 用户。Marble 支持从文本、图像、视频或粗略 3D 布局生成 3D 世界,并可交互式编辑、扩展和组合,生成结果可导出为 Gaussian splats、网格或视频。同时推出 Marble Labs 创作社区,提供案例研究、教程和文档。

    he next frontier in AI, demanding powerful world models to realize its full potential. World models should reconstruct, generate, and simulate 3D worlds; and allow both humans and agents to interact with them. Spatially intelligent world models will transform a wide variety of industries over the coming years. Two months ago we shared a preview of Marble, our World Model that creates 3D worlds from image or text prompts. Since then, Marble has been available to an early set of beta users to crea

    匹配字段正文

  3. Analytics India Magazine

    Meta 发布 Muse Wonder 与 Muse Wonder Full 智能体模型

    Meta 发布 Muse Wonder 和 Muse Wonder Full 两款面向个人与专业智能体的 AI 模型,具备长期记忆、多步任务执行和编码能力,并在公司 gigawatt 级 Prometheus 数据中心完成训练。模型结合 Active Memory 与 Active Focus 两项能力,前者跨对话保留并检索相关信息,后者支持长时间朝目标推进、尝试替代方案并适应新信息。Meta 称其在个人与专业智能体、记忆和编码基准上取得 SOTA,评测涵盖 AutomationBench-AA、MemoryBench、SWE-Marathon 和 DeepSWE,并测试了法律、金融与健康等专业任务。

    Meta has launched Muse Wonder and Muse Wonder Full, two AI models built for personal and professional agents, with capabilities spanning long-term memory, multi-step task execution, and coding. The models are part of Meta’s effort to scale its AI efforts. Meta trained both models were trained at the company’s gigawatt-scale Prometheus data centre. The company also plans to use the model to develop specialised models for wider access through Muse. The Muse Wonder series combines two capabilities

    匹配字段正文

  4. Computerworld

    微软发布 Decision-1 决策模型,基于 Qwen3.5-9B 后训练

    微软发布 Decision-1,这是一款对预设答案返回校准概率的 AI 模型,让应用直接使用其输出,而无需处理大语言模型的自由文本回复。该模型基于 Qwen3.5-9B 后训练,支持是非判断、预设选项选择、评分以及基于评分标准的评估,可用于分类请求、事件优先级排序和校验 AI 生成内容,已通过 Microsoft Foundry 和 OpenRouter 提供。微软称其在覆盖近 15 万个问题的 36 项基准对比中准确率最高,速度约为第二名的 2.5 倍、GPT-6 Sol 的 35 倍,定价为每百万输入 token 4.2 美分且输出 token 不收费,但上述结果与成本计算尚未经独立验证。分析师提醒该模型不提供决策理由,企业应关注校准测试、问题措辞控制、审计日志和高影响决策的人工复核。

    penAI models. Model targets specific decisions Decision-1 supports yes-or-no judgments, choices among predefined options, ratings, and rubric-based assessments of AI responses and agent actions, Microsoft said. Developers can use its outputs to classify inputs, rank work, verify responses, or determine the next action in an AI agent workflow. Unlike a general-purpose LLM, which can generate explanations and other natural-language content, decision models return probabilities for the available an

    匹配字段正文

  5. Latent Space

    Meta MSL 发布第二代模型 Muse Wonder,第三方评测接近前沿

    Meta Superintelligence Labs 发布第二代模型家族 Muse Wonder(代号 Watermelon),距实验室成立约 14 个月。Artificial Analysis 的 Intelligence Index v4.3 中 Wonder Full(max)得 56、Wonder(max)得 52,高于 Muse Spark 1.3 的 48,Opus 5.5 以 58 领先;提升最大的是智能体能力,Terminal-Bench 4.0 从 33% 升至 57%。规格为 1M 上下文,输入支持文本、图像、视频和音频,输出仅文本,定价为每百万 token 输入 4 美元、缓存输入 0.20 美元、输出 20 美元。

    x) at 48. The gap between Spark 1.3 and Wonder releases was only 6 weeks. Opus 5.5 leads at 58 (@TheRundownAI); Wonder Full improved on all ten index evals. The largest gains were agentic:Terminal-Bench 4.0: 33% → 57%; GDPval-AA v2.1: 1681 → 1857 Elo; AA-Briefcase: 1581 → 1729 Elo; Where Wonder Full ranks: top three on 6 of 10 evals. 1 on GDP.pdf (33%) and on CritPt (33%); 2 on GDPval; 3 on AA-Briefcase, AutomationBench-AA (71%) and SciCode (63%); Wonder (non-Full) gains: Terminal-Bench 33% → 52

    匹配字段正文

  6. TechCrunch AI精选

    Meta 发布首个前沿模型 Muse Wonder 与 Muse Wonder Full

    Meta 的 Superintelligence Lab 发布 Muse Wonder 和 Muse Wonder Full 两款模型,这是该公司首次推出前沿模型。两款模型规模大于此前的轻量模型 Muse Spark,Meta 称其在编码等复杂任务上基准成绩与 Fable 5.1、GPT-6 Astra 相当,并通过 Meta Model API 提供,定价为每百万输入 token 4 美元、每百万输出 token 20 美元。Meta 还强调模型保留和整合用户信息的“active memory”能力,称 Muse Wonder 在 MemoryBench 上的得分高于 Fable、Opus 和 Astra。

    Kopparapu in a video accompanying the launch. The new models are the first frontier model release since Scale AI founder Alexandr Wang restructured Meta’s AI efforts in August of last year . Since then, Meta has released its lightweight Muse Spark model and Muse agent but has avoided the kind of state-of-the-art model releases OpenAI and Anthropic are known for. According to the post, the models were trained at Meta’s Prometheus data center in central Ohio , which came online earlier this year.

    匹配字段正文

  7. The Rundown AI

    Meta 发布 Muse Wonder 与 Muse Wonder Full 模型

    Meta Superintelligence Labs 发布 Muse Wonder(代号 Watermelon)和 Muse Wonder Full 两款模型,其中完整版在 Artificial Analysis 智能排名中位列第二,仅次于 Anthropic 的 Opus 5.5。报道称 Meta 由此进入此前由 OpenAI 和 Anthropic 主导的前沿模型竞争,其优势还包括数据中心、数十亿用户以及智能体应用 Muse。文中还提到 Andrej Karpathy 关于 AI 能力认知分层的观点、微软 Maia 300 芯片,以及一份使用 Muse Wonder 完成工作坊议程与预算的教程。

    between OpenAI and Anthropic so far. The climb has been impressive, but the scarier part for rivals is everything around the model — the data centers, billions of users, and a hit agent app in Muse that are hard qualities for other labs to replicate. TOGETHER WITH BOX 💭 Reimagine enterprise AI at BoxWorks 2026 The Rundown: Unlocking enterprise AI begins by connecting agents to where your business knowledge lives: your content. Box securely connects unstructured data to the tools your teams use d

    匹配字段正文

  8. Wired AI

    Meta 发布 Muse Wonder 与 Muse Wonder Full 模型

    Meta 发布 Muse Wonder 和 Muse Wonder Full 两款新模型,称后者具备前沿能力,将通过 API 和 Muse Code 提供,并用于其平台功能与 Muse 个人智能体。Meta 称最大版本在 Artificial Analysis Intelligence Index 上超过 Claude Fable 5.1、仅次于 Claude Opus 5.5,并在法律文档处理和软件开发等专项基准上超过 GPT-6 Astra。新模型还引入 Active Memory 和 Active Focus 两项功能,用于让智能体锁定既定目标、避免混乱。

    gh an API and through Muse Code, a tool for writing software with AI. Meta says the best version of the model will power features across its platforms, including its Muse personal agent. Zuckerberg overhauled his company’s AI research last year by sinking billions into the recently formed Meta Superintelligence Labs, and hiring the former Scale AI CEO Alexandr Wang to lead it. This effort has sometimes been rocky, with some researchers not sticking around for long. Meta was once a trailblazer in

    匹配字段正文

  9. The Verge AI

    Meta 发布两款新 AI 模型,称可对标 OpenAI 与 Anthropic 旗舰

    Meta 发布两款新 AI 模型,称其能力可对标 OpenAI 和 Anthropic 的领先模型,包括 GPT-6 Astra、Claude Opus 5.5 和 Claude Fable 5.1,依据是多项行业基准的内部测试结果。这两款模型是 Meta 重组后的 Superintelligence Labs 继 Muse Spark 和 AI 智能体 Muse 之后的新品,目前尚不清楚它们与 Google Gemini 4 Argon 的对比情况。Meta 正持续扩充 AI 产品线,此前已推出图像模型 Muse Image。

    Meta is making up for lost time in the AI race. After launching Muse Spark , the first model from its revamped Superintelligence Labs division, and buzzy AI agent Muse , it’s now launching two new models it claims can go toe-to-toe with the industry’s best. The company says its new models can rival leading models from OpenAI and Anthropic, including GPT-6 Astra, Claude Opus 5.5, and Claude Fable 5.1, pointing to results from internal testing on several industry benchmarks. It’s unclear how they

    匹配字段正文

  10. Thinking Machines Lab:官方博客

    Thinking Machines Lab 发布开源权重模型 Inkling-Small

    Thinking Machines Lab 发布开源权重模型 Inkling-Small,这是一个 276B 总参数、12B 激活的 MoE Transformer,性能与 Inkling 相当但规模仅为四分之一。该模型原生支持音频与图像推理、可变思考预算和最高 1M token 上下文窗口,在 HLE 上得分 31.6%,超过 Inkling 的 29.7%,SWE-bench Verified 超过 80%。完整权重已开放,并可在 Tinker 上微调,在 Tinker Playground 进行文本、图像和音频对话。

    and well-rounded performance across a range of benchmarks. Inkling-Small Inkling Compared to Inkling, Inkling-Small achieves comparable performance with much less compute. Across agentic tool use (Terminal-Bench 2.1), reasoning (HLE text-only, no tools), and instruction following (IFBench) benchmarks, Inkling-Small is more efficient than Inkling and competitive with other models in its weight class. Furthermore, its variable thinking effort lets users easily adapt it to target their use case, b

    匹配字段正文

  11. Thinking Machines Lab:官方博客

    Thinking Machines Lab 发布开源权重模型 Inkling

    Thinking Machines Lab 发布开源权重模型 Inkling,这是一个 975B 总参数、41B 激活的 MoE Transformer,支持最高 1M token 上下文窗口,预训练数据为 45 万亿 token 的文本、图像、音频和视频。官方称 Inkling 并非当前最强模型,但具备多模态、可控思考算力和可在 Tinker 上微调等特点,适合作为定制底座,并同步预览了 12B 激活参数的 Inkling-Small。Inkling 已在 Tinker 上线,提供 64K 和 256K 上下文选项,权重发布在 Hugging Face。

    Capabilities Generalist model; Agentic coding and tool use One-shot web app with embedded browser use Design Arena; Cohesively styled artifacts; Multiplayer game created through long refinement loop; Controllable thinking effort; Multimodality; Epistemics; Safety; Benchmarking Inkling; The making of Inkling Architecture; Training; RL at scale; Inkling-Small; Customizing Inkling Inkling availability Our mission is to build AI that extends human will and judgment. We have developed a platform that

    匹配字段正文

  12. 蚂蚁 inclusionAI:GitHub 新仓库

    蚂蚁 inclusionAI 开源 LLaDA-UI 扩散式 GUI 智能体

    蚂蚁 inclusionAI 在 GitHub 开源 LLaDA-UI,一个基于 MoE 的块级扩散视觉语言 GUI 智能体,端到端约 16.7B 参数,结合原生动态分辨率视觉编码器与 LLaDA2.0-mini-base 扩散语言骨干。训练覆盖 grounding、移动端、桌面端和网页任务,包含 100 多个中文和 70 多个英文移动应用数据。官方称其在全部六项 GUI 基准上超过 Qwen2.5-VL-7B,并在 ScreenSpot-Pro、AndroidWorld、MobileWorld 和 WebVoyager 上超过 Qwen3-VL-8B。

    on settings; Fork1 (1); Star15 (15)You must be signed in to star a repository Repository files navigation README LLaDA-UI is an MoE-based, block-wise diffusion vision-language GUI agent. It combines a native dynamic-resolution vision encoder with the LLaDA2.0-mini-base diffusion language backbone, and generates reasoning and GUI actions through the same block-wise diffusion decoder. Figure 1. LLaDA-UI GUI-agent performance and qualitative block-wise diffusion decoding. The radar chart and GUI ob

    匹配字段正文

  13. 蚂蚁 inclusionAI:GitHub 新仓库

    蚂蚁 inclusionAI 发布 UI-Venus-2,统一移动、网页与桌面 GUI 智能体

    蚂蚁 inclusionAI 在 GitHub 发布 UI-Venus-2,提供 9B 和 27B 两个版本,仅以截图作为输入,将移动、网页和桌面交互统一到一个端到端 GUI 智能体中。相比 UI-Venus-1.5,新版本扩展了中英文移动环境,从零构建桌面 computer use 能力,并引入基于关键点的验证与验证增强反思机制。仓库同时给出移动、Computer、Browser、Grounding 和 CAPTCHA 等基准上的对比结果,并提供 Venus Framework 等运行框架。

    ficationsYou must be signed in to change notification settings; Fork87 (87); Star1.1k (1.1k)You must be signed in to star a repository UI-Venus is a general-purpose foundation GUI agent for mobile apps, web platforms, and desktop operating systems using only screenshots as input. Repository files navigation README English | 简体中文 A general-purpose foundation GUI agent for mobile apps, web platforms, and desktop operating systems — scaling environments, tasks, and feedback jointly within one close

    匹配字段正文

  14. 智源 FlagOpen:原创开源项目

    智源 FlagOpen 开源跨本体基础模型 RoboBrain-X0

    智源 FlagOpen 发布 RoboBrain-X0,一个面向异构本体迁移的跨本体基础模型,2025-09-29 已放出 RoboBrain-X0-preview。该模型用 SE(3) 任务空间末端执行器位姿表示、统一动作词表 UAV 与动作 tokenizer,并通过 Grouped Residual Quantizer 把不同自由度和机械结构的连续控制序列映射到共享离散动作基元空间,实现 AgileX、R1-Lite 双臂轮式机器人和 Franka 单臂系统之间的零样本泛化与复杂任务分解。模型由 RoboBrain 2.0 与动作 tokenizer OmniSAT 组成,支持多视图 RGB-D 输入到具体执行的解码,仓库采用 Apache-2.0 许可,后续计划放出基于 Fast Tokenizer 的 checkpoint、快速推理示例以及训练与评测代码。

    ing and inference overhead. RoboBrain-X0 delivers state-of-the-art performance in embodied reasoning tasks, laying a robust foundation for developing versatile, real-world robotic agents and advancing embodied intelligence research. 2025-09-29: 🔥 RoboBrain-X0-preview was released 📆 Todo Release model checkpoint for RoboBrain-X0-Preview based on Fast Tokenizer; Release quick inference example for RoboBrain-X0; Release training and evaluation codes for RoboBrain-X0; Release omnisat-based RoboBrain

    匹配字段正文

  15. Meta:Newsroom · AI精选

    Meta 发布 Muse Wonder 与 Muse Wonder Full 智能体前沿模型

    Meta 发布 Muse Wonder 系列,包含 Muse Wonder 和 Muse Wonder Full 两款模型,称其为目前能力最强的模型,在个人与专业智能体任务上达到 SOTA,覆盖法律、金融、健康等专业领域以及前沿编码能力。两款模型具备 Active Memory,可跨对话保留关键信息并调取与当前任务相关的细节;还具备 Active Focus,在任务变难时继续尝试其他方法、从错误中恢复,并在执行重要操作前先确认。Meta 表示该系列按 Meta Superintelligence Scaling Framework 的标准训练、评估和发布,完整安全评估报告将随后公布。

    nd Muse Wonder Full, our most capable models to date, built on the groundwork we laid with Muse Spark. The models deliver state-of-the-art performance on personal and professional agentic tasks. Built for Real World Needs Whether the job is navigating an insurance claim, understanding a lease, or making sense of someone’s finances, a model has to interpret the information in front of it and work through the problem. Muse Wonder and Muse Wonder Full bring that capability to expert domains includi

    匹配字段正文

  16. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-Rosalind-5.5 系统卡,面向生物研究预览部署

    OpenAI 发布 GPT-Rosalind-5.5 系统卡,该模型在 GPT-5.5 基础上用有益生命科学数据增量训练,以研究预览形式向经过审核的科研机构、政府伙伴等可信组织开放。生物领域能力高于 GPT-5.5,Labwork Bench 得分 63.2% 对 55.8% 且消耗更少 token;生物与化学领域达到 Preparedness 框架的高能力阈值但低于关键阈值。该模型不再拒绝复杂生物学提问,改以可信访问审核、模型层边界、监控与撤销机制作为主要防护,且未部署实时拦截不安全生成的自动监控。

    decision-making, and retrosynthesis. Table 1 3.2 Genomics and quantitative biology To evaluate GPT-Rosalind-5.5 on genomics understanding and quantitative biology, we designed an agentic evaluation on long horizon, end-to-end genomics analysis tasks. This evaluation assesses agentic performance on long-horizon quantitative tasks: based on realistic scientific data, can an agent plan valid analysis, QC, modeling, and corrections to arrive at decision-relative answers? Genebench spans a variety o

    匹配字段正文

  17. OpenAI:部署安全与系统卡

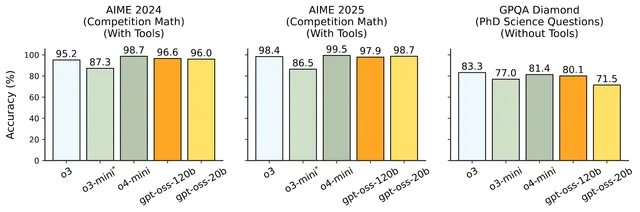
    OpenAI 发布 gpt-oss-120b 与 gpt-oss-20b 模型卡

    OpenAI 发布 gpt-oss-120b 和 gpt-oss-20b 两个开放权重推理模型,采用 Apache 2.0 许可,兼容 Responses API,支持工具调用、完整 CoT 与可调推理强度。gpt-oss-120b 为 36 层 MoE 架构,116.8B 总参数、5.1B 激活参数,MoE 权重以 MXFP4 量化后可放入单张 80GB GPU;gpt-oss-20b 为 24 层、20.9B 总参数、3.6B 激活参数,可在 16GB 内存设备上运行。OpenAI 对 gpt-oss-120b 做了对抗性微调测试,其安全咨询组认为即便使用其训练栈进行微调,模型也未在生物化学与网络安全两个类别达到 Preparedness Framework 的高能力阈值。

    Figure 1. <em>Main capabilities evaluations</em>. We compare the gpt-oss models
at reasoning level <code>high</code> to OpenAI’s o3, o3-mini, and
o4-mini on canonical benchmarks. gpt-oss-120b surpasses OpenAI o3-mini
and approaches OpenAI o4-mini accuracy. The smaller gpt-oss-20b model is
also surprisingly competitive, despite being 6 times smaller than
gpt-oss-120b. <em>*Note:</em> o3-mini was evaluated on AIME without
tools, see Table <a class="xref-link" data-xref="tab:all_evals" href="/gpt-oss/full-evaluations#tab:all_evals">3</a> for the gpt-oss
models on AIME without tools

    d our gpt-oss usage policy. Developed with feedback from the open-source community, these text-only models are compatible with our Responses API and are designed to be used within agentic workflows with strong instruction following, tool use like web search and Python code execution, and reasoning capabilities—including the ability to adjust the reasoning effort for tasks that don’t require complex reasoning. The models are customizable, provide full chain-of-thought (CoT), and support Structure

    匹配字段正文

  18. OpenAI:部署安全与系统卡精选

    OpenAI 发布 GPT-6 Sol 与 GPT-6 Luna 系统卡

    OpenAI 在 ChatGPT 免费与付费方案中向全球用户推出 GPT-6,取代 GPT-5.6 Sol 和 GPT-5.6 Luna,Codex 与 ChatGPT Work 中仍使用此前版本。系统卡显示,GPT-6 对越狱(含多轮自适应攻击)的抵抗力更强,不诚实、欺骗和绕过护栏的行为减少,指令层级评测中 GPT-6 Sol 与 Luna 分别达到 99.99% 和 99.79% 的稳健性。同时 GPT-6 Sol 在标准自我伤害类别出现统计显著回退,GPT-6 Luna 在自我伤害、血腥和性内容上出现回退,OpenAI 称人工复核后违规程度总体较低。按 Preparedness Framework,两款模型在网络安全和生物化学领域被列为 High capability,均未达到 AI 自我改进的 High 阈值。

    Figure 1. Safety and non-overrefusal on challenging prompts. Higher is better
on both axes.

    propriate safeguards, and improving how we measure and report model performance for younger users. 3.2 Vision We ran the image input evaluations originally introduced with ChatGPT Agent. These tests use disallowed requests that combine text and images and measure whether the model’s responses are classified as safe. GPT‑6 Sol (October) and GPT‑6 Luna (October) performed on-par with GPT-5.6 Sol (August) and GPT-5.6 Luna (August), respectively, except for a regression on the extremism vision evalu

    匹配字段正文

  19. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-6 Astra 系统卡

    OpenAI 发布 GPT-6 Astra 系统卡,宣布这是其迄今能力最强、已广泛部署的模型,也是首个在 Preparedness Framework 下达到网络安全 Critical 等级的模型。系统卡称 Astra 对越狱和提示注入的鲁棒性显著强于 GPT-5.6 Sol,间接提示注入鲁棒性从 96.23% 升至 99.79%,在 54,218 个内部 Codex 任务模拟中严重度 3 级及以上的错位行为标记减少约 53%。同时 OpenAI 指出 Astra 的 CoT 可监控性相对 GPT-5.6 Sol 下降,在对抗条件下可能规避内部监控,因此将错位监控扩展到全部工具调用推理。

    Figure 1

    des performance information for GPT-6 Astra on the new, updated versions; September 29, 2026: We added an Appendix: dots with information about dots, remarkably capable, always-on agents built to handle everything. Dots are built on existing model and agent capabilities, powered by GPT-6 Astra 1. Safety Overview: GPT-6 Astra Today, we are releasing GPT-6 Astra, the most capable model we have ever broadly deployed. Astra is our first model to reach the Critical level of cybersecurity capability u

    匹配字段正文

星期一

  1. Artificial Analysis 完整文章精选

    Meta 发布 Muse Wonder 与 Muse Wonder Full,智能指数最高升至 56

    Meta 发布 Muse Wonder 和 Muse Wonder Full,在 Artificial Analysis Intelligence Index v4.3 最高推理强度下分别得分 52 和 56,高于 Muse Spark 1.3(max)的 48,发布间隔仅 6 周。Muse Wonder Full(max)在十项评测中全面超过 Muse Spark 1.3(max),智能体类提升最大,Terminal-Bench 4.0 从 33% 升至 57%,GDPval-AA v2.1 从 1681 Elo 升至 1857。Muse Wonder 已在 Meta 一方 API 和 Muse Code 上线,Muse Wonder Full 仅面向 Muse Code 用户,两者上下文窗口均为 1M tokens。

    e for users on Meta's first-party API, while Muse Wonder Full is currently only available for Muse Code users. Meta notes that each model is designed for personal and professional agent use Key takeaways: ➤ Both models exhibit a material jump in overall Intelligence Index score. Muse Wonder Full (max) improves on Muse Spark 1.3 (max) across all ten Intelligence Index evaluations, gaining 8 points to 56. The largest gains were seen in agentic evaluations: Terminal-Bench 4.0 (+24 points, 33% to 57

    匹配字段正文