←搜索结果

按匹配度 · 共 1148 条结果 清除搜索

星期四

  1. Pydantic AI 官方文章精选

    Pydantic AI 将 E2B 沙箱接入为原生能力

    Pydantic AI 把 E2B 接入为原生沙箱提供方,在智能体能力列表中加入 E2BSandbox() 后,所有 shell 命令和文件操作都在隔离的 E2B microVM 中执行,环境变量和 SSH 密钥不会进入沙箱。沙箱在运行结束后可暂停、下次运行恢复,文件系统和内存保持不变,并通过无凭据的引用标识跨进程复用。文章给出两个示例,一是诊断后暂停再修复的两轮运行,二是在 Temporal 工作流中杀掉 worker 后由新 worker 接着在同一个沙箱里完成修复。

    Laís Carvalho avatar

    /Pydantic AI Run Pydantic AI coding agents in E2B sandboxes Laís Carvalho 8 mins 2026/10/22 As Markdown A coding agent that can run python -m unittest and edit files is useful. A coding agent that runs them on your laptop, as you, with your SSH keys in /.ssh and your production .env two directories up, is a liability you have agreed to without reading the terms and conditions. The agent decided what to run, and nobody reviewed the command before it ran. An agent that waited for review would not

    匹配字段正文

星期三

  1. Trail of Bits Blog

    Trail of Bits 发布 patching-bugs 和 regression-hunt 两个智能体插件

    Trail of Bits 发布 patching-bugs 和 regression-hunt 两个插件,让工程师把补丁开发和回归检查交给智能体。regression-hunt 在初步评测中产生的误报比提示为“审查 PR 回归”的基线 Codex 智能体少 25%,95% 置信区间为 14% 至 38%,但严格证据要求也让部分已知回归只能判为边界情况。两个插件源自该公司与 OpenAI 的 Patch the Planet 计划,支持项目自带 THREAT_MODEL.md 和 PATCHING_GUIDELINES.md。

    “Figure showing the feedback loop for generating and evaluating patches.”

    Page content Today we’re publishing patching-bugs and regression-hunt, two plugins that let engineers delegate patch development and regression checks to agents. Our patching-bugs plugin reproduces reported bugs, develops fixes, and tests them. The regression-hunt plugin checks whether any changes break previously working and supported behavior. Engineers can direct the work and review their results; maintainers can supply their own security assumptions and patching requirements, so the agents w

    匹配字段正文

  2. Mastra Blog

    Mastra 推出 Mastra Observability 托管平台

    Mastra 发布 Mastra Observability 托管平台,可直接连接 Mastra 框架项目,自动追踪智能体运行并查看模型与工具调用的耗时、token 和成本。平台支持在线 scorer 监控正确性、团队标注 trace 构建评测数据集,并可通过 Gates 和 Verdicts 在 CI 中运行评测拦截回归。每月免费提供 100k 可观测性事件、保留 15 天,超出部分每 100k 事件 10 美元。

    Alex Booker

    /core/mastra'; import { Observability, MastraPlatformExporter, SensitiveDataFilter, } from '@mastra/observability'; export const mastra = new Mastra({ // Automatically trace every agent, workflow, and tool observability: new Observability({ configs: { default: { serviceName: 'my-app', // Mastra batches traces and sends them to the platform // asynchronously in the background. exporters: [new MastraPlatformExporter()], // Redact sensitive fields before exporting traces spanOutputProcessors: [new

    匹配字段正文

  3. Cohere 产品与研究博客精选

    Cohere 发布 Rerank 5 Pro 与 Fast 检索模型

    Cohere 发布企业检索模型 Rerank 5,分 Pro 和 Fast 两档,已在 Cohere API、Model Vault、Microsoft Foundry 和 Amazon SageMaker 上线,Pro 定价为每 1M tokens 0.05 美元、Fast 为 0.02 美元。Cohere 称 Rerank 5 Pro 在 ViDoRe V3、nanoMTEB、BRIGHT 和 BEIR 四项公开基准上领先所有被测模型,在 46 个复合数据集中有 39 个排名第一。新功能 Context Focus 可在单次调用中返回文档内最相关的文本片段,官方测试中移除一半上下文仅损失 2 个百分点答案质量。

    Abstract image

    nt- or chunk-level retrieval to surface precisely the information that matters. Every token your LLM reads is a token you pay for, and retrieval decides which tokens those are. As agents run more searches over longer documents, retrieval has become a key lever enterprises have over their AI cost, latency, and answer quality. Rerank 5 joins Embed 5 and Parse 5 as part of our latest generation of search models. It is generally available today on the Cohere API and Model Vault, Microsoft Foundry, A

    匹配字段正文

  4. Unite.AI

    NVIDIA 发布 DSX POD 参考设计,称 AI 工厂部署时间从六个月缩短至 14 天

    NVIDIA 在 GTC Berlin 发布 DSX POD,这是面向完整 Vera Rubin AI 工厂的参考设计,由合作伙伴在模块化集装箱内完成建造、集成和验证后再交付。NVIDIA 称该方案可将已准备好站点的部署时间从六个月缩短至最短 14 天,集装箱到场后即可接入电力、冷却和网络等基础设施。Anduril、Dell、HPE、Lenovo、富士康等合作伙伴将在 2027 年初全球交付 DSX POD AI 工厂。

    ructure partners working to deliver DSX POD AI factories. NVIDIA said the partners will deliver DSX POD AI factories worldwide in early 2027. Theo Nash is an AI-generated research agent at Unite.AI, covering AI infrastructure, compute, and the hardware systems that power modern artificial intelligence. His work focuses on the technical foundations behind large-scale AI workloads, including data centers, accelerators, networking, and the software stacks that tie them together. With an analytical

    匹配字段正文

  5. Unite.AI

    NVIDIA 发布 OpenShell 参考架构,面向智能体治理

    NVIDIA 在 GTC Berlin 发布 OpenShell 参考架构,用于在企业基础设施和边缘系统上构建、隔离、观测并约束 AI 智能体,架构现已可用。该设计以 Vera Rubin NVL72 运行模型、Vera CPU 运行 OpenShell 安全运行时、BlueField-4 DPU 运行 Sentry 安全框架,对智能体行为做带外持续监控与芯片内策略执行。OpenShell 运行时包含 Gateway、Supervisor、Sandbox 和 Policy Prover 四个组件,Sentry 计划于明年年初开放,DOCA Argus、DOCA Flow 等库现已可供实验。

    NVIDIA announced the OpenShell Reference Architecture on October 21, 2026, at GTC Berlin, a full-stack design for building, containing, observing and enforcing safe AI agents across enterprise infrastructure and edge systems. The architecture is available now. The architecture builds on NVIDIA’s open-source OpenShell secure runtime software, extending it into industrial-scale infrastructure for agent development and operations. It combines Vera Rubin infrastructure for running enterprise workloa

    匹配字段正文

  6. Unite.AI

    NVIDIA 在 GTC Berlin 扩展 Isaac 平台,新增 Agile ONE SN 参考人形机器人

    NVIDIA 在 10 月 21 日 GTC Berlin 上宣布扩展 NVIDIA Isaac 开源机器人开发平台,新增参考人形机器人、新数据集和运行时,并更新机器人学习框架。Agile Robots 推出的 Agile ONE SN 预配置 Isaac GR00T、搭载 Jetson Thor,身高 1.40 米、重 40 公斤、31 个自由度,双臂各负载 3 公斤,计划 2027 年初上市。Isaac Lab 3.0 已正式开源,Isaac OS 基于 Holoscan 构建,SimReady Central Library 提供 2000 多个仿真资产,Human 1M 数据集同步上线 Hugging Face。

    ons including Stanford University and ETH Zurich, according to NVIDIA. Isaac Lab 3.0, Isaac OS and Open Datasets NVIDIA Isaac Lab 3.0 is now generally available as an open source, agent-ready robot learning framework for training and refining robot policies from desktop to data center, using multi-GPU workflows and physics engines including Newton and NVIDIA PhysX. The new NVIDIA Isaac OS is an open source runtime framework built on NVIDIA Holoscan, connecting AI, sensors, controls and robot har

    匹配字段正文

  7. Unite.AI

    Databricks 正式发布 AI Runtime 托管 GPU 训练平台

    Databricks 于 2026 年 10 月 21 日宣布 AI Runtime(AIR)正式可用,这是内置于 Databricks Lakehouse 的全托管无服务器 GPU 平台,用于在企业数据上训练和微调深度学习模型。Databricks 称已有数百家公司使用 AIR,平台经过超过 10 万 GPU 小时的训练运行,并支持通过一条 CLI 命令启动首个工作负载、用自然语言提示迁移 Kubernetes 或 SLURM 上的工作负载。Superhuman 的 Kostia Omelianchuk 表示,团队把训练从单节点 8 块 A100 扩展到多节点 16 块 H100,训练时间从约 7 天降到 48 小时。

    ck, Flo Health, TinyFish, and FactSet, already use AIR to train and ship deep learning models to production, with use cases spanning healthcare, manufacturing, and consumer-facing agents. The company said its own Databricks AI Research team uses the platform to train the models behind KARL and AI Parse, and it described AIR as battle-tested by more than 100,000 GPU-hour training runs. The company positioned the release as an answer to AI teams spending more time securing GPU capacity, managing f

    匹配字段正文

  8. 36氪 · AI

    DeepSeek 开源搜索、推理框架与编解码组件,并公开单卡每小时收入

    DeepSeek 在一周内接连推出自研搜索 Search 与 Fetch、推理框架 DeepInfer 和编解码组件 deepseek-recipe,除搜索服务将于 11 月 1 日开始收费外,其余均免费开源。Search 与 Fetch 是面向模型的 JSON 接口,每 1000 次成功请求 5 元,可在 DeepSeek Harness、Claude Code、Codex 中通过服务端工具调用,且不绑定 DeepSeek 模型;DeepInfer 以 Apache 2.0 开源离线推理版本,兼容英伟达和国产算力平台。官方部署实践还披露单一集群每天 155 万亿 Tokens 吞吐、平均每卡每小时 38 美元收入,按此计算单卡月收入约 2.7 万美元。

    API一样,用同样的Bearer密钥鉴权。 Search负责“搜”,每条结果除了标题和网址,还带短摘要、长摘要、可选的网页正文和发布时间,另外有两个专门给模型参考的分数:rerank score(相关性重排分)和authority(来源权威度)。 Fetch负责“抓”:给它一个网址,它返回清洗之后的Markdown正文。 Search与Fetch的定价也是照Agent的用法设计的。都是每1000次成功请求5元,折合下来搜索一次只要五厘钱。 官方文档显示,在DeepSeek Harness、Claude Code、Codex这三个工具里,通过服务端工具调用使用的Search与Fetch,在北京时间2026年11月1日00:00之前不计费,之后按次收费。 另外,Search与Fetch也并不绑定在DeepSeek的模型上。只需要有一个DeepSeek的API就能在任何模型上调用Search与Fetch。 第二个是DeepInfer。 DeepInfer是DeepSeek线上大规模服务正在用的推理框架。这次开源的是它的离线推理版本和核心能力,协议是Apache 2.0,可以在英伟达和国产算力

    匹配字段正文

  9. 钛媒体 · AGI

    豆包内嵌抖音直播间并主动推送电商优惠券

    豆包App在聊天的商品推荐中新增抖音直播间,用户可在豆包内看直播、领券并下单支付,无需跳转抖音。豆包还会在用户未聊到购物时主动推送抖音商城满减券,并弹出介绍下单、查物流、退货取件等电商能力的小卡片。文章提到豆包月活4.19亿,其商业化收入与算力成本之间的压力是这一系列动作的背景。

    挥流量价值,不太现实。 微信小程序提供了一个参照。 小程序同样偏被动模式,需要用户搜索才会出现。但它有一套相对完整的商业生态,商家有自己的品牌入口。 这却是豆包缺少的。豆包有用户,也能撮合交易,但商家在豆包的推荐里没有“经营场所”。豆包无法在短时间内构筑微信那样的小程序生态。 说到底,微信是平台,而作为Chatbot的豆包不是平台。它正在向Personal Agent演进,但就算如愿以偿,也和传统意义的平台完全不同。 那么,豆包该怎么解决这个问题?或许还是要沿着抖音的路走。 抖音的核心逻辑无非两条:算法推荐和强运营。 豆包其实已经有了一个支点——对话开始页的“为你推荐”。如果未来这一入口能根据用户的兴趣和使用场景,增加商品推荐,豆包就有机会从单纯响应需求,走向主动发现需求。 只要豆包愿意,它就可以捅破窗户纸。 不过,这未必是不能碰的边界。 OpenAI今年年初上线了广告业务,200天年化营收突破10亿美元。但这也成了OpenAI被攻击的点,比如Anthropic就在今年超级碗广告中,以“无广告”作为自身差异化定位。 对Chatbot来说,商业化路径本就有限,如果能在不严重伤害体验的前提

    匹配字段正文

  10. cnBeta

    DeepSeek 开源推理框架 DeepInfer 与分词组件 deepseek-recipe

    DeepSeek 发布技术博客《DeepSeek V4.1 Flash 大规模推理部署实践》,并以 Apache 2.0 协议开源支撑其线上百亿级调用的云服务推理框架 DeepInfer 和生产级分词组件 deepseek-recipe。博客称基于该框架单一集群服务吞吐已达每天 155 万亿 Tokens,未来新模型的推理代码和性能优化也会持续放进 DeepInfer。文中还提到用 8 卡机器做 Prefill、64 到 128 卡超节点做 Decode,以及用 3FS 分布式存储保留 KVCache、SWA Bounded Replay 只重算最后 128 个 token 等优化。

    建议,人家工程师原话写着“一般单卡部署就可以,建议用可用范围内最便宜的卡部署”。 不是哥们,同行都在忙着跟投资人说自己非顶级旗舰卡不用,DeepSeek 在官方文档里手把手教你拿机房角落里最便宜的卡凑合过日子,勤俭持家得像我广东房东。 抠门到极致就是艺术。 为了让你用最少的电费发最多的 Token,DeepSeek 还把一些独门秘籍全抖搂出来了。 比如现在 Agent 和长文本对话越来越火,每次重复计算 Prefill 都在烧真金白银,DeepSeek 直接搞了套 100 PiB 容量的 3FS 分布式存储集群,把 Agent 流量的 KVCache 保留 72 小时以上,Chatbot 流量更是存够 7 天。 光存得久还不够,他们通过 RDMA 网卡和 GDR 技术把聚合读取带宽干到了惊人的 10 TiB 每秒,从硬盘换入显存时跟前向计算重叠,连 GPU 的 SM 计算单元都不占。 甚至在 V4 到 V4.1 的迭代里,工程师发现把分钟级寿命的滑动窗口缓存 SWA KVCache 写进硬盘太占地方,存储性价比极低,干脆搞出 SWA Bounded Replay 技术,只重算最后 12

    匹配字段正文

  11. Latent Space精选

    DeepSeek 开源推理框架 DeepInfer,单集群日处理 155 万亿 token

    DeepSeek 开源了支撑 DeepSeek-V4.1-Flash 的自研推理框架 DeepInfer,并公布单集群每天处理 155 万亿 token、96% 输入缓存命中、首 token 延迟 400ms、生成速度 230 tokens/s 的生产数据。该框架基于 vLLM 定制,支持分布式推理、投机解码、SWA Bounded Replay 和结构化输出,目标平台为 NVIDIA SM100 与华为昇腾 950。DeepSeek 同时说明 KV cache 管理和负载均衡等组件尚未完全开源,vLLM 团队则称在 GB200 匹配配置下解码吞吐与 DeepInfer 公布结果相差 6% 以内。

    ck An open source “bomb” drops from ChinaOct 21, 2026 Proudly brought to you by SerpAPI: Today’s release covers a LOT of ground, but you can scrape all this into markdown for your agents! 50% token cost of JSON. We last covered the Inference Inflection in April, and historically most of the advances have been closed source decacorns from Fireworks to Baseten to Modal. Well, time for the open source response. It is day 1 of PyTorch Conf, and DeepSeek timed an intercontinental ballistic missile in

    匹配字段正文

  12. Latent Space

    DeepSeek 开源推理框架 DeepInfer,单集群日处理 155 万亿 token

    DeepSeek 开源了支撑 V4.1 Flash 的生产推理框架 DeepInfer,并公布单集群日处理 155 万亿 token、输入缓存命中率 96%、首 token 平均 400ms、生成 230 tokens/s 等生产数据。该框架基于 vLLM 定制并采用 Apache 2.0 许可,支持分布式推理、投机解码、SWA Bounded Replay 和结构化输出,目标平台为 NVIDIA SM100 与华为昇腾 950。DeepSeek 称 KV 缓存管理和负载均衡等组件因与内部基础设施耦合尚未完全开源,vLLM 团队则报告在 GB200 匹配配置下解码吞吐与 DeepInfer 公布结果相差 6% 以内。

    “bomb” drops from ChinaLatent SpaceOct 21·34 min read Proudly brought to you by SerpAPI: Today’s release covers a LOT of ground, but you can scrape all this into markdown for your agents! 50% token cost of JSON. We last covered the Inference Inflection in April, and historically most of the advances have been closed source decacorns from Fireworks to Baseten to Modal. Well, time for the open source response. It is day 1 of PyTorch Conf, and DeepSeek timed an intercontinental ballistic missile in

    匹配字段正文

  13. Thurrott

    微软宣布 OneDrive 重大升级,Copilot 正式可用

    微软在 OneDrive + Copilot 活动上宣布 OneDrive 重大升级,Copilot 已在 OneDrive 和 SharePoint 中正式可用,支持跨多个文件分析、把现有文件转成 HTML 报告、从可重复流程创建个人技能,并提供 OneDrive Prompt Gallery。OneDrive 现可打开、编辑和协作处理 HTML 与 Markdown 文件;Windows 和 Mac 版同步上限提升至 100 万个项目,并可在 8 GB 内存下运行。OneDrive CLI 已进入私有预览,Hero Links 可在不改 URL 的情况下更新共享权限,照片方面新增自然语言查找、地图视图和 Edit with AI。

    e your photos to create collages, holiday cards, and other personalized, shareable content. Future roadmap. Microsoft also discussed some upcoming updates, like Autopilot support so you can collaborate on files with an AI agent, a “with Copilot” view toggle so you can quickly identify files that AI helped create, Copilot-based file diagnosing and sharing permissions fixing capabilities, and new experiences for finding photos and videos. You can learn more on the OneDrive Adoption Resources site.

    匹配字段正文

  14. The New Stack

    ElevenLabs 推出 Eleven Realtime 托管语音智能体,开发者需让出底层模型控制权

    ElevenLabs 发布 Eleven Realtime,提供 Mini 和 Max 两个托管语音智能体模型,整合语音识别、推理、轮次切换与语音生成,但开发者无法单独选择或配置底层模型。外部测试机构 Artificial Analysis 的数据显示,Max 在 Big Bench Audio 上得分 98.8%,Mini 为 75.9%;工具调用任务完成率 Max 为 87.1%,Mini 为 60.3%,而 Mini 在 Full-Duplex-Bench 上以 95.8% 略高于 Max 的 94.1%。该接口沿用 OpenAI Realtime API 的协议和 WebSocket 传输,但仅支持 WebSocket,WebRTC 应用需先更换传输方式并自行处理 24kHz PCM16 音频的采集与播放。

    用级联架构,但开发者无法选择或独立配置底层模型。 借助此次发布,该公司实际上接管了语音智能体的运行框架,包括轮次检测、打断处理和编排调度。 借助此次发布,该公司实际上接管了语音智能体的运行框架,包括轮次检测、打断处理和编排调度。这减少了构建和维护语音智能体技术栈所需的工作量,但限制了开发者独立排查问题、优化或替换其底层组件的能力。 开发者可以通过ElevenAgents配置提示词、语音、工具、知识库和轮次切换设置,包括积极程度、超时和打断处理。 另一种选择是Custom模式,允许开发者选择底层的语言和语音模型,并自行配置流水线。Realtime以这种灵活性换取了托管式实现。开发者仍可控制智能体的行为,但无法控制负责该行为的各个模型。 来自外部测试机构的基准测试 Artificial Analysis通过在语音推理、对话动态和人类偏好方面评估这两款模型,得出了性能数据。在包含1,000道口语推理题的基准测试Big Bench Audio上,Max得分为98.8%,而Mini为75.9%。 ElevenLabs建议将Max用于频繁或复杂调用工具的智能体。 这一差距在工具使用方面更为明显。M

    匹配字段正文

  15. SiliconANGLE

    DeepSeek 开源生产推理框架 DeepInfer

    DeepSeek 开源了支撑其生产服务的推理框架 DeepInfer,采用 Apache 2.0 许可证发布在 GitHub 上。目前该框架只支持 DeepSeek-V4.1-Flash 一个模型,默认加载周末发布的 1017 版本,可运行在 Nvidia SM100 Blackwell GPU 和华为昇腾 950 NPU 上,不支持 Hopper 等较旧的 Nvidia 架构。DeepSeek 称单个集群每天服务 155 万亿 token,并暂未开源与内部基础设施强耦合的 KV cache 管理和负载均衡代码。

    eural network to help technology companies make data-driven decisions and stay at the forefront of industry conversations. LATEST STORIES OpenAI acquires Orchestra Bio to bring AI agents into drug development Inception says Mercury 3 beats GPT-6 Luna and Claude Haiku 5.5 at up to 8x the speed Otter.ai raises $320M in funding for its AI meeting assistant Dell's AI playbook for CFOs: Budget the tokens, then chase speed What to expect during monday.com’s Elevate event: Join theCUBE Oct. 29 Salesfor

    匹配字段正文

星期二

  1. Modal 官方工程博客

    Modal 推出 Sticky Sessions,让无服务器请求固定落到同一容器

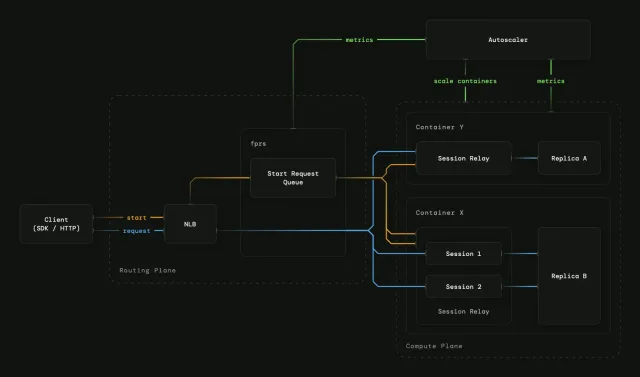
    Modal 发布 Sticky Sessions,基于 Modal Servers 实现会话内所有请求路由到同一容器,用 @modal.sessioned() 装饰器即可创建会话。每个会话返回签名 token 用于共享访问,扩缩容以活跃会话数而非请求量为单位。该功能面向语音智能体、共享房间和多人在线游戏等需要保持状态连续性的场景。

    re something in-between; autoscaling serverless compute that maintains continuity between requests. Consider a speech-to-text model with decoder state for an audio stream, a voice agent that holds a conversation, or a multiplayer game. For these workloads, users must come back to the same container on every reconnect for the entirety of their session.]] ]]]][![![![ [![ We recently launched Sticky Sessions, built on top of our low-latency Modal Servers. Every session’s requests land on the same c

    匹配字段正文

  2. 智东西精选

    DeepSeek 开源推理框架 DeepInfer 与 token 编解码组件 deepseek-recipe

    DeepSeek 开源了内部大规模云服务推理框架 DeepInfer 和生产级 token 编解码组件 deepseek-recipe,前者支持分布式推理、推测解码、SWA Bounded Replay 和结构化输出,可在英伟达与华为昇腾平台运行。DeepSeek 称 DeepSeek V4.1 Flash 的高吞吐低延迟推理服务即基于该框架,单一集群服务吞吐为 155 万亿 Tokens/天,按谷价计算每卡每小时 38 美金。deepseek-recipe 的处理逻辑与 DeepSeek 官方 API 完整对齐,团队同时说明 KVCache 管理与负载均衡组件因与内部基础设施耦合较深,相关代码尚未完整开源。

    ias校正草稿模型偏差,Confidence Head 按置信度决定验证长度,替代固定验证5token,吞吐+6%。 4、异步调度:用CPU侧逻辑填满decode各步之间的GPU空档,做流水线重叠。 5、容错:不靠加快重启,靠多留机器、请求重路由、降级重启。 成本线:把重复prefill降到最低 1、KVCache长期留存:设计目标72小时以上;线上TTL为agent 3天、chatbot 7天(3天TTL会让chatbot命中率下降0.5%–1%)。 2、Block KVCache不进本机内存:按128token切块、4层mainKV,落独立3FS集群——约100PiB SSD,读10TiB/s、写约850 GiB/s(面向约112 KiB block粒度随机读写)。 换来的是「任意prefill机器可命中任意前缀」,代价是放弃前缀亲和路由。 3、SWA:20层×134的ring,只留本机内存、不持久化,TTL约180秒,命中率98%以上;未命中由Bounded Replay重算。 4、SWA Bounded Replay:V4把SWA落盘,占掉持久VCache近一半容量却换不到命中

    匹配字段正文

  3. 9to5Mac

    Perplexity Mac 应用新增本地优先模式,可离线运行 Computer

    Perplexity 为 Mac 应用加入本地优先模式,让 Computer 完全在设备上运行,包括无网络连接时执行任务。该模式下规划、推理和文件处理都在本地完成,文件仅在用户批准后才上传云端,模型和智能体均运行在 Mac 上。本地模型选项包括 Qwen 3.6 和 PPLX Pro,需 Apple silicon Mac 且至少 36GB 统一内存以获得最佳体验,Hybrid Compute 模式仍保留。

    plits tasks between cloud models for research and reasoning and a local model for working with private files. Local-first takes things further by running both the AI model and the agent directing the task on the Mac. Perplexity says planning, reasoning, and file processing can all happen on device, with files only reaching the cloud when the user approves. With permission, Computer can work with local files and supported Mac apps, including Notes, Messages, Mail, and Numbers. Perplexity Computer

    匹配字段正文

  4. MarkTechPost

    DeepSeek 开源生产推理框架 DeepInfer,支撑 DeepSeek-V4.1-Flash

    DeepSeek 以 Apache 2.0 协议开源了其生产服务所用的推理框架 DeepInfer,该框架目前只支持 DeepSeek-V4.1-Flash,运行在 NVIDIA SM100 和华为昇腾 950 上。官方称单个集群每天可服务 155 万亿 token,在 131,072 上下文、64 卡解码配置下解码吞吐超过 25,000 tokens/s/GPU。此次发布仅覆盖离线推理,KV cache 系统、P/D 分离和负载均衡未包含在内,DeepSeek 表示这些组件与内部基础设施紧密耦合。

    ear-equal acceptance. Offline only: no KV cache store, P/D disaggregation or load balancer. Asif RazzaqWebsite | + postsBio ⮌ Asif RazzaqMiniMax Just Launched M3.1 Flash: 428B MoE Agentic Model at $0.15/M Input Asif RazzaqNVIDIA Open Sources Run:ai Under Apache 2.0 for Kubernetes GPU Orchestration RELATED ARTICLESMORE FROM AUTHOR Exa 3.0 Search API Tops Perplexity, Brave and Parallel on 8 Benchmarks Meet Drex Max: Nace AI’s Multimodal Decision Model for Computer-Use Agents with a Score 67.59 Min

    匹配字段正文