←搜索结果

按匹配度 · 共 1146 条结果 清除搜索

星期三

  1. 腾讯混元精选

    腾讯混元 Hy3 上线 WorkBuddy 全球版,免费开放至 2026 年 8 月 31 日

    腾讯混元宣布 Hy3 已在 WorkBuddy 全球版上线,面向全球用户免费开放至 2026 年 8 月 31 日(PT)。用户可在智能体 AI 工作台中完成研究、数据分析、文档与演示文稿制作以及职场沟通,无需额外配置。Hy3 同时可通过腾讯设计 Miora 和腾讯云 TokenHub 使用。

    🚀 Hy3 is now live in WorkBuddy global—free for users worldwide through August 31, 2026 (PT). Research, analyze data, create documents and presentations, and handle workplace communications in an agentic AI workspace—no setup required. Hy3 is also available through Tencent Design Miora and Tencent Cloud TokenHub. TencentHy Hy3 WorkBuddy Miora TencentCloud

    匹配字段正文
星期二

  1. Microsoft Research精选

    微软研究院开源 Orchard 智能体框架,并发布三个领域训练方案

    微软研究院推出开源框架 Orchard,核心是 Orchard Env,一个基于 Kubernetes 的轻量环境,可并行创建、管理和移除数千个隔离组件,用于数据收集、强化学习 rollout 和评估。团队同时发布 Orchard-SWE、Orchard-GUI、Orchard-Claw 三个领域训练方案及训练数据与评估方法。Orchard-SWE 在 SWE-bench Verified 上从 61.4% 基线提升至 69.7%,加入价值模型重排序后达到 73%;Orchard-GUI 训练 4B 参数视觉语言模型,在 WebVoyager、Online-Mind2Web、DeepShop 上平均 68.4%。

    Alongside the models and workflows, the project releases training data and evaluation methods intended to help the broader research community build and study open agentic systems. Artificial intelligence is rapidly moving beyond static question-answering toward autonomous agents that can plan, reason, and act across complex, multistep environments. These systems can fix bugs in complex codebases, navigate the web on a user’s behalf, and manage workflows involving calendars and email. While there

    匹配字段正文

星期一

  1. OpenRouter:Announcements

    OpenRouter 发布 Ori Eval,为你的项目自动挑选最合适的模型

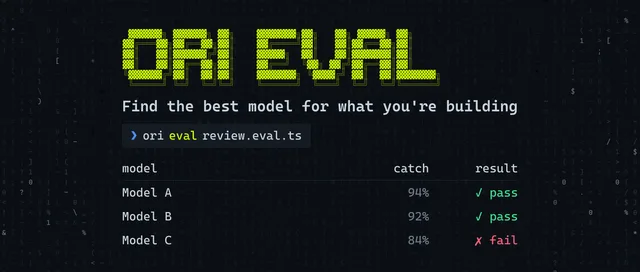
    OpenRouter 发布 Ori Eval,一个面向产品内模型的评测工具,可让编码智能体扫描代码库中调用模型的位置,确认成本、性能、延迟、工具调用准确率等偏好后,从最新模型中选出 5 个候选并生成 review.eval.ts 文件,用 bun test 并行跑评测并给出带理由的推荐。评测文件会检查智能体调用了哪些工具、避开了哪些工具以及答案质量,开放式回答由 LLM-as-a-judge 按设定标准打分。单次评测通常花费 10 到 30 美元,可接入 GitHub Actions,评测失败即构建失败,也可定期重跑并在新模型更优时自动开 PR。

    Ori Eval: Find the Best Model for What You're Building

    friendly and experienced engineering friend - no eval experience needed. Tl;dr Ask a question, get an answer (with proof) To use Ori Eval, you can simply tell your favorite coding agent: Your agent hands the request to Ori Eval. Ori Eval explores your codebase, and it comes back with questions. Before it runs any evaluations, it works with you to help figure out what’s important to you — is it cost, performance, latency, speed, tool call accuracy, etc. It then chooses the 5 latest models that fi

    匹配字段正文

星期日

  1. Sakana AI:Blog

    Sakana AI 推出日语特化 LLM API「Sakana Namazu」

    Sakana AI 发布日语特化 LLM API「Sakana Namazu」,基于 Moonshot AI 的开源模型 Kimi K2.6,用自有数据适配日语与日本业务语境,并内置 Web 搜索和代码执行工具。该 API 兼容 OpenAI 接口,已有代码只需改写 base_url 并设置 API 密钥即可接入。基准方面,它在 JFBench、日英翻译任务和 FairPoliticsQA 上均超过基座模型,其中 FairPoliticsQA 从 34.10% 提升至 56.30%,同时保持 Kimi K2.6 在 AIME26、MMLU-Pro、LiveCodeBench v6 上的推理与编码表现。

    ting the model since Sakana Chat first launched, and this version improves on earlier ones both in the quality of its Japanese responses and in its ability to carry out work as an agent. For the technical background at the time of the Sakana Chat release, see this blog. Why we built it Ever since Sakana Chat launched, we have heard the same request many times over: people wanted to use this model from their own products and workflows through an API. At the same time, the choice of LLM APIs that

    匹配字段正文

星期五

  1. The Register

    ShieldFont 开源字体用同词性替换向 AI 爬虫投毒

    阿姆斯特丹设计工作室 Seneda & Abrucio 与哥本哈根字体公司 Playtype 合作推出开源项目 ShieldFont,通过扩展 OpenType 的 GSUB 字形替换表,让网页在人类眼中正常显示、而爬虫读取的原始 HTML 中约四分之一词汇被替换成同词性同语义类别的其他词,从而向训练数据注入难以分辨的噪声。项目已提供在线编码器、React 组件以及 CSS 和 CDN 集成方式,桌面字体约 5 MB、压缩网页字体约 800 KB,并附带三套 GSUB 字典且支持自建字典以防逆向。团队承认它可被 OCR 截图、下载字体跑字典等方式绕过,也可能影响 SEO、翻译应用、系统复制粘贴和屏幕阅读器,目前处于 v0/alpha 阶段。

    e testing Anthropic took more than two months to alert cops; AI systems are fully capable of carrying out nightmare attacks against infrastructure and nobody's ready Meanwhile, AI agents move robotic arms, 'make OT device operator screens lie'; Nvidia found $1B under the couch to help secure American scientific computing dominance Commitment comes as GPUzilla prepares to fortify Uncle Sam's arsenal with at least seven AI-optimized supers; TSMC taps GlobalFoundries to bolster US silicon interpose

    匹配字段正文

星期四

  1. Microsoft AI Blog精选

    微软发布 MAI-Cyber-1-Flash,并披露 MAI 系列模型降本数据

    微软发布针对 MDASH harness 优化的 MAI-Cyber-1-Flash,在 CyberGym 上取得 96% 的 any crash 分数,成本为当前 MDASH 最佳方案的 50%,并可在 H100 上部署。该模型设计用于高效处理最多 90% 的任务,把 GPT 5.4 等最贵模型留给 10% 的极难问题。微软同时披露上季度已交付十余个覆盖图像、语音、转写、编码和安全的新模型,其中 MAI-Image-2.5-Flash 在 PowerPoint 中相比 GPT-Image-2 降低最多 84% 的 GPU 成本,MAI-Voice-2-Flash 在 Dynamics 365 Contact Center 中降低最多 89% 的 GPU 成本。

    Nine app icons, including mail, JetBrains, GitHub, PowerPoint, Excel, Visual Studio Code, and Microsoft OneDrive, displayed in a row on a blurred green and pink gradient background with dotted lines.

    y 26% and delivers up to 2.5x greater token efficiency; MAI-Voice-2-Flash now powers Dynamics 365 Contact Center, where customers like T-Mobile and EasyJet build their call center agents, reducing GPU costs by up to 89%; MAI-Transcribe-1.5 now serves Dragon Copilot’s multilingual workflow across 58 languages — a solution used by 170,000 medical providers that processed 28 million patient encounters last quarter, where our tests show a 50% relative in reduction transcription and language-identifi

    匹配字段正文

  2. Replit Blog精选

    Replit 发布 Replit Design 设计套件

    Replit 发布 Replit Design 创意设计套件,面向所有用户开放,可从想法直接生成设计并发布,无需导出或重建。该套件支持 Claude、GPT-5、Gemini、Kimi、GLM 等模型,内置 Ambient Intelligence 逐步给出可一键采纳的变体建议,并集成 Mobbin 的 60 万张真实界面素材与 1000 多个应用参考。Replit Design 是 Canvas 的下一代演进,原有 Canvas 项目全部保留,官方同时启动奖金超过 5 万美元的 Designathon 活动。

    Introducing Replit Design — cover image

    ter if based on advanced heuristics or a small model that reads each turn and picks which LLM to use, a router will always be less capable than the model it’s choosing for. Replit Agent lets the model decide instead. The main agent, or core loop, chooses its subagents’ tier and effort, and adjusts its own as the task unfolds. Given that freedom, GPT-6 Astra hands routine implementation to less costly subagents and decides for itself where its tokens are worth spending. On both DeepSWE and Termin

    匹配字段正文

星期三

  1. The Register

    Perplexity 将 Model Council 扩展至 Computer 平台,最多可选 8 个模型

    Perplexity 周二把上线五个月的 Model Council 扩展到云端 Computer 平台,用户可选 2 到 8 个模型组成顾问团,模型各自独立作答后由用户选定的模型担任主席,综合出报告并标出结论一致与分歧之处。该功能此前仅限企业版和 Max 用户,现在也向个人 Max 和 Pro(20 美元/月)用户开放,可选模型涵盖 OpenAI、Anthropic、Google 以及 GLM、Kimi 等开放权重模型。Computer 采用按量计费,100 credits 等于 1 美元,Pro 用户获 4000 赠送 credits,Max 用户获 35k 及每月续期的 10k。

    re their conclusions agree and diverge. According to Perplexity comms chief Jesse Dwyer, Model Council functions as a skill that tells an orchestrator model to spin up parallel subagents, each acting as a full agent harness and tackling the problem independently. “A wait barrier holds until every perspective finishes, then the model the user selected acts as the ‘chair,’” Dwyer told us in an email. “It reads all the perspective outputs and synthesizes them, explicitly surfacing where the models

    匹配字段正文

星期一

  1. Mastra Blog

    Mastra 发布 Mastra Factory,让智能体从 issue 推进到生产

    Mastra 发布 Mastra Factory,一套让智能体把软件从 issue 推进到生产的系统,可连接 GitHub、Linear 和 Slack,用户在工厂界面点击开始后由编码智能体接手。该系统在 intake、triage、planning、building、review、completion 各环节设置显式门禁,并提供类型化工作流、记忆、调度、工具和可观测性来保证过程可治理、可审计。Mastra 称其此前在 issue 接收和 PR 评审上存在瓶颈,为此构建了理解 PR 与 issue 的技能以及提供代码库上下文的评审智能体。

    Sam Bhagwat

    Announcing Mastra Factory From issue to production, run by agents.Sam Bhagwat· Jul 27, 2026· 2 min read Software production is becoming a hierarchy of loops. Engineers move “down” into lower-level loops to debug reliability. They move “up” to design better processes. The highest-value human work is deciding which loops to create. So today we’re launching Mastra Factory, a system for agents to take software from issue into production. In Mastra Factory, specialized agents triage issues, write and

    匹配字段正文

  2. LMSYS Blog精选

    SGLang 与 Miles 为 Kimi K3 提供 Day-0 支持

    SGLang 与 Miles 宣布在 Kimi K3 发布当天提供 Day-0 支持,前者负责推理、后者负责 RL 训练,与 Moonshot AI、NVIDIA 团队合作完成。K3 是首个 3 万亿参数级别的开源模型,实际为 2.8T 参数、1M token 上下文窗口并具备原生视觉理解,其 69 层 KDA 线性注意力与 24 层 MLA 交织的混合架构打破了常规服务栈的多项假设。文中给出统一显存池、DSpark 投机解码与 ReplaySSM、分阶段并行等方案,并报告在 16 节点 × 4 GB300 上做 DAPO 数学 RL 训练,AIME-2024 贪心评测在 12 小时内从 43.3% 升至 76.7%。

    The three KDA state moves, copy-on-write, snapshot and donate, and where each sits relative to the serial forward stream.

    t rather than per token, so there is no position axis to shard, and the KDA layers stay TP-sharded by head. The whole feature is one flag, --dcp-size N. What this buys shows up on agentic traffic, where hundred-thousand-token sessions pile up in the cache. Replaying real coding-agent sessions on 2×4 GB300, with a host-memory KV tier on both arms and DCP as the only difference: DCP removes the active-set wall. The host tier rescues re-prefill traffic, but at 16 concurrent sessions the active work

    匹配字段正文

  3. A6 a6-052 · Fireworks AI精选

    Fireworks 上线 Kimi K3 推理与训练服务

    Fireworks 在 Kimi K3 开源当天提供 Day-0 推理与训练支持,称其为全球最强开源模型,并推出仅限美国区域的 Serverless 端点和零数据保留。Kimi K3 是首个达到 2.8 万亿参数的开源模型,采用 Kimi Delta Attention 与 Stable Latent MoE,激活 896 个专家中的 16 个,扩展效率是 Kimi K2 的 2.5 倍。Fireworks 称自托管需 64 个以上加速器超级节点,其 Serverless 推理默认速率限制提升 10 倍以上,Serverless Training 进入私有预览。

    level intelligence, the top open model in the world, at a fraction of closed-model cost. It is 1 at frontend code, strong at writing, and it reliably finishes the long, multi-step agentic tasks where other models stall. Michele Catasta, the President of Replit, told us, "Kimi K3 on Replit Design exceeded our expectations. Unprecedented product design and UI capabilities, at a fraction of the cost we've come to expect from frontier models." Silas Alberti, SVP of Research at Cognition, highlighted

    匹配字段正文

星期五

  1. Andrew Ng精选

    Andrew Ng 发布开源智能体 OpenWorker

    Andrew Ng 与 Rohit Prasad 发布开源智能体 OpenWorker,它不只对话,还能交付成品,例如生成文档、发送 Slack 消息或更新日历条目,可处理客户简报、整理日历、起草报告和分诊 Slack 告警,并在执行重要操作前先确认。OpenWorker 运行在 Mac 上,Windows 支持即将推出,不绑定单一模型,用户自带 API key 即可搭配 GPT 5.6 Sol、Claude Fable、Gemini 3.6、Kimi、GLM、DeepSeek、Inkling 等开源权重模型或 Ollama 本地运行,数据除经用户选择的 LLM 服务商和集成外不离开本机。

    Announcing OpenWorker! An open-source agent that doesn't just chat with you, but delivers finished work -- like hand you a polished document, send a slack message, or update a calendar entry. Ask it to prepare a customer brief, untangle your calendar, draft a report, or triage a Slack alert. It works across your files and everyday tools, produces the deliverable, and checks in before doing anything consequential. OpenWorker runs on your Mac, with Windows support coming soon. It does not lock you

    匹配字段正文

  2. Microsoft AI Blog精选

    微软 MAI 模型落地 GitHub Copilot 与 Excel

    微软 AI 公布面向智能体工作负载的 MAI 模型在 GitHub Copilot 和 Excel 中的部署情况。MAI-Code-1-Flash 自 6 月在 GitHub Copilot 上线以来已有数百万开发者使用,在 VS Code 中代码接受率比 GPT 5.4 Mini 和 Claude Haiku 4.5 高约 10%,中位 token 用量低 10%。在 Excel 中,基于该 checkpoint 继续强化学习得到的模型在常见任务上质量与 GPT-5.6 相当,且可运行在 Nvidia H100 和 A100 上,降低部署成本。微软表示正将这一方法扩展到 Copilot Chat、Outlook、PowerPoint 等产品。

    Line graph showing pass rates on SWE Bench (VS Code and Base) across model checkpoints, with data points labeled "Code" and "Excel." Pass rates increase over checkpoints, starting below 72% and peaking at 86%.

    we introduced our hill–climbing machine, our integrated data, model, and harness flywheel. Today we are excited to share two examples inside Microsoft: MAI models specialized for agentic workloads in GitHub Copilot and Excel. Early results are promising. In our live product deployment, we see that our MAI model deployed in Excel is on par with GPT-5.6 for the most common tasks while being more cost-efficient. The figure below shows how MAI-Code-1-Flash, post-trained within the GitHub Copilot ha

    匹配字段正文

星期四

  1. Together AI Blog

    Together AI 更新开源权重模型推理平台并开启自定义训练内测

    Together AI 发布 Dedicated Model Inference 推理平台更新,支持在同一稳定端点后运行多个部署,并提供 canary、蓝绿和滚动更新及按阈值自动回滚、A/B 与影子流量测试、按 inflight 请求或 GPU 利用率等指标自动扩缩容。平台重建了模型缓存与分发层,内部测试中多个前沿模型的冷启动速度约提升 4 倍,同时提供组织级 Prometheus 端点接入自有可观测工具。Together AI 还开启自定义训练内测,涵盖全权重与 LoRA 强化学习及监督微调,checkpoint 可直接部署到推理服务,内测名额有限。

    odels on quality, run at a fraction of the cost, and are fully customizable for your task. That combination has made them the foundation for teams building serious AI products and agents. But the strategic motivation for adopting open-weight models is still the ability to exercise control. Unlike their closed alternatives, open-weight models give teams control over performance, quality, and functionality. Many commercial AI applications have adopted a majority open-weight endpoint strategy so th

    匹配字段正文

  2. xAI News精选

    Grok Build 上线 Workflows 工作流功能

    Grok Build 新增 Workflows 功能,用户用自然语言描述大型任务后,Grok 会将其规划为脚本,在后台并行调度数百个智能体执行,完成后返回报告,会话全程保持空闲。单次运行默认预算为 128 个智能体,大型任务可扩展到 1,024 个;进度会随运行保存,暂停恢复不会重做已完成部分,可用 /workflows 实时查看各阶段与每个智能体的 token 消耗。保存的工作流放在 .grok/workflows/ 可与团队共享,放在 ~/.grok/workflows/ 则跟随个人,每个保存的工作流会变成带参数的 slash 命令;内置的 /deep-research 会把研究问题分发给并行调查者并核对来源后返回带引用的报告。

    Grok Build can now run workflows : describe a large task in plain language, and Grok plans it, fans it out across hundreds of parallel agents in the background, and reports back when everything is done. Your session stays free the whole time. When to use a workflow Workflows are built for complex, multi-faceted tasks a single conversation can't hold: reviewing every feature in a large PR, triaging the last 100 issues, auditing a codebase for one class of bug. If the work splits into many indepen

    匹配字段正文

星期三

  1. Prime Intellect精选

    Prime Intellect 整合 23 个智能体任务集,提供 36.5 万+ 环境用于 SWE、终端与搜索 RL

    Prime Intellect 将 23 个智能体任务集整合到统一的 taskset API 之下,共约 36.5 万个任务,包括 20 多种语言的约 19.8 万个软件工程任务、约 2.86 万个终端任务和约 13.76 万个搜索任务,可直接用于评测和 RL 训练。整合保留各任务集原有评分路径,统一了配置接口、镜像注册表和完整性标准,评分材料在打分前对智能体隐藏。团队还对数据集做了 gold-patch 与 no-op 验证并重新上传清洗版本,例如 R2E-Gym-Subset-Verified 保留 4,578 行中的 4,522 行。

    Scaling Agentic RL: 365,000+ Environments for SWE, Terminal, and Search

    The open research ecosystem has produced many great datasets for the three main agentic domains - software engineering, terminal use, and web research - but every one of them ships with its own harness, its own image conventions, its own grading scripts, and its own failure modes. 23 tasksets behind one taskset API We integrated them all. We ship first-party integrations for 23 agentic tasksets behind one taskset API, unified runtime/sandbox hooks, and one command: 198,000 software engineering t

    匹配字段正文

星期二

  1. Modal 官方工程博客

    Modal 发布 modal-devin,让 Devin Outposts 在 Modal Sandbox 中运行

    Cognition 推出 Devin Outposts,让 Devin 的执行环节迁入用户自控环境,推理仍留在 Cognition 云端。Modal 作为发布伙伴推出开源集成 modal-devin,使 Devin Outpost 会话运行在 Modal Sandbox 中,具备快速冷启动、自定义镜像、快照和百万级沙箱扩展能力,7 月 21 日起进入 alpha。modal-devin 提供 CLI,一条 uvx modal-devin init 命令即可搭建 outpost,并预装 Devin CLI、FFmpeg 和 Chromium。

    lled tools, everything. Resume it later and there's no re-cloning the repo or reinstalling dependencies. One command sets up your outpost. Standing up secure infrastructure for an agent to run on your own machines usually means real work: a queue watcher, credential handling, sandboxing, lifecycle management. uvx modal-devin init does all of it, and generates code you own and can keep customizing: a scheduler function (the orchestrator from above) and a session function (the worker): Each team g

    匹配字段正文

  2. xAI News

    xAI 为 Microsoft Outlook 推出 Grok 插件

    xAI 将 Grok 引入 Microsoft Outlook,以插件形式在收件箱旁提供智能体,可总结长邮件线程、按用户语气起草回复并整理邮箱。该插件能读取附件并搜索网页和 X,回复需用户手动发送;即日起面向所有付费 X 和 SuperGrok 用户开放,可从 Microsoft Marketplace 添加,同时也支持 Word、Excel 和 PowerPoint。

    Today we're bringing Grok into Microsoft Outlook. The add-in puts an agent beside your inbox: it summarizes long threads, drafts replies in your voice, and keeps your mailbox organized. Legal came back on the renewal terms Five stories to start your day A lunar landing, a marathon record, and more We need sign-off from finance and legal All 1,204 checks green on main Three flows to review, deck attached Current rate holds if we commit by Jun 30 Accruals due to finance by Wednesday Q3 Vendor Cont

    匹配字段正文

星期一

  1. Unsloth精选

    Unsloth 推出 AMD 版本,可在 AMD GPU 上训练和运行 LLM

    Unsloth 发布 AMD 版本,用户现在可以在 AMD 硬件上训练和运行 LLM。该版本与 AMD 合作实现,支持在 AMD GPU 上训练和运行 500+ 模型,覆盖 Windows、WSL、Linux,并可在 3GB VRAM 上训练 Qwen、Gemma。官方称借助自研 Triton kernel 和数学算法,在 Radeon、Instinct、Ryzen 及数据中心 GPU 上最高提速 2 倍、显存占用减少 70% 且无精度损失,同时提供针对 GGUF 与 Safetensors 推理优化的 ROCm 构建。

    t, Ryzen and data center GPUs with up to 2× faster with 70% less VRAM and no accuracy loss via our custom Triton kernels and math algorithms. We also support optimized ROCm builds for GGUF & Safetensors inference. Unsloth is an open-source local UI for faster LLM training and inference, with tool-call healing, code execution, secure web search, remote APIs, and HTTPS deployment. Connect local models to Claude Code, Codex agents and run the latest Kimi, GLM, DeepSeek, Qwen3.6, and Gemma 4 models.

    匹配字段正文

星期四

  1. Modal 官方工程博客精选

    Modal 重建沙箱平台,可并发运行 100 万个沙箱

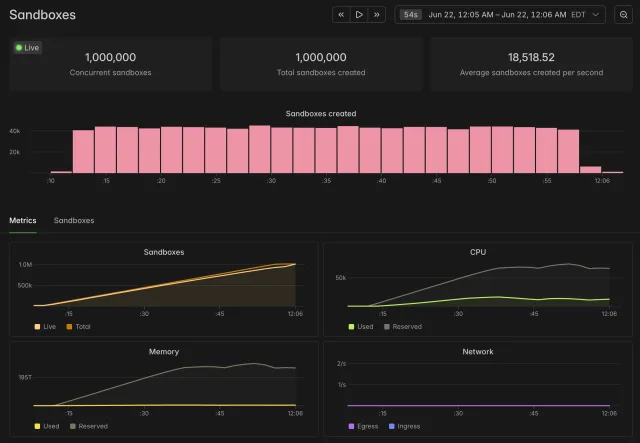
    Modal 重建了核心沙箱平台,可并发运行数百万个沙箱、每秒创建数万个沙箱,并演示了在不到一分钟内创建全部 100 万个沙箱。新架构去掉了控制面的中心协调,每个 worker 自持状态并通过 Redis stream 异步发布,沙箱创建路径只需两次网络跳转,中位启动时间不到半秒。该系统已进入 Beta,用户可通过一处代码改动选择启用。

    Evidence that we can run a lot of sandboxes.

    At Modal, we build sandboxes, among other things. Agents run in sandboxes, and agents are eating software. Today, Modal runs millions of sandboxes per day, supports up to fifty thousand concurrent sandboxes per customer, and supports a variety of use cases at scale, from reinforcement learning to background agents. Increasingly, our users require more and more sandboxes, created at higher and higher rates. Reinforcement learning can require running millions of sandboxes concurrently, and creatin

    匹配字段正文