Thinking Machines 的 Inkling 上线 Modal,975B 参数多模态模型支持 Day 0 托管
Thinking Machines 发布通用多模态模型 Inkling,可接受文本、图像和音频输入并生成文本输出,Modal 以 Day 0 合作将其作为按 token 计费的托管端点上线。Inkling 是 MoE Transformer,总参数 975B、激活 41B,上下文窗口 1M token,原生支持音频与视觉。Modal 为其定制了 DFlash 推测解码器,在 8x B200 的智能体负载上实现每用户 250 tokens/s、每 GPU 2.5M TPM,交互性比模型内置推测路径快 67%。

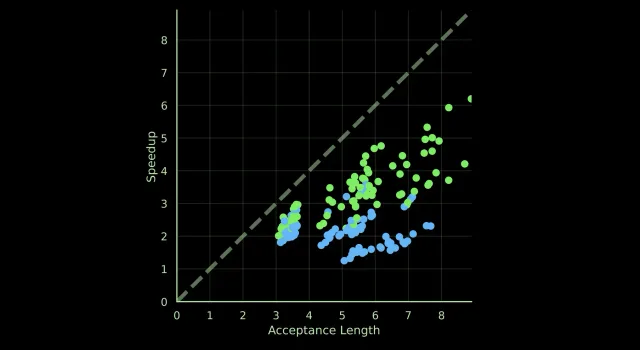
keeps compute and memory flat as sequences grow. For endpoints on Modal, we took this even further with Day 0 support for a custom DFlash speculator tuned to this model shape. On agentic workloads on 8x B200s, we saw 250 tokens per second per user at 2.5M TPM of per-GPU throughput, 67% faster interactivity than the model's built-in speculative path at matched throughput. Towards local attention: Evolving DFlash speculation for frontier attention models Inkling’s unique architecture moves in a d
匹配字段正文