←搜索结果

按匹配度 · 共 1147 条结果 清除搜索

星期三

  1. Ollama Blog精选

    Ollama 上线 Llama 3.2 的 1B 与 3B 端侧模型

    Meta 的 Llama 3.2 现已可通过 Ollama 运行,其中 1B 和 3B 为纯文本模型,针对手机或边缘设备本地运行做了优化,可用于构建高度个性化的端侧智能体,例如总结 WhatsApp 最近十条消息或下月日程。Ollama 表示处理在本地完成,数据不发送给第三方或云服务,提示与响应接近即时。11B 和 90B 视觉模型即将推出,支持图表等文档级理解和图像描述。
    A picture of Ollamas acting out what small and multimodal looks like. We hope you enjoy the new llama 3.2 models from Meta!

    ilable to run using Ollama. 1B and 3B models are text-only models are optimized to run locally on a mobile or edge device. They can be used to build highly personalized, on-device agents. For example, a person could ask it to summarize the last ten messages they received on WhatsApp, or to summarize their schedule for the next month. The prompts and responses should feel instantaneous, and with Ollama, processing is done locally, maintaining privacy by not sending data such as messages and other

    匹配字段正文
星期四

  1. vLLM 官方博客

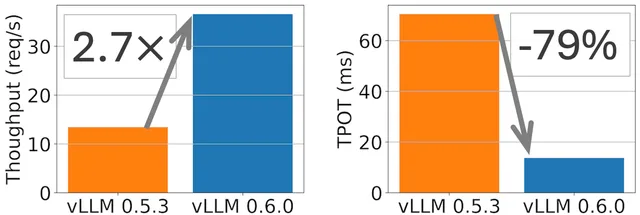
    vLLM v0.6.0 发布,吞吐量提升最高 2.7x、TPOT 最多降低 5x

    vLLM 发布 v0.6.0,相比 v0.5.3 吞吐量提升 1.8-2.7x,其中 Llama 8B 的吞吐量提升 2.7x、TPOT 加快 5x,Llama 70B 的吞吐量提升 1.8x、TPOT 减少 2x。主要优化包括拆分 API server 与推理引擎、多步批量调度、异步输出处理、对象缓存和非阻塞数据传输。多步调度目前会造成 token 间延迟波动,并可能在低请求率下提高 TTFT。

    has highest throughput on ShareGPT and Decode-heavy dataset (though the throughput is only marginally higher than TensorRT-LLM), but the throughput of vLLM is lower on Prefill-heavy dataset. Related Posts DeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.

    匹配字段正文

星期四

  1. Prime Intellect

    Prime Intellect 开源 OpenDiLoCo,实现跨洲分布式低通信训练

    Prime Intellect 开源 OpenDiLoCo,这是 DeepMind DiLoCo 低通信分布式训练方法的可复现实现,代码基于 Hivemind 与 PyTorch FSDP,已发布在 GitHub。团队在加拿大、芬兰和美国两地共四个 DiLoCo worker(各 8 张 H100)上训练 1.1B 参数模型,跨两大洲三国,计算利用率保持 90-95%,all-reduce 仅占训练时间 6.9%。相比原论文 400M 参数规模,该方法被扩展到 1.1B 参数,并验证伪梯度可用 FP16 all-reduce 而不损失性能。

    OpenDiLoCo: An Open-Source Framework for Globally Distributed Low-Communication Training

    nique and look forward to building on it for the third part of our masterplan soon: to collaboratively train and contribute to open AI models in high-impact domains like language, agents, code, and science for collective ownership of AI models. Join Us in Building the Open Future of AI The power to shape the future of AI should not be concentrated in the hands of a few, but open to anyone with the ability to contribute. We invite you to join us in building a more distributed and impactful future

    匹配字段正文

星期一

  1. Prime Intellect精选

    Prime Intellect 发布算力交易平台 Prime Intellect Compute

    Prime Intellect 宣布其聚合与调度全球 GPU 资源的平台 Prime Intellect Compute 全面公开,已接入 12 家云厂商,用户可即时按需获取最多 8 张 GPU,H100 按需价格为每小时 1.5 至 4 美元。平台后续计划支持 16-128+ GPU 的多节点集群、即时报价与可靠性数据,并研究跨集群分布式训练框架 OpenDiLoCo。官方称当前 H100 在不同供应商间价格从每小时 1.2 到 18 美元不等,高端 GPU 闲置率常达 20-50% 以上。

    Introducing Prime Intellect Compute: The compute exchange

    ute. Train models. Democratize Intelligence. AI compute needs to be accessible to all, accelerating progress and ensuring democratized access! We invite everyone to join us on this journey: Sign up to find instant compute H100s starting at 1.65.A100sat1.65. A100s at 1.65.A100sat0.87. 4090s at $0.3 Let's accelerate progress by making compute and machine intelligence more open and accessible for all. ‍ Feel free to upvote us on producthunt ‍ Rewriting Prime Agent in Rust On the Nature of the Swarm

    匹配字段正文

星期四

  1. Ollama Blog

    Ollama 内置兼容 OpenAI Chat Completions API

    Ollama 宣布内置兼容 OpenAI Chat Completions API,可在本地使用更多工具和应用。使用时只需把请求的 hostname 改为 http://localhost:11434,即可沿用 OpenAI 的调用格式,官方还给出了 cURL 和 Microsoft 开源多智能体框架 Autogen 的接入示例。该支持目前为实验性,后续改进方向仍在考虑中。

    lama: Next, run the app: Finally, open the example app in your browser at http://localhost:3000: Autogen Autogen is a popular open-source framework by Microsoft for building multi-agent applications. For this, example we’ll use the Code Llama model: Install Autogen: Then create a Python script example.py to use Ollama with Autogen: Lastly, run the example to have the assistant write the code to plot a chart: More to come This is initial experimental support for the OpenAI API. Future improvement

    匹配字段正文

星期二

  1. vLLM 官方博客精选

    vLLM 发布基于 PagedAttention 的开源 LLM 推理与服务库

    vLLM 发布开源 LLM 推理与服务库,利用 PagedAttention 管理 KV cache,无需修改模型架构即可实现比 HuggingFace Transformers 最高 24x 的吞吐量。实验中其吞吐量比 TGI 最高提升 3.5x,内存浪费降至 4% 以下;LMSYS 部署后将服务所需 GPU 数量减少 50%。

    ire team — Siyuan Zhuang, Ying Sheng, Lianmin Zheng (UC Berkeley), Cody Yu (Independent Researcher), Joey Gonzalez (UC Berkeley), Hao Zhang (UC Berkeley & UCSD), and Ion Stoica (UC Berkeley). Related Posts DeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.

    匹配字段正文

星期四

  1. Replit Blog精选

    Replit 发布 Ghostwriter AI 编程助手,Complete Code 进入封闭测试

    Replit 宣布推出 Ghostwriter,把 AI 能力接入几乎全部 IDE 功能,旗舰功能 Complete Code 是实时补全代码的 AI 结对程序员,目前处于封闭测试。官方称通过 FasterTransformer 与 Triton 推理、知识蒸馏和量化等优化,中位响应时间低于 400ms;Explain Code、Generate Code、Transform Code 则调用 OpenAI 等更大模型。Ghostwriter 后续将打包为基于 Cycles 的付费功能,最终计划像 Multiplayer 一样默认免费开放。

    Ghostwriter AI & Complete Code Beta — cover image

    w in your editor). Ghostwriter is like Multiplayer in that you collaborate in real-time with someone else. However, in this case, you're not coding with a person; instead, it's an agent representing the entire programming knowledge of the human race. We believe Ghostwriter will leapfrog traditional IDE features. Ghostwriter is the next major evolution of our platform. We think this will radically change how people write code on Replit — and in the process, will change software writ large. Foreve

    匹配字段正文