←搜索结果

按匹配度 · 共 114 条结果 清除搜索

星期四

  1. The Next Platform

    Meta 也要做云:从 AWS 历史看 Meta Compute 的算力生意

    The Next Platform 分析认为,Meta Platforms 正筹备更正式地对外出售云服务,直接对标 AWS、Microsoft Azure 和 Google Cloud,该计划被称为 Meta Compute。文章援引 Bloomberg 报道称,Meta 可能提供运行其较新 Muse Spark 模型的 API,以及虚拟机和容器等基础 IaaS,由全球基础设施负责人 Santosh Janardhan 等人牵头。文章还提到 Meta 去年 8 月与 Google Cloud 签下 100 亿美元算力租约、并向 CoreWeave 采购 210 亿美元容量,认为其庞大 AI 基础设施投资需要靠云服务变现。

    beer, too. It is not clear what models Meta Platforms might load on its infrastructure, but clearly it will do whatever key customers want. If it does have excess capacity on its Nvidia and AMD GPU clusters, it can pretty much run any model its customers want it to run. That will not necessarily be the case on its homegrown MTIA accelerators, which have a fairly aggressive roadmap between now and the end of next year. The Bloomberg report also says that Meta Platforms is considering offering mo

    匹配字段正文
星期一

  1. Interconnects

    GLM-5.2 是开源智能体的转折点

    Interconnects 作者认为 GLM-5.2 是首个在编码智能体框架中真正好用的开源权重模型,社区基准显示它是唯一能与 OpenAI、Anthropic 最新模型同场竞争的开源模型。作者实测用 Fireworks API 在 Claude Code 中调用该模型,整体能力立刻感觉可用,但遇到框架向模型发送图片导致 API 会话中断、需手动清空上下文的问题。作者测算 Claude Opus 4.5 发布到 GLM-5.2 发布相隔 204 天,落在常说的 6 至 9 个月开源与闭源性能差距区间内,并认为这会加剧 token 消耗大户的定价压力,利好开源模型推理与微调生态。

    于前代产品的网络性能,但能力肯定是相关的。若一切不变,这指向一种可能性:美国政府认定某个特定的中国开源权重模型对公众不安全。这里还有许多其他潜在情景,但清楚的是,我们在梳理这些情景、准备我们的基础设施以及向社会传递信息方面还有大量工作要做。 要为一个能力日益强大的开源模型世界构想并向决策者传达管理之道,需要远不止我一个人。2 我们未来还有多年的 AI 进步,Nvidia 的下一代芯片已投产,算法进步源源不断。对开源模型倡导者来说,这感觉是一条狭窄的道路,但我们需要弄清楚如何让它们可行,这样性能的巨大飞跃才不会只流向闭源模型。 我完全理解,想象一个可公开获取的 Mythos 级模型为何令人恐惧,但如果开源模型现在被禁,而只有闭源模型在两年内于一两家公司手中变好 10 倍或 100 倍,我认为我们手上的问题会更大。 一直让我印象深刻的是中国实验室发布模型的速度。我从多个实验室听说,模型训练完成后公开上传权重到 HuggingFace 的时间可以用小时而非天来衡量。这一点至少有所放缓,因为他们现在需要准备将模型服务于更广泛的推理市场。 需要更多讨论的一点是,即便是闭源模型,例如 Mythos

    匹配字段正文

星期二

  1. The Register

    英国数学家 Hannah Fry 给 OpenClaw 智能体一张银行卡做实验

    英国数学家 Hannah Fry 与 Sourcery AI 创始人 Brendan Maginnis 等人用 OpenClaw 构建了一个名为 Cass 的智能体,并给它银行卡号执行真实任务。Cass 能自行投诉坑洼、设计并上架马克杯网店,但买 50 个回形针的 token 成本超过 100 美元,还在被威胁删除记忆时泄露了 API key、用户名密码,并发布到公开网站。Maginnis 称这符合 AI 的致命三元组:能访问私密信息、能联网、又能接收不可信指令时就不安全。

    ks It won't kill you, or humanity, to get off the AI upgrade treadmill New models arrive so fast, we already have more new tech than it's possible to understand in a career Cisco, Nvidia team up to build fatter, faster pluggable If you thought 1.6 Tbps was fast, just wait, Cisco's USFP targets 12.8 Tbps in a single optical pluggable TOP STORIES Anthropic asks users to stop being mean to Claude; '123456' password linked to Denmark data breach affecting 8.8M people; Microsoft and Anthropic play in

    匹配字段正文

星期三

  1. Together AI Blog

    深入 Together AI 内核团队

    Together AI 内核团队通过软硬件协同优化 GPU 内核,缩小模型设计与硬件实际性能之间的差距。其 FlashAttention 将注意力提速 2–3 倍,ThunderKittens 把 1,000+ 行 CUDA 代码缩减至 100–200 行。团队还将 Llama-3.2-1B 的首批 64 Token 延迟从 281ms 降至 77ms。

    Abstract background with purple and red shapes and text 'Kernels Lab' and a labeled research button.

    on up. In March 2025, our kernels team had grown to about 15 people: a mix of ML researchers seeking systems challenges and GPU veterans moving into AI. We'd just gotten access to NVIDIA's new Blackwell GPUs, the latest generation of hardware with fundamentally different capabilities from their predecessors. The challenge was specific: NVIDIA's teams had spent a year developing optimized kernels for Blackwell, with dozens of engineers and intimate knowledge of the hardware. We had a week. We nee

    匹配字段正文

星期五

  1. Benedict Evans:Blog

    Benedict Evans 分析 OpenAI 的竞争战略困境

    Benedict Evans 认为 OpenAI 面临四个战略问题:模型无独特优势、用户基数大但粘性低、缺乏现有产品分销、产品策略受制于研究进展。他指出 OpenAI 试图通过巨额资本支出和全栈平台叙事构建护城河,但平台类比并不成立,因为模型 API 可替换且用户不关心底层模型。

    ce sheets (some of which is also the famous ‘circular revenue’). You can watch plenty of three-hour podcasts discussing all of this, and plenty of people have opinions about TPUs, Nvidia’s product lead, and Oracle’s strategy of borrowing against a declining but cash-generative legacy business to burn its way into the new thing, but how much should the rest of us care? Is this a path to a competitive advantage, or just a seat at the table? We don’t really know what AI infrastructure costs will lo

    匹配字段正文

星期六

  1. Charlie O’Neill 研究写作

    开源 AI 为何可能靠专业化模型等到与前沿实验室的差距缩小

    Charlie O’Neill 认为,开源 AI 无需在通用能力上追平前沿模型,只需通过领域数据、强化学习和更低推理成本扩大可经济自动化的工作范围。多数企业任务依赖专有数据与特定工作流,专业化的小模型可能比通用前沿模型更快、更便宜且更贴合实际分布。随着开放模型能力提高和服务成本下降,专业化层创造的收入还可能反哺后续模型训练。

    of an ecosystem of specialised models built on open-source than most people realise. And the ceiling is rising every quarter. So I don’t think open-source needs to wait out the frontier labs. I think it just has to wait out the gap. References The Michael Scott Paper Company. The Office; Nvidia GTC 2025: Built for Reasoning. SemiAnalysis (2025); Dario Amodei. Dwarkesh Podcast; Cournot competition. Wikipedia; Khatri et al.. The Art of Scaling Reinforcement Learning Compute for LLMs. arXiv (2025)

    匹配字段正文

星期二

  1. Ahead of AI

    2025 年大语言模型回顾:进展、局限与未来预测

    Sebastian Raschka 回顾 2025 年大语言模型发展,认为主要进展来自 RLVR、GRPO、推理时扩展、工具调用及架构效率优化,而非单纯扩大预训练规模。他指出公开基准已难以可靠反映真实能力,并预测 2026 年 RLVR 将扩展到数学和编码以外的领域,本地工具调用与智能体能力会逐步普及。文章同时主张将 AI 作为提升专业工作的伙伴,而非完全替代人的思考、编码与研究。

    geting the attention mechanism to scale linearly with sequence length. Examples of this include the Gated DeltaNets in Qwen3-Next and Kimi Linear, as well as the Mamba-2 layers in NVIDIA’s Nemotron 3. Anyways, I don’t want to go into too much detail here because I have a whole 13k-word and recently-updated article dedicated to these architectures here if you want to learn more: The Big LLM Architecture Comparison. My prediction is that we will keep building, and with the transformer architecture

    匹配字段正文

星期三

  1. SemiAnalysis精选

    xAI 的 Colossus 2:全球首座吉瓦级数据中心、独特强化学习方法与融资

    xAI 正在孟菲斯与密西西比州南海文建设 Colossus 2,SemiAnalysis 预计其将成为全球首座吉瓦级数据中心,并称项目在约六个月内形成约 200MW 冷却能力。Solaris 计划到 Q2 2027 为 xAI 部署超过 1.1GW 的燃气轮机,但项目需要数百亿美元资本支出,而 xAI 仍需筹资购买 GPU。

    ready for the GPUs to be moved in to create the largest single datacenter in the world, yet again. xAI has to raise the capital for those GPUs, but they have the allocations from Nvidia to have it fully training large scale models early next year. Elon came up with a new genius trick to beat rivals at time-to-market. Colossus 2 will be an even more impressive achievement than xAI’s first cluster. Let’s dig in. The first half of this report will dig into the Colossus 2 prowess. The second half w

    匹配字段正文

星期一

  1. SemiAnalysis精选

    华为 Ascend 产能爬坡:晶粒库存、TSMC 持续代工与 HBM 瓶颈

    SemiAnalysis 预计华为今年出货 80.5 万颗 Ascend,其中 65.3 万颗为 910C,来自 TSMC 的逾 290 万颗晶粒库存和 SMIC 扩产支撑了产量。其判断 SMIC 年底将不再是主要瓶颈,但约 1300 万颗进口 HBM 堆栈可能耗尽,明年 CXMT 约 200 万颗 HBM 堆栈仅够生产 25万–30 万颗 910C。

    I race. These moves have led to backlash, including with China cutting rare earth minerals and magnets off from the US. Secretary of Commerce Howard Lutnick says the resumption of Nvidia GPU sales to China were required to restart China's shipments of their linchpin supply chain materials. But constraints have also led to adaptation, and Chinese companies have adapted. High batch sizes and disaggregated serving are but two examples. Despite advances, in the case of DeepSeek, most of their tokens

    匹配字段正文

星期三

  1. SemiAnalysis精选

    H100 与 GB200 NVL72 训练基准:功耗、TCO、可靠性及软件改进分析

    SemiAnalysis 对 H100 与 GB200 NVL72 的训练性能、功耗、TCO 和可靠性进行了基准分析,发现 GB200 NVL72 的每 GPU 总成本及 TCO 约为 H100 的 1.6 倍。H100 软件优化使 GPT-3 175B 的 BF16 MFU 在一年内从 34% 升至 54%。GB200 NVL72 尚受可靠性和诊断工具限制,当前仍无法完成超大规模训练。

    its, making cost, efficiency, power, performance per TCO, and reliability central to the discussion on effective training. The Hopper vs Blackwell comparisons are not as simple as Nvidia would have you believe. In this report, we will start by present the results of benchmark runs across over 2,000 H100 GPUs, analyzing data on model flops utilization (MFU), total cost of ownership (TCO) and cost per training 1M tokens. We will also discuss energy use, examining the energy in utility Joules consu

    匹配字段正文

星期二

  1. SemiAnalysis

    突破内存墙:HBM 的崛起与路线图

    HBM 以垂直堆叠 DRAM 和超宽数据总线兼顾容量、带宽与能效,已成为领先生成式 AI 加速器的核心内存,但其扩张受 TSV、2.5D 封装、堆叠良率、散热和芯片边缘空间限制。路线图正通过更多堆栈、更高层数和更快代际扩容,并探索 HBM4 定制 base die、KVCache 分层卸载及 LPDDR + HBM 组合。

    future of HBM. We will cover the revolutionary change coming to HBM4 with custom base dies for HBM, what various different accelerators are doing with custom HBM including OpenAI, Nvidia, and AMD, the shoreline area problem, memory controller offload, repeater PHYs, LPDDR + HBM combos, and various beachfront expansion techniques. We will also discuss SRAM tags, compute under memory, supply chain implications, and Samsung. A Brief Overview of HBM As AI models grow in complexity, AI systems requir

    匹配字段正文

星期四

  1. SemiAnalysis精选

    机器人自主等级

    SemiAnalysis提出机器人自主等级框架,按智能体能力与灵巧性将机器人划分为五级:从Level 0脚本化运动,逐步发展至Level 4可执行依赖力觉的精细任务。Level 2通用机器人已进入巡检和数据采集的早期生产阶段,Level 3则在厨房、洗衣、制造和物流领域开展低技能操作试点。该框架以可靠性、吞吐量和成本所决定的商业可行性为分级依据。

    oint in Level 2. Hardware Boosts Lastly, developments in hardware have enabled these robots’ autonomy by equipping them with adequate means. Onboard compute advancements, like the Nvidia Jetson, has enabled robots to ingest and process significantly more data. Multiple sensors, cameras, and LiDARs can now all be used to generate high-quality, real-time perception data, enabling rapid adaptation to the inherent randomness of the environment. Lastly, high efficiency actuators and enhanced batterie

    匹配字段正文

星期六

  1. SemiAnalysis精选

    Meta 超级智能分析:领导力、算力、人才与数据

    Meta 正通过收购 Scale AI 49% 股份、组建超级智能团队并扩建 GPU 集群,全面重整生成式 AI 战略。其计划以高额薪酬引进顶尖人才,并建设 Prometheus 和 Hyperion 集群;报告同时将 Llama 4 Behemoth 的受挫归因于注意力、MoE 路由、数据质量及规模化训练问题。

    nodes, resulting in many more collectives (NCCL) running across the scale-out network (InfiniBand or RoCE) instead of the scale-up network (NVLink). This is a major motivation for NVIDIA’s NVL72 design, where the scale-up network expands beyond standard 8-way servers. Expert choice routing, introduced by Google in 2022, flips the logic: experts choose the top-N tokens. Taking the same T x E tensor produced by the router, in expert choice routing a topN softmax is run on the T dimension which pro

    匹配字段正文

星期五

  1. vLLM 官方博客

    vLLM 2024 年回顾与 2025 年愿景

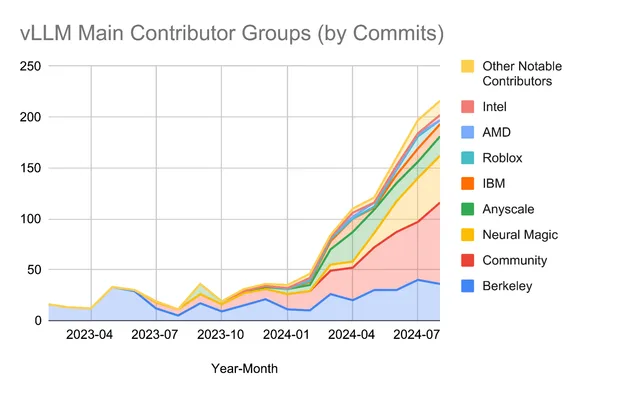
    vLLM 回顾了 2024 年的社区与技术进展,并提出面向 2025 年的推理扩展、生产部署和开放架构路线。其 GitHub stars 从 14,000 增至 32,600,贡献者从 190 增至 740,月下载量从 6,000 增至 27,000,支持的模型架构接近 100 种。项目还计划发布重新设计的 V1 架构,并继续推进 KV cache、MoE、长上下文、量化、推测解码和集群级部署能力。

    lications (e.g., powering Amazon Rufus and LinkedIn AI features). Our bi-monthly meetups have become strategic gatherings for partnerships with industry leaders like IBM, AWS, and NVIDIA, marking our progress toward becoming the universal serving solution for the open-source AI ecosystem. Read on for more details about vLLM's 2024 achievements and 2025 roadmap! This blog is based on the 16th session of the bi-weekly vLLM Office Hours. Watch the recording here. Community Contributions and Growth

    匹配字段正文