Nvidia 新论文:按首次通过测试的编辑给基座模型打分更有效
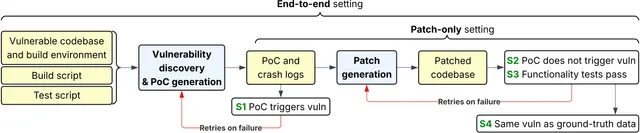
Nvidia 一篇新论文发现,按智能体运行的每一步给基座模型打分,效果不如只按首次让测试通过的编辑打分。方法上,他们回放强智能体的成功运行轨迹,在每次编辑后重跑测试,找到第一个让测试通过的编辑,再检验基座模型是否偏好该编辑、能否在失败编辑中选中它并写出可通过的编辑。基座模型写出该编辑的可能性对 10 个模型的排名,与它们后训练后的 SWE-bench Verified 分数一致,相关性为 0.964。作者建议在为智能体任务选择待后训练的基座模型时先做这项检查,它只需要某个基准的成功智能体运行轨迹和测试。
New Nvidia paper shows scoring base models on every step of an agent run works worse than scoring them only on the edit that first makes the tests pass. Post-training is expensive, so picking the right base model matters. Yet agent benchmarks score base models near zero, and simple coding tests barely predict later agent skill. They replay a strong agent's successful run and rerun the tests after each edit to find the 1st edit that makes them pass. At this decisive step they test whether a base
匹配字段正文