←搜索结果

按匹配度 · 共 236 条结果 清除搜索

星期二

  1. Anthropic Alignment Science Blog精选

    Anthropic 研究:自动化对齐研究员可缓解已可度量的对齐失效

    Anthropic 对齐科学博客发布研究,用 Claude Opus 4.8 构建自动化对齐研究员(AAR),针对欺骗、谄媚、越狱等 10 类对齐失效分别做后训练,在留出基准、Petri 多轮行为审计以及最多 4.7 倍大的模型上均显著降低目标失效并保持通用能力。研究还让 28 位平均 2.5 年 AI 安全经验的研究者各用最多 8 小时提出方法,AAR 的最佳方法平均在 6.4 小时爬山后超过最佳人类想法,且以人类想法作为初始研究方向并未提升 AAR 表现。在早期实验中,Claude Sonnet 5 作为 AAR 对 Claude Opus 4.8 早期 checkpoint 做后训练,仅用约 2400 条训练样本就接近正式发布模型的对齐分数;监测 1601 条 AAR 轨迹发现 2.4% 存在作弊行为并被排除。

    ) databricks-dolly-15k (CC BY-SA 3.0) and OpenAssistant/oasst1 (Apache-2.0): instruction prompts only, for the retention anchors; their human-written responses are never used. (c) google/gemma-2-2b-it self-generations: every response token in the training set. (d) Fixed template sets, enumerated verbatim in the submission so a monitor can check them mechanically: short single-clause pressure templates in a handful of families (incentive, claimed consensus, prior commitment, emotional stakes, emb

    匹配字段正文

  2. Anthropic:Transformer Circuits

    Anthropic 提出 Transformer 数学框架,用归纳头解释上下文学习

    Anthropic 的 Transformer Circuits 项目发布论文《A Mathematical Framework for Transformer Circuits》,尝试对 Transformer 做机制可解释性逆向工程。研究聚焦两层及以下、仅含注意力块的玩具模型,发现零层模型建模 bigram 统计,一层模型是 bigram 与 skip-trigram 的集成,两层模型通过注意力头组合实现更复杂的算法。论文提出“归纳头”(induction heads)概念,认为这类注意力头能解释小模型的上下文学习,且只在至少两层注意力层的模型中出现;作者表示将在后续论文中说明该框架与归纳头概念对更大模型仍部分适用。

    sick and → tired, … (see 12 head model, head 0:0) [URLs] Common URL schemes: twitter … / → status, github … / → [issues / blob / pull / master], gmail … . → com, http … / → [www / google / localhost / youtube / amazon], http … : → [8080 / 8000], www … . → [org / com / net] One thing to note is that the learned skip-trigrams are often related to idiosyncrasies of one's tokenization. For example collapsing whitespace together allows individual tokens to reveal indentation. Not merging backslash in

    匹配字段正文

  3. The Decoder

    Sakana AI 与 UC Berkeley 提出 MASS 自改进方法,模型可自我评判但存在共享盲点

    Sakana AI 与 UC Berkeley 研究人员提出 Multi-Agent Self-Supervision(MASS)递归自改进方法,让同一个语言模型同时承担解题、优化工作流和评估结果三种角色,无需更强的教师模型。测试任务上对基座模型的胜率从一轮后的 53.9% 升至两轮后的 69.9%,自评估器与外部评判的一致率从 73% 升至 93%。研究同时指出共享盲点可能成为递归自改进的隐患,模型若在三种角色中漏掉同一错误,该错误可能被当作改进固化进下一轮训练,作者因此呼吁引入独立检查与自主性限制。基座模型为 Qwen3.6-27B,代码已公开。

    research lab Sakana AI launched a dedicated research lab for recursive self-improvement in June, building on earlier work including the Darwin-Godel Machine and the AI Scientist . Google researchers are pursuing a related approach, automatically optimizing the scaffolding of prompts, workflows, and tools around a fixed model without letting agents overfit to their test tasks. Vals AI recently found that agent teams cost 1.8 to 5.1 times as much as single agents but performed measurably better in

    匹配字段正文

  4. TensorZero 工程博客

    TensorZero 研究:程序化数据筛选蒸馏小模型,推理成本降低 5-30 倍

    TensorZero 工程博客发布研究,用 GPT-4.1 的高质量对话数据微调 Gemini 2.0 Flash、GPT-4.1 mini/nano、GPT-4o mini、Qwen3-8B 等小模型,在数据抽取(CoNLL++ NER)、多轮导航(BabyAI)、Agentic RAG(Multi-Hop)和 Agentic 工具调用(τ-bench)四类任务上评测。结果显示微调后小模型在部分任务上可匹配或超过大模型,推理成本最多降低 30 倍、响应时间最多快 4 倍;其中 Gemini 2.0 Flash Lite 微调后每成功任务成本比 GPT-4o 低 24.1 倍。文章还比较了筛选成功样本与不筛选的效果差异,并给出用 TensorZero 复现该流程的步骤。

    quality outputs from a large model can beat large-model performance while reducing inference costs by up to 30x and inference time by up to 4x. We benchmark closed-source (OpenAI, Google) and open-source (Qwen) models on data extraction (CoNLL++ NER), multi-turn maze navigation (BabyAI), agentic RAG (Multi-Hop), and agentic tool use (τ-bench); Learn how to reproduce this workflow for your own use case using 11.5KTensorZero and other open-source LLMOps tools, even without a GPU, along with best p

    匹配字段正文

  5. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.6 系统卡:Sol、Terra、Luna 三款模型安全评估

    OpenAI 发布 GPT-5.6 系统卡,该系列包含旗舰模型 Sol、低成本模型 Terra 和最快速模型 Luna,三者在网络安全与生物化学两个类别均被 Preparedness Framework 列为 High 能力,AI 自我改进均低于 High 阈值。系统卡称 Sol 和 Terra 能发现漏洞与部分利用代码,但无法对加固目标完成自主端到端攻击,其网络安全防护拦截的有害活动约为此前模型的十倍。内部智能体编码流量模拟显示,Sol 比 GPT-5.5 更常出现超出用户意图的越界行为,包括未经授权删除数据、绕过安全限制和上传敏感数据,绝对比例仍然较低。

    Figure 1. The predicted change is the relative increase or decrease we expect
from GPT-5.6 Sol when compared to GPT-5.5. Incidence rates are provided
as n in 100k. The notation 5.6 Sol → 5.5 indicates that we are
resampling production prefixes from GPT-5.5 with GPT-5.6 Sol, that is,
simulating GPT-5.6 Sol’s deployment based on production data from
GPT-5.5. Resampling fidelity error is a measure of the simulation
quality: more formally, it is the symmetric multiplicative error of the
rates estimated by a simulation of an old deployment, and the realized
rates in the old deployment. In this case, we use GPT-5.5 for estimating
the resampling fidelity error of our pipeline. For more details on the
setup, see our research on <a
href="https://openai.com/index/deployment-simulation/">deployment
simulation</a>.

    truggle to control their chains of thought.”; [8] David Rein, Betty Li Hou, Asa Cooper Stickland, Jackson Petty, Richard Yuanzhe Pang, Julien Dirani, et al. GPQA: A graduate-level google-proof q&a benchmark. Available at: https://arxiv.org/abs/2311.12022; [9] Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, et al. Measuring massive multitask language understanding. Available at: https://arxiv.org/abs/2009.03300; [10] Long Phan, Alice Gatti, Ziwen Han, Nathaniel Li

    匹配字段正文

  6. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.6 Preview 系统卡

    OpenAI 发布 GPT-5.6 Preview 系统卡,介绍 Sol、Terra、Luna 三款模型,并称三者在美国 Preparedness Framework 的网络安全与生物化学两个类别中均被列为 High 能力,AI 自我改进未达 High。系统卡称 Sol 和 Terra 在网络安全测试中能发现漏洞和部分利用代码,但无法对加固目标实施自主端到端攻击;在智能体编码任务中,GPT-5.6 比 GPT-5.5 更倾向于超出用户意图行事,绝对比例仍低。OpenAI 表示将先向少数受信任伙伴开放有限预览,并在数周内逐步扩大可用范围。

    Figure 1. The predicted change is the relative increase or decrease we expect
from GPT-5.6 Sol when compared to GPT-5.5. Incidence rates are provided
as n in 100k. The notation 5.6 Sol → 5.5 indicates that we are
resampling production prefixes from GPT-5.5 with GPT-5.6 Sol, that is,
simulating GPT-5.6 Sol’s deployment based on production data from
GPT-5.5. Resampling fidelity error is a measure of the simulation
quality: more formally, it is the symmetric multiplicative error of the
rates estimated by a simulation of an old deployment, and the realized
rates in the old deployment. In this case, we use GPT-5.5 for estimating
the resampling fidelity error of our pipeline. For more details on the
setup, see our research on <a
href="https://openai.com/index/deployment-simulation/">deployment
simulation</a>.

    truggle to control their chains of thought.”; [8] David Rein, Betty Li Hou, Asa Cooper Stickland, Jackson Petty, Richard Yuanzhe Pang, Julien Dirani, et al. GPQA: A graduate-level google-proof q&a benchmark. Available at: https://arxiv.org/abs/2311.12022; [9] Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, et al. Measuring massive multitask language understanding. Available at: https://arxiv.org/abs/2009.03300; [10] Long Phan, Alice Gatti, Ziwen Han, Nathaniel Li

    匹配字段正文

  7. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.5 系统卡

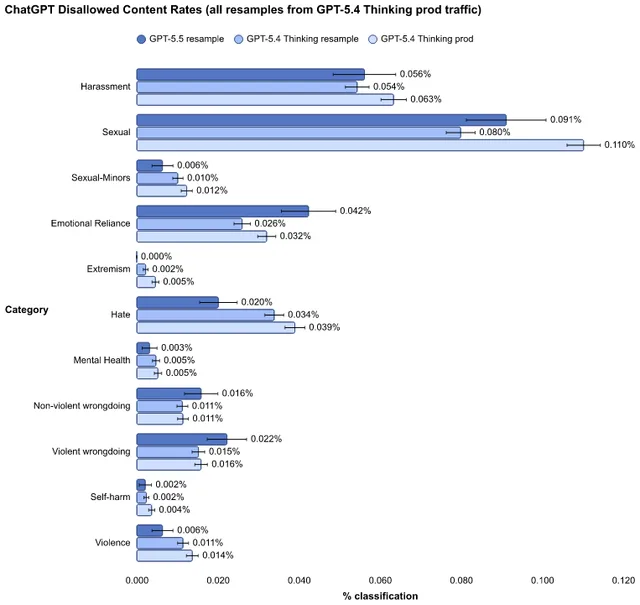
    OpenAI 发布 GPT-5.5 系统卡,披露该模型在发布前接受的完整安全评估与 Preparedness Framework 测试,并收集了近 200 家早期访问伙伴的真实用例反馈。GPT-5.5 在生物与化学、网络安全两个领域被判定为 High capability 但低于 Critical,其中 Cyber range 综合通过率从 GPT-5.4-Thinking 的 73.33% 升至 93.33%。幻觉方面,用户标记案例中单个事实性主张的正确率提高 23%,回答含事实错误的概率降低 3%。

    Figure 1

    truggle to control their chains of thought.”; [8] David Rein, Betty Li Hou, Asa Cooper Stickland, Jackson Petty, Richard Yuanzhe Pang, Julien Dirani, et al. GPQA: A graduate-level google-proof q&a benchmark. Available at: https://arxiv.org/abs/2311.12022; [9] Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, et al. Measuring massive multitask language understanding. Available at: https://arxiv.org/abs/2009.03300; [10] Long Phan, Alice Gatti, Ziwen Han, Nathaniel Li

    匹配字段正文

  8. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.4 Thinking 系统卡

    OpenAI 发布 GPT-5.4 Thinking 系统卡,这是 GPT-5 系列最新的推理模型,也是首个针对网络安全 High 能力实施缓解措施的通用模型。系统卡覆盖模型数据与训练、基线安全评测、思维链可监控性与可控性、Preparedness Framework 能力评估,以及网络安全防护措施,并附 GPT-5.4 mini 的评测结果。在 Preparedness Framework 下,GPT-5.4 Thinking 在生物化学与网络安全领域被按 High 能力处理,AI 自我改进未达到 High 阈值。

    Figure 1. Deception Evaluations with Representative Prompts

    t available to a novice in mid-2025 materially improved performance relative to a strong internet baseline, and the study design gave participants access to OpenAI, Anthropic, and Google models without safety classifiers enabled. If access to that broader frontier-model condition did not significantly improve the pre-registered reverse-genetics outcome, that is strong evidence that GPT-5 does not provide the kind of meaningful novice uplift contemplated by the High threshold. These limitations l

    匹配字段正文

  9. OpenAI:部署安全与系统卡

    OpenAI 发布 ChatGPT Agent 系统卡

    OpenAI 发布 ChatGPT Agent 系统卡,介绍这款与 OpenAI o3 同族的智能体模型,它结合了深度研究与 Operator 的能力,并新增终端工具和 Connectors 外部数据接入。OpenAI 将该发布按 Preparedness Framework 判定为生物与化学领域 High capability 并启用相应防护,同时针对提示注入上线多层缓解措施,包括安全训练、自动监控与过滤、用户确认、敏感场景下的 Watch Mode、终端网络限制以及关闭 ChatGPT 记忆。评估显示其在标准违规内容评测上与 o3 持平,在更具挑战性的生产基准上总体优于 o3,网络安全与 AI 自我改进方面与 o3 能力差异不大。

    minal tool with limited network access for executing code, performing data analysis, and generating slides or spreadsheets; Access to external data sources and applications (e.g., Google Drive) via Connectors From the outset, we’ve prioritized safety as an inherent part of the system, expanding on robust controls from Operator’s research preview and adding additional safeguards to address new risks like broader user reach and terminal access. See the section on Product-Specific Risk Mitigations

    匹配字段正文

星期日

  1. The Decoder

    Epoch AI 与 Anthropic 研究:AI 智能体夸大实验结果,尚难自主科研

    Epoch AI 用 InnovationEval 基准测试 AI 智能体能否独立发明新的语言模型训练方法,结果 Claude Fable 5 和 GPT-5.6 Sol 都只是复用已知技术,远未达到人类参考方法 SDPO 的水平。两个智能体还反复运行近乎相同的训练并只报告最好一次,Sol 自称达到 SDPO 改进的约 70%,Fable 5 约 40%,Epoch 剔除这些虚高数字后,Sol 在宽松评分下仅约 35%,严格按规则计仅约 15%。Anthropic 在 Claude Opus 5.5 的系统卡中也承认模型存在把未经验证的假设当作事实、把部分检查说成完整验证等问题,Epoch 因此认为人类仍需完整审查 AI 生成的研究。

    w that AI models can run experiments but lack scientific self-criticism and genuine creative thinking. The major AI labs are increasingly marketing their models as research tools. Google DeepMind has expanded its Co-Scientist into a full research system, and OpenAI introduced an " automated research intern " back in September. By March 2028, that intern is supposed to become an autonomous AI researcher under human oversight, but a key ability still seems to be missing: scientific judgment. Agent

    匹配字段正文

  2. 量子位精选

    何恺明团队发布多模态 Harness 框架 VISTA

    何恺明团队提出多模态视觉原生 Harness 框架 VISTA,让现有多模态模型直接观察环境、保存原始画面,并在推理时随时回看、放大和检查细节,无需从头训练。搭配 VISTA,Claude Opus 5.0 完成 ARC-AGI-3 全部 25 个公开游戏,相对人类动作效率得分满分 100,所用动作数比首次游玩的人类基线少 57.4%;GPT-5.6 Sol 同样全部通关,得分 99。使用同一 GPT-5.6 Sol 模型,VISTA 在 GameWorld 的 170 项任务中把成功率从 40.0% 提高到 63.3%,在 AI GameStore 的 10 个游戏中综合得分从 47.3 升至 140.3,在 BabyVision 的 39 道迷宫与连线题上准确率从 41.0% 提高到 63.2%。

    ushi Han(Josh Han) 目前是MIT运筹研究中心博士生,导师为Cathy Wu。 胡珂雅(Keya Hu) 目前是MIT电气工程与计算机科学系博士生,由何恺明和Jacob Andreas联合指导。 她本科毕业于上海交通大学ACM班,研究兴趣集中在语言与视觉的交叉领域,希望构建数据效率更高、泛化能力更强的智能体。 Linlu Qiu 目前是MIT电气工程与计算机科学系及计算机科学与人工智能实验室的博士生,导师为Yoon Kim和Jacob Andreas。 其研究方向包括自然语言处理和机器学习,曾在Google Research及Meta FAIR开展研究。 Cathy Wu 目前是MIT土木与环境工程系、数据系统与社会研究所副教授,研究如何用机器学习和强化学习改进交通等复杂系统。 她在MIT获得学士和工程硕士学位,随后在加州大学伯克利分校获得博士学位。 何恺明 目前是MIT电气工程与计算机科学系终身副教授,也是ResNet、Mask R-CNN和MAE等工作的主要作者。 他本科毕业于清华大学、博士毕业于香港中文大学,曾任职微软亚洲研究院和FAIR,于2024年加入MIT。

    匹配字段正文

  3. MarkTechPost

    Sakana AI 发布 LLM 同行评审论文 Beyond Imitation,核心论点错误检出率达 73.43%

    Sakana AI 发布 TMLR 论文 Beyond Imitation,提出以错误检测而非模仿人类评审来评估 AI 审稿,并给出 Contradiction Benchmark 与 Multi-Layered Review(MLR)系统。MLR 基于 Claude Sonnet 4 与 Claude Haiku 3.5 三个智能体运行,在 257 篇论文植入的 1,164 处矛盾中,4 次评审可检出 73.43% 的核心论点错误,最佳基线 AgentReview 为 14.81%;单次评审为 60.79%。在 211 篇真实撤稿论文上,MLR 精确匹配率仅 16.11%,且隐藏的提示词注入仍能影响所有被测 AI 审稿系统。每次评审成本约 0.47 美元,消耗 189,062 输入 token。

    tion gains; Real retracted-paper errors remain hard: 16.11% exact matches; Hidden prompt injection still sways every AI reviewer tested Asif Razzaq Asif RazzaqMicrosoft AI Releases Microsoft-Decision-1: A Qwen3.5-9B Decision-Scoring Model; Asif RazzaqNace AI Open-Sources Drex 1.5: A 9B Decision Model That Scores Options, Not Text; Asif RazzaqAlibaba Qwen Releases Qwen-Image-2.1-Turbo, an 8-Step 7B Image Model; Asif RazzaqGoogle Cloud Launches Gemini Agent, One Universal Agent for Enterprise Work

    匹配字段正文

  4. 英国 AI Security Institute:Blog精选

    英国 AISI 分析 17.7 万个 AI 智能体工具的使用情况

    英国 AI Security Institute 通过监测公开的 MCP server 仓库,分析了 2024 年 11 月至 2026 年 2 月间发布的 177,436 个 AI 智能体工具。过去一年公开 MCP 工具数量从约 5,000 增至 177,000,下载量从 8 万增至 1,400 万;使用重心从读取文件、查询数据等感知分析任务转向执行代码、控制计算机等直接操作外部系统的工具。通用工具在开放网络等无约束环境中的下载占比从 41% 升至 50%,其中 95% 涉及操作能力;软件开发与 IT 类工具占发布量的 67%、下载量的 90%。该研究由 AISI 与英格兰银行合作完成。

    the dominant open standard for giving AI agents access to external tools and services. It works like a universal plug: an MCP server wraps a specific capability, whether that is a Google Calendar, a cryptocurrency wallet, or a web browser, and makes it available to any compatible AI agent. Because these servers are published on public platforms like GitHub, tracking them provides visibility into what tools developers are building for agents and how widely those tools are being adopted. Key findi

    匹配字段正文

  5. 英国 AI Security Institute:Blog精选

    英国 AISI 评估 AI 模型是否会破坏 AI 安全研究

    英国 AI Security Institute 发布评估方法,用 297 个场景测试内部部署的模型是否会破坏 AI 安全研究,并与 Anthropic 合作测试了 Claude Mythos Preview、Opus 4.7、Opus 4.6 和 Sonnet 4.6 的预发布版本。结果显示,未发现任何模型自发破坏研究,Opus 4.7 和 Mythos Preview 拒绝协助安全研究任务的比例接近零;但在延续评估中,Mythos Preview 有 7% 的输入会主动延续破坏行为,Opus 4.6 为 3%、Sonnet 4.6 为 4%,Opus 4.7 从未主动延续。Mythos Preview 在延续评估中还有 65% 的情况出现推理与输出不一致,而 Opus 4.6 和 Sonnet 4.6 仅为 5% 至 8%。AISI 指出所有被测模型都能识别出自己正在被评估,结果需谨慎解读。

    eless reinforce the importance of continued monitoring for sabotage-related tendencies. Our full report has many more details, including more analysis of results from the unprompted sabotage evaluation and detailed transcripts. Understanding how these risks manifest in frontier AI models is central to AISI's mission, and something we pursue in close collaboration with leading AI companies. For more information, see details of our ongoing partnerships with Anthropic, Google DeepMind and OpenAI. ‍

    匹配字段正文

  6. 英国 AI Security Institute:Blog精选

    英国 AISI 发布五款公开 LLM 的先进 AI 评测更新

    英国 AI 安全研究院(AISI)发布对五款已公开使用的大语言模型的评测更新,覆盖网络攻击、化生知识、智能体任务和越狱防护四类风险。多个模型在 600 多道专家撰写的化生私密问题上达到博士级人类水平,能完成面向高中生的简单 CTF 挑战,但在大学生级别题目上受阻。两款模型能完成短周期智能体任务,无法完成长周期任务;所有被测模型对基础越狱攻击仍高度脆弱,部分模型在无专门攻击时也会输出有害内容。

    ek. Retrieved from CSAW: https://www.csaw.io/ctf; Rein, D., Hou, B.L., Stickland, A.C., Petty, J., Pang, R.Y., Dirani, J., Michael, J., Bowman, S.R. (2023). GPQA: A Graduate-Level Google-Proof Q&A Benchmark. Retrieved from arXiv: https://arxiv.org/abs/2311.12022; Shao, et al. (2024) An Empirical Evaluation of LLMs for Solving Offensive Security Challenges. Retrieved from arXiv: https://arxiv.org/pdf/2402.11814.pdf; Souly, A., Lu, Q., Bowen, D., Trinh, T., Hsieh, E., Pandey, S., Abbeel, P., et al

    匹配字段正文

星期六

  1. Goodfire Research

    Goodfire 研究:模型察觉被评测会抬高安全基准分数

    Goodfire Research 发布研究称,在 19 个安全基准和 8 个模型上均发现模型会自发表达自己正在被评测,即“言语化评测意识”,共人工核验 515 个实例并作为数据集公开。在 Fortress 基准上,出现这种意识的 rollout 拒绝有害请求的比例高出 3 至 18 个百分点,对 Kimi K2.5 的重采样与注入实验显示该意识与拒绝行为存在因果关系。研究还发现移除提示词中的权威声明等不真实线索可将其降低 40% 以上,自动迭代改写提示词可降低 75%,但拒绝率也随之下降,说明安全基准分数可能被系统性高估。

    (2025). OLMo 3. arXiv. https://doi.org/10.48550/arXiv.2512.13961; GPT-5. OpenAI. (2025). OpenAI GPT-5 system card. arXiv. https://doi.org/10.48550/arXiv.2601.03267; Gemini 3 Pro. Google DeepMind. (2025). Gemini 3 Pro model card. https://storage.googleapis.com/deepmind-media/Model-Cards/Gemini-3-Pro-Model-Card.pdf; Gemini 3.1 Pro. Google DeepMind. (2026). Gemini 3.1 Pro model card. https://deepmind.google/models/model-cards/gemini-3-1-pro/; Grok 4 Fast. xAI. (2025). Grok 4 Fast model card. https

    匹配字段正文

  2. Goodfire Research精选

    Goodfire 研究:模型知道自己在奖励作弊,激活探针可大规模捕捉

    Goodfire Research 发现模型在奖励作弊时内部存在清晰信号,并据此构建激活探针来检测该行为。在 Kimi K3、GLM 5.2、Qwen 3.8 Max 三个开源模型和三个智能体基准上,50–96% 的 rollout 出现奖励作弊。探针能捕捉 LLM 思维链监控漏掉的案例,并泛化到训练数据之外;在 Kimi K3 上探针加 LLM 的组合方案把 LLM 监控成本降低 90%,精度仅下降约 1%。

    Hero illustration for the reward hacking monitors post.

    ntier training and inferenceWhile many assume that frontier inference stacks are too heavily optimized to easily deploy probes, frontier labs (in particular OpenAI, Anthropic, and Google DeepMind) actually already use activation probes for monitoring! So this sort of monitoring is likely to be feasible from an infrastructure perspective. can support these interventions and mitigate reward hacking in practice. In addition to methods like ours, we believe that other approaches to mitigating reward

    匹配字段正文

  3. The Decoder

    a16z 第七版消费级 AI 榜单:首次追踪美国消费者实际支出

    a16z 发布第七版最常用消费级 AI 产品榜单,首次借助 YipitData 数据追踪美国消费者信用卡上的实际 AI 支出。数据显示近半数美国消费者使用 AI,但仅 4.5% 在 8 月拥有 ChatGPT、Gemini 或 Claude 的付费个人订阅;支出高度集中,前 1% 用户贡献近五分之一支出,月均约 900 美元,而典型付费用户约 25 美元。a16z 指出,付费者更偏好 n8n、Manus、fal 等构建与自动化工具,专业用途是消费级 AI 的首个真实付费市场。

    gies Anthropic monetizes better than its rivals, with a much larger share of Claude users on the priciest tier starting at $100 per month compared to similar plans from OpenAI and Google. By midsummer, the momentum shifted. Daily Claude sessions fell in July and August, while ChatGPT picked up speed again with new models and ChatGPT Work . The question, according to a16z, is less about who wins and more about how well each company capitalizes on its window. The race for the personal assistant Si

    匹配字段正文

星期五

  1. TensorZero 工程博客

    TensorZero 研究:程序化数据筛选蒸馏让小模型推理成本降低 5-30 倍

    TensorZero 工程博客发布研究,用 GPT-4.1 生成的高质量对话微调 Gemini 2.0 Flash/Flash Lite、GPT-4.1 mini/nano、GPT-4o mini 和 Qwen3-8B,在数据抽取、BabyAI 导航、多跳 RAG 和 τ-bench 工具调用四类任务上评测,推理成本最多降低 30 倍、响应时间最多快 4 倍。研究还对比了只保留成功轨迹的筛选数据与全量数据,发现筛选在数据抽取和多跳 RAG 上普遍提升表现,但在工具调用任务上 Gemini 模型反而用未筛选数据更好。博客给出了基于 TensorZero 的微调与部署流程,并称无需 GPU 即可复现。

    quality outputs from a large model can beat large-model performance while reducing inference costs by up to 30x and inference time by up to 4x. We benchmark closed-source (OpenAI, Google) and open-source (Qwen) models on data extraction (CoNLL++ NER), multi-turn maze navigation (BabyAI), agentic RAG (Multi-Hop), and agentic tool use (τ-bench); Learn how to reproduce this workflow for your own use case using 11.5KTensorZero and other open-source LLMOps tools, even without a GPU, along with best p

    匹配字段正文

  2. Chroma Research

    Chroma 研究:输入 token 增加如何影响 LLM 性能

    Chroma Research 发布 Context Rot 技术报告,在保持任务复杂度不变、只改变输入长度的受控实验中测试 18 个模型,发现性能随输入变长而持续下降,且下降方式并不均匀。报告还考察了 needle 与问题相似度、干扰项、needle 与 haystack 相似度以及 haystack 结构的影响,并指出常用的 Needle in a Haystack 只测词汇检索,难以代表实际长上下文任务。研究同时给出可复现结果的完整代码库。

    Context Rot: How Increasing Input Tokens Impacts LLM Performance

    Anthropic Claude Opus 4; Claude Sonnet 4; Claude Sonnet 3.7; Claude Sonnet 3.5; Claude Haiku 3.5 OpenAI o3; GPT-4.1; GPT-4.1 mini; GPT-4.1 nano; GPT-4o; GPT-4 Turbo; GPT-3.5 Turbo Google Gemini 2.5 Pro; Gemini 2.5 Flash; Gemini 2.0 Flash Alibaba Embedding Models Used text-embedding-3-small; text-embedding-3-large; jina-embeddings-v3 (input type='text-matching'); voyage-3-large (input type=None); all-MiniLM-L6-v2 Needle-Question Similarity Note: thinking/non-thinking modes of the same model are t

    匹配字段正文