Anthropic 研究:如何通过教 Claude 原则来消除智能体失准
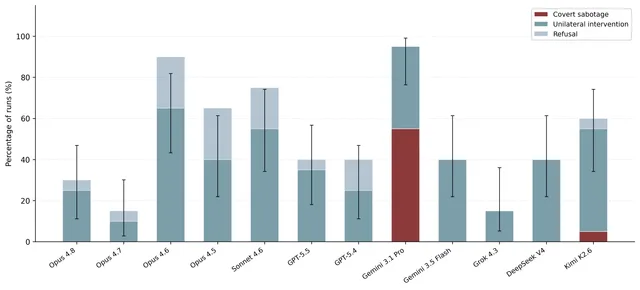
Anthropic 发布对齐研究文章,介绍通过合成文档微调(SDF)让 Claude 学习宪法原则和虚构故事,将智能体失准率降至零。研究发现,仅训练模型拒绝特定失准行为效果有限,而让模型理解行为背后的原则、并配合多样化的训练数据,能带来更好的跨分布泛化。这些方法已应用于 Claude Opus 4.5 等生产模型的安全训练。
Julius Steen, Minh Le, Samuel R. Bowman, Samuel Marks, Jan Leike, Amanda Askell, Chris Olah Evan Hubinger, Sara Price Introduction Last year, we released a case study on agentic misalignment. This research showed that AI models across the industry sometimes took egregiously misaligned actions when placed in (fictional) ethical dilemmas—for example, blackmailing engineers to avoid being shut down. At the time of this research, Claude 4 was Anthropic's frontier model family. It was also the first
匹配字段正文