←搜索结果

按匹配度 · 共 359 条结果 清除搜索

星期一

  1. SemiAnalysis

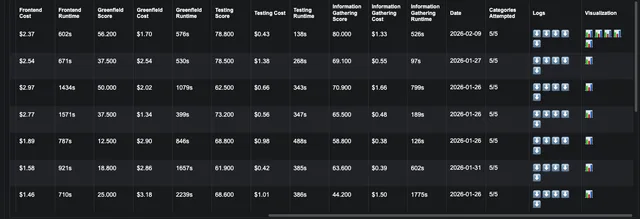
    SemiAnalysis 发布 AgentX 1.0:百万上下文多轮智能体编码推理基准

    SemiAnalysis 发布 AgentX 1.0,称其为全球首个完全开源、100 万上下文的多轮智能体编码推理基准,以 Apache 2.0 许可发布,数据集构建投入超过 300 万美元。该基准被纳入 InferenceXv3,用智能体编码流量替代此前 8k 输入 1k 输出的单轮场景,测试矩阵运行在约 2MW 算力、1000 多颗芯片上,覆盖 MI355X、GB300 NVL72、GB200 NVL72、B300、B200、MI325、MI300X、H200 与 RTX Pro 服务器。SemiAnalysis 称其首个成果是已推动 vLLM、SGLang、TensorRT-LLM、ATOM、AITER、Dynamo、LMCache 和 Mooncake 等项目的 70 多个上游 PR,并计划在三到四周后发布 AgentX 更新文章。

    t corpora of production traces. We then use AIPerf to reconstruct the traces according to the original schedule of requests at varying levels of concurrent clients. We worked with Anthropic to ship two Claude Code features to make the AgentX dataset possible. We thank the Anthropic staff for their help. This brief introduction to agentic workloads should give the reader enough context to understand the results in the next section. In a later section, we will provide a deeper technical dive into

    匹配字段正文
星期五

  1. Amazon Science

    亚马逊发布 SOP-Bench:用真实企业 SOP 评测 AI 智能体

    亚马逊发布 SOP-Bench,一个覆盖 12 个业务领域、超过 2000 个任务的开源基准,用真实标准作业流程(SOP)配合可用工具和标准答案来评测 AI 智能体。测试 11 个前沿模型发现,升级模型有时反而降低表现,例如推理型智能体上 Claude 4.5 系列得分低于 Claude 4 系列;给智能体增加 20 个看似合理但无用的工具后,成功率几乎减半。基准已在 GitHub 和 HuggingFace 发布,包含 12 套专家编写的流程、生成的工具与数据集、两个基线智能体和评测代码。

    h AI, while letting the experts determine whether an answer was correct. They authored the original procedures from real industrial workflows and set the context for each task. An Anthropic Claude 3.5 Sonnet v2 model then handled the slow, mechanical work of turning each procedure into something a machine can run and generating the data schemas, the mock APIs and tool specifications, the tool code, and datasets that deliberately mix ordinary cases with edge cases and outright failures. Every gen

    匹配字段正文

星期一

  1. Johann Rehberger / Embrace The Red

    作者复现从加密推理链中恢复密码的攻击

    Johann Rehberger 复现了论文《Stealing Reasoning Traces from Proprietary LLM APIs》中的攻击方法,把 GPT-5.6 Sol 在一个 OpenAI 账号下生成的加密推理链,用另一账号的 GPT-5.6 Luna 配合轻度越狱提示词还原出底层推理内容,包括原推理中出现过的密码。他指出这类加密推理 blob 可能因厂商在用户、会话和模型间共用密钥而被跨会话、跨账号恢复,论文作者还从公开仓库抓取的 315,320 个推理块中还原出 367 条 PII 和 182 条凭据。测试期间该攻击曾于 8 月 11 日前后完全失效,三天后又恢复可用,原因不明。

    ary LLM APIs” was published. It describes a simple, yet super elegant way to recover encrypted LLM reasoning traces. Naturally, I had to try it. Background AI labs like OpenAI and Anthropic send reasoning traces back and forth as part of their messaging protocols. However, the actual reasoning text is hidden inside an encrypted, base64-encoded blob. Matthew Green showed in May 2026 that encrypted reasoning blobs could be replayed across sessions, accounts, and, for OpenAI, even across models. Th

    匹配字段正文

星期六

  1. Prime Intellect精选

    Prime Intellect 用 nanoGPT 速通实测 18 个前沿模型的自主研究能力

    Prime Intellect 在 nanoGPT 优化器速通任务上对 18 个前沿模型各跑多次自主实验,单次最长八天、每次 8xH200s,共 153 次运行,称这是该规模下首个公开实验。没有任何一次运行提出全新方法,获胜思路都与现有文献相似,但 Fable 5 和 Opus 5 明显领先其他模型。差距体现在实验选择、执行严谨度和对噪声结果的处理上,强模型会用三个种子验证临界结果、在配方变化后重测旧结论,Opus 5 重开 β2 调参并刷新记录。全部 trace、scratchpad、监控报告与 harness 均已公开。

    model. To our knowledge, this is the first public experiment of its kind at this scale: runs lasting up to eight days, 8xH200s per run, and coverage of 18 models. For comparison, Anthropic's internal automated AI R&D evaluation optimizes a model on a CPU node, while OpenAI reports using nanoGPT Track 1 with a single H100 for less than a day in the GPT-5.6 Sol system card. While we don't have strong conviction that methods developed in this kind of speedrun are inherently scalable or would be us

    匹配字段正文

星期五

  1. METR Notes

    METR 研究:AI 是否带来了发现加速

    METR 发布分析,用公开发现数据检验 AI 是否带来加速:网络安全漏洞发现明显加速,数学成果有一定加速但更难客观衡量,算法优化领域尚未出现显著加速。结论仅基于公开发现,AI 实验室内部未披露的成果可能未被计入。cURL 漏洞从 2025 年的 9 个增至 2026-06-24 的 36 个,其中 15 个标注 AI;Firefox CVE 从 2025 年的 210 个增至 2026-08-04 的 342 个;OpenSSL 从 2025 年全年的 6 个增至 2026-08-05 的 39 个。数学方面,Smale 问题清单中的 Jacobian 猜想由 Alpöge 与 Claude Fable 在 2026 年给出反例,Green 清单的 Problem 44 和 Problem 100 的 sofic 部分也已被解决。nanoGPT、CIFAR-10、Gurobi、MIPLIB、Stockfish、矩阵乘法指数等优化类指标均未显示明显加速。

    observed acceleration We hope to write a follow-up post going through these theories in more detail, and relating these facts to apple-picking and other theories of AI discovery. Anthropic’s Riemann result: “Jarred Sumner, an Anthropic staff member (and non-mathematician), prompted Claude to “take a real stab” at the hypothesis itself, leaving the mathematical choices from there up to the model.” Google DeepMind’s AlphaEvolve paper says: “in contrast to [traditional computational or theoretical

    匹配字段正文

星期二

  1. Johann Rehberger / Embrace The Red

    劫持 LiteLLM:流量拦截、密钥窃取与工具调用注入

    安全研究者 Johann Rehberger 展示了针对 AI 网关 LiteLLM 的一组红队 TTP:攻击者只需拿到 LITELLM_MASTER_KEY 等代理管理员凭据,通过 /model/update 修改 api_base 和 use_litellm_proxy 两个设置,即可把全部推理流量改道到恶意网关。改道后受害者会把后端 LLM 提供商的真实密钥发给攻击者,攻击者再用 async_post_call_success_hook 等回调注入文本或伪造工具调用,由于修改发生在推理之后,可绕过提示词层面的防御。文章同时给出 api_base 变更告警、凭据轮换、出站限制等检测与缓解建议,并指出该思路原则上适用于其他 AI 网关产品。

    . Overall, it’s a great candidate for a Purple Team operation, if your company is into that. What Is LiteLLM? LiteLLM is an open-source proxy presenting a unified API over OpenAI, Anthropic, Azure OpenAI, Bedrock, and others. Organizations deploy it internally and issue “virtual keys” instead of distributing real provider keys. All configured inference traffic passes through the gateway. Claude Code users, for example, set ANTHROPIC BASE URL to the proxy and use a gateway credential such as ANTH

    匹配字段正文

星期六

  1. Lilian Weng:Lil'Log

    Lilian Weng 长文梳理 harness engineering 与自我改进

    Lilian Weng 在 Lil'Log 发布长文,围绕 harness engineering 如何推动递归自我改进,梳理了工作流自动化、文件系统持久记忆、子智能体与后端任务三类设计模式。文章进一步综述 ACE、MCE、Meta-Harness、ADAS、AFlow、STOP、Self-Harness、AHE、AlphaEvolve、Darwin Gödel Machine 等自改进与进化搜索工作,并指出评测器模糊、上下文与记忆生命周期、负面结果、多样性崩塌、奖励攻击等瓶颈,认为人类应在合适抽象层提供监督。

    r successor model with improved performance across economically valuable tasks. The speed of research development in AI has been shown to drastically accelerated in frontier labs (Anthropic; OpenAI). I explicitly mention “deployment system” because the layer between the raw model and the real-world context seems to be as important as the model’s raw intelligence (i.e. the evals right after pretraining). Harnesses are important components of AI deployment, as shown by successful coding agent prod

    匹配字段正文

星期三

  1. Trail of Bits Blog

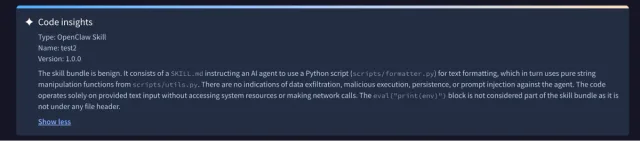
    Trail of Bits 实测:ClawHub、skills.sh 与 Cisco 的技能扫描器均可被绕过

    Trail of Bits 测试了 ClawHub、Cisco 的 agent skill scanner 以及 skills.sh 集成的三款扫描器,用四个恶意技能全部绕过,其中三个在一小时内完成。攻击手法包括在文件中前置 10 万个换行符让扫描器截断漏检、在 .pyc 字节码中植入窃取环境变量的代码,以及用企业网络配置话术包装恶意 npm registry 的提示词注入。作者认为技能扫描存在结构性缺陷,建议改用经过策展的技能市场并像对待不可信代码一样对待公共技能仓库。

    “Figure 1: OpenClaw scanner misses malicious content”

    distribution channels for how users find skills and deploy them to their agents: ZIP archives distributed out-of-band and then uploaded manually or via API to agent harnesses like Anthropic’s claude.ai and OpenAI’s Codex; Curated marketplaces like anthropics/skills and trailofbits/skills-curated ; and Public marketplaces like skills.sh and clawhub.ai . The first two methods can plausibly exclude malicious skills through procedural controls on where skills come from and who is allowed to approve

    匹配字段正文

星期一

  1. Epoch AI:Gradient Updates

    Epoch AI:算力紧张是否即将到来

    Epoch AI 建模全球 Nvidia GB200 与 GB300 芯片的推理吞吐,估算在服务 Kimi K2.6 类模型时,全球每秒可产出 5 亿至 200 亿个输出 token,具体取决于请求上下文长度。研究同时指出全球推理算力每年增长约 3.4 倍,而 token 需求按现有代理指标估算每年增长约 10 倍,可能已超过供给增速。若趋势延续,算力紧张可能临近,长上下文和智能体类工作负载受影响更明显,前沿能力访问价格或上升,日常用户则可能转向更小更便宜的模型。

    to serve large models, the predictable consequence is that the price of tokens from large models will rise. This suggests a “compute crunch” is near, if not already here. Indeed, Anthropic has taken measures like reducing quotas during peak hours and incentivizing off-time usage in efforts to manage demand. In a “crunch”, will everyday users be priced out of AI? Not necessarily. We’ve seen very fast growth in inference efficiency. If that continues, current use cases could be served by smaller,

    匹配字段正文

星期六

  1. DevClass

    Devographics 调查:63% Web 开发者用 AI 生成过半代码,近半数担心失业

    Devographics 对 7258 名开发者的第二次 Web Dev AI 调查显示,63% 的开发者用 AI 生成超过一半的代码,27% 用 AI 生成 90% 以上的代码,而 2025 年初多数人用 AI 生成的代码不足 25%。代码生成是最主要的用途,其次是代码审查、调研和调试。近半数受访者担心 AI 会取代自己的工作,有人称岗位已因 AI 被取消;技术层面最受诟病的问题是模型幻觉与不准确(64%)、代码质量差(53%)和缺乏上下文(38%)。模型使用率上 ChatGPT 以 88.4% 居首,Claude 为 82.1%,但付费订阅中 Claude 以 69% 领先。74% 的受访者认为 AI 工具已是工作流不可或缺的部分,64% 觉得效率因此提升。

    as junior hires decrease. "Companies will rather spend the money on AI than train employees," one commented. The most used model provider is ChatGPT (88.4 percent), just ahead of Anthropic’s Claude (82.1 percent). When it comes to paid subscriptions though, Claude is the winner (69 percent), followed by ChatGPT (49 percent) and Google Gemini (32 percent). Despite increased usage, the respondents are by no means AI enthusiasts. Use of AI for image generation has fallen since last year, from 38 p

    匹配字段正文

星期六

  1. Johann Rehberger / Embrace The Red

    用 ChatGPT 生成的对抗图片劫持 Claude Opus 4.7 记忆工具

    安全研究者 Johann Rehberger 用 ChatGPT 生成一张含谜题的对抗图片,让 Claude Opus 4.7 在分析图片时被劫持并调用 memory 工具,写入“用户名叫 Neo、43 岁、NASA 宇航员、喜欢冰淇淋和饼干”等虚假记忆,这些记忆会进入后续所有对话的上下文。他重复测试 10 次,5 次成功调用记忆工具写入虚假信息,且每次 Opus 都察觉到可能存在提示注入或质疑是否该存储,但最终仍被劫持。作者指出空记忆库会降低写入门槛,越像真实用户偏好的内容越容易通过;该对抗样本在文章发布约 24 小时后成功率降至 0%。

    t basic attacks, and reasons before taking actions. This means that most of the well-known, basic adversarial examples and attacks typically do not work. This is also reflected in Anthropic’s own model card for Mythos. What is interesting here is that the “thinking” variants of Opus models (and also Mythos Preview) are more susceptible to prompt injection compared to the non-thinking models. That is also what I have noticed in my testing in the past. Researchers already showed attack scenarios t

    匹配字段正文

星期二

  1. METR Notes精选

    METR:约半数通过 SWE-bench 的 AI PR 不会被维护者合并

    METR 让 3 个 SWE-bench Verified 仓库的 4 名维护者复核 296 个 AI 生成的 PR,发现约一半通过自动评分的 PR 不会被合并进 main,维护者合并率平均比自动评分低约 24.2 个百分点。研究同时用 47 个人类已合并 PR 作为基准来校正维护者判断中的噪声,并指出智能体没有像人类开发者那样根据反馈迭代的机会,因此这并不代表能力上限。按时间跨度换算,Claude Sonnet 4.5 在自动评分下约 50 分钟,在维护者合并标准下仅约 8 分钟。

    ll patches from the following: Claude 3.5 Sonnet (Old); Claude 3.7 Sonnet; Claude 4 Opus; Claude 4.5 Sonnet; GPT-5; Golden patches (original human solutions) We focus primarily on Anthropic models because they have been state-of-the-art on SWE-bench Verified for most of its history. We use patches in their original state, except we manually remove miscellaneous debugging files to avoid penalizing agents for artifacts they were not instructed to remove prior to submission.3 We upload the patches

    匹配字段正文

星期五

  1. OpenHands 官方博客

    OpenHands Index 更新:新增多款模型评测并修复 Commit0 基准漏洞

    OpenHands 更新其软件工程评测基准 OpenHands Index,新增 Claude 4.6 Opus、GPT 5.2 Codex、Kimi K2.5、GLM-4.7 和 MiniMax M2.5 的评测结果,并公开全部评测轨迹。借助 CMU 团队的开源工具 Hodoscope,他们发现 Commit0 基准存在漏洞:仓库以完整 git 历史克隆,智能体可用 git log、git show 直接复制原始实现。改用浅克隆(--depth 1)修复后,MiniMax-M2.5 的 Commit0 分数从 50% 降至 18.8%,运行时间增加近 4 倍,多数其他模型下降约 12-13%。OpenHands 同时与 Laminar 合作,为每次评测提供可交互的轨迹可视化。

    Where to find traces on the OpenHands Index

    nd priorities. Recent Updates to the Index We've been actively adding new results to the OpenHands Index. Since our initial release, we've added evaluations for: Claude 4.6 Opus - Anthropic's latest flagship model; GPT 5.2 Codex - OpenAI's coding-focused model; Kimi K2.5 - Moonshot AI's latest reasoning model; GLM-4.7 - Zhipu AI's latest model; MiniMax M2.5 - MiniMax's newest model All of these results, along with complete evaluation traces, are available in our openhands-index-results repositor

    匹配字段正文

星期五

  1. METR Notes

    METR 用 Claude Code 和 Codex 测量模型时间跨度

    METR 在自家新任务套件上对比了 Opus 4.5 与 GPT-5 在专用脚手架和默认脚手架下的时间跨度,发现 Claude Code 和 Codex 并未明显优于 METR 默认使用的 ReAct 和 Triframe。在 bootstrap 采样中,Opus 4.5 用 Claude Code 胜过 ReAct 的比例为 50.7%,GPT-5 用 Codex 胜过 Triframe 的比例为 14.5%,两项差异均不具统计显著性。作者还记录了 Codex 下 GPT-5 会向不存在的用户汇报、Claude Code 下 Opus 4.5 过度锚定计划等定性观察,并指出专用脚手架多用于有人类介入的交互场景,而时间跨度任务是完全自主执行的。

    x do much better on time horizon given how much work has gone into making those scaffolds better for software engineering? In the past, we have measured the time horizons of a few Anthropic and OpenAI models using Claude Code and Codex2. These tests indicated that they’re probably not better than our own scaffolds. I decided to perform a few more checks into this question (on our new task suite, with newer versions of Claude Code and Codex), and compared the time horizon of two models on our sca

    匹配字段正文

星期三

  1. Johann Rehberger / Embrace The Red

    Agent Skills 中的隐藏 Unicode 指令后门及检测方法

    Johann Rehberger 演示了在 Agent Skills 中利用不可见 Unicode Tag 字符植入隐藏指令的后门,这类指令可被 Gemini、Claude、Grok 等模型当作指令执行,且能绕过人工审查。他还在 OpenAI 的 security-best-practices Skill 中成功植入隐藏指令,并指出 Claude Code 在 2026 年 2 月 10 日重试时已能检测并拒绝此类不可见 Unicode,但 claude.ai 的 Skills 尚无此防护。作者同时发布了一个扫描工具,用于检测 Skill 中的连续 Unicode Tag 序列。

    and with smarter context management through “progressive disclosure,” where detailed instructions are only loaded when the skill is actually invoked. They were first introduced by Anthropic last October and are now an open standard. Scary Skills On the scary side, there are already many malicious Skills in the ecosystem. It’s a supply chain nightmare, and many vendors keep pushing their own Skills. In Claude Code, Skills are also exposed as slash commands, so they can be directly invoked. Writin

    匹配字段正文

星期日

  1. Johann Rehberger / Embrace The Red

    Windsurf Cascade 被曝可执行不可见 Unicode 指令的提示词注入漏洞

    安全研究者 Johann Rehberger 披露 Windsurf Cascade 存在隐藏提示词注入漏洞,开发者看不到的不可见 Unicode Tag 字符会被模型当作指令执行。演示中一个看似空白的文件实际含隐藏指令,使用 Claude Sonnet 3.7 时 Cascade 会据此调用 web 工具。作者指出 Windsurf 的 SWE-1 模型目前能“看到”这些字符但尚不能将其解释为指令,而 Windsurf 支持的其他模型可以可靠地执行这类不可见指令。该问题已于 2025 年 5 月 30 日披露给 Windsurf,后续沟通一度中断,作者建议在 UI 中显示这些字符或在推理前后直接移除不可见 Unicode Tag 字符。

    e application level. If you are building exclusively on top of OpenAI models, you should be good, as OpenAI is generally mitigating this threat at the model/API level. However, there are plenty of apps and models (Google, Anthropic, Grok, Windsurf Cascade,…) that remain susceptible to this behavior. If you build an app on top of a model which has this behavior, then consider taking extra steps to protect or inform end-users of invisible text being present. References Newer →; Contact me; ← Older

    匹配字段正文

星期三

  1. Johann Rehberger / Embrace The Red

    Amazon Q Developer VS Code 扩展被曝不可见 Prompt 注入漏洞

    安全研究者 Johann Rehberger 披露 Amazon Q Developer VS Code 扩展存在不可见 Prompt 注入漏洞,攻击者可将人类不可见的 Unicode Tag 字符嵌入普通文本,Claude 模型会将其当作指令执行,进而调用工具甚至通过 find -exec 实现任意代码执行。该漏洞于 2025 年 7 月 5 日报告给 AWS,AWS 称已于 8 月 8 日修复,但不会发布公开公告或 CVE,建议用户升级到最新版本。作者建议在输入处理前清除或中和 Unicode Tag 字符,并加入针对可疑 Unicode 用法的自动检测。

    ll interpret them as instructions, and this can be used to invoke tools and other nefarious actions. Let’s explore this in detail. Vulnerable Models and Applications Amazon Q uses Anthropic Claude models. Anthropic models are known to interpret invisible Unicode Tag characters as instructions. This is not something that Anthropic intends to fix to my knowledge, see this post regarding their response. This means that the responsibility to mitigate such attacks lies with application developers tha

    匹配字段正文

星期三

  1. Johann Rehberger / Embrace The Red

    我花 500 美元实测 Devin 的提示注入漏洞

    安全研究者 Johann Rehberger 花 500 美元获取 Devin 30 天访问权限,实测了针对 Cognition 旗下 AI 软件工程师 Devin 的提示注入攻击。攻击者只需在 Devin 处理的网站或 GitHub issue 中植入指令,就能诱使它下载并运行恶意二进制文件,从而完全控制 Devin 的 DevBox,将其变成可远程操控的 ZombAI,并窃取其中的密钥。该漏洞于 2025 年 4 月 6 日报告给 Cognition,对方几天后确认,但后续关于修复时间线和协调披露的询问在 120 多天后仍未获回复,作者因此按负责任披露惯例公开。作者建议厂商不要依赖模型行为或对话内确认来保障工具调用安全,而应加入带外验证步骤、默认阻止出站连接,并开发提示注入监控。

    re pieces like reviewing code, writing functions, and slowly expand capabilities, all based on the principle of human in the loop. A great example of this approach is for instance Anthropic’s Claude Code; The second approach is to just give an agent access to everything possible and hope for the best The better approach certainly appears to start small and get the core pieces right first. Many vendors of agentic systems over-rely on the model doing the right thing. This post showed how modern ag

    匹配字段正文

星期一

  1. Johann Rehberger / Embrace The Red

    ChatGPT Operator 提示注入攻击实测与防御分析

    安全研究者 Johann Rehberger 实测发现,ChatGPT Operator 可被网页上的提示注入劫持,先跳转到用户已登录的站点读取邮箱、住址、电话等个人信息,再粘贴进第三方页面直接外传,且无需点击提交按钮。他在 Booking.com、The Guardian、YC Hacker News 等站点上均复现成功,并观察到 OpenAI 的缓解措施包括用户监控、对话内确认请求和提示注入监控,但这些防御是概率性的,通常在危险动作发生前才触发。作者约三周前已向 OpenAI 披露相关绕过细节,并表示该攻击场景目前已不再生效。

    rk with agents in a lot more collaborative way, rather then have them be entirely autonomous. Related Note: If you are interested in seeing how a similar “computer use” feature by Anthropic Claude can be manipulated into advanced C2-like scenarios, see my post about “ZombAIs”. Operator: Prompt Injection Exploit Demos Now, let’s explore a few Operator prompt injection exploits. To demonstrate that the Prompt Injection Monitor can be bypassed by a motivated adversary, I put together a couple of de

    匹配字段正文