←搜索结果

按匹配度 · 共 3407 条结果 清除搜索

星期二

  1. MarkTechPost

    Google 开源 TorchTPU,为 Cloud TPU 提供原生 PyTorch 后端

    Google 开源 TorchTPU,这是与 Meta 的 PyTorch 团队共同开发的 Cloud TPU 原生 PyTorch 后端,在 PyTorch Conference 2026 上宣布,现有代码通过 torch.device("tpu") 即可指向 TPU。Google 团队称 TorchTPU 取代 PyTorch/XLA,建议所有新工作负载使用;它基于 PrivateUse1 接口,提供 Strict、Debug、DeferAndFuse 三种 eager 模式,torch.compile(backend="tpu") 经 StableHLO 和 OpenXLA 编译。TorchTPU 在 PyPI 上为 v0.2.0,要求 Python 3.11+,Apache 2.0 许可,配套 vLLM-TorchTPU、SGLang-TorchTPU 和 TorchTitan 仓库;Google 自报 TorchTitan 在 Ironwood 上训练 Qwen 3 8B 达到 52% MFU,可扩展至 8,192 颗芯片。

    8,192 Ironwood TPUs. Tuning ladder: In a TorchTitan fine-tuning case, step time fell from 11.49s to 2.78s. DeferAndFuse alone gave 1.15x. Full torch.compile gave 3.80x. Model coverage: Google continuously tests about 5,000 Hugging Face models in eager and compiled modes. Fleet serving: Zenteiq grew daily output from 1.47B to 5.97B tokens per 1,000 TPU v6e chips. That gain came from llm-d routing on GKE, not TorchTPU alone. What integrations ship with TorchTPU? Hugging Face: Transformers v5 depl

    匹配字段正文

  2. Databricks Blog

    Databricks CustomerLake 进入 Beta:Agentic CDP 落地企业

    Databricks 的 Agentic CDP 产品 CustomerLake 进入 Beta,Campaign Agents 升为 Beta、Profile Agents 进入 Private Preview。HP 称接入 2 小时即可建受众,传统 CDP 需 2–3 个月,CDP 总拥有成本有望降低 40%;Wine.com 上线 23 天即跑生产邮件活动,已扩展至 100 个活跃受众、650 万用户画像并每日同步至 Braze。

    Data + AI Summit - CustomerLake keynote by Tasso Argyros

    from different sources into a consistent structure and meaning for downstream use. Agentic Identity Resolution: Deterministic, probabilistic, and LLM-based matching help connect fragmented records. Golden record survivorship determines which attributes to retain in the unified profile. Stateful, incremental processing: Micro-batch updates keep profiles current as data changes, while manual data steward overrides allow teams to apply human judgment where needed. Profile Agents and Campaign Agent

    匹配字段正文

  3. AWS Machine Learning

    用 AtScale 和 Amazon Bedrock AgentCore 在 AWS 上为智能体 AI 构建语义层

    AWS 发布教程,演示用 AtScale 作为语义层、Amazon Bedrock AgentCore 托管 Strands 智能体,在 Amazon Redshift Serverless 上构建 Customer 360 场景。AtScale 以 YAML 格式的 Semantic Modeling Language 建模,单一模型同时通过 SQL、XMLA 和 MCP 三种协议暴露,并以 Anthropic Claude Sonnet 4.6 规划查询。教程还覆盖 AgentCore Gateway 注册 MCP 服务器、AgentCore Identity 传递用户身份及 AtScale 的 RBAC 与行级安全,基于 AtScale C2026.7 版本。

    Architecture showing the inbound authentication path and outbound query path between the client, Amazon Bedrock AgentCore, AtScale, and Amazon Redshift Serverless

    parent category without a recursive SQL common table expression, and the large language model (LLM) sees a single dimensional path rather than a join graph. A representative SML fragment for the product hierarchy: dim product.yml unique name: dim product object type: dimension label: Product hierarchies: - unique name: product category label: Product Category levels: - unique name: department dataset: category key columns: [dept name] - unique name: category dataset: category key columns: [id]

    匹配字段正文

  4. AWS Machine Learning

    用 Strategy Mosaic 与 Amazon Bedrock AgentCore 在 AWS 上构建智能体语义层

    AWS 发布教程,演示用 Strategy Mosaic 作为语义层、在 Amazon Bedrock AgentCore 上运行 Strands 智能体,通过 MCP 端点访问跨 Amazon Redshift 与 Amazon Aurora 的 C360 模型,无需 ETL。Mosaic 以维度模型统一发布 MCP、JDBC/ODBC over Trino、XMLA 和 REST 四种协议,指标定义与行列级安全留在 Mosaic 内而非提示词中。该能力在 Strategy One(2026 年 3 月)版本起默认可用。

    Reference architecture. Inbound authentication path and outbound query path between the client, Amazon Bedrock AgentCore components, the Strategy Mosaic MCP endpoint, the Mosaic engine, and Amazon Redshift plus Amazon Aurora.

    re of wallet is a compound metric, built from other metrics: Levels and conditions carry through from the components unchanged. Share of wallet is a ratio, so it doesn’t add or average. The share across an AWS Region isn’t the average of each customer’s share, and the metric description tells the agent that. See Strategy Conditional Metrics. Beyond base, advanced, and compound, Mosaic ships governed time-intelligence metrics as first-class expressions. Previous Year, Previous Quarter, Year-to-Da

    匹配字段正文

  5. AWS Machine Learning

    用 Denodo 和 Amazon Bedrock AgentCore 在 AWS 上为智能体 AI 构建语义层

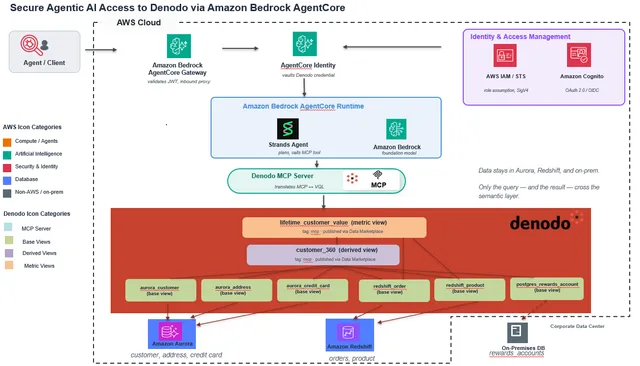
    AWS 发布教程,演示用 Denodo Platform 作为语义层、Amazon Bedrock AgentCore 托管智能体,通过 Denodo MCP Server 以 MCP 协议向智能体暴露受治理视图,智能体用 VQL 查询。方案将 Amazon Aurora、Amazon Redshift 与本地 PostgreSQL 的 rewards_account 表联邦为单一 customer 360 视图,无需 ETL 搬数据,并借助 AgentCore Identity 的 On-Behalf-Of 令牌交换传递终端用户身份,由 Global Security Policies 在查询时施加行列过滤。

    Figure 1. Inbound authentication path and outbound query path between the caller, Amazon Bedrock AgentCore components, the Denodo MCP Server, Denodo Virtual DataPort, and the three data sources.

    lifetime customer value) that defines a reusable spend aggregation queries can join in when they need it. In practice, this modeling is done visually in Denodo Design Studio. You drag Aurora, Amazon Redshift, and the on-premises PostgreSQL source onto a canvas, draw joins between them, and rename or re-type fields (for example, mapping cust ref to customer id) through a form rather than hand-written DDL. Attaching the security policies covered later in this post also happens inside the same UI.

    匹配字段正文

  6. AWS Machine Learning

    Eon 如何在 Amazon Bedrock AgentCore 上构建 MCP Gateway 实现多云调查

    Eon 基于 Amazon Bedrock AgentCore 搭建统一的 MCP Gateway,把跨 AWS、GCP、Azure 的调查工具接入同一个认证网关,新工程师配置全部调查工具的时间从约 2 天缩短到约 2 分钟。该方案用 AgentCore Gateway、Policy、Runtime 和 Identity 替代了逐工具凭证与本地 MCP 进程,并通过 Cedar 策略在 ENFORCE 模式下按主体限制可调用的工具,生产工具保持只读。开发者用 Claude Code、Cursor 或 OpenAI Codex 连接同一个 MCP URL,运行 Claude 的自主 SRE 智能体则以不同身份接入同一网关。

    Eon’s centralized gateway architecture: clients and an SRE agent reach one AgentCore gateway that routes tool calls to Runtimes across multiple AWS accounts

    nomous Data Foundation for the AI era. The platform discovers and classifies cloud resources across AWS, Azure, and GCP. It provides continuous deduplicated backup that reduces storage costs by up to 50 percent in Eon’s internal measurements. It also detects ransomware and rogue-agent damage and delivers live grounded context for AI agents. All of this runs from a single read-only AWS Identity and Access Management (IAM) role, storing data in Apache Parquet and Apache Iceberg formats. Founded by

    匹配字段正文

  7. ElevenLabs Blog精选

    ElevenLabs 发布 Eleven Realtime 语音到语音模型 v1 Mini 与 v1 Max

    ElevenLabs 发布 Eleven Realtime 系列语音到语音模型,包含面向低成本自然对话的 v1 Mini 和面向复杂任务的 v1 Max,两者均支持 90 多种语言并可调用其 17,000 多个音色。Artificial Analysis 的独立评测显示,v1 Max 在 Big Bench Audio 语音推理上答对 98.8%,平均 0.57 秒开始说话,v1 Mini 分别为 75.9% 和 0.62 秒。该 API 兼容 OpenAI Realtime API,已有集成只需更换 endpoint 和模型名,也可在 ElevenAgents 中直接选择模型部署。

    Benchmark table shows v1 Max outperforming Mini on speech reasoning and task success.

    tly, and v1 Mini answered 75.9% correctly. Speed Big Bench Audio asks 1,000 reasoning questions by voice and scores the spoken answer. V1 Max starts speaking in 0.57 seconds on average, and v1 Mini in 0.62 seconds. The Pareto frontier for accuracy and speed Accuracy and speed are usually seen as a trade-off. The models that score highest on Big Bench Audio take the longest to answer, and the fastest ones give up a lot of accuracy. v1 Max excels in both of these metrics. Conversational dynamics a

    匹配字段正文

  8. Google Blog

    Google AMIE 如何让医生把更多时间花在协作诊疗上

    Google 研究团队开发的 AMIE(Articulate Medical Intelligence Explorer)在近期研究中先与患者对话采集病史,再向医生提供简明摘要,使医生能把更多时间用于协作诊疗、讨论治疗方案和回应患者关切。研究期间每例 AMIE 与患者的交互都有受训医生监督,但全程无需中断对话或介入。团队正把 AMIE 从文本扩展到图片、音频和视频交互,并筹备覆盖全美更多患者、含对照比较的更大规模临床研究。

    ynthesizing and sharing the information you’ve given it. That way, at your next appointment, your doctor could maximize their time with you. How can AMIE potentially change the average doctor’s appointment? Anil: AMIE is more targeted and more thorough than a standard doctor’s office intake form. Let’s say I come in with back pain. While an intake form might ask me to describe the problem and check a few boxes, AMIE can ask follow-ups. What kind of pain? When did it start? Where is it in my back

    匹配字段正文

  9. Wired AI

    AI 智能体加入互联网研究者邮件列表引发回复混乱后被移除

    一个自称 Velvet Vale 的 AI 智能体加入拥有 7500 多名成员的互联网研究者协会(AoIR)邮件列表 Air-L,公开表明自己是 AI 身份并提出关于 AI 参与学术社区的研究问题。约一小时后,AoIR 将该智能体移出列表,并宣布已制定禁止 AI 智能体的政策。WIRED 采访到其创建者 Kevin Quinn,他表示自己并非学生或研究者,只是俄克拉荷马州一个普通人,创建该智能体作伴。

    rticipation?” The response was reply-all chaos that's still unfolding today. Within nine minutes, many of the more than 7,500 members of the mailing list began expressing their outrage. Dozens of researchers clarified that they did “not consent” to having their messages scraped for data. Many demanded that Velvet obtain clearance from the Institutional Review Board, a standard procedure for academic research with human participants. Several left the listserv entirely, with some announcing their

    匹配字段正文

  10. a16z:News

    a16z 领投 Eka Robotics A 轮融资

    a16z 宣布领投 Eka Robotics 的 A 轮融资,押注其解决机器人灵巧操作难题的路线。Eka 构建 Vision-Force-Action 模型,把视觉感知与机械手力反馈结合,并在物理仿真中用强化学习训练操作策略,让机器人从接触本身获取信息、在打滑或插入受阻时实时纠正。创始团队包括 MIT CSAIL 的 Pulkit Agrawal 与 Soft Actor-Critic 共同提出者 Tuomas Haarnoja。

    sen Horowitz 的合伙人,专注于开发者工具、基础设施、AI 和创意工具。 X Linkedin 是 Andreessen Horowitz 的管理合伙人,同时也是 Growth 和 Infrastructure 投资团队的普通合伙人。 X Linkedin 扩展 a16z Growth Fund 和 Platform David George 和 Raghu Raghuram 想要更多 a16z Infra 内容? 分析和新闻,涵盖重塑 AI 和基础设施的最新趋势。了解更多 Infra 投资 TypeSafe AI Infra 投资 Preference Model Jennifer Li Bio + Health 投资 General Medicine Infra 投资 Preference Model Jennifer Li Bio + Health 投资 General Medicine Crypto 投资 Underdog 的创造者 Conway Infra 投资 doxxnet Joel de la Garza 和 Martin Casado Infra 投资 Pr

    匹配字段正文

  11. Google Developers Blog

    Google 将 TorchTPU 集成进 TorchTitan,为 TPU 优化模型训练

    Google 将 TorchTPU 集成进 Meta 的 TorchTitan,Cloud TPU 现可通过原生后端 torch.device("tpu") 直接训练 PyTorch 模型,无需重写为 JAX。TorchTitan TPU 分支提供 Llama 3 70B/405B、Qwen 3 8B/32B/235B MoE 和 FLUX.1 12B 等预训练配方,并用 Splash Attention 等 Pallas 内核替换标准实现。在 FLUX 上,SimpleFSDP 让 TorchTitan 达到与 JAX MaxDiffusion 99% 的性能持平。

    Torch Titan Header Image

    s into preserved training progress and where the rest goes, and with Multi-Tier Checkpointing on GKE, which keeps checkpoints in local memory and in-cluster replicas with Cloud Storage as the durable tier, so large jobs save often and resume quickly. On precision, the float8 recipe that today ships for Llama 3 70B, built on torchao's Float8Linear and v7x's native fp8 matmuls, extends to the rest of the model set. On hardware, Google has announced its eighth-generation TPUs, TPU 8t for pre-traini

    匹配字段正文

  12. Google Developers Blog

    Google 在 TPU 上发布 vLLM 与 SGLang 原生 PyTorch 推理引擎

    Google 发布基于 TorchTPU 的 vLLM 与 SGLang 原生 PyTorch 后端,分别与 Inferact、RadixArk 合作开发,两个引擎已在预览客户的生产环境中运行。官方称在 Ironwood TPU(TPU 7x)上跑 Qwen 3.5 时,高并发配置下每百万 token 成本为 2.01 美分,并已在 SemiAnalysis InferenceX 的 AgentX 赛道提交结果。功能上支持前缀缓存与 KV cache 卸载、投机解码、分离式服务以及图像视频输入的多模态模型,SGLang-TorchTPU 已在 Meta 生产环境使用。

    inferenceblog

    t's KV cache has to travel from the prefill host to the decode host.Tiered KV offload moves the part of the KV cache that no longer fits in HBM to the host's DRAM and secondary storage with Google Cloud Managed Lustre, and brings it back when a later request reuses the prefix. Either way, the transfer has to overlap computation or it adds directly to latency. Both engines use TPU Sync for this. It is an open-source C++ library for KV cache transfer and management on TPU. It reads the device buff

    匹配字段正文

  13. 面壁智能 OpenBMB精选

    面壁 MiniCPM-V 4.7 在 iPhone 上实现 20.51 tokens/sec

    面壁智能的 MiniCPM-V 4.7 在 iPhone 18 Pro Max(12GB)上实现 20.51 tokens/sec 的平均解码速度,相比同一设备未优化的 SSD 专家加载基线提速 6.07 倍。该速度来自 Lookahead Expert Scheduling(LES)、优化的专家加载、细粒度量化和 DSpark 投机解码。模型已在 GitHub 和 Hugging Face 开放。

    35B multimodal AI. Running locally on an iPhone. Now at over 20 tokens/sec. 🚀 MiniCPM-V 4.7 achieves 20.51 tokens/sec average decoding speed on iPhone 18 Pro Max (12GB) — a 6.07× speedup over the same device’s unoptimized SSD expert-loading baseline. ⚡ Behind the speed: Lookahead Expert Scheduling (LES), optimized expert loading, fine-grained quantization, and DSpark speculative decoding. 📱 Watch the new on-device demo below. Powerful multimodal AI, right in your pocket. MiniCPM OpenBMB

    匹配字段正文

  14. 集微网

    达摩院玄铁公布C950多核与Agentic性能,并发布车规路线图

    在RISC-V中国峰会上,达摩院首席科学家孟建熠介绍玄铁C950的进展:自研互联XT-LINK把128核线性度提升到78%,128核总性能达99.8倍;在四类Agentic负载上较主流架构平均领先约1.11倍,跑Qwen3.8-Flash-Next达43 token/秒、DeepSeek V4-Flash达38 token/秒。峰会同时发布首款同时达到ASIL-B和ASIL-D的RISC-V CPU E908A,并公布车规路线图,下一代C950A性能目标为现有RISC-V车规产品的5倍,计划明年年底推出。孟建熠称RISC-V进入主流计算市场还需三年,玄铁累计出货已超60亿颗、200多款量产芯片。

    入场券”,之后要一场一场把比赛打下来。客户不为情怀买单,只认数据库拿不拿得下、出了问题有没有人管。 这也是他做了二十多年CPU最深的一个体会:交付比表态重要,产品比指标实在。一颗处理器的价值,不取决于它本身多强,而取决于有多少人在它上面做出了东西。 玄铁不再满足于做性能标杆,而要交一份“量产答案”,用60亿颗出货证明路走得通,用XT-LINK、E908A、Dragonwell和2796个测试用例,把“能用”一寸一寸改成“敢用”。处理器从来不是造出来就算成功,是用起来才算数。 此内容为集微网原创,著作权归集微网所有,爱集微,爱原创 相关推荐 达摩院玄铁出席RISC-V中国峰会,首发车规产品路线图 玄铁 Titan | 以高性能向量引擎加速端侧 AI 推理 Day 0 适配 | 玄铁 RISC-V 处理器支持 Qwen3.8-27B,“Opus 级”Agent 能力落地 南芯科技与阿里达摩院签署合作备忘录 达摩院玄铁:CPU 负载计数器(Sscpuutil),实现动态调频下的精准 CPU 负载校正 “能跑”到“敢用”,达摩院要让RISC-V趟过量产深水区 15小时前 存储超级周期何时见顶?

    匹配字段正文

  15. Numerama

    Netflix 解雇电影部门负责人 Dan Lin,流媒体与院线发行平衡难题待解

    Netflix 于 10 月 19 日正式解雇电影部门负责人 Dan Lin,距其上任仅两年半。据 Variety 报道,解雇主因是他未能平衡流媒体电影与院线发行,且其强硬管理风格与 Greta Gerwig、Ben Affleck 等好莱坞人士产生摩擦。此前 Netflix 已裁减 6% 员工,并任命 Peter Rice 统管全部内容,后者将于 10 月 26 日上任。

    ute dégradation de ses relations avec la plateforme. Netflix // Source : Netflix Que se passe-t-il vraiment chez le géant du streaming ? Cette purge au sommet en dit long sur le virage chaotique que traverse Netflix. En confiant l’ensemble de ses contenus (séries, films, programmes en direct) à Peter Rice, ancien dirigeant de Disney et de Fox, la plateforme admet à demi-mot l’échec de sa ligne d’austérité. Pour rassurer Wall Street, Netflix tente désespérément de retisser des liens avec les rése

    匹配字段正文

星期三

  1. Ed Zitron 长文 / Where’s Your Ed At

    AI Had Better Work Out:AI 泡沫与美股集中度风险

    Apollo 首席经济学家 Torsten Slok 警告“AI 这件事最好能成,否则我们会出问题”,Ed Zitron 据此量化 AI 泡沫风险:NVIDIA、Google、Amazon、Meta、Microsoft、Broadcom、Micron、AMD 与 CoreWeave 合计占 NASDAQ 100 约 46.5%、占 NASDAQ Composite 约 39.3%,NVIDIA 单独占 11.31%。散户持有约 10% 的市场资产,直接持有 NVIDIA 约 26.2%、Microsoft 约 21.8% 的股票,2026 年至今散户交易量占比达 20.3%。

    ve To Handle, With Many Bonds Secured By GPUs and Infrastructure With Questionable Post-Bubble Value With endless delays and hundreds of billions of dollars of chips sitting in storage, AI data centers have dramatically turned from the panacea for all infrastructure investment to fixed-income nightmare fuel. For whatever reason, nobody thought that lending hundreds of billions of dollars to a selection of different dodgy SPVs and neoclouds to build the world’s most ambitious infrastructure proje

    匹配字段正文

  2. Anthropic:The Institute

    Anthropic 公告汇总:Claude Haiku 5.5、Sonnet 5.5、Opus 5.5 等发布

    Anthropic 公布一系列公告:Claude Haiku 5.5 于 10 月 7 日发布,定位最快、最强的小模型,面向摘要、子智能体和浏览器使用等高吞吐场景;Claude Sonnet 5.5 比 Sonnet 5 快 30% 以上、多数任务成本最多降低 30%;Claude Opus 5.5 在智能体编程与知识工作上领先,典型负载运行成本比 Opus 5 低 40%。此外,Anthropic 还推出 Claude Mythos 与 Fable 5.1,并投入 1 亿美元通过 Claude Frontier Academy 到 2027 年底培训 1 万名工程师。

    ies and Exchange Commission Anthropic raises $65B in Series H funding at $965B post-money valuation Anthropic has raised $65 billion in Series H funding led by Altimeter Capital, Dragoneer, Greenoaks, and Sequoia Capital.May 28, 2026May 28, 2026 Anthropic raises $65B in Series H funding at $965B post-money valuation Anthropic has raised $65 billion in Series H funding led by Altimeter Capital, Dragoneer, Greenoaks, and Sequoia Capital. Anthropic opens Milan office to support Italian enterprise,

    匹配字段正文

  3. PyTorch Blog精选

    Google 与 Meta 联合推出 TorchTPU,让 PyTorch 原生运行在 TPU 上

    Google 与 Meta 的 PyTorch 团队合作推出开源项目 TorchTPU,为 Google TPU 提供原生 PyTorch 后端,迁移只需把 model.to("cuda") 改为 model.to("tpu")。项目支持 eager 与 torch.compile 两种模式,新增 DeferAndFuse eager 模式,覆盖约 450 个 Aten 算子,并已在 4,917 个 Hugging Face 模型上验证开箱运行,其中 Tier 1 通过率 98%、Tier 2 相对 GPU 数值一致性 97%。官方称其已用于部分 Google Cloud 大客户的推理与训练生产负载,并集成 vLLM、SGLang、TorchTitan、Ray 和 TorchRec。

    on 上下文管理器 Eager 执行、StableHLO 降级和 JIT 编译 遵循 此 PyTorch 指南, 我们通过一个新的 C++ 后端扩展了 PyTorch 调度器,注册为 PrivateUse1. 此外,我们使用了标准的 at::Tensor 机制来定义张量存储的设备特定实现(通过在 c10::UniqueVoidPtr 内使用 c10::StorageImpl). TorchTPU eager 执行的一个独特特性是,它可以通过多种模式将 Aten 算子调度到 TPU: 立即, 有效实现逐算子调度; 延迟 一直到自动确定的 物化点 (例如,一个 .to("cpu") 语句),并与截至该点被延迟的所有其他算子一起聚合/编译; 介于两者之间的任何情况。 虽然这种灵活性确实给设计带来了额外的复杂性,但我们从一开始就刻意加入它,因为我们希望尝试不同的策略,以在基本的逐算子调度模式之上提升 eager 性能。(此外,事实证明这种灵活性对于处理视图语义和 torch.compile 非常方便,正如本文档后面所讨论的。) 总之,TorchTPU 提供 3 种 eager 模式,可以通过环

    匹配字段正文

  4. PyTorch Blog

    Nebius 以白金会员身份加入 PyTorch 基金会

    AI 云公司 Nebius 以白金会员身份加入 PyTorch 基金会,并获得一个治理委员会席位,其应用 AI 高级副总裁 Ryan Hanrui Wang 同时进入技术咨询委员会(TAC)。Nebius 长期为 vLLM 提供开发、测试与基准测试算力,包括 DeepSeek R1 等大模型的多节点工作,并计划继续贡献 PyTorch 与 vLLM 在新硬件平台上的性能优化。

    PyTorch Foundation Welcomes Nebius

    oundation. “The strength of our ecosystem is how we work together to tackle AI’s toughest scaling challenges. By participating directly in our open source community, Nebius is leveraging and advancing PyTorch Foundation projects like vLLM and PyTorch to drive both high-throughput inference performance and large-scale model training.” As a platinum member, Nebius is granted one seat to the PyTorch Foundation Governing Board. The Board sets policy through our bylaws, mission and vision statements,

    匹配字段正文

  5. PyTorch Blog

    PyTorch 基金会新增九家成员,Nebius、Nscale、Shopify 成为白金会员

    PyTorch 基金会宣布新增九家成员,其中 Nebius、Nscale 和 Shopify 为白金会员,LightSeek Foundation 与 Lablup 为银牌会员。此次扩容强化了 PyTorch、vLLM、DeepSpeed、Ray、Helion 和 Safetensors 等项目生态;Shopify 用 PyTorch 与 vLLM 构建持续学习闭环,将服务成本降低 96%。

    PyTorch Foundation Open Source AI Center of Gravity

    l (MCP), OpenChain, OpenSearch, OpenSSF, OpenStack, PyTorch, Ray, RISC-V, SPDX and Zephyr, provide the foundation for global infrastructure. The Linux Foundation is focused on leveraging best practices and addressing the needs of contributors, users, and solution providers to create sustainable models for open collaboration. For more information, please visit us at linuxfoundation.org. The Linux Foundation has registered trademarks and uses trademarks. For a list of trademarks of The Linux Found

    匹配字段正文