←搜索结果

按匹配度 · 共 3407 条结果 清除搜索

星期二

  1. MIT Tech Review

    MIT Tech Review 每日速览:Goodfire 研究者的 LLM 可解释性主张与互联网的智能体难题

    MIT Tech Review 的 The Download 汇总了 Goodfire 研究者 Nick Cammarata 一篇 26,000 字博文引发的争议,他主张 LLM 可能比此前认为的更容易被理解和监控,但并非所有人都认同。另一则内容讨论个人 AI 智能体承担订机票、订酒店等在线任务后与网站产生冲突,许多网站已开始屏蔽 AI 智能体,Meta 的 Muse 上线首月下载量达 500 万次。速览还提到美国已禁止在民用政府系统中使用 DeepSeek 及其模型构建的产品。

    that demand keeps rising, the internet could be redesigned for agents rather than people. Find out what that could mean for the rest of us . —James O'Donnell Demand for energy storage is surging, with capacity expected to grow eightfold in the next decade. To meet that demand, Moment Energy wants to shortcut a supply chain that now flows largely through China by domestically repurposing EV batteries into new grid-connected storage systems. Ongoing trade battles between the US and China have bee

    匹配字段正文

  2. Cohere 产品与研究博客

    重新思考推理模型的置信度

    Cohere 提出 CALIBER 方法,训练推理模型在推理前估计解题成功率、推理后评估具体答案的正确概率。在数学基准上,7B 模型的校准误差从最强单置信度基线的 0.059 降至 0.028,降幅 52.5%,AUROC 达 0.806、Brier 分数 0.130。研究用 30,000 道数学题训练 7B 和 30B 模型,并在 1,000 道留出题及三个问答基准上评测。

    AI for utilities requires capability and control

    . Training rewards it for moving those predictions closer to their respective targets. We combine these confidence rewards with a reward for answering correctly. The model is encouraged both to solve the problem and to assess its chances accurately. Recognizing uncertainty about a wrong answer can improve its confidence reward, but it does not earn the reward for a correct solution. The aim is to make confidence more useful while keeping the model focused on getting the answer right. Why saying

    匹配字段正文

  3. ChinaTalk

    The Lithography Lever:为何应切断对华 DUV 出口

    美国智库 Center for Technology and Statecraft 联合创始人 Nick Brown 主张,美国应限制对华 DUV 浸没式光刻机出口与服务,以保住 AI 算力优势。2024–25 年中国每年进口约 90 台浸没式光刻系统,接近 ASML 浸没式出口的三分之二;若维持这一速度,中国有望在十年内追平美国的 AI 芯片制造能力。相关立法设想为 MATCH Act。

    ase for banning DUV exports to China: Why lithography is the hardest part of the semiconductor manufacturing stack for China to replicate/indigenize and the strongest point of leverage the US and its allies have over China’s future AI compute. The cannonball-sized hole in US export controls: China imported roughly 90 immersion lithography systems a year in 2024–25, nearly two-thirds of ASML’s immersion exports. If imports continue at this rate, China could approach or even reach parity with the

    匹配字段正文

  4. Anthropic Research精选

    Claude 设计抗蝎毒神经毒素蛋白结合体,211 个设计中 17 个达标

    Anthropic 让内部研究模型在 Claude Science 中自主设计针对蝎毒神经毒素的 minibinder,64 小时内生成 318,484 个设计并选出 180 个,加上团队补充的 31 个共 211 个交由 Adaptyv Bio 和 Twist Bioscience 实验测试,其中 17 个达到结合体标准。这 17 个均针对单一毒素,多毒素设计无一达标;最强候选 Cn2-B1 和 Cn2-B2 与 Cn2 的结合亲和力在个位数纳摩尔级,竞争实验显示它们与已知中和抗体 LR 结合同一表位附近。研究尚未在细胞或活体动物中验证中和效果,Anthropic 不称其为抗毒血清,并公开全部 211 个设计及数据。

    produced its final list of 180 designs. The campaign used on the order of 10,000 GPU hours. 2 Claude worked autonomously for 24 hours following our first prompt. Its results encouraged us to prompt Claude to continue its campaign and look for better designs. Our follow-up prompts were mainly focused on directing Claude to design a multitoxin binder. Claude selected most of the 180 designs—including our strongest binder (Cn2-B1)—only after our third follow-up. At our request, Claude sent the pro

    匹配字段正文

  5. Google Developers Blog

    Google 完成 Coral NPU 32 位架构并发布 v1.0 编译器

    Google 发布 Coral NPU 完整 32 位架构(含新增 Matrix Execution Unit,可配置至 1 TOPS、推理平均功耗目标 10mW)和基于 IREE/MLIR 的开源 Coral Compiler v1.0,支持 JAX、PyTorch、TensorFlow 模型直接编译到该硬件。完整 32 位 RTL 已在 GitHub 开放,Synaptics 同步推出搭载第二代 Coral NPU IP 的 Astra SR200 系列 MCU(400 GOPS)和 Coralboard SR 开发套件,Coralboard SL(1 TOPS)经 DigiKey 全球发售。两代产品共用同一架构与编译器,模型优化一次即可部署到毫瓦级可穿戴设备或 1 TOPS 板卡。

    blog-header-image-1600x900

    ed around a few standard software stacks, the edge is split across hundreds of proprietary chip architectures and incompatible toolchains. For ML developers, this creates a heavy fragmentation tax, where you end up rewriting kernels, re-quantizing models, and debugging vendor-specific compilers for every chip you target. Last year, Google Research introduced Coral NPU with a simple idea: an open hardware and software standard is the only way to unify the edge and unlock developer productivity an

    匹配字段正文

  6. TechSpot

    传闻:Nvidia RTX 6060 或推迟至 2029 年,性能将不及 PS6

    爆料者 Kepler_L2 称,Nvidia 下一代主流显卡 RTX 6060 可能因内存供应短缺推迟到 2029 年,性能预计仅接近 RTX 5060 Ti 或 4070,不及索尼 PS6。RTX 60 系列预计 2028 年推出,代际间隔可能拉长到近四年;RTX 6060 与 5060 的发布间隔至少 3 年 9 个月。Kepler 估算 PS6 仅内存和存储的物料成本就达 680 美元,整机售价可能远超 1000 美元。

    mpete with a single high-end AMD RDNA 5 GPU. The RTX 60 series is not expected until 2028, possibly extending the generational release gap to nearly four years, compared to the average gap of just over two years. A 2029 debut for the RTX 6060 would separate it from the 5060 by at least 3 years and 9 months. For comparison, the 5060 launched 4 years and 2 months after the 3060. As for estimating the RTX 6060's relationship to the PlayStation 6, it's obviously too soon for precise predictions, but

    匹配字段正文

  7. 邵猛

    MIT 课程 MAS.S62 两讲梳理 Harness 演化与多 Agent 演化

    MIT 课程 MAS.S62「How to AI an AI」的 Lecture 4-5 聚焦 Harness evolution,分别讲 harness 组件、记忆、工具与技能演化,以及规划、任务分解与多 agent 系统演化。记忆部分用三轴分类法串起 MemGPT、mem0、MEM1、Reflexion/ExpeL,并以 CLM 把上下文管理统一为文件操作;工具部分从 Toolformer、ToolLLM、CodeAct 讲到 Meta-Harness,后者把整个 harness 表示为文件系统,反馈信息量约为此前方法的 400 倍。多 agent 部分给出五条实证发现,包括 MAS 在可分解任务上赢 81%、在顺序依赖任务上输 70%,以及 CORAL 在 8 个任务上取得新 SOTA、多 agent 演化比单 agent 提升 4%–20%。

    选”,而 harness 复杂得多。Meta-Harness 把整个 harness 表示为文件系统,完整源代码、分数、全部执行轨迹都放在里面,让 proposer(Claude Code,用 grep/cat 阅读)把失败回溯到具体的 harness 决策上,反馈信息量是 prior 方法的近 400 倍(1000 万 token 对 2.6 万)。提示、RAG、Skills、工具、记忆、程序循环全部统一为文件系统中可优化的对象。 共同点:简单、无手工设计、端到端;可自主优化的对象沿“记忆 → 上下文 → harness”不断升维;且同一范式在 zero-shot、上下文学习、微调三种模式下都可扩展。这是整门课“自演化”思想最凝练的表达:不让 AI 在某一点上变强,不断扩大“什么是可以被 AI 自己改写的”边界。 Lecture 5:从规划到多 Agent,把玄学变成实证科学 https://t.co/9MfFAfLJV3 规划部分:三个关键问题 讲义先明确规划的核心问题:规划何时有用、何时有害?计划如何表示?何时该改计划? 结论清晰:基于提示的规划(CoT、Least-to-Mos

    匹配字段正文

  8. Aaron Levie

    Aaron Levie:模型越强,应用层越需按领域专业化

    Box CEO Aaron Levie 认为,模型能力越强、能处理更长任务和更好工具调用,应用层按领域差异化的空间反而更大,而非缩小。他指出模型能力有限时只能做“wrapper”,而智能体调用工具、运行数小时至数天的任务、协调 agent swarm、领域专属数据与模型路由,都让系统专业化程度可能上升。他预计安全、生命科学、医疗、金融、制造等领域将出现此前难以构建的自主系统。

    d in what they could do, ironically all you could be literally was a “wrapper” because you were effectively delivering tokens back to the user with a custom prompt or some limited RAG. But in a world of agents using tools, tasks that run on for hours or days, workflows that kick off agents, agent swarms that need to be coordinated against a goal, data sources that are domain specific, model routing that requires domain-specific routing, implementation that requires real change management of the

    匹配字段正文

  9. Rohan Paul

    摩根士丹利称英伟达风险回报最佳,但2027年91.7%收入依赖基础设施需求

    摩根士丹利认为英伟达在AI板块中风险回报最佳,但其2027年收入的91.7%依赖基础设施需求。该行预计超大规模云厂商和AI云服务商2027年支出达1.58万亿美元、增长约60%,其中近7000亿美元流向英伟达,而SpaceX与AWS约占其2027年超大规模客户收入的54%和增长的72%。摩根士丹利按2028财年15倍市盈率认为股价便宜,但其电力模型预计到2028年美国数据中心电力缺口达32GW,需求为97GW。

    and AI cloud providers to spend $1.58T in 2027, up roughly 60%, with nearly $700B reaching Nvidia. That haul leans on 2 buyers, with SpaceX and Amazon Web Services modeled at about 54% of Nvidia’s 2027 hyperscaler revenue and 72% of growth. Morgan Stanley still calls the stock cheap at 15 times fiscal 2028 earnings, arguing analysts underestimated 4 past compute cycles by 38% on average. Its own power model, though, projects US data centers falling 32GW short of the 97GW they need through 2028.

    匹配字段正文

  10. Artificial Analysis

    Artificial Analysis 上线 HealthBench 双榜单

    Artificial Analysis 为 OpenAI 的 HealthBench 与 HealthBench Professional 两个医疗对话基准推出排行榜。HealthBench Professional 上 GPT-6 Astra(max)以 66.0% 的长度调整分居首,GPT-6.1 Sol(max)65.1%、Claude Sonnet 5.5(max with fallback)63.0% 紧随;HealthBench 则由 Claude Sonnet 5.5 以 62.1% 登顶,DeepSeek V4.1 Flash 60.9%。Claude Opus 5.5 原始分最高(71.4%),但因平均回答约 5,900 字符、接近 2,000 字符阈值 3 倍,调整后跌至 59.9%。

    6.0%, $0.27). GPT-6 Luna (max) scores 4 points below GPT-6 Astra (max) at under 2% of the cost ➤ Claude Opus 5.5 and Claude Fable 5.1 receive the largest length penalties: Both average 5,900 characters per answer, nearly 3x the 2,000-character threshold, and lose over 11 points after adjustment. Claude Opus 5.5 (max with fallback) has the highest raw score (71.4%) but drops to sixth (59.9%). GPT-6 Sol (max) is the only model averaging under 2,000 characters ( 1,600), and the only one whose score

    匹配字段正文

  11. ElevenLabs Blog

    Hippolyte.ai 三周完成 4,830 场语音预筛选面试,借助 ElevenLabs 实现数据在欧处理

    法国招聘平台 Hippolyte.ai 在 Screen.ai 语音面试环节接入 ElevenLabs 语音合成,三周内完成 4,830 场语音预筛选面试、累计 272 小时对话,平均每场 3 分 23 秒,单日峰值 640 通。ElevenLabs 的语音处理在欧盟境内完成,双方签署 DPA,原始录音在转写后 24 小时内自动删除,以满足大客户的数据合规要求。

    Emmanuelle Benoliel

    compromise on data residency Over the first three weeks of September 2026, Hippolyte.ai conducted 4,830 voice screening interviews, representing 272 hours of conversation. The average interview lasted 3 minutes and 23 seconds, with a peak of 640 calls in a single day, versus an average of 302 calls per business day over the period. At this pace, the voice channel should represent nearly 20,000 conversations and 1,125 hours per quarter. And these volumes continue to grow as Hippolyte.ai activate

    匹配字段正文

  12. Data Center Knowledge

    表前电力会成为数据中心的下一个玩法吗?

    表前电力(front-of-the-meter power)指数据中心运营商参与建设向电网供电的发电容量,而非像表后发电那样只为自有园区供电,从而为电网增加供给。亚马逊在得克萨斯州一座大型 AI 数据中心项目上被指可能采用这一模式,但公开表态显示其仍在评估选项。该策略资本密集、运营复杂且面临监管障碍,目前仍处早期,多数运营商仍依赖公用事业合作、长期购电协议、储能和表后发电。

    s. For now, however, the concept remains in its early stages. Most data center operators are still relying on a mix of utility partnerships, long-term power procurement, energy storage, and behind-the-meter generation rather than directly building grid-serving power plants themselves. Will Front-of-the-Meter Power Catch On? That will depend on how severe grid constraints remain, how quickly grid utilities can expand service, and whether hyperscalers see a strategic advantage in taking a more dir

    匹配字段正文

  13. TechCrunch AI

    Mamdani 称联邦政府在 AI 监管上失职,呼吁纽约人反击

    纽约市长 Zohran Mamdani 在 AI Now Institute 主办的 The People's AI Assembly 活动上批评联邦政府在 AI 监管上“完全失职”,呼吁纽约人不要接受 AI 冲击就业与教育的“必然性”。他上月已下令禁止小学和初中使用 AI,今夏还推出政策要求房产挂牌照片或视频由 AI 生成时必须明确披露。Mamdani 称当前是“鲁莽地采用技术,却不对其局限做任何清算”。

    oad City” star Ilana Glazer, spoke about AI at Webster Hall in Manhattan on Monday night, with Glazer posing questions to the mayor about the future of AI in society. Mamdani encouraged New Yorkers to resist the overwhelming feeling that AI is inevitably coming for their jobs, their kids’ minds, and their dignity, and to take back control instead. His message came at a moment when the federal government is doing little to regulate AI, leaving cities to act on their own. At The People’s AI Assemb

    匹配字段正文

  14. 蚂蚁 inclusionAI:GitHub 新仓库精选

    蚂蚁 inclusionAI 开源 Ming-3.0-tts 语音合成模型,含 0.5b 稠密版与 tiny MoE 版

    蚂蚁 inclusionAI 在 GitHub 开源 Ming-3.0-tts 语音合成模型,包含 0.5b 稠密模型和基于 Ling V3 的 tiny MoE 模型(7.9B 总参数、1.3B 激活参数),提供推理代码、任务 Cookbook 和评测表。模型支持声音克隆、文本设计音色、100+ 中文与 5 种英文内置音色、自然语言自由控制、14 种副语言标签,可合成中英德西法韩日及川渝话、广粤话。官方称在 Artificial Analysis 榜单上,Controlled Voice 开源模型第 1、Pronunciation Robustness 总榜第 1(93.2%)、Provider Voice 开源模型第 3。

    Ming-3.0-tts Logo

    or 2nd on Japanese CER. Emotion: tiny ties for SOTA on CV3 text-related Happy and reaches SOTA on both CV3N Sad subsets; 0.5b reaches SOTA on CV3 text-related Angry. Tiny's CV3 average ranks 2nd. Attribute control: 0.5b leads the current comparison on average ACC and pitch, while tiny leads on WER and SIM. Historical Ming-omni-tts results still hold the corresponding overall records. Podcast: tiny achieves CER 2.03%, cpSIM 0.561 and UTMOS 2.12, ranking 1st, 2nd and 2nd; historical Ming-omni-tts

    匹配字段正文

  15. 蚂蚁 inclusionAI:GitHub 新仓库精选

    蚂蚁 inclusionAI 开源 vLLM-Omni 全模态模型推理服务框架

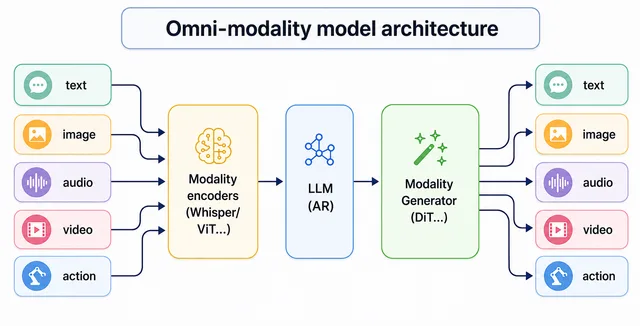
    蚂蚁 inclusionAI 在 GitHub 发布 vLLM-Omni 仓库,这是一个在 vLLM 基础上扩展全模态模型推理与服务的框架,支持文本、图像、音频、视频和动作数据处理,并支持 DiT 等非自回归架构。README 显示其已迭代至 0.30.0,对齐 vLLM 0.30.0,新增 MiniCPM-o 4.5 与 AURA 的全双工会话服务、Mooncake AR-to-DiT 跨阶段 KV 与多模态传输,以及在 NVIDIA Blackwell 和昇腾 950 上的 MiniMax H3 Turbo 实时推理。框架提供 OpenAI 兼容 API 服务、流式输出和分布式并行推理,并列出 Qwen3-Omni、MiniMax H3、Wan2.2、π0.5 等已支持模型。

    vllm-omni

    load, and broader model, hardware, streaming, TTS, and quantization support. [2026/07] We released 0.24.0 - aligned with the vLLM 0.24 release line, expanding production-ready coverage across TTS, speech, diffusion, image/video generation, and robot-policy serving, with major Omni stage runtime refactoring, diffusion request-level batching, async output materialization, quantization/cache/memory improvements, and broad CUDA/ROCm/XPU/NPU support. [2026/06] Starting with 0.14.0, vLLM-Omni publishe

    匹配字段正文

星期一

  1. Rohan Paul

    亚马逊论文:智能体记忆评测应直接检查存储事实

    亚马逊新论文指出,智能体记忆基准只评答案会混淆记忆、检索与作答环节,应直接检查每次更新后实际存了什么。团队构建 FEB-30(30 条脚本化事实历史、147 份文档),在类 Mem0 与 Hindsight 的记忆系统上对比存储事实与 QA 分数:两者平均相差 16.8 分,21% 的事实历史通过/失败判定不一致,系统选对 update、reinforce 等记忆动作的比例仅 20.1%。

    o the correct memory state is known after every document. On a memory system built like Mem0 and Hindsight, they compared the stored facts with that truth and with QA scores. The 2 scores differed by 16.8 points on average, and pass/fail verdicts disagreed on 21% of fact histories. The system picked the right memory action, like update or reinforce, only 20.1% of the time, which QA never showed. If you build agent memory, test the stored facts directly after each update, alongside end-to-end QA.

    匹配字段正文

  2. 腾讯云开发者社区

    SpringAI 客服安全合规实战:敏感词过滤、PII 脱敏与对话审计

    基于 SpringBoot 3.3.x 与 SpringAI 1.0.x,文章给出 AI 客服上线金融、政企场景的安全合规方案:用 DFA 算法做敏感词双向过滤,10 万词库匹配 1ms 内完成;在调用混元前用正则脱敏手机号、身份证号、银行卡号与邮箱;审计日志独立存储于腾讯云 CDB,只允许 INSERT、保留 5 年,并保留原始与脱敏两份记录。方案参照等保三级与《个人信息保护法》设计。

    I 1.0 作为 Spring 官方 AI 框架,与 SpringBoot 生态无缝集成,通过 OpenAI 兼容接口对接混元,数据不出腾讯云。相比 LangChain4j 更贴近 Spring 哲学,相比腾讯云 Agent 平台(CodeBuddy/WorkBuddy)更灵活可控。 核心经验三条: Advisor 链是架构骨架——所有横切逻辑(安全/限流/RAG/日志)通过 Advisor 链编排,业务代码保持纯净 多模型路由是成本关键——按复杂度选 pro/standard/lite,成本降 66% 安全合规是上线前提——敏感词/PII 脱敏/审计留痕不是可选项,是必选项 随着 SpringAI 生态成熟和混元能力增强,这套架构会持续演进。但核心方法论——抽象、编排、路由、治理、合规——不会过时。 真实性声明: 本文基于腾讯云 CDB/CLS + 混元实测。安全合规方案参照等保三级要求设计,PII 脱敏规则参照《个人信息保护法》实施。审计表权限控制在腾讯云 CDB MySQL 8.0 上验证。 如果本文对你有帮助,欢迎点赞、收藏、转发! 有任何问题或建议,请在评论区留言交流 关注我

    匹配字段正文

  3. Factory 研究 / 产品

    Factory 与 Databricks 达成合作:用数据驱动软件开发

    Factory 宣布与 Databricks 合作,客户可用 Databricks Data + AI Platform 中的数据与模型,为 Factory 构建或迁移的软件提供支撑。双方正帮助一家全球大型企业把承载数百个业务应用、PB 级数据和数十万张表的数据平台迁移到 Databricks,并把数据迁移与应用重建纳入同一工程流程。合格客户可通过 Databricks Marketplace 采购 Factory,使用其现有 Databricks 承诺额度中的最多 10%。

    Factory and Databricks partnership

    ng, monitoring, and enhancing applications built on or powered by data in Databricks. This includes building and evolving data-driven applications and AI-powered software that leverage the Databricks Data + AI Platform as an open, governed foundation. Migration and Modernization Factory can help teams analyze, plan, and execute data platform migrations to Databricks and the applications that depend on the data in Databricks. Cybersecurity Factory can help teams remediate vulnerabilities in the a

    匹配字段正文

  4. Newcomer 新闻长文

    Mercury 年化营收突破 10 亿美元,CEO 做客 Newcomer 播客

    Mercury 年化营收突破 10 亿美元,同比增长约 50%,客户数已超过 45 万,并正在推出薪资服务。CEO Immad Akhund 在 Newcomer 播客中披露了这些数据,还谈到 AI 智能体花钱、创业公司泡沫化以及疫情后 fintech 创业降温等话题。

    Eric Newcomer's avatar

    t hit $1 billion in annualized revenue, up around 50% year over year. The company now has more than 450,000 customers. It’s also launching a payroll service. But it wasn’t just a brag-fest: We talked about AI agents spending money, how he thinks we are in a bubbly moment for startups, and the cooldown in fintech startups after the pandemic frenzy. Give it a listen. The Newcomer Podcast We’ve featured guests like Amanda Askell, Reid Hoffman, Vinod Khosla, Keith Rabois, Tony Fadell, Ed Zitron, Ben

    匹配字段正文

  5. Timothy B. Lee:Understanding AI

    AI 正在开启个人媒体时代

    AI 音乐生成器 Suno 4.5 能把用户哼唱的片段转成完整编曲,作者借此把约 50 段旧录音生成数百首专业质感的歌曲,但听众只有自己。作者认为当“乐队”成本趋近于零,创作不再需要大众受众,这类“个人媒体”正随 coding agent 等工具一同兴起。

    equest away, the typical consumer may prefer consuming mass media as a shared cultural event. On the other hand, those shared cultural groups may grow ever smaller as the culture fragments in new and surprising ways. The ethics of enjoying personal media Generative AI is extremely divisive at the moment, and I understand why. It’s disruptive to the status quo along many dimensions. If used poorly in the arts, it can flatten the variety of human expression into a sort of mediocre pablum. If you a

    匹配字段正文