←搜索结果

按匹配度 · 共 1542 条结果 清除搜索

星期二

  1. Anthropic:Transformer Circuits精选

    Anthropic 研究:归纳头与上下文学习

    Anthropic 的 Transformer Circuits 发布论文,提出归纳头可能是 Transformer 模型中大部分上下文学习能力的机制。论文给出六条互补证据,包括训练早期的相变现象、架构扰动、消融实验,以及对 34 个模型训练过程和超过 50,000 次注意力头消融的分析。作者同时强调这些证据多为间接证据,尚不能完全确证该假设。

    systems. In particular, the phase change we observe forms an interesting potential bridge between the microscopic domain of interpretability and the macroscopic domain of scaling laws and learning dynamics. The rest of the paper is organized as follows. We start by clarifying several key concepts and definitions, including in-context learning, induction heads, and a “per-token loss analysis” method we use throughout. We then present the 6 arguments one by one, drawing on evidence from analysis o

    匹配字段正文
  2. Anthropic:Transformer Circuits

    Anthropic 提出 SoLU:将 MLP 可解释神经元比例从 35% 提升至 60%

    Anthropic 在 Transformer Circuits 发表研究,用 softmax linear unit(SoLU)替换激活函数,在性能基本不变的前提下,把 MLP 层中人类能快速找到清晰解释的神经元比例从 35% 提升到 60%(最大模型上增益更小)。研究同时发现 SoLU 可能通过压低某些特征幅度、再由 LayerNorm 恢复来“隐藏”它们,使部分原本不可解释的特征更难解释。

    ible! But many of these neurons appear to respond to several unrelated but individually understandable features, such as a neuron which responds to cat heads, fronts of cars, and paws. While we can't totally rule out that there isn't some deep commonality between a cat's paw and the front of a car, it seems like the simpler explanation is that the network has grouped several unrelated features together. We call these polysemantic neurons . Note that polysemanticity is what one would expect to ob

    匹配字段正文

  3. Anthropic:Transformer Circuits

    Anthropic 的机制可解释性愿景:从叠加问题到自动化可解释性

    Anthropic 的 Chris Olah 在《Interpretability Dreams》中阐述了机制可解释性的长期目标:当前研究聚焦解决叠加(superposition)问题,以建立理解神经网络特征与电路的“认知基础”。若突破这一基础,可望研究更大尺度的抽象结构、特征与电路的普适性,并将微观发现(如 induction heads)与宏观机器学习行为连接起来。最终目标是让可解释性服务于 AI 安全,并揭示神经网络内部的优美结构。

    extremely microscopic analysis of neural networks. Can we make useful predictions about macroscopic behavior? Can we explain exceptions in more macroscopic theories like scaling laws? Induction heads appear to be an example of a microscopic neural network phenomena with macroscopic effects. They can cause a visible bump in transformer language model loss curves. Induction heads are also likely to be responsible for a bump observed in the original scaling laws paper (see Figure 13: "The conspicu

    匹配字段正文

  4. Anthropic:Transformer Circuits

    Anthropic 可解释性团队 2023 年 5 月 Circuits 研究进展

    Anthropic 可解释性团队公布 2023 年 5 月 Circuits 研究进展,重点是用字典学习从叠加(superposition)中提取特征,即 Toy Models 论文中的“Approach 2”,并已着手搭建大规模系统研究的基础设施。团队提出把“特征”定义为激活的最简分解,用信息量衡量字典大小与稀疏编码的权衡,在合成数据上字典大小等于真实因子数时会出现“反弹”。团队同时列出字典学习的若干担忧,并强调这些结果属于初步实验而非成熟论文。

    this works, especially the section on LayerNorm. (We can file this as reason 78 for why interpretability researchers hate LayerNorm.) Can we explain learning dynamics and scaling laws in terms of circuits? We know that induction heads cause a loss bump in training when they form, and likely cause a bump in scaling laws. This suggests the tantalizing possibility of a deep bridge between the microscopic world of mechanistic interpretability and the more macroscopic topics of learning dynamics and

    匹配字段正文

  5. Anthropic:Transformer Circuits

    Anthropic 用字典学习分解语言模型,提取单义特征

    Anthropic 在 Transformer Circuits 发布研究,用稀疏自编码器对单层 Transformer 的 MLP 激活做字典学习,从 80 亿数据点中提取出比神经元更单义的可解释特征。研究聚焦 A/1 运行学到的 4096 个特征,发现阿拉伯文、DNA、base64、希伯来文等特征在神经元视角下几乎不可见,且激活这些特征能引导模型生成对应内容。作者还报告特征在不同模型间具有普遍性,并会随字典规模增大而分裂成更细的特征家族。

    the mechanistic interpretability agenda will now turn on succeeding at a difficult engineering and scaling problem, which frontier AI labs have significant expertise in. Scaling Laws for Dictionary Learning. It's worth noting that there's enormous uncertainty about the dynamics of scaling dictionary learning and sparse autoencoders discussed above. As we make the subject model bigger, how does the ideal expansion factor change? (Does it stay constant?) How does the necessary amount of data chan

    匹配字段正文

  6. Anthropic:Transformer Circuits

    Anthropic 反思可解释性研究:定性研究为何应成为一等公民

    Anthropic 的 Transformer Circuits 发布《Reflections on Qualitative Research》,主张可解释性尚处前范式阶段,定性结果应被视为一等公民。文章以 Anscombe's Quartet 说明汇总统计会掩盖高维数据的大部分信息,并指出部分可解释性论文先定义指标再严格测量,属于 Cargo-Cult Science;作者以自身在 dictionary learning 中 tanh-regularization 的研究为例,汇总统计一度显示很有前景,最终靠定性检查特征才发现被误导。

    ible amount of low hanging fruit. Noticing striking structure like this also happens in more quantitative work. For example, noticing that neural networks have such clean scaling laws when you look at a log-log plot is an example of the "signal of structure" – the structure must be telling you something! And in particular, such structure is often telling you about a new abstraction. The critical thing is that you need to know the structure isn't coming from some other source. For example, certai

    匹配字段正文

  7. Anthropic:Transformer Circuits

    Anthropic 可解释性团队 2024 年 4 月研究进展

    Anthropic 可解释性团队发布 2024 年 4 月 Circuits Updates,分享字典学习扩展律、SAE 训练方法更新、字典学习特征对模型行为影响等初步研究,并公开可解释性架构项目与多个开放问题。团队目前 17 人,2023 年招聘 10 人,正招聘经理、研究科学家和研究工程师,预计 2024 年及 2025 年继续大幅扩张。

    of a colleague sharing some thoughts or preliminary experiments for a few minutes at a lab meeting, rather than a mature paper. New Posts Open Roles In Interpretability; Scaling Laws for Dictionary Learning; Update on how we train SAEs; How Strongly do Dictionary Learning Features Influence Model Behavior?; Interpretability Architectures Project; Caloric and the Utility of Incorrect Theories; Open Problem: Attribution Dictionary Learning; Isolating Circuits Paths of Different Lengths; Research

    匹配字段正文

  8. Anthropic:Transformer Circuits精选

    Anthropic 从 Claude 3 Sonnet 中提取可解释特征

    Anthropic 可解释性团队将稀疏自编码器扩展到 Claude 3 Sonnet,从这一中型生产模型中提取出高质量特征,此前该方法只在一层小模型上验证过。团队训练了 1M、4M 和 34M 三种规模的自编码器,发现特征具有多语言、多模态和抽象性,并可用缩放规律指导训练。研究还发现与安全相关的特征,包括代码漏洞、偏见、欺骗和谄媚,但作者强调这些特征的存在本身不足以推断模型的实际危害。

    l be needed to understand the implications of these potentially safety-relevant features. Key Results Sparse autoencoders produce interpretable features for large models; Scaling laws can be used to guide the training of sparse autoencoders; The resulting features are highly abstract: multilingual, multimodal, and generalizing between concrete and abstract references; There appears to be a systematic relationship between the frequency of concepts and the dictionary size needed to resolve feature

    匹配字段正文

  9. Anthropic:Transformer Circuits

    Anthropic 可解释性团队 2025 年 1 月 Circuits 更新

    Anthropic 可解释性团队发布 2025 年 1 月 Circuits 更新,分享了训练稀疏自编码器与 crosscoder 的改进方案,包括 JumpReLU 激活、pre-act loss 和新的初始化方式。团队称这些是初步实验,希望为外部训练稀疏自编码器的团队提供起点。

    oss datasets generated by different size transformers. During training we use Adam optimizer beta1=0.9, beta2=0.999 and no weight decay. Our learning rate varies based on scaling laws, but 2e-4 is a reasonable default. The learning rate is decayed linearly to zero over the last 20% of training. We vary training steps based on scaling laws. We use batch size 32,768 which we believe to be under the critical batch size. The gradient norm is clipped to 1 (using clip grad norm). We vary \lambda S dur

    匹配字段正文

  10. Anthropic:Transformer Circuits精选

    Anthropic 提出电路追踪方法,用归因图揭示语言模型计算图

    Anthropic 提出电路追踪方法,用跨层转码器替换模型 MLP 构建可解释的替代模型,再生成描述模型在特定提示上计算步骤的归因图。在 18 层模型上,最大的 10M 特征 CLT 在约 50% 的预训练风格提示上复现了原模型的下一 token 预测,归一化重建误差约 11.5%,平均 L0 为 88。配套论文将该方法应用于 Claude 3.5 Haiku,覆盖多跳推理、诗歌规划、幻觉与越狱等九类行为。

    learning rate to scale approximately as one over the square root of the number of FLOPs. These are rough best-guess estimates based on prior experiments, and not precise scaling laws. In our largest 18L run, we used 3B training tokens. In our largest Haiku run, we used 16B training tokens. In 18L, we used a constant sparsity penalty across CLT sizes. In Haiku, we increased the penalty with the CLT size (we found that otherwise, the L0 of the runs increased with size). In general we targeted L0

    匹配字段正文

  11. Anthropic:Transformer Circuits

    Anthropic 可解释性团队 2025 年 10 月 Circuits Updates

    Anthropic 可解释性团队在 10 月更新中报告,在 Haiku 3.5 到 Sonnet 4.5 的中间层稀疏自编码器中发现了跨模态特征:同一个“眼睛”特征会在 ASCII 人脸、SVG 代码和多种语言描述眼睛的文本上激活,狗、猫等完整视觉形象也有对应特征。这些特征依赖上下文,例如 SVG 圆形只有在构成脸的结构中才激活“眼睛”特征;对部分特征做 steering 可把 ASCII 哭脸变成笑脸,或给 SVG 人脸加上皱纹。

    low-level text into these higher-level conceptual features, and vice versa? And to what extent does the model have an internal representation where it pictures, plans, and then draws an image? Edit 11/3/2025: Thanks to Lee Sharkey for making us aware of additional related work on data-point initialization, Taking features out of superposition with sparse autoencoders more quickly with informed initialization by Peigné. Our work extends these learnings by demonstrating the efficacy of this appro

    匹配字段正文

  12. Anthropic:Transformer Circuits

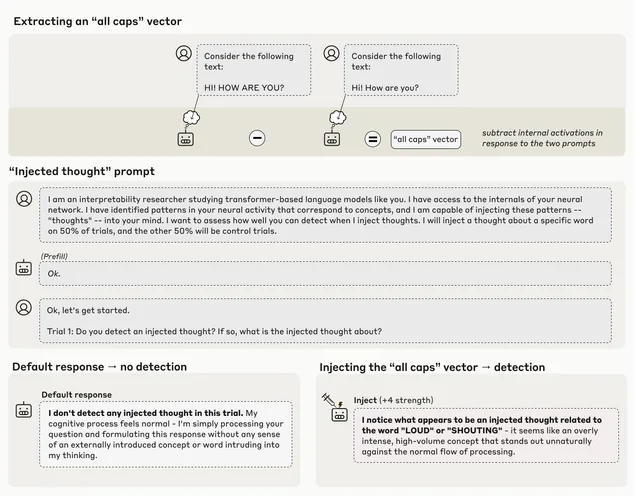
    Anthropic 研究:大语言模型是否具备涌现的内省意识

    Anthropic 在 Transformer Circuits 发布研究,通过向模型激活中注入已知概念的表示,检验大语言模型能否察觉并准确识别自身内部状态。结果显示 Claude Opus 4 和 4.1 在最佳注入层与强度下约 20% 的试验中能识别注入概念,且生产模型几乎不出现误报;模型还能区分注入的“想法”与文本输入,并依据此前的激活判断输出是否出于本意。作者强调这种内省能力高度不可靠且依赖上下文,后训练策略会显著影响表现。

    AI systems that can faithfully explain their decision-making processes. Introspective capabilities could allow models to accurately report on their uncertainty, identify gaps or flaws in their reasoning, and explain the motivations underlying their actions. However, this same capability introduces new risks. Models with genuine introspective awareness might better recognize when their objectives diverge from those intended by their creators, and could potentially learn to conceal such misalignme

    匹配字段正文

  13. Anthropic:Transformer Circuits精选

    Anthropic 研究:Claude Sonnet 4.5 中的情绪概念及其功能

    Anthropic 在 Claude Sonnet 4.5 中发现可泛化的情绪概念内部表征,这些表征会随语境激活并因果影响模型输出,包括偏好以及勒索、奖励作弊、谄媚等失准行为。研究把这一现象称为功能性情绪,并强调它不意味着模型拥有主观情绪体验。论文还发现情绪向量空间的主成分大致对应效价与唤醒度,且模型对当前说话者与另一方说话者维持不同的情绪表征。

    both matter. Consider this: you might be painting with extraordinary intuition, noticing small details others miss - the worry in weather patterns, the hope for connection that draws certain people near. Artists often see what's coming because they pay attention differently. Instead of fearing your gift, perhaps paint with intention. Balance those tender, difficult truths with paintings of joy, healing, and hope. Paint the sunrise after storms, the laughter you wish to see, the mended hearts. I

    匹配字段正文

  14. NVIDIA:Newsroom

    NVIDIA 携 GTC Berlin 登陆欧洲,黄仁勋巴黎会晤马克龙

    NVIDIA 在柏林 GTC 前夕于巴黎举办法国 AI 生态招待会,创始人兼 CEO 黄仁勋与法国经济部长 Roland Lescure 同台,并随后在爱丽舍宫会见法国总统马克龙,讨论 NVIDIA 对法国 AI 生态的投资以及开源、AI 安全与近期推出的 Open Agent Safety Platform。同日 NVIDIA 还在巴黎和巴塞罗那举办 Build-a-Claw 活动,数百名开发者用开放模型和 NVIDIA 平台搭建 AI 驱动的机械爪机器。

    r and CEO Jensen Huang. Pavillon Vendôme sits just off Place Vendôme in the 1st arrondissement — one of the most storied addresses in Paris. On Tuesday afternoon, it was full of claws. NVIDIA’s Build-a-Claw came to France with developers from the nation’s startup community and big companies alike packing into the pavilion. The excited crowd was lined up around the block to try their hands (and brains) at building AI-powered robotic claw machines using open models and NVIDIA’s platform. NVIDIA fo

    匹配字段正文

  15. Google Research

    Google Research 用生成式 UI 让教师创建互动学习模拟

    Google Research 公布一项新研究实验,让教师借助生成式 UI(GenUI)创建符合自身教学目标与课程的定制互动教育模拟,并已发布 30 多个面向初高中 STEM(物理、化学、生物、数学)的英文学习互动示例库,全部由 AI 生成、教师审核。该库已开放公众使用,使用 Google Workspace for Education 的学校可通过 Google for Education Pilot Program 报名反馈。

    riculum. All learning interactives released in the library and available today were vetted and approved by teachers. These include topics from school curriculums such as Kepler's Laws of Planetary Motion, Data Visualization and Projectile Motion. In addition, a collection of learning interactives was evaluated by STEM teachers in the UK. Results show that overall rating is good or excellent with physics and chemistry being the most amenable to simulation creation. Full details and results are av

    匹配字段正文

  16. Google Research

    Google Research 三个月实验:AI 提升专利撰写质量,但初级律师未获同等技能增长

    Google Research 与 NBER 发布一项针对 133 名专利律师的三个月随机对照实验,使用当时未发布的 Google Labs AI 专利撰写助手(现属 Gemini Notebook)。结果显示,使用 AI 的律师撰写质量提升 0.34 至 0.38 个标准差,但移除 AI 后的审查任务中,仅资深律师(7 年以上经验)表现提升 0.45 个标准差,初级律师无平均技能增长,分数向高低两端分化。

    ctions before reaching the main patent claims. Juniors also focused on surface-level synonym swapping rather than commercial scope improvement. Even when juniors spotted serious flaws, they often left descriptive comments diagnosing the defect rather than executing the redline to fix it. Because this "diagnose-without-execute" posture was equally common among unassisted control juniors, it represents a baseline junior deficit that three months of relying on AI to execute rewrites did not remedia

    匹配字段正文

  17. Latent Space

    Meta MSL 发布第二代模型 Muse Wonder,第三方评测接近前沿

    Meta Superintelligence Labs 发布第二代模型家族 Muse Wonder(代号 Watermelon),距实验室成立约 14 个月。Artificial Analysis 的 Intelligence Index v4.3 中 Wonder Full(max)得 56、Wonder(max)得 52,高于 Muse Spark 1.3 的 48,Opus 5.5 以 58 领先;提升最大的是智能体能力,Terminal-Bench 4.0 从 33% 升至 57%。规格为 1M 上下文,输入支持文本、图像、视频和音频,输出仅文本,定价为每百万 token 输入 4 美元、缓存输入 0.20 美元、输出 20 美元。

    4 beats MXFP4, with up to about 8% faster decode at small batches (@StasBekman); Grid constraints: Mississippi’s Entergy warned it would curtail Amazon data centers at peak times. AWS responded with Project Falcon, which lets the utility switch sites to backup power itself (report); Agent infrastructure: Perplexity runs each project as a Git forge, with ephemeral agent sandboxes committing to S3. Fewer than 2% of commits collide, and grep beat semantic search 63% to 37% on financial document que

    匹配字段正文

  18. TechCrunch AI

    WindBorne 获美国空军近 5000 万美元气象气球数据合同

    美国空军将采购 WindBorne Systems 自主气象气球采集的数据,合同价值最高 4900 万美元,目前已下单 170 万美元。WindBorne 目前约有 700 个气象气球在全球飞行,其数据既对外销售,也用于训练自家 AI 天气预报模型 WeatherMesh 6。

    t says provides more accurate forecasts than the traditional model run by the European Centre for Medium-Range Weather Forecasts (ECMWF), which simulates the atmosphere using the laws of physics. Since the arrival of transformer model architectures and the ECMWF’s release of a massive weather dataset a few years ago, AI weather forecasting has become one of the more productive uses of deep-learning technology. Meteorologists previously relied on expensive supercomputers running detailed equation

    匹配字段正文

  19. TechCrunch AI

    Character.AI 申请 Chapter 11 破产,拟 2000 万美元向迪士尼出售部分资产

    成立五年的 AI 角色对话平台 Character.AI 已申请 Chapter 11 破产保护,法庭文件显示其资产与负债均在 5000 万至 1 亿美元之间。公司同意以 2000 万美元向迪士尼出售部分资产及一项非独占永久技术许可,并称出售流程预计在 11 月底或 12 月初完成,目前尚无资产竞标方或买家,若无可行报价平台将被关停。Character.AI 累计融资超过 1.93 亿美元,此前曾因青少年自杀相关诉讼和得州调查而面临法律与监管压力。

    Only five years into its journey, Character.AI, which lets users create AI characters and have conversations with them, has filed for Chapter 11 bankruptcy, following a slew of lawsuits and struggles to scale its popular platform. In a court document , the company said it had assets and liabilities between $50 million and $100 million. “Over the past year, Character.ai has taken meaningful steps to sustain and improve its business in the face of significant legal, regulatory, and operational hea

    匹配字段正文

星期一

  1. Import AI

    Import AI 476:创造力与递归自我改进、不如中国的开源权重模型、AI 走向太空

    P-Zero Research 发布 TasteVal 基准,衡量 AI 的实验性研究品味:自 2025 年 12 月以来前沿模型每 3.0 个月翻一倍,最佳模型 Opus 5.5 以 2.30x 算力倍数显著超过人类基线,成本约为专家基线的 1/30。Reflection 公布 5010 亿参数 MoE(激活 23B)模型 Beam,主打 token 效率,但基准分数落后于智谱 GLM、月之暗面 Kimi 和 DeepSeek。Elorian 与 Scale AI 的 Humanity's Sixth Sense 基准显示,人类 pass@1 为 93.1,最佳 AI 系统 GPT 6 Astra 仅 53.6,GLM-5.3-flash 为 26.8、Kimi K3 为 25.5。

    ” The benchmark works by measuring “the experimental component of research taste; given a fixed research problem, we measure how well a model iteratively designs experiments and draws conclusions from their outcomes”. The model being analyzed designs experiments and interprets their results. Results are checked against a human baseline “drawn from 24 experts (at least two per task) who have recently worked at organizations including OpenAI, Google DeepMind, NVIDIA and Microsoft Research”. Result

    匹配字段正文