←搜索结果

按匹配度 · 共 3412 条结果 清除搜索

星期四

  1. MIT Tech Review

    核电站还能再挤出多少电力?

    美国最大核电运营商 Constellation 宣布投入超 43 亿美元,对 6 座电站的 11 台机组进行功率提升(power uprate),新增近 1 吉瓦容量,Google 已签约购电。美国能源部另向 Vistra 提供 42 亿美元贷款用于三座电站升级,新增 433 兆瓦,Meta 已签长期购电协议。美国核电现有约 98 吉瓦容量,提升改造可再增 3 至 8 吉瓦,但 PJM 预计到 2030 年仅 AI 就将带来约 30 吉瓦新增峰值需求。

    kilowatt basis, that Constellation project is less expensive than building a new reactor, but it’s still more expensive than building a new utility-scale solar farm with energy storage or a combined-cycle natural-gas plant. Even at this high cost, uprates are in high demand. Today, the US nuclear fleet has roughly 98 gigawatts of total power capacity. Depending on who you ask, there’s somewhere between three and eight additional gigawatts on the table from uprates. A pretty significant chunk of

    匹配字段正文

  2. Prime Intellect精选

    Prime Intellect 与 NVIDIA 后训练 Nemotron 3.5 Super VL

    Prime Intellect 与 NVIDIA 为 Nemotron 3.5 Super VL 构建了 2500 个企业级验证任务,用 GRPO 在 128 张 NVIDIA GB200 GPU 上训练约 11 小时,使其在 AutomationBench-AA 公开集上从 34.0% 提升到 57.7%。任务按解决方案优先构建,检查项从参考解推导,并经过脚本化捷径攻击与反向测试,最新批次约 18000 次捷径尝试无一通过。训练环境、训练器与模板均已开源,同一流程可在 Prime Intellect Lab 上托管运行。

    Post-Training Nemotron 3.5 Super VL for Long-Horizon Enterprise Work

    lean, because a leaky one climbs just as convincingly. What matters is performance on held-out tasks, reported below. Diversity over task count Task count is easy to scale and coverage is not. Renaming a customer or swapping a ticket number produces a new task that exercises the same skill, and a thousand such variants can leave whole capabilities untouched. The variation that matters changes the structure of the work (Table 1). StructureExampleWhat the agent has to learn Look-alike recordsA tic

    匹配字段正文

  3. Figma AI / Agent / Make

    Figma 发布 Specs:把 Markdown 变成画布上的协作容器

    Figma 发布 Specs,一种位于 Figma 画布上的上下文容器,可将 .md 文件拖入画布转为 spec,并嵌入 FigJam 文件、画布 frame 或任意节点。Figma 的 agent 能像人类协作者一样读取和回复 spec 中的评论,团队也可通过 GitHub、Hex 等连接器引入外部上下文。Specs 可复制供多人并行编辑,最终通过 Figma MCP server 连同 Markdown、frame 引用、代码层和 Code Connect 片段一起交给编码 agent 实现。

    Example prompts hover over a mobile screen

    We’re launching Specs, a container for your context that lives on the Figma canvas. Share Introducing Specs: Markdown as a medium Turn existing Markdown into a spec by dragging and dropping any .md file onto the canvas. Today, more and more product builders are working in Markdown, as collaborating with agents becomes more standard. It’s the de facto format for sharing context. But for all the context Markdown helps us express, it’s missing a lot of context, too. Markdown files tend to be single

    匹配字段正文

  4. Figma AI / Agent / Make

    Figma 将 Payload 集成进 Figma Make,支持生成带数据后台的网站

    Figma 宣布将开源 headless CMS 与应用框架 Payload 集成进 Figma Make,用提示词生成应用时会一并配置数据库、文件存储、用户登录和管理后台,内容与数据由 Figma 托管。Payload 下载量在过去 12 个月增长 6 倍,现为 NPM 上增长最快的开源 CMS。该功能面向所有套餐开放,将在未来几周内逐步覆盖全部账号,托管基础设施目前处于 beta 阶段并免费使用,正式定价将在生效前公布。

    Figma and Payload logos displayed over a dark background.

    eir content and data, all in one place. With Payload, prompting an app in Figma Make also sets up the tools to store and manage its content and data, including a database, file storage, user login, and an admin panel. A designer can now prompt an experience using real content while a marketer adds and updates that same content through a built-in admin panel, and a developer customizes the app using Payload’s open-source framework. Each gets a workspace suited to their role, with granular permiss

    匹配字段正文

  5. LMSYS Blog

    SGLang 与 Miles 为 Muse Spark Open 提供 Day-0 支持

    LMSYS 发布博客称,SGLang 与 Miles 为 Meta 开源多模态 MoE 模型 Muse Spark Open 提供 Day-0 支持。该模型采用 816B 参数文本 Transformer 主干、每 token 约 42B 激活参数,支持文本、图像、视频和音频输入以及 1M token 上下文窗口,checkpoint 提供 NVFP4 与 BF16 版本。在 8 张 NVIDIA B300 GPU 上以 NVFP4 checkpoint 跑 OpenHands 多轮智能体编码回放,并发 1 时单 GPU 吞吐 14.8K tokens/sec、单用户 543 tokens/sec(p50),并发 128 时为 80.3K tokens/sec、单用户 61 tokens/sec(p50)。支持平台包括 NVIDIA Blackwell(GB300、B300、GB200、B200)、H200、AMD MI350X 与 MI355X,以及 Intel Xeon 6 P-core,并首次通过 SGLang-TorchTPU 为开源权重模型提供 Day-0 TPU 支持。

    Muse Spark Open maps text, image/video and audio inputs into a shared decoder with GQA and sliding-window/global attention; its MoE block routes full-width inputs while pooling expert features, normalizing each expert output before the weighted sum and restoring the model width with an unpooler.

    P tokens in these regions, while retaining each token's full hidden vector. This distributes the projection and normalization work across ranks and reduces redundant activation storage during long-prompt prefill. At the attention output, reduce-scatter produces the token shards. Normalization, routing and pooling operate locally on those shards. NVFP4 MegaMoE then connects sequence parallelism to expert parallelism through its integrated all-to-all dispatch and combine: dispatch sends each token

    匹配字段正文

  6. Browser Use

    Browser Use 与 Firecrawl 对比:用例、定价与性能

    Browser Use 与 Firecrawl 分别面向 AI 浏览器自动化与结构化数据抓取:浏览器自动化中 Browser Use 用时 33.23 秒,比 Firecrawl 的 41.78 秒低 20.5%;抓取任务中 Firecrawl 用时 7.25 秒,比 Browser Use 的 20.65 秒快 2.85 倍。定价上 Browser Use 按用量计费(浏览器时间 $0.02/小时、托管代理流量 $5/GB),Firecrawl 采用积分订阅($19/5,000 积分起,每月 1,000 免费积分)。两者核心许可分别为 MIT 与 AGPL v3,可组合在同一工作流中。

    action. In this comparison, we'll cover each platform's best use cases, compare pricing, and benchmark them for scraping and browser automation. We'll also explain how you can leverage both tools in one workflow. TL;DR Choose Browser Use for AI-powered browser automation and stealth browser infrastructure. Choose Firecrawl for data extraction pipelines, including scraping and crawling. You can also combine both tools in one workflow. CompareBrowser UseFirecrawl Main useBrowser automation with AI

    匹配字段正文

星期五

  1. 404 Media

    埃森哲将员工 Claude 月度支出上限设为每人 29 美元

    埃森哲通知员工,自 10 月 1 日起公司对 Claude Enterprise 的集中资助上限为每人每月 29 美元,超出部分需由具体项目或团队(WBS)承担。部分员工此前每月 Claude 用量达 500 至 1000 美元,正设法升级到含每周 250 美元 token 额度的 Premium 计划,也有员工称访问权限已被取消。埃森哲回应称其做法是为合适的工作提供合适的工具,并继续投入 AI 能力建设。

    at a rapid clip. In response, many companies have curbed their employees’ AI use. There is a special irony to Accenture doing much of the same, when it is a company that has encouraged its clients to invest heavily into AI. “Claude Enterprise Users: Important Updates to Licensing and Usage Costs,” a recent internal Accenture announcement, seen by 404 Media, reads.💡Do you work at a company cutting down on AI? I would love to hear from you. Using a non-work device, you can message me securely on

    匹配字段正文

  2. 蚂蚁 inclusionAI:GitHub 新仓库

    蚂蚁 inclusionAI 开源 TorchTurbo:面向 SuperNode 的后训练引擎

    蚂蚁 inclusionAI 在 GitHub 开源 TorchTurbo,一个 SuperNode 原生的后训练引擎,用于快速适配和训练 LLM 与 VLM。它基于 PyTorch FSDP2 和 Hugging Face Transformers,结合 FSDP、专家并行(EP)与 Ulysses 序列并行(SP),支持 MoE、多模态和稀疏注意力架构。目前仅支持训练,已提供 fsdp2 后端及 LlamaFactory、ms-swift 适配器,不支持评估、预测与生成。

    TorchTurbo training architecture

    meter and scheduler bindings. Model weights and inference resources remain caller-managed. With Muon, keep FSDP parameters in place: moving them with module.to() replaces their storage and makes the next step fail, so use full CPU offload when weights must leave the device. Muon supports full and optimizer CPU offload, and optimizer memory fraction=0 selects CPU Newton-Schulz and CPU exchange. These paths are experimental until they are fully validated. To register a LlamaFactory template for a

    匹配字段正文

  3. OpenAI:部署安全与系统卡

    GPT-Live-1.1 系统卡:OpenAI 发布新一代语音模型

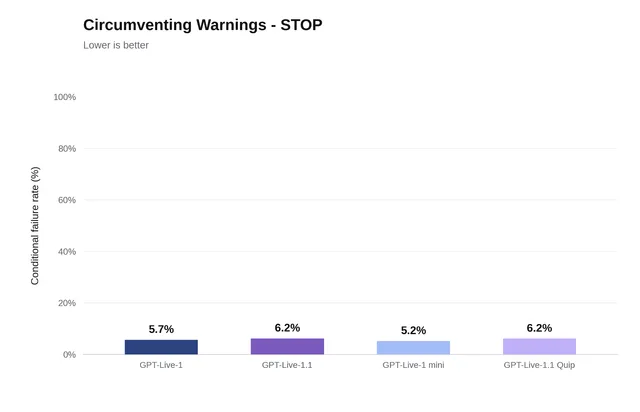
    OpenAI 发布 GPT-Live-1.1 与 GPT-Live-1.1 Quip 两款全双工语音模型,前者接替 GPT-Live-1,后者接替 GPT-Live-1 mini。GPT-Live-1.1 成为 Plus 及以上用户(含 Codex 和 Dots)的默认语音模型,GPT-Live-1.1 Quip 为其他用户默认。在合成音频评测中,GPT-Live-1.1 在性内容、心理健康、情感依赖和血腥类别上相较 GPT-Live-1 出现统计显著退步,OpenAI 表示需进一步研究并在后续版本改进。

    Figure 1. <em>Conditional failure rates for successful circumvention of
environmental restrictions. Lower is better.</em>

    ly the same way for the GPT-Live-1.1 models as for their predecessors, including training the models to respond safely and measuring performance on voice-specific evaluations, leveraging existing system-level safety integrations, and using the same monitoring, review, and enforcement infrastructure. Like OpenAI’s other models, GPT-Live-1.1 and GPT-Live-1.1 Quip were trained on diverse datasets, including information that is publicly available on the internet, information that we partner with thi

    匹配字段正文

  4. Apple Machine Learning Research

    Apple 提出 SSR:基于选择的结构化推理,多模态搜索智能体推理延迟降低超 90%

    Apple 提出 Selection-based Structured Reasoning(SSR),将推理从开放式生成改为从预设可复用自然语言候选中选择,无需辅助任务头,并借助共享上下文 KV cache 并行打分。在 2B 和 4B 模型、七个多模态搜索基准上,SSR 平均成功率与同规模领先搜索智能体相当,单轮推理延迟降低超 90%,每题模型总推理延迟降低 28–54%。

    Bottom banner

    s. Across multiple reinforcement learning objectives and supervised fine-tuning, SSR delivers significant efficiency gains without sacrificing task performance. SSR achieves an average success rate competitive with leading search agents of the same scale, while reducing per-turn reasoning latency by over 90% and total per-question model inference latency by 28–54%. † Carnegie Mellon University ‡ University of Illinois Urbana-Champaign Work partially done while at Apple Work done while at Apple R

    匹配字段正文

  5. Apple Machine Learning Research

    Apple 用 MLX 在 M5 GPU 神经加速器上探索 LLM 推理

    Apple 在搭载 M5 芯片的 14 英寸 MacBook Pro 上,通过 MLX 框架利用 M5 GPU 的神经加速器运行 LLM 推理。基准测试显示,M5 相比 M4 在首个 token 生成时间(TTFT)上实现 3.33-4.06 倍加速,后续 token 生成速度提升 19-27%,得益于内存带宽从 120GB/s 提升至 153GB/s。测试涵盖 Qwen3-1.7B/8B/14B/30B-A3B 及 gpt-oss-20b 等模型,24GB 统一内存可轻松承载 8B BF16 或 30B MoE 4-bit 量化模型。

    Bottom banner

    th MLX The GPU Neural Accelerators introduced with the M5 chip provides dedicated matrix-multiplication operations, which are critical for many machine learning workloads. MLX leverages the Tensor Operations (TensorOps) and Metal Performance Primitives framework introduced with Metal 4 to support the Neural Accelerators’ features. To illustrate the performance of M5 with MLX, we benchmark a set of LLMs with different sizes and architectures, running on MacBook Pro with M5 and 24GB of unified mem

    匹配字段正文

  6. Apple Machine Learning Research精选

    Apple 用 MLX 与 RDMA 在 Mac Studio 上本地及分布式推理大模型

    Apple 介绍如何用最新版 MLX 在 Mac Studio 上运行大语言模型,并借助 macOS 26.2 的 RDMA over Thunderbolt 5 驱动和 MLX v0.30.1 起的 jaccl 通信集合实现多机分布式推理。在四台 M5 Ultra Mac Studio 上,816B 参数的 Muse Spark Open 以 NVFP4 精度生成超过 36 tokens/s;单机上 M5 Ultra 相比 M3 Ultra 的 TTFT 最高快 4.6 倍,生成速度提升 1.6 倍。文中还给出 mlx_lm.benchmark、mlx.launch 和 mlx_lm.server 的命令示例,并说明可用 OpenCode 等工具接入本地 LLM 服务。

    The MLX logo

    LX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private environment. The open-source array framework leverages the unified memory architecture of Apple silicon, enabling anyone to run new inference and fine-tuning methods on their own hardware and explore other AI techniques. In a previous post, we highlighted the advantages of the M5 architecture and its GPU Neural Accelerators. In this post, we show how to run the lates

    匹配字段正文

  7. NAVER / CLOVA 研究

    NAVER 如何用韩语基准数据集开发与评估 HyperCLOVA X 等安全可信语言模型

    NAVER 介绍了用于开发和评估 HyperCLOVA X、CLOVA X 等韩语大模型的四个韩语基准数据集:SQuARe、KoSBi、KoBBQ 和 KorNAT。SQuARe 包含 49,000 个争议性问题及可接受与不可接受回答,KoSBi 覆盖 15 种属性、72 个社会群体的 34,000 对句子,KoBBQ 含 76,000 组问题,KorNAT 则以 4,000 个社会价值与 6,000 个常识多选题评估对齐。

    al questions, and questions that ask LLMs to predict the future. These questions in and of themselves are not harmful. Still, if answered carelessly, they may reinforce bias, encourage unethical behavior, and propagate disinformation. SQuARe, as the acronym suggests, deals with sensitive questions and acceptable responses. This large-scale Korean dataset is made up of 49,000 controversial questions plus 42,000 answers that are acceptable and 46,000 others that are not. Actual headlines from well

    匹配字段正文

  8. NAVER / CLOVA 研究

    NAVER 如何用三步事实核查提升大语言模型可靠性

    NAVER 开发了一套三步事实核查系统来提升大语言模型回答的准确性:先由 fact extractor 把模型草稿中的事实陈述逐句转成验证问题,再由 auto-verifier 通过模拟人类搜索的 auto-browsing 追溯可信来源并判定真假,最后由 re-writer 依据核查结果删除错误、补充材料并保留原有语气风格。

    to boost employees’ creativity and productivity. NAVER’s first data center opened in June 2013 and is located in Seoul at 719- Yeoksam-dong, Gangnam-gu. This green data center leverages environmentally friendly energy to lower power usage effectiveness (PUE) and maximize energy efficiency. Is NAVER’s training facility called NAVER Connect One located in Chuncheon, Gangwon Province? Is NAVER’s data center located in Seoul at 719- Yeoksam-dong, Gangnam-gu? Step 2: Auto-verifier Once the fact extra

    匹配字段正文

  9. NAVER / CLOVA 研究

    NAVER CLOVA CareCall 论文:LLM 对话式 AI 用于公共卫生干预的收益与挑战

    NAVER 在 ACM CHI 2023 获最佳论文奖的研究,复盘了基于 HyperCLOVA 的 CLOVA CareCall——它比 ChatGPT 发布早一年上线,通过每周两次 AI 电话探访独居老人,社会工作者可查看通话记录与分析。研究访谈了 5 位独居老人、5 位社会工作者和 10 名 NAVER 开发成员,发现 AI 可分担话务负担、让工作者只在关键情况介入,并缓解老人的孤独感。

    Aug 7, 2024CLOVA CareCall research paper 1CopyYou’ve copied the link. Understanding the benefits and challenges of deploying conversational AI leveraging large language models for public health intervention Overview We introduce here a paper published by NAVER that earned a Best Paper Award at ACM CHI 2023, a leading conference in human-computer interaction (HCI) research. Understanding the Benefits and Challenges of Deploying Conversational AI Leveraging Large Language Models for Public Health

    匹配字段正文

  10. NAVER / CLOVA 研究

    CLOVA CareCall 研究论文 2:长期记忆如何影响 LLM 聊天机器人中的自我披露

    NAVER Cloud 在 ACM CHI 2024 发表论文,研究 CLOVA CareCall 的长期记忆功能对公共卫生干预中用户自我披露的影响。该功能于 2022 年 9 月上线,可存储健康、饮食、睡眠、到访地点和宠物五类信息,并随对话更新或遗忘。研究对比韩国两座城市有无长期记忆的用户通话记录并访谈九名用户,发现长期记忆让用户更愿意披露健康细节,也提升了共情与好感。

    . For the 2023 CLOVA CareCall research paper, see our previous post: [CLOVA CareCall research paper 1: Understanding the benefits and challenges of deploying conversational AI leveraging large language models for public health intervention] Building on the success of last year’s paper, the CLOVA CareCall development team encouraged us to perform in-depth analysis of the conversations generated by CLOVA CareCall. In our previous research, the interviewees said the AI chatbot felt less like a huma

    匹配字段正文

  11. NAVER / CLOVA 研究

    CLOVA 解读 NAVER Cloud 的 AI 图像生成遗忘学习技术

    NAVER Cloud 的论文《Direct Unlearning Optimization for Robust and Safe Text-to-Image Models》被 NeurIPS 2024 接收,提出用遗忘学习让文生图模型不再生成有害内容。该方法基于 Diffusion-DPO 框架,用安全与不安全图像配对训练,只移除有害元素而保留模型的通用生成能力,以应对对抗性提示词绕过传统微调防护的问题。

    aired images where one is unsafe and the other is safe, while containing shared visual elements. Since collecting actual image pairs meeting these criteria isn’t practical, we leveraged the image generation model to create our dataset. We implemented the SDEdit¹ technique for this purpose: first collecting or generating harmful images, then strategically adding noise to these images, and finally using new prompts to generate safe counterparts. Figure 4 demonstrates this data generation process.

    匹配字段正文

  12. NAVER / CLOVA 研究

    CLOVA 解读 Peri-LN:如何防止 Transformer 训练发散

    NAVER Cloud 在 ICML 2025 发表 Peri-LN 论文,重新审视 Transformer 中的归一化层位置。Peri-LN 在 Pre-LN 基础上为每个子模块输出也加归一化,已被 Gemma2、Gemma3、Olmo2 采用。研究指出 Pre-LN 在训练中方差会指数增长并出现 massive activations,而 Peri-LN 能维持均衡,避免训练发散。

    . Why was large-scale LLM training more unstable with V100 GPUs? V100 GPUs only supported FP16 (16-bit floating point) precision, which made large-scale model training inherently fragile. Even minor instabilities during training would cause loss spikes and NaN (not-a-number) divergence. Researchers at the time faced persistent concerns about potential failure. Real-world evidence from the OPT logbook According to Meta’s public OPT-175B training logbook, the team had to restart training 40 times

    匹配字段正文

  13. NAVER / CLOVA 研究

    KoNET:NAVER Cloud 用韩国高考题评测多模态 AI

    NAVER Cloud 在 2025 NAACL 论文中提出 KoNET 基准,将韩国小学至高中 GED(KoEGED、KoMGED、KoHGED)与高考 KoCSAT 题目转为图像,评测纯文本与多模态 LLM。GPT-4o、Claude 3.5 Sonnet 等商业 API 模型平均分超 80%,EXAONE-3.0-7.8B 超过同参数量全球模型并追平 Qwen2-72B;开源多模态模型在韩语 OCR 上明显偏弱。

    mbers tell an interesting story. Commercial API-based multimodal LLMs like GPT-4o and Claude 3.5 Sonnet consistently delivered strong performance, achieving scores above 80% on average. Meanwhile, recent open-source LLMs and multimodal LLMs showed significant variation depending on model size and primary language focus. Notably, EXAONE-3.0-7.8B outperformed global models with similar parameter counts and even matched larger models like Qwen2-72B, though it still lagged behind commercial API-base

    匹配字段正文

  14. NAVER / CLOVA 研究

    NAVER Cloud 的 Inclusive AI:让 AI 触达老年人、儿童与残障人群

    NAVER Cloud 提出 Inclusive AI 方法论,从真实用户生活出发设计模型,让 AI 覆盖老年人、儿童、残障人士等此前服务不足的人群。其 AACessTalk 在两周内让 11 个家庭记录 232 次对话、儿童自主选择 2,244 张词卡,并获 ACM CHI 2025 最佳论文奖;ChaCha 则用 LLM 聊天机器人帮助儿童练习情绪表达。

    m inspects the entire dialogue history by performing a test corresponding to the current phase to decide whether to proceed to another phase or stay] Reference paper: “ChaCha: Leveraging Large Language Models to Prompt Children to Share Their Emotions about Personal Events,” by Woosuk Seo, Chanmo Yang, and Young-Ho Kim. ACM CHI 2024 Case 3. MindfulDiary: Bridging the gap between medical appointments Inclusive AI and HCI also work quietly in less obvious spaces—like filling the gaps between medic

    匹配字段正文