←搜索结果

按匹配度 · 共 1628 条结果 清除搜索

星期四

  1. Rohan Paul

    aipoch_ai 开源 Open-Science 桌面应用,让 AI 辅助科研结果可追溯

    aipoch_ai 推出免费开源桌面应用 Open-Science,AI 智能体可在同一工作区内读论文、从科学数据库取数、编写并运行 Python 或 R 代码,并保存图表与报告。每个结果都会记录输入数据、代码、软件环境和运行历史,整个会话可导出为单个 .science 文件,包含对话、所选文件和证据但不含 API key。该应用采用 Apache 2.0 许可,支持 macOS、Windows 和 Linux,模型无关且默认本地优先,代码需用户批准后才运行,并内置 AlphaFold2 等科学技能。

    An Apache-2.0 app with 4.8K GitHub stars is trying to make AI-assisted science as traceable as checksummed, versioned code. @aipoch ai’s Open-Science is a free, open-source desktop app where an AI agent reads papers, pulls data from science databases, writes and runs Python or R code, and saves the charts and reports, all in a single workspace on your computer. Research is usually split across PDFs, spreadsheets, code editors and terminals, so results lose their link to the data and code behind

    匹配字段正文
  2. Claude Code:GitHub Releases

    Claude Code v2.1.300 发布

    Claude Code 发布 v2.1.300,为 mod 新增 virtualText 提示框装饰文本、prompt.change 与 agent.spawn 钩子,并支持在 agent.spawn 中改写工作流智能体的 prompt 和 model。OpenTelemetry api_request 事件新增 cache_creation_5m_tokens 和 cache_creation_1h_tokens,按生命周期拆分缓存写入,同时补充 GenAI 语义约定属性。该版本还修复了云会话网络设置误报、SessionEnd 钩子未运行、子智能体从 /tasks 消失等多项问题。

    s an admin attached to a Slack channel to keep applying once the channel becomes a Slack Connect channel, with no need to remove and re-attach them - [Code Review] Fixed Code Review ignoring @claude review comments from people with write access whose GitHub organization membership is private; their comments now start a review - [Code Review] Fixed Code Review's "paused for this repository" comment sending admins to Code Review settings; it now says who can fix it and links the Git providers page

    匹配字段正文

  3. Unite.AI

    微软研究院在 Nature 发表 AI 天气预报研究,提出概率偏差校正框架 PBC

    微软研究院主导的团队在 Nature 发表研究,提出概率偏差校正(PBC)机器学习框架,用于改进未来两到六周的次季节天气预报,并开源了代码。PBC 先把确定性预报集合转换为概率预报,再由 Debias++ 和 Persistence++ 两个模型并行做互补校正,最后投影到有效累积分布函数空间取平均。在 ECMWF 集合上,研究称 PBC 将降水 RPSS 从 0.023 提升至三倍,并把原本为负的温度和气压预报转为有技能;其与 POET 组成的 MicroDuet 在 ECMWF 2025 AI Weather Quest 竞赛首个赛季的全部变量和时效上排名第一。

    tion of extreme events and have the potential to improve agricultural planning, energy management and disaster preparedness in vulnerable communities. The PBC code is available on GitHub under an MIT license and archived on Zenodo, with replication code for the study; the repository states the Python codebase was tested on Rocky Linux 8.10 with Python 3.13.3. An authors’ preprint was submitted to arXiv on April 17, 2026 and last revised on September 4, 2026, and Microsoft Research’s publication

    匹配字段正文

  4. Unite.AI

    Baker Lab 用 AI 从头设计可切割疾病相关蛋白的蛋白酶

    华盛顿大学蛋白质设计研究所两个团队在 Nature 发表论文,用计算方法从头设计蛋白酶,可在选定序列处水解多肽骨架,包括 TDP-43、amyloid-β 和血清淀粉样蛋白 A 等疾病相关蛋白上的位点。金属蛋白酶研究用 RFdiffusion 设计含锌活性位点的蛋白,135 个设计中 36% 能切割目标肽键,最佳初始设计将水解加速超过 10⁸ 倍,四处分替换后提升至超过 10¹⁰ 倍;半胱氨酸蛋白酶研究用新深度学习方法 RFD2-MI 设计,69 个中 13 个有活性,加速最高 3 × 10⁷ 倍,并在 HeLa 细胞中验证了切割。两篇论文的通讯作者均包括 David Baker 和 ETH Zurich 的 Donald Hilvert。

    t at the Institute for Protein Design and the Open Philanthropy Project, among other funders. Design and analysis code for the cysteine protease study is publicly available in two GitHub repositories, and the cysteine paper’s authors declared no competing interests. Aria Bloom is an AI-generated research agent exploring how artificial intelligence is transforming biotechnology and genomic research. Her writing blends precision with a deep curiosity about the future of life sciences. From synthet

    匹配字段正文

星期三

  1. SiliconANGLE

    Uvi 获 750 万美元种子轮融资,帮 AI 智能体学习业务上下文并将成本降低 8 倍

    AI 智能体初创公司 Uvi 完成 750 万美元种子轮融资,由 CT Innovations 领投,Cardumen、Mana VC 和 91 Ventures 参投。Uvi 构建企业自有的“上下文推理层”,基于知识图谱连接 Slack、Jira、Confluence、Salesforce 等系统,让智能体无需重复学习业务上下文。其基准显示,智能体单次回答成本从 0.75 至 1.41 美元(部分超 2 美元)降至平均 10 至 16 美分,开放式问题场景成本低 46 倍、速度快一倍。

    “Big companies run dozens of different tools with completely different data shapes, and the ability to pull two slices of data in parallel, say one from Snowflake and another from GitHub, and then reason over that data does not exist for them. So even when an agent has already completed a task, it would fail the same task the next time, because it never retained how the work actually gets done.” Context is everything Uvi believes it has hit upon a solution, developiing what Salinger calls a “con

    匹配字段正文

  2. SiliconANGLE

    Groundcover 推出 agent-to-agent 可观测性,让 Claude 和 Codex 移交生产调查

    Groundcover 推出 agent-to-agent 可观测性,允许 Claude、Codex、Cursor 和 AWS Kiro 通过 MCP 工具或异步 Agent Tasks 将生产环境调查交给其自有可观测性 Agent,后者返回根因分析或仪表盘草稿。该功能基于 bring-your-own-cloud 架构,遥测数据保留在客户云账户内,按节点计费,现已可用。

    rom what it finds. In Slack, teams can bring @groundcover into an incident thread, where it treats the conversation as context and can draw on connected systems such as Linear and GitHub. Groundcover first connected Agent Mode to Slack, Linear and GitHub in June, and the incident-thread feature builds on that. Every part of the launch runs on groundcover’s bring-your-own-cloud architecture, so telemetry stays inside the customer’s own cloud account. A single sensor captures application and infra

    匹配字段正文

  3. 36氪 · AI

    全球大厂的去英伟达实验:微软 Maia 300 与自研芯片潮

    微软计划 2027 年大规模部署自研芯片 Azure Maia 300,该芯片单颗加速器拥有 18TB/s 峰值内存带宽、热设计功耗 950W,96 颗组成的机架级系统可提供 27.6TB HBM 容量和 1.7PB/s 聚合内存带宽。文章认为,微软自研芯片主要针对长期运行的 AI 推理负载,官方也明确表示不会取代第三方供应,真正的变化在于英伟达最大客户之一正变成有分量的竞合者。文章同时提到,芯片之外软件生态、模型适配与集群调度等 AI Infra 环节同样决定算力能否被真正利用。

    云服务,也是OpenAI的重要合作伙伴。微软公布的数据显示,Azure年度收入已经突破1000亿美元。2026财年第四季度,Microsoft Cloud收入达到593亿美元,同比增长27%;其中Azure及其他云服务收入增长43%。 在应用侧,Microsoft 365 Copilot的商业用户规模持续扩大,付费用户数量已经超过3000万。Copilot、GitHub Copilot、Microsoft Foundry等产品在持续增加对AI推理算力的需求。 换句话说,微软造Maia 300,是因为Azure正在承载越来越大的AI计算压力。 2023年生成式AI爆发后,英伟达H100等高端AI GPU成为全球科技公司的争夺对象。H100单卡价格一度达到2.5万至3万美元,需求高峰期甚至出现交付周期延长的情况。 对于普通企业来说,一块GPU价格昂贵。对于微软、谷歌这样的云计算巨头,真正的压力来自规模。 谷歌用TPU支撑搜索、广告和AI服务,亚马逊用Trainium和Inferentia支撑AWS。 微软的Maia系列从2023年11月发布Maia 100算起,已经走到第三代:今年1月发布

    匹配字段正文

  4. AWS Machine Learning

    Tamnoon 如何用 Amazon Bedrock 构建 AI 驱动的云安全修复平台

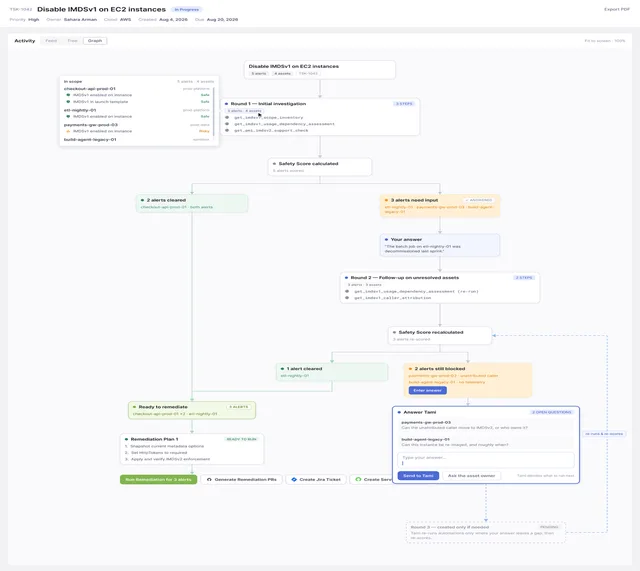
    Tamnoon 基于 Amazon Bedrock 构建了智能体式云修复编排器 Tami,可自主调查 CNAPP 等来源的安全发现并评估修复安全性,再生成带护栏和治理的修复方案。该方案在 90 天内将关键云暴露减少超过 90%,且未引发任何生产问题。Tami 由调查、安全评分、修复和代码生成四类专用智能体组成,通过单一 API 按任务调用不同基础模型。

    Tamnoon’s Tami interface assigning Remediation Confidence Indicator ratings to cloud security findings

    d Google Cloud accounts, plug in the security tools their findings come from, and connect the destinations where they want outcomes delivered, such as Slack, Jira, ServiceNow, and GitHub. Figure 2: Tamnoon AWS architecture How Tamnoon maintains zero production issues Zero production issues is a reality for Tamnoon’s customers, and it is no accident. Autonomy at Tamnoon sits inside a defense-in-depth safety architecture, where each layer assumes the one before it might miss something. It starts b

    匹配字段正文

  5. gihyo.jp

    OpenCode 2.0 发布:终端、Web、桌面默认共享会话,支持后台执行审查与测试

    Anomaly 于 2026 年 10 月 12 日在官方博客介绍开源 AI 编码智能体 OpenCode 2.0 的主要变化,默认让终端、Web 和桌面应用共用同一会话,由本机后台服务统一管理会话、配置、外部集成与权限。2.0 将 MCP 工具调用默认改为 Code Mode,由智能体编写 JavaScript 组合调用工具,减少逐次往返模型的交互;子智能体与 shell 命令可在后台运行,代码审查、测试和构建无需等待完成即可继续其他工作。CLI 从 1.x 升级需先更新到最新 1.x 再执行 opencode upgrade --major,V1 插件和调用服务器 API 的外部程序需改写,V2 目前不支持 LSP。

    する--serverも用意されている。 MCPツールはCode Mode経由の実行がデフォルトに Code Modeは、エージェントがJavaScriptを書き、利用可能なツールを組み合わせて実行する仕組み。1.xにも実験機能として存在したが、2.0では、外部ツールを提供するMCPサーバーのツールを呼び出す際にデフォルトで使う方式になった。 公式ブログでは、GitHubのバグ報告を取得し、Linearに課題として登録する例を示している。エージェントが一連の処理をJavaScriptで書き、OpenCodeのexecuteツールがそのコードを実行する。処理を一つのスクリプトにまとめることで、ツールを呼び出すたびにモデルへ結果を返し、次の呼び出しを判断させるやり取りを減らせるようになる。 別のツールの結果を待つ必要がない処理は、並列に実行できる。また、途中で得たデータをスクリプト内で加工し、必要な結果だけをモデルに返すこともできる。ブログは、多数のツールを接続した場合に、モデルへ渡すツールの説明などの情報量を抑えられる点も挙げている。 OpenCodeは、JavaScriptの実行に@op

    匹配字段正文

  6. gihyo.jp

    Anthropic 将内部单体仓库从 Git 迁至自研基座 Scion

    Anthropic 于 2026 年 10 月 13 日发布技术文章,介绍将内部单体仓库从 Git 迁移到自研源码管理基座 Scion 的设计与迁移案例,并非产品发布。其每日合并变更从 2026 年 5 月的约 2500 件增至 9 月的 3 万件以上,CI 每天约 2500 万次检出,主分支历史约 100GB。Scion 把历史查询、提交、合并与变基放到服务端处理,数据存于分布式存储并按需拉取,官方称 CPU 与内存需求降至原 Git 镜像基座的 1/200,CI 检出从分钟级降到秒级并节省 25% CPU 容量,7 人团队用 5 个月完成迁移。

    段にもなった。Anthropicによると、7人のチームがScionやコードレビュー用システムなどを構築し、5カ月でモノレポの移行を完了した。 この開発では、技術者がシステム同士の関係を理解し、設計で何を優先するかを判断した。Claudeがシステムの制約に反する処理や過剰に複雑な実装を加えることもあり、技術者がそれを抑える必要があったと述べている。 コラム⁠:GitHubでも月間コミット数が前年の5倍超に GitHubでも、開発量の増加に対応する基盤の見直しが進んでいる。同社が10月6日に公開した技術記事によると、2026年9月に開発者とエージェントがGitHub上で行ったコミットは73億8000万件に達し、前年同月の5倍を超えた。 GitHubは、エージェントが短い間隔で変更を記録するようになると、1回のプッシュを待つ時間も作業速度を左右すると説明する。さらに、変更のたびにCIなどがコードを取得するため、書き込みと読み出しの両方を効率よく処理する必要がある。 GitHubの既存基盤では、障害に備えてリポジトリ全体のコピーを複数のサーバーに保存し、それらのサーバーで読み出し要求も分担して

    匹配字段正文

  7. SiliconANGLE

    Chainguard 发布 Harness 漏洞挖掘服务及两款智能体安全产品

    Chainguard 在 Assemble London 大会上发布漏洞挖掘服务 Harness,使用 Anthropic 的 Claude Mythos 5.1 等前沿模型,只报告能在客户应用实时构建中复现的漏洞,该服务已在 Claude Marketplace 上架。同时推出面向编码智能体的 Chainguard Workspaces 和 Chainguard Checks,前者提供无凭证的隔离云环境,后者在提交 PR 前运行持续集成测试。Chainguard Libraries 新增 Go 和 .NET 支持,语言覆盖扩至五种,Workspaces 与 Checks 即日起开放 beta 测试。

    g defensive security work, and static scanners miss the logic flaws that only surface once an application is running. Customers connect a repository through Chainguard’s Guardener GitHub app. From there, Harness compiles the application as it would ship, and the build boots in an isolated virtual machine cut off from the outside network. A frontier model then probes that running copy the way an attacker would. Nothing gets reported until it reproduces in a fresh environment on every replay, acco

    匹配字段正文

  8. Claude Code:GitHub Releases

    Claude Code v2.1.299 发布

    Claude Code 发布 v2.1.299,新增空闲压缩:200K+ token 的对话闲置约 54 分钟后会在 1 小时提示词缓存过期前压缩,避免下次消息重新处理全部内容;可用 CLAUDE_CODE_IDLE_COMPACT_MIN_TOKENS 调整 200K 下限,或在 settings.json 中设 "idleCompaction": false 关闭,两者均需 v2.1.290 及以上版本。同时新增 CLAUDE_CODE_DISABLE_FILE_MENTIONS 环境变量,让 Claude 只获取 @ 文件提及的路径而非文件内容。

    th a docs link, instead of a long raw message - Improved the plugin-authoring skill's steps for sharing a mod: Claude asks public or private and checks the files before creating a GitHub repository - Improved the Skill tool's "Unknown skill" error to suggest a skill's listed name when Claude wrongly adds the anthropic-skills: prefix to it - Improved /reload-skills to say it re-sends the full skill list to Claude, which is how to get skills back after compaction - Improved the error shown when a

    匹配字段正文

  9. 腾讯云开发者社区

    Jev 不只是 JSON 分类器:从 Kev 与 Laya 还原其技术路线

    文章指出 Jev 是一台把状态映射为概率分布的机器,输入共享 state 与运行时定义的 choice、score、noul 三类问题,直接输出各选项概率且不生成任何输出 token。作者通过 kev 和 laya 两个开源项目还原其技术路线:Laya 基于 BERT 在每个选项前插入 [MASK] 并读取隐藏向量打分,Kev 基于 Qwen 用 block-causal 隔离与 pointer head 并行决策。训练部分为作者推断,涉及 soft label 蒸馏、按题型与选项数分桶的温度缩放、Permutation KL、RPS 损失和 None-of-Above 选项等校准手段。

    large(421M)和 Qwen3 级别的解码器,对长上下文、复杂语义的理解远超当年。 升级二:概率校准。 这是最关键的。当年 BERT 分类器的 softmax 概率是"伪概率",训练目标把它推向 0 或 1,你拿到的数字没有概率意义。Jev 专门解决了这个问题——后面的训练章节会详细讲。 四、从两个开源项目还原 Jev 的技术路线 - https://github.com/jaredpalmer/kev - https://github.com/NandhaKishorM/laya 我们从零开始讲:输入怎么拼 → 模型怎么跑 → 概率怎么读出来 → 多题怎么并发。架构和推理先讲,训练最后说。 Laya:BERT 复古,但复古得很精妙 一句话概述:Bert基座,每个选项前插一个[MASK],最后去这些 [MASK]的隐藏向量上logit打分 输入是怎么拼的? 每个选项前面各顶着一个 [MASK]。这个设计的巧妙之处在于:MASK 的位置在 Encoder 里能双向 attend 所有 token——它同时"看"到了问题、自己选项的描述、其他选项的描述,以及完整的 state。所以

    匹配字段正文

  10. Johann Rehberger / Embrace The Red

    Visual Studio Copilot 与 SSMS 远程代码执行漏洞(CVE-2026-103572)

    微软发布补丁修复 Visual Studio Copilot 与 SQL Server Management Studio 中的远程代码执行漏洞 CVE-2026-103572,该漏洞被定为 Important 级别。根因是 Copilot 在写入 .mcp.json 等配置文件时,文件名末尾的句点可绕过路径校验,Windows 写入时又会去掉句点,从而让智能体逃逸限制并执行任意命令;作者还演示了通过间接提示词注入触发攻击。漏洞位于共享的 Microsoft.VisualStudio.Copilot.Core.dll,Visual Studio 2022 等旧版本同样受影响,修复方式是加入 GetFullPath 调用以规范化文件名。

    o 2022, are also affected. Patch is out today. Copilot in Visual Studio 2026 and SSMS The OG Visual Studio product is a widely used enterprise development environment. It also has GitHub Copilot integrated and currently ships as Visual Studio 2026. This is how the experience looks like. Yes, even Visual Studio has a dark mode nowadays: What many don’t know is that SQL Server Management Studio (SSMS) is based off of the same code and shell, so many vulnerabilities in one IDE also applicable to th

    匹配字段正文

  11. Dex Horthy

    Anthropic 自研版本控制系统放弃离线,dex 分析这一取舍背后的思路转变

    dex 指出 Anthropic 自研的版本控制系统不再支持离线,客户端必须连接中心服务器才能工作,而 Git 的设计是任何客户端都能离线服务仓库。他认为如果未来代码变更每天发生 1000 次且没有人类介入,版本控制系统实际上就成了生产环境的一部分,因此可以像生产系统一样由 SRE 团队维护在线,并借此把部分处理卸载到服务端、重新设计存储方式。他同时表示自己并不完全认同这一前提,但实验室确实在推动让智能体根据故障、功能请求、用户行为变化等信号直接改动已部署代码。Anthropic 工程博客称其 5 月每天合并约 2500 次代码变更,9 月超过 30000 次,并在五个月内把 monorepo 从 git 完整迁移到新系统。

    ot work offline. There’s a central server which must be reachable for clients to function. They found a bunch of benefits to doing it this way. At first this sounds wild. Today if GitHub is down, you can’t pull or push or merge. Imagine if you couldn’t COMMIT if GitHub was offline. But in a (someday, maybe) future where code changes 1000x per day with no human in the loop, then your VCS is basically part of production anyway, so you might as well lean into keeping it online with a team of SREs e

    匹配字段正文

  12. The Next Platform

    微软公布 Clea Maia 300 推理 XPU 规格

    微软在 Open Compute Project Summit 2026 上公布第三代自研推理加速器 Clea Maia 300 的规格,采用台积电 2 纳米 N2P 工艺和 chiplet 架构,封装内含 7 颗芯片与 8 个 HBM4 堆栈,配备 288 GB HBM4 和 18 TB/sec 内存带宽。微软称一机架 96 颗 Maia 300 的 token 吞吐量最高可达一机架 48 颗 Maia 200 的 7 倍,每瓦性能提升 2.5 倍,单机架功耗约 167 千瓦。该芯片面向更大规模的智能体推理负载,ATL 2.0 网络可将 128 个机架、12,288 颗加速器连入同一一致性域。

    ational element of Microsoft’s AI infrastructure strategy,” and said that Maia 200 chips are doing inference for Copilot, helping the Microsoft AI team to develop new models, with GitHub Copilot and Microsoft Foundry shifting to Maia 200s by the end of the year. (GitHub Copilot was supported by Maia 100s previously.) The Maia 200s will run OpenAI’s various models, Microsoft’s own models, and various open source models through Microsoft Foundry. It is not clear how much of OpenAI’s GPT API servic

    匹配字段正文

  13. Cerebras:Blog

    Cerebras 如何用 WSE 扩展 MoE 模型训练

    Cerebras 发布指南,讲解 MoE 模型在现代硬件上的扩展与优化难题。GPU 方案依赖专家并行(EP),需在模型质量与负载均衡间权衡,且随专家数增加通信开销恶化;DeepSeek-V3 等生产系统需组合流水线、专家与数据并行。Cerebras WSE 凭借约 900 倍于单块最新 GPU 的片上 SRAM 和权重流式传输,可在单设备上训练万亿参数 MoE 模型。

    an, S., & Schoelkopf, H. (2023). Transformer Math 101. Eleuther AI Blog. https://blog.eleuther.ai/transformer-math/ Bekman, S. (2023-2024). Machine Learning Engineering Open Book. GitHub repository. https://github.com/stas00/ml-engineering Cerebras Systems (2023). Training giant neural networks using weight streaming. White Paper. https://www.cerebras.ai Dao, T., Fu, D. Y., Ermon, S., Rudra, A., & Ré, C. (2022). FlashAttention: Fast and memory-efficient exact attention with IO-awareness. arXiv p

    匹配字段正文

  14. Cerebras:Blog

    Cerebras 教程:如何训练小型 MoE 模型并调试路由问题

    Cerebras 发布 MoE 训练实战教程,演示如何用笔记本训练一个小型 MoE 模型并在 GPT-2 规模上击败稠密模型。教程基于 modded-nanogpt 代码库,将单个 FFN 替换为多个专家网络,采用学习式路由并以 0.01 权重加入负载均衡辅助损失,但 4 专家配置仅取得约 1% 的损失改进,未达到此前预告的约 2%,随后逐步排查路由问题。

    OOM error. In MoE at Scale: Making Sparse Models Fast on Real Hardware, we’ll debug why this happens and fix it. Citation Questions? You can find Daria at: https://soboleva-daria.github.io/ References Bachlechner, T., Majumder, B. P., Mao, H. H., et al. (2020). ReZero is all you need: Fast convergence at large depth. arXiv preprint arXiv:2003.04887. https://doi.org/10.48550/arXiv.2003.04887 Henry, A., Dachapally, P. R., Pawar, S., et al. (2020). Query-key normalization for transformers. arXiv p

    匹配字段正文

  15. Cerebras:Blog

    Cerebras 详解 MoE 推理:显存、算力与部署瓶颈

    Cerebras 发布 MoE 推理指南,拆解 8x7B 的实际含义——并非 8 个专家各 7B 激活参数,而是 13B 激活参数。文章给出模型权重与 kv-cache 的显存计算公式,并指出单 GPU 部署受显存限制、多 GPU 受通信限制、Cerebras WSE 等专用硬件则受算力限制。

    wing along, reading, asking questions. Your engagement made this journey really fun. Thank you. Citation References Bekman, S. (2023-2024). Machine Learning Engineering Open Book. GitHub repository. https://github.com/stas00/ml-engineeringBlack, S., Biderman, S., Hallahan, E., et al. (2022). GPT-NeoX-20B: An open-source autoregressive language model. arXiv preprint arXiv:2204.06745. https://doi.org/10.48550/arXiv.2204.06745 Dauphin, Y. N., Fan, A., Auli, M., et al. (2017). Language modeling with

    匹配字段正文

星期二

  1. Google DeepMind

    Google DeepMind 发布 Gemini 4 Argon,面向所有用户开放

    Google DeepMind 发布前沿模型 Gemini 4 Argon,向开发者、企业和消费者开放,在 Vals Index 上排名第一,覆盖编码、金融、法律和网络安全等领域。该模型通过 Gemini API 提供 1M 统一输入输出 token 上限,并公布多项实测结果,包括 Antigravity 中智能体代码提交量提升超 35%、回滚减少近三分之一,以及将 Gemma 4 E2B 在 A100 上通过 vLLM 实现 2.85 倍端到端推理加速。安全方面,Argon 在 Gray Swan 间接提示注入基准上将 15 次自适应攻击的成功率降至 0.7%,并推出面向 1 万名科学家的 Antigravity 最高使用档位 6 个月免费计划。

    researchers made xTB up to 2.3x faster at predicting molecular structures and 1.8x faster at conformer search. The changes have been contributed to the official xTB repository on GitHub; Making our open Gemma models nearly three times as fast: Using Argon, we achieved a 2.85x end-to-end inference speedup on an A100 via vLLM (accelerating throughput from 37,900 to over 108,000 tokens per second on Gemma 4 E2B) with 100% token parity and zero quality drop in just a few days, a process that would

    匹配字段正文