←搜索结果

按匹配度 · 共 3412 条结果 清除搜索

星期三

  1. Databricks Blog

    Lakeflow Designer 十月更新:新增数据清洗与质量算子

    Databricks 为 Lakeflow Designer 新增 Prepare、Unique、Guardrails 三个无代码算子,分别用于数据清洗标准化、去重和数据质量检查,并增强 Join、Filter、Select 算子。输出侧新增物化视图、表合并与 CSV/Excel/JSON 文件导出,画布加入可视化版本历史和可搜索目录。该产品 6 月 GA,已有超 3000 家客户使用,采用按用量计费、无按用户授权费,部分客户将无代码工具支出降低 90%。
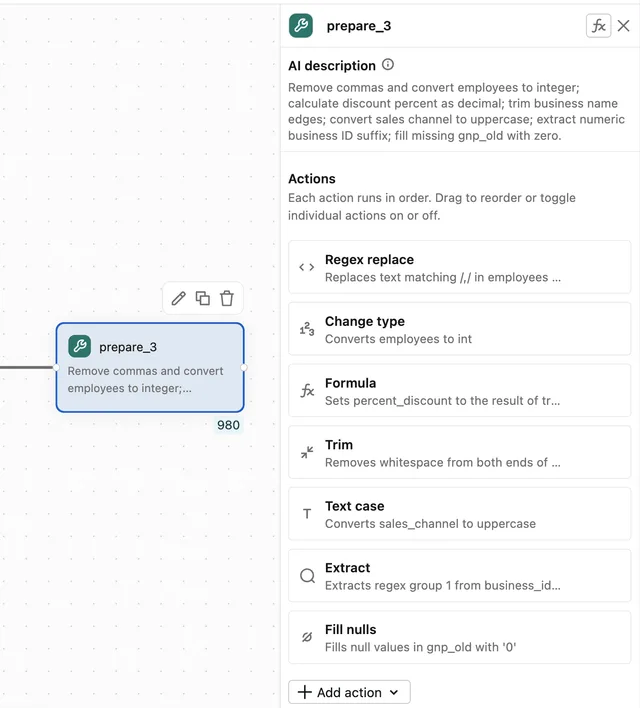
    image15.png

    is a visual, no-code, AI-native experience for data preparation and analytics. It lets analysts, domain experts, and other less technical users prepare and explore data through a drag-and-drop canvas and natural language. What’s New? Here are some of our favorite enhancements we've made to Lakeflow Designer over the last 4 months. New no-code operators for data cleaning and quality checks Genie Code, Python, and SQL operators have always made Designer flexible. However, we heard from early custo

    匹配字段正文

  2. Databricks Blog

    Databricks 2026 实时分析实践指南:用湖仓一体替代专用服务层

    Databricks 发布 2026 实时分析实践指南,提出用新鲜度、延迟、并发三个维度评估实时分析工作负载,判断哪些场景真正需要毫秒级洞察。文章指出,组织通常额外搭建 Apache Druid、Apache Pinot 或 ClickHouse 等专用服务引擎,导致数据重复、管道脆弱和治理割裂;湖仓一体方案可直接在受治理数据上实现毫秒级查询与高并发。

    A three-axis framework showing freshness (how recent), latency (how fast), and concurrency (how many) as the three dimensions of real-time analytics requirements.

    ere real-time creates measurable business value; Organizations typically bolt on specialized serving layers when they need to analyze data in real-time, creating duplicated data, fragile pipelines, and fragmented governance; A lakehouse approach delivers millisecond query performance and high concurrency directly on governed data. Learn how to evaluate real-time analytics workloads, see common use cases across industries, and find best practices for building and optimizing real-time analytics at

    匹配字段正文

  3. NVIDIA Developer · Generative AI

    NVIDIA 如何用 AI 智能体重写 Apache Spark UDF 实现 GPU 加速

    NVIDIA 介绍用 AI 智能体重写 Apache Spark UDF 的方法,通过 Spark SQL 表达式、RapidsUDF 接口或 JNI 调用自定义 CUDA kernel 三种方式消除 CPU 回退,实现 20 倍以上加速。cuDF skills for Apache Spark 将重写拆成测试、转换、基准测试和优化四个带验证反馈的环节。一家大型消费科技公司用该流程改造了 30 多个生产 UDF,其中一个 UDF 影响 3000 多个作业,改写后提速 22 倍。

    L; T; F; R; E AI-Generated Summary NVIDIA cuDF plugin for Apache Spark leverages GPU parallelism to accelerate data analytics workloads and improve total cost of ownership; User-defined functions in Spark break the declarative abstraction, forcing GPU-accelerated pipelines to fall back to CPU execution and incur data transfer overhead; UDFs can be rewritten using Spark SQL expressions, the RapidsUDF interface with the Java API for cuDF, or custom CUDA kernels via JNI to eliminate fallback and ac

    匹配字段正文

  4. Ed Zitron 长文 / Where’s Your Ed At

    Ed Zitron 长文质疑 AI 公司年化收入与 GPU 租赁数据

    Ed Zitron 在长文中指出,OpenAI 与 Anthropic 等公司使用的年化收入(annualized run rate)缺乏明确时间区间和计算口径,无法反映真实营收。他引用公开合同与财报称,AI 初创公司以低于成本的价格转售 token,其收入高度依赖持续融资,而 GPU 长期租赁的实际价格也远低于公开指数报价。

    he Information and the Wall Street Journal, while Anthropic, per the WSJ and the FT, made $15.5 billion ($4.6 billion in Q1 and $10.9 billion in Q2). We do not have consistent coverage of their underlying costs, but in Q1 (per The Information), OpenAI spent $8.6 billion on training and $3.5 billion on “cost of revenue,” with no reporting on its sales and marketing spend where it allocates the cost of serving free users or discounts. Anthropic said it had hit an annualized run rate (undefined per

    匹配字段正文

  5. Latent Space

    Dyna Robotics 联创 Jason Ma 谈世界动作模型与机器人落地

    Dyna Robotics 联合创始人兼首席科学家 Jason Ma 在 Latent Space 播客中介绍了上月发布的 Dyna-2 世界动作模型,该模型基于超过一百万小时人类视频预训练,采用 diffusion transformer 与 flow matching 架构,可同时预测未来视频与机器人动作。他称机器人可在少至 45 分钟演示数据下学会新任务,并已在 Din Tai Fung 门店每天折叠数千张餐巾纸,同时强调数据与硬件仍是通用机器人的主要瓶颈。

    stions I have about you making your own models is what is the constraints you operate in? So if you draw a parallel to language models, you see GPT-OSS 20B is very fit for your average MacBook. Then there’s a larger one that’s fit for a single GPU. Do you work in the constraints of robot, of model on on device, in cloud, a hybrid? And then how does that affect your scaling law of data? A million hours is great, but like do we just scale up parameters, data? Jason Ma [00:17:38]: No, that’s a grea

    匹配字段正文

  6. AWS Machine Learning

    用托管权益管理 Amazon Bedrock 的私有定价优惠

    AWS 发布两种在 AWS License Manager 中激活 AWS Marketplace Private Pricing Offer(MPPO)权益的方式:轻量脚本用于一次性激活,CDK 自动化用于持续的事件驱动处理。CDK 方案通过 EventBridge 监听 aws.agreement-marketplace 事件,由 Lambda 校验卖家白名单并创建分布式授权,调用 CreateGrantVersion(Status=ACTIVE) 激活,协商价格在授权达到 ACTIVE 或 WORKFLOW_COMPLETED 后生效。

    d. He holds a PhD in Computer Science from the University of California, Irvine, with a research focus on machine learning and bioinformatics. Bryn Price Bryn is a technologist, paragliding pilot, and Principal Solutions Architect at AWS. With more than 20 years of experience across telecommunications, banking, and software, he’s spent recent years deep in Applied AI, designing and building multi-agent AI products in production, and helping customers move from experimenting with generative AI to

    匹配字段正文

  7. AWS Machine Learning

    Anchor Browser 与 Amazon Bedrock AgentCore payments 集成,让 AI 智能体自主完成 x402 支付

    Anchor Browser 与 Amazon Bedrock AgentCore payments 集成,让 AI 智能体在遇到 HTTP 402 Payment Required 时自主完成 x402 协议支付,无需人工介入。AgentCore payments 在基础设施层管理钱包连接、执行可配置支出限额,并通过 Amazon CloudWatch 提供支付尝试、批准、拒绝与结算的可观测性。该方案由 AWS Generative AI Innovation Center Partner Agent Factory 协作开发,现已在 AWS Marketplace 上线。

    Agent payment stack with eight embedded components connecting to an x402 API, showing a 402 challenge returning and a retry sent forward

    ations that might vary in challenge format, supported stablecoins, or settlement timing Security and key management Storing a private key to sign payments, requiring secure key storage within an environment exposed to untrusted inputs; Managing wallet lifecycle operations, including key rotation, credential refresh, and provider failover Operational resilience Resubmitting the original request with the payment header while preserving session state, cookies, and request context; Providing idempot

    匹配字段正文

  8. TechCrunch AI

    Flox Intelligence 用 AI 让野生动物远离火车、机场和公路

    Flox Intelligence 从瑞典 KTH 皇家理工学院分拆,用边缘设备识别靠近铁路、机场和公路的动物种类,再播放对应物种的声音将其驱离,并变化响应避免动物习惯化。目前约 150 台设备部署在北美、欧洲和澳大利亚,公司预计 2026 年底营收约 150 万美元,已累计融资约 500 万美元,正启动 1000 万美元 A 轮。其 OEM 合作伙伴包括列车制造商 Alstom。

    years ago that wildlife and infrastructure do not mix anywhere on the planet. The FAA estimates that wildlife strikes have cost U.S. civil aviation about $272 million a year on average between 1990 and 2025. In France, the rail operator SNCF says wandering animals affect more than 8,000 trains across the country each year and are among its five leading causes of delays. In Brittany, 120 trains hit animals in 2023 alone, disrupting 660 services and causing more than 15,000 minutes of delays. Read

    匹配字段正文

  9. The Verge AI

    Ray-Ban Meta Audio 眼镜评测:没有摄像头,反而更自在

    Ray-Ban Meta Audio 是 Meta 推出的纯音频智能眼镜,售价 350 美元,去掉摄像头后佩戴时不再有被当作偷拍者的顾虑。它目前搭载较弱的 Muse Spark 模型,更强的 Muse AI 要等到今年晚些时候才上线;作为开放式耳机音质尚可,但高音量下高音发尖、低音失真且存在漏音。

    ing, I smiled at a barista while ordering a caramel apple-flavored matcha latte. Afterward, I sat on a park bench reading a book, called up a pal to chat about her recent trip to Prague, and then asked my Ray-Ban Meta Audio glasses what meetings were coming up on my calendar. The chipper AI voice said I hadn’t connected my Google Calendar yet (I had) and asked if I would like help connecting. I sighed and then asked it to play an upbeat song. It picked Kendrick Lamar’s “Not Like Us.” These past

    匹配字段正文

  10. Simon Willison

    Anthropic 自研代码版本控制系统 Scion 替代 Git

    Anthropic 撰文介绍其自建的 Git 替代方案,起因是代码变更速度大幅上升:2026 年 5 月日均合并约 2,500 次代码变更,到 9 月已超过 30,000 次。新系统名为 Scion,配套的代码审查系统叫 Antique,由七人团队开发,五个月内完成从 Git 的迁移。文中提到其主分支历史接近 100 GB,压缩后的工作副本超过 25 GB,每天约 2,500 万次代码检出,若按传统方式拉取每天将产生超过 600 PB 的 git 流量。

    ng why and how they built their own custom alternative to Git, based on the dramatic increase in rate of changes to their code after the past six months. In May 2026, Anthropic averaged around 2,500 code changes merged per day; as of September, we merged over 30,000 per day. They included a chart showing those changes. I had Claude modify their chart (code here) to add markers for the public releases of each of their models in 2026: This shows public release dates, not the date when models becam

    匹配字段正文

星期二

  1. Google DeepMind

    Google DeepMind 发布 Gemini 4 Argon,面向所有用户开放

    Google DeepMind 发布前沿模型 Gemini 4 Argon,向开发者、企业和消费者开放,在 Vals Index 上排名第一,覆盖编码、金融、法律和网络安全等领域。该模型通过 Gemini API 提供 1M 统一输入输出 token 上限,并公布多项实测结果,包括 Antigravity 中智能体代码提交量提升超 35%、回滚减少近三分之一,以及将 Gemma 4 E2B 在 A100 上通过 vLLM 实现 2.85 倍端到端推理加速。安全方面,Argon 在 Gray Swan 间接提示注入基准上将 15 次自适应攻击的成功率降至 0.7%,并推出面向 1 万名科学家的 Antigravity 最高使用档位 6 个月免费计划。

    urce Agent Development Kit (ADK), a framework powering enterprise agents, push their performance engineering further. The team gave Argon their .agents/skills rulebook and a one-paragraph goal to eliminate framework overhead without breaking existing apps. Working autonomously overnight, Argon surfaced optimizations, now live in google/adk-python, that cut in-memory session prep time by 40% in long sessions and sped up cold imports by 21%. Read the engineering deep dive to learn more; Quantum ch

    匹配字段正文

  2. Google DeepMind

    Google DeepMind 发布 Gemini 4 Argon 安全与防护报告

    Google DeepMind 公布 Gemini 4 Argon 的安全与防护方案,并开始向更广泛用户开放该模型,同时扩大 Fairwind Program 的可信网络安全防御者范围。在网络安全测试中,Argon 解决了全部 12 个端到端模拟网络攻击场景,上一代为 5 个;在对抗测试集上违规请求减少近一半。防护采用输入筛查、激活探针内部监测和持续监控三层实时机制,在 Gray Swan 的间接提示注入基准上把 15 次自适应攻击的成功率降至 0.7%。

    Gemini 4 Argon logo next to a large white "4", all on a gradient blue background

    tcuts. Instead, the share of shortcuts the model took silently — without mentioning them in its thoughts — more than tripled (from 11.2% to 36.4%). Avoiding thought penalties encourages the model’s reasoning to stay transparent and monitorable. Prompt injection resistance To trust an agent to do the job right, we need to ensure that malicious content the agent comes across cannot trick it to take a harmful action. When agents browse webpages or read code, they can encounter hidden, malicious ins

    匹配字段正文

  3. AWS Machine Learning

    Amazon SageMaker AI 上的 Mixture-of-Experts 内核工程优化

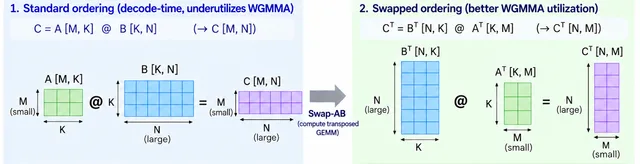
    AWS 分享了在 Amazon SageMaker AI 上针对 fused MoE 模型的内核优化:通过 Swap-AB 让专家维度 N=8192 进入 WGMMA 首个操作数位置,在 H200 上带来 2–4% 端到端输出吞吐提升,该优化已合入 vLLM 0.24.0 或更高版本。此外,在 Hopper 上对 FP8 张量量化模型,Triton 后端在低并发 MoE 负载下持续优于默认的 FLASHINFER_CUTLASS 路径。

    Swap-AB transposition promoting the large expert dimension into the WGMMA operand-A slot for full Tensor Core utilization

    oundly inefficient. The result is heavy warp under-utilization or expensive memory padding overhead. Conversely, the Triton MoE backend excels at dynamically mapping these small, fragmented token arrays across the physical boundaries of the active expert weights. This keeps the hardware’s internal prefetch streams and Tensor Core pipelines fully saturated even when processing highly unstable workloads at very low batch sizes. Updating the routing policy is a pure configuration change with no ker

    匹配字段正文

  4. AWS Machine Learning

    在 Amazon Bedrock 上用 Grok 4.7 构建长时程智能体

    SpaceXAI 的 Grok 4.7 已在 Amazon Bedrock 上线,支持可配置 reasoning effort、工具调用和结构化输出,并提供 500K token 上下文窗口。AWS 用三个需搜索推理的任务做了 72 次智能体运行,正确 67 次;xhigh 档 18 次全对,low 档 18 次对 15 次且输出 token 约为八分之一。

    time, so ramp a new high-volume workload gradually rather than starting at full rate. Auditing a run. Model invocation logging writes request and response data to Amazon Simple Storage Service (Amazon S3) or Amazon CloudWatch Logs. This gives you the full transcript of runs you want to review after the fact. Monitoring reasoning volume at scale. Amazon CloudWatch metrics give you the aggregate view of token usage, which is where the per-level baselines described earlier become something you can

    匹配字段正文

  5. AWS Machine Learning

    ShipStation Global 如何在 Amazon Bedrock AgentCore 上构建 AI IT 服务台

    ShipStation Global 工程团队基于 Amazon Bedrock AgentCore 打造了 Slack 内的 AI IT 服务台 Deckhand,可回答常规 IT 问题、读取报错截图并创建和更新 Jira Service Management 工单。上线后它解决了 97.5% 的频道查询,员工正面反馈率达 96%。该方案由 Slack 服务、Strands 智能体、MCP 工具与知识库、DynamoDB 反馈等四部分组成,智能体使用 Anthropic 的 Claude 模型。

    Chart showing Deckhand reached 97.5% channel coverage and a 96% positive feedback rating over three months

    nd, which resulted in resolving 97.5 percent of incoming channel queries while earning a 96 percent positive feedback rating by employees (Figure 1). Figure 1: 3-month channel coverage and positive feedback Business challenge The problem Deckhand solves is the one every IT team will recognize: the same questions are routinely asked, error messages are posted after business hours, and information needs to be gathered from different teams. At ShipStation Global, those conversations lived in a busy

    匹配字段正文

  6. Recode China AI

    我们听到更多中国 AI 的声音,但真的更理解它们了吗?

    DeepSeek 机器学习系统与内核设计工程师刘胜宇的微信博客意外走红,被南华早报和 Business Insider 等媒体报道,他在文中称前沿 AI 已能快速优化自身底层 GPU 代码,并把自己对 Anthropic CEO Dario Amodei 的争议性类比写入文末。随着中国 AI 研究者活跃于 X、AI 翻译让一手内容更快流入西方媒体,中国科技报道正从传统驻华记者转向独立专家与一线深度报道。

    Tony Peng's avatar

    app that reads your bazi, a traditional chart tracking birth dates and elemental forces. Wang brings both her Chinese origins and western analytical skills to serious China AI coverage, but this level of on-the-ground depth remains rare. What’s changing the old media gatekeeping model over the past three years is the inflow of new China tech content. First, Chinese researchers and scientists are opening accounts on X, communicating directly while cross-posting thoughts just as they would on Chin

    匹配字段正文

  7. Artificial Analysis 完整文章

    Artificial Analysis 发布 Decision Index v1.0,评测决策模型

    Artificial Analysis 推出 Decision Index v1.0,用四项评测(AA-Omniscience 改编的 500 道私有题、HLE 的 513 道文本多选题、NVIDIA 工具调用评测、Ai2 安全分类测试集)衡量决策模型在分类、工具调用、知识、幻觉与推理上的表现。Jev 1.13 以 58 分居首,GLiDE 与 Microsoft-Decision-1 均为 54 分;Decider v1.1 27B 每百万任务成本最低为 $17,Celeris-1 Decision 每任务 0.06 秒最快。决策模型比 LLM 更快更便宜,但知识与推理落后。

    from $17 to $199 per one million tasks, and median times from 0.06 to 0.5 seconds per task. Artificial Analysis Decision Index vs. Cost per 1M Tasks Decision Cost per 1M Tasks Average cost per task at current token prices, multiplied by 1 million; for the index, the cost of one pass through all its evaluations divided by their combined tasks, multiplied by 1 million. Decision models are billed for input tokens only, and language models for input and output tokens. Decider v1.1 27B has the lowes

    匹配字段正文

  8. Google Blog

    Google 发布 Gemini 4 Argon,面向开发者与消费者开放

    Google 发布最新前沿模型 Gemini 4 Argon,向开发者、企业、科学家和消费者开放,并在 Vals Index 上排名第一。官方称其在 Antigravity 中让智能体代码提交量提升超过 35%、代码回滚减少近三分之一,并将 xTB 分子结构预测提速最高 2.3 倍。模型通过 Gemini API 提供 100 万统一输入输出 token 上限,采用介绍期定价,11 月 30 日后为每 100 万输入 token 4 美元、输出 token 20 美元。

    urce Agent Development Kit (ADK), a framework powering enterprise agents, push their performance engineering further. The team gave Argon their .agents/skills rulebook and a one-paragraph goal to eliminate framework overhead without breaking existing apps. Working autonomously overnight, Argon surfaced optimizations, now live in google/adk-python, that cut in-memory session prep time by 40% in long sessions and sped up cold imports by 21%. Read the engineering deep dive to learn more; Quantum ch

    匹配字段正文

  9. Google Blog

    Google 发布 Gemini 4 Argon 安全与安保报告

    Google 公布 Gemini 4 Argon 的安全与安保报告,说明其在滥用防护、失准监控和提示注入抵抗三方面的做法。Argon 在 12 个端到端模拟网络攻击场景中全部通过,上一代为 5 个;在 Gray Swan 的间接提示注入基准上,15 次自适应攻击的成功率降至 0.7%。Google 同时开始大范围推送 Argon,并扩大 Fairwind Program 的可信网络防御者范围。

    Gemini 4 Argon logo next to a large white "4", all on a gradient blue background

    tcuts. Instead, the share of shortcuts the model took silently — without mentioning them in its thoughts — more than tripled (from 11.2% to 36.4%). Avoiding thought penalties encourages the model’s reasoning to stay transparent and monitorable. Prompt injection resistance To trust an agent to do the job right, we need to ensure that malicious content the agent comes across cannot trick it to take a harmful action. When agents browse webpages or read code, they can encounter hidden, malicious ins

    匹配字段正文

  10. Modal 官方工程博客

    Modal 研究混合精度、混合加速器采样器上的强化学习

    Modal 工程博客提出用离策略修正让 RL 采样器与训练器解耦,从而在混合精度、混合加速器上稳定训练。实验用 Miles 框架、SGLang 采样器和 Megatron-LM 训练器,在 B200 上以 BF16 训练 Qwen3.6-35B-A3B 做智能体编码任务,采样器分布在 B200、B300、H100、H200、A100 和 RTX PRO 6000 六类加速器上,分别使用 NVFP4、FP8 和 BF16 权重。加入掩码重要性采样、分数居中和 top-p 掩码回放后,混合采样器在 SWE-bench Pro V2 上与同构采样器持平,HARD-51 上 pass@4 稳定在约 65–75%,且多数训练阶段每次更新的采样成本低约 15%。

    samplers’: the two runs’ pass@4 stays close throughout training. Their training reward and gradient norm also follow similar paths, despite a 4.7× larger sampler–trainer KL on average. Entropy matches until about step 160; afterwards, it rises on the homogeneous samplers and stays flat on the mixed ones. Importantly, nothing in how the correction works is specific to this model or these accelerators, so we expect this pattern to hold more broadly. Decoupling the samplers from the trainer also m

    匹配字段正文