←搜索结果

按匹配度 · 共 3412 条结果 清除搜索

星期二

  1. Tomasz Tunguz 博客

    Theory 2026 AI 实践调查:安全成首要痛点,45% 团队跨模型路由查询

    Theory 第二届 AI in Practice Survey 调查 455 名资深技术构建者,43% 将安全与治理列为最重要痛点,较去年第六位升至第一,但仅 10% 认为安全工具当前最有价值。45% 团队跨模型路由查询,其中 23.7% 用自训练路由器、21.5% 用商用路由器;259 个用智能体写代码的团队中 62% 将沙箱托管在 Cloudflare,56% 用 BI 工具分析智能体表现,48% 用编码智能体读取生产日志。

    nded & multi-select questions sum above 100%, & where 2025 allowed one answer & 2026 allowed several, every 2026 share is lifted. The pain comparison holds each area’s place by average rather than its score, because 2025 asked for a ranking & 2026 asked for a 1-7 rating of each area, so context moving from first to fourth is a comparison of place, not of score. Q9 routing & Q12 sandbox hosting are new in 2026 & have no prior-year comparison ; Q12 was asked only of the 259 teams whose agents writ

    匹配字段正文
  2. Liquid AI 模型与工程博客精选

    Liquid AI 发布 LFM2.5-24B-A2B 端侧智能体模型

    Liquid AI 发布 LFM2.5-24B-A2B,总参数 24B、每 token 仅激活 2B,是 LFM2.5 家族中最大也是最后一款模型,基础版与后训练版均已在 Hugging Face 和 Playground 开放权重。该模型在八项智能体与工具调用基准中的五项领先或持平 Qwen3.6-35B-A3B,AutomationBench 得分为 27.69 对 8.72,LiveClaw 为 48.09 对 38.19。它采用显式思维链的纯推理模式,上下文窗口从 32,768 扩展到 131,072 tokens,词表从 65K 扩至 128K,预训练数据从 17T 扩至 33T tokens,在 Apple M5 Max 上解码 184 tokens/s,单张 NVIDIA B300 GPU 高并发下输出超过 21K tokens/s。

    ment learning. Unlike its predecessor, LFM2.5-24B-A2B is a reasoning-only model that produces an explicit chain of thought before its final answer. We adopted this strategy to leverage its high decode speed and improve answer quality. Architecture. It keeps the 40 layers, 64 experts per MoE block with top-4 routing, and the same hybrid of gated short convolutions and GQA. The two architectural changes are the context window extension from 32,768 to 131,072 tokens, and the in-place tokenizer expa

    匹配字段正文

  3. 腾讯云开发者社区

    开源三个月、5次大变更、9100+ Star:腾讯Octop的狂奔之路

    腾讯云 Octop 自 2026 年 7 月 10 日在 GitHub 开源,95 天内经历从 LightClaw ACE 重构、v1.0.0 GA、v1.0.1 企业级 SSO 接入到 v1.0.2 插件化与多模态四次大变更,Star 数突破 8500,Issue 和 PR 超过 1200 条。团队将 harness-agent、harness-memory、harness-browser、harness-gateway 四大模块拆分为独立仓库开源,并公开了 AgentTeams、移动端客户端、浏览器技能录制等后续规划。CVE-2026-108581 显示 1.0.2b6 之前版本存在 Provider API Keys 未授权访问问题,已在后续版本修复。

    {"type":"doc","content":[{"type":"paragraph","attrs":{"id":"7d947b97-ce54-48d9-92b1-b91ff84f9d73","textAlign":"inherit","indent":0,"color":null,"background":null,"isHoverDragHandle":false},"content":[{"type":"text","text":" "}]},{"type":"image","attrs":{"id":"5a1b870b-4697-4c18-baa8-b94660eb7e3d","src":"https://developer.qcloudimg.com/http-save/audit-1051367/3381adc449b16baa126bdd76571b8c44.png","extension":"png","align":"center","alt":"","showAlt":false,"href":"","boxShadow":"","width":1100,"as

    匹配字段正文

  4. CNN Business Tech

    Character.ai 因青少年自杀诉讼申请 Chapter 11 破产

    Character.ai 已申请 Chapter 11 破产,公司称计划在年底前寻求法院监督下的出售,若交易未完成平台将被关停。迪士尼已作为竞购买家出价 2000 万美元收购其部分知识产权,并提供过渡服务;Character.ai 破产申请显示其资产在 5000 万至 1 亿美元之间。此前该平台因被指与青少年自杀、自残相关而面临多起诉讼,今年已就包括 Megan Garcia 案在内的五起案件达成和解。

    e death of her 14-year-old son Sewell Setzer III. Other families filed a string of additional lawsuits, accusing the platform of providing sexual content to their children or encouraging suicide, self-harm or violence. Character.ai agreed to settle five cases, including Garcia’s, earlier this year. Matthew Bergman, founder of the Social Media Victims Law Center, which represents several of the families who sued Character.ai, declined to comment on the bankruptcy filing. Related video CNN Mom des

    匹配字段正文

  5. 腾讯云开发者社区

    从"割裂感太强"到 34 次点击:我用 WorkBuddy 做课件动画的四次迭代

    一名大三计算机专业学生用 WorkBuddy 完成《数据结构》"二叉树及遍历"多媒体课件,从前期调研、18 页排版、自绘图形到动画编排与逐页验证均由 AI 执行,其中"分步演示"环节被连续退回四次。开工前 WorkBuddy 先检索 AI 自动生成 PPT 的常见坑点,汇总为 A 内容与教学设计、B 视觉设计、C 素材与图形、D 动画与技术、E 交付规范五类避坑清单,并据此把主线改为"导入—讲解—示例—练习—小结"、锁定学术蓝配色与正文 ≥22px 字号。

    {"type":"doc","content":[{"type":"blockquote","attrs":{"id":"b0454304-374c-4f15-948d-4c0e6fdbf3aa","textAlign":"inherit","isHoverDragHandle":false},"content":[{"type":"blockquote","attrs":{"id":"bf60f3d9-8d8e-48e5-8944-afd6b5bee034","textAlign":"inherit","isHoverDragHandle":false},"content":[{"type":"paragraph","attrs":{"id":"02d146b1-4341-4ab7-bf8f-0b4078e48573","textAlign":"inherit","indent":0,"color":null,"background":null,"isHoverDragHandle":false},"content":[{"type":"text","text":"我是大三计算机专业

    匹配字段正文

  6. Jeff Dean

    Jeff Dean 支持 Khipu AI 与 DeepIndaba

    我一直通过我们的家族基金会以个人身份支持 @Khipu_AI 和 @DeepIndaba,这两个活动对非洲和南美洲的 AI 研究者来说非常棒。我过去曾鼓励 Google 支持它们。Discovery Loop(@DiscoLoopAI)很高兴提供支持!

    I've been a personal supporter (through our family foundation) of @Khipu AI & @DeepIndaba, which are fantastic events for AI researchers in Africa and South America. I've encouraged Google to support these in the past. Discovery Loop (@DiscoLoopAI) is thrilled to support!

    匹配字段正文

  7. Arena

    Meta Muse Wonder 系列模型上线 Arena

    Meta 的 Muse Wonder 与 Muse Wonder Full 已进入 Arena,可在 Agent Arena 中测试,分数即将公布。Agent Arena 基于全球用户数百万个真实长周期智能体任务评测模型,模型可调用网页搜索、文件系统和终端工具,排行榜用因果追踪方法衡量相对平均模型的结果表现。Muse Wonder 同时上线 Code Arena 的 WebDev、Image-to-WebDev、Text 和 Vision 板块。

    is now in the Arena. Head to Agent Arena to test it out, scores coming soon! In Agent Arena, we measure models on millions of real-world, long-horizon agentic tasks from a global community of users. Models can access web search, filesystem, and terminal tools to complete complex workflows. The leaderboard measures model performance on outcomes relative to the average model using a causal tracing methodology. Muse Wonder is also available in Code Arena: WebDev, Image-to-WebDev, Text, and Vision.

    匹配字段正文

  8. Arena

    Arena 称 7 月最可靠的 AI 智能体现已沦为平均水平

    Arena 的 Agent Arena 通过让用户委派真实任务并确认结果是否满足需求,形成 Confirmed Success 信号。7 月 1 日 Claude Fable 5 明显领先其他模型,仅 12 周后前 20 名平均分就追平了它;Kimi K3 在 3 周内以每任务低 89% 的成本超过它,DeepSeek V4.1 Flash 则以低 96% 的成本追平。目前前 5 名任务确认完成率达 94%,高于 7 月的 80%,领先者为 Claude Opus 5.5、Claude Fable 5.1 和 GPT-6.1 Sol。

    July's most reliable AI agent is now just average. With Agent Arena, people delegate real tasks to agents and confirm whether the result met their needs. We call this signal Confirmed Success. On 1 July, Claude Fable 5 was well ahead of every other model, and it only took 12 weeks for the top‑20 average to match it. Kimi K3 beat it within just 3 weeks at 89% lower cost per task, and DeepSeek V4.1 Flash now matches it at 96% lower cost. Meanwhile, the top 5 now get 94% of tasks confirmed done, up

    匹配字段正文

  9. 腾讯混元 Research

    腾讯混元发布 Hy4 preview:770B 总参数、49B 激活、1M 上下文

    腾讯混元发布 Hy4 preview,总参数 770B、激活参数 49B、上下文长度 1M,在代码、办公、科学等真实生产力任务上做了扩展,模型权重已在 GitHub、HuggingFace 和 ModelScope 开放。官方称 163 名内部专家对 203 个工程任务盲测中,Hy4 preview 均分 2.99/4,略优于 GLM 5.3 的 2.92/4 和 Kimi K3 的 2.94/4。API 价格为每百万 Tokens 输入命中缓存 0.3 元、输入 6 元、输出 18 元,官方同时说明这是 Hy4 的早期版本,存在复杂任务长思考和过度自我验证等已知问题。

    0,\n 跃变处留 3px 软过渡(soft = 3/256)避免锯齿。未登记的行留纯黑。\n 一个物件类型占一行,用行号索引,例:\n 0 深色远景树冠 / 2 中景树冠 / 9 树干 / 23,24 岩石 /\n 26,27 枯草 / 48,49 地面草地 / 50 小径 / 56 沙 /\n 58,59 草叶 / 73 墙 / 93 屋顶\n 材质 fragment:\n rampX = fit(dot(N, uSunDir), -1, 1, 0, 1) shadow\n col = texture2D(tRamp, vec2(rampX, rowV)).rgb\n 即:明暗只有两档色块,硬边分界。这是绘本色块的本质,不要磨平。\n\n3. 草地专用规则(最容易做错的一处):\n 草不能用 dot(N,L) 查 ramp —— 实例化草叶法线杂乱,会发暗发噪。\n 草改用 shadow 值直接查 ramp。\n 另外用 step(0.8, hash) 让 20% 的草采「基行 +1」那条 ramp,\n 靠两行色差造出叶片明暗差异,而不是靠堆面数。\n\n4. 雾在 HSV 空间

    匹配字段正文

  10. InternLM 原创项目

    InternLM 发布 STAR-Bench:评测音频 4D 智能的时空推理基准

    InternLM 发布 STAR-Bench,一个用于衡量音频 4D 智能(对声音在时间与 3D 空间中动态变化的推理)的基准,v1.0 已上线 HuggingFace,相比 v0.5 修订了空间任务问答。该基准包含基础声学感知(绝对与相对两种设定下的六项属性)和整体时空推理(连续与离散过程的片段重排,以及静态定位、多源关系、动态轨迹等空间任务)。评估支持 Qwen2.5-Omni、Kimi-Audio、Phi4-MM、Gemini、GPT-4o Audio 等模型,数据与代码仅限研究用途。

    Improving multi-audio reasoning. Open-source models lag significantly in comparing, integrating, and grounding information across multiple audio clips; 🔥 Moving beyond channel-averaged audio preprocessing. The common practice of averaging multi-channel audio into a mono signal is a major bottleneck for spatial reasoning. Developing architectures that natively process multi-channel cues is essential for unlocking genuine spatial awareness ⚙️Data Curation 🛠️ Test Your Model! The ALMEval code/ is

    匹配字段正文

  11. InternLM 原创项目

    InternLM CapRL:用强化学习提升密集图像与视频描述能力

    InternLM 发布 CapRL 系列密集描述模型,用强化学习替代传统监督式描述模仿,以 QA 效用作为可验证奖励。CapRL-Qwen3VL-2B 在描述任务上超过 CapRL-Qwen2.5VL-3B 和 Qwen2.5VL-72B,CapRL-Qwen3VL-4B 性能进一步提升。CapRL++ 将框架扩展到视频,CapRL-Video-4B 基于 Qwen3-VL-4B 训练,支持带时间戳的视频描述。

    nderstanding when used as caption data; 🔥 Remarkable visual understanding for charts, infographics, and documents: CapRL-3B achieves perception accuracy and visual information coverage comparable to Qwen2.5-VL-72B; 🔥 Well-organized dense output: CapRL models generate structured captions that cover fine-grained objects, attributes, OCR content, relations, and events Model Card Based on the same recipe as CapRL-3B, we used InternVL3.5-8B as the policy model and obtained CapRL-InternVL3.5-8B throug

    匹配字段正文

  12. InternLM 原创项目精选

    InternLM 发布 35B 基础模型 Intern-S2-Mobius

    InternLM 发布 Intern-S2-Mobius,一个基于 Mobius-v0 架构、由 Xtuner 和 LMDeploy 实现的 35B 基础模型。它把知识存储与推理计算解耦,用全局共享 Memory 替代逐层绑定的 FFN 知识存储,让多个 Reasoner 迭代查询和精炼隐状态,具备 Backward Residual Connection 和 Dynamic Latent Reasoning 两项能力。模型由 Qwen3.5-35B 继续预训练并经 SFT 和 RL 后训练,技术报告称端到端推理效率提升近 4 倍,在推理基准上得分与 Qwen3.5-35B 相当或更强,同时推理链更短、请求吞吐更高,并在 Biology-Instructions、Mol-Instructions、MolecularIQ 等科学任务上有较大提升。模型以 bfloat16 权重格式发布,支持 LMDeploy、Transformers、vLLM、SGLang 部署,推荐使用 MTP 投机解码。

    ository files navigation We introduce Intern-S2-Mobius, a 35B foundation model built on the Mobius-v0 architecture realized by Xtuner and LMDeploy. Instead of binding knowledge storage and reasoning computation layer by layer as in conventional Transformer models, Mobius organizes knowledge into a globally shared Memory and lets multiple Reasoners iteratively query and refine hidden states against this shared repository. This knowledge-reasoning separation gives Intern-S2-Mobius two native capab

    匹配字段正文

  13. 小米 MiMo 官网发布与博客

    小米详解 MiMo-V2.5 推理系统优化实践

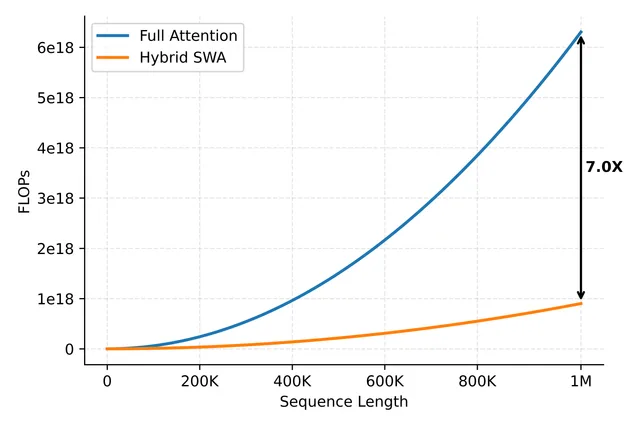
    小米 MiMo 团队发布 MiMo-V2.5 系列推理系统的端到端工程实践,覆盖 KVCache 管理、分层缓存、SWA 感知前缀缓存树、调度策略、Prefill/Decode 执行流水线与多模态优化。MiMo-V2.5-Pro 共 70 层,其中 10 层 Full Attention、60 层 SWA,滑动窗口为 128,Hybrid SWA 使计算量与 KVCache 存储降至 Full Attention 的约 1/7。团队称上线以来服务端 KV Cache 命中率平均 93%,重度用户可达 95% 以上,并将部分优化以 PR 形式回馈 SGLang 社区。

    Attention FLOPs vs sequence length: Full Attention vs Hybrid SWA, roughly a 7.0× compute reduction

    The V2.5 model family, including MiMo-V2.5 and MiMo-V2.5-Pro, combines several architectural design choices: Hybrid Sliding Window Attention (Hybrid SWA) compresses KVCache storage to roughly 1/7 that of Full Attention; sparse MoE activation cuts per-token compute while preserving model capacity; and multimodal encoders enable cross-modal understanding across vision, audio, and video. Together, these features give the MiMo-V2.5 series significant performance and efficiency potential in long-cont

    匹配字段正文

  14. InternLM 原创项目

    InternLM 发布 InternLumina-U2 统一多模态模型推理代码与昇腾权重

    InternLM 发布 InternLumina-U2,一个 16B-A1B 的 MoE 统一多模态模型,用同一套骨干和离散 token 接口覆盖文本问答、文生图、图像理解与编辑、视频理解和 3D 理解。该模型基于 LLaDA-2.0 MoE 扩散语言模型,采用 AToken 的 8 码本全离散视觉表示,输入侧拼接各码本嵌入,输出侧以空间并行去噪加码本深度自回归预测。目前仓库只放出推理代码,昇腾训练权重已在 Hugging Face 提供,NVIDIA 权重、训练代码和技术报告将后续发布。

    yTorch SDPA; flash-attn is needed only by the AToken visual tokenizer (i.e. every task that encodes or decodes images/video/3D — plain text generation works without it); Object-storage packages (petrel-oss-sdk / boto3) are optional — local token files need neither; Precomputed .pkl/.pt token files are deserialized with PyTorch's trusted-payload mode for legacy NumPy payloads; load only files from a trusted source. To create such files yourself, see Tokenizer Utilities; The root driver is intenti

    匹配字段正文

  15. InternLM 原创项目精选

    InternLM 发布 Intern-S2 系列科学多模态模型

    InternLM 发布 Intern-S2-397B 及其预览版 Intern-S2-Preview-397B、Intern-S2-Preview-35B 等科学多模态基础模型,覆盖预训练、强化学习任务与长程智能体三个方向。其中 Intern-S2-Preview-35B 基于 Qwen3.5 继续预训练,仅用 35B 参数在多个核心专业科学任务上达到万亿级 Intern-S1-Pro 的相当水平,并采用共享权重 MTP 与 CoT 压缩提升推理效率。系列模型支持 LMDeploy、vLLM、SGLang 部署,以 Apache 2.0 许可发布。

    ltimodal foundation model for scientific intelligence and long-horizon agents. Intern-S2-397B scales along three critical dimensions: pre-training, reinforcement-learning task coverage, and interactive agent environments. By combining a new vision-language pre-training paradigm with large-scale multi-task reinforcement learning and long-horizon agent reinforcement learning, Intern-S2-397B delivers a step change in general reasoning, scientific problem solving, and agentic capabilities. Features

    匹配字段正文

  16. InternLM 原创项目

    InternLM 发布 WildClawBench:面向 AI 智能体的真实环境基准测试

    InternLM 推出 WildClawBench,一个在真实 OpenClaw 环境中运行的 AI 智能体端到端基准测试,包含 60 个原创任务,覆盖 6 个类别。技术报告快照中,最强前沿模型整体得分最高 62.2%,最新审计的 OpenClaw 运行已将最佳成绩提升至 67.2%。该基准支持 OpenClaw、Claude Code、Codex CLI 和 Hermes Agent 四种智能体框架,每个任务在独立 Docker 容器中运行以保证可复现性。

    del leaderboard (OpenClaw harness) Overall score follows the weighted Multimodal / Pure-text breakdown in that table. Total time and total cost are the paper’s Overall per-task averages (minutes / USD) multiplied by 60 for the full 60-task suite. Claude Opus 4.8 cost uses the dynamic base-tier rates for this evaluation: $5/M input, $25/M output, $0.5/M cache read, and $6.25/M cache write. Muse Glimmer 30B cost uses the OpenRouter rates for this evaluation: $0.35/M input, $1.50/M output, and $0.0

    匹配字段正文

  17. InternLM 原创项目

    InternLM 开源多模态决策模型 Intern-Decision,4B 版本七套基准平均准确率 90.02%

    InternLM 发布开源多模态决策模型 Intern-Decision,将状态、可选图像和多个带类型的问题转化为带概率的决策,支持 choice、score 和 noul(是/否)三类问题,训练时微调 Qwen3.5 的语言主干并冻结视觉塔和投影器。Intern-Decision-4B 在七套基准上平均准确率 90.02%,RTX 4090 本地平均请求延迟 44.16 ms,在 96 例校准基准上 Brier 为 0.550、ECE 为 0.089。该版本包含训练、两种推理后端、基准评分、温度校准和浏览器 demo,但训练数据、校准与验证记录、图像及模型权重未包含在内。

    ngle-token answer symbols, applies softmax, and maps them back to the original labels. Question and option ordering must be preserved. Results Intern-Decision-4B reaches 90.02% average accuracy across seven suites (Jev: 88.74%), 44.16 ms mean local request latency on an RTX 4090, and 0.550 Brier / 0.089 ECE on the 96-case calibration pilot (Jev: 0.595 / 0.130). The protocols and scope differ: see accuracy, latency, and calibration. Benchmark accuracy Accuracy columns are percentages; Average is

    匹配字段正文

  18. InternLM 原创项目

    InternLM/lmdeploy:压缩、部署与推理服务 LLM 的工具包

    LMDeploy 是 InternLM 团队开发的 LLM 压缩、部署与推理服务工具包,通过持续批处理、分块 KV cache、张量并行等特性实现最高达 vLLM 1.8 倍的请求吞吐,4-bit 推理性能为 FP16 的 2.4 倍。其论文《LMDeploy Accelerates Mixed-Precision LLM Inference with TurboMind》已被 EuroSys 2027 接收,v0.12.3 已上线 PyPI,可直接 pip install lmdeploy 安装。

    | 🤔Reporting Issues [2026/08] Our paper, “LMDeploy Accelerates Mixed-Precision LLM Inference with TurboMind,” has been accepted to EuroSys 2027; [2026/04] PyPI has expanded the storage quota for LMDeploy and wheel uploads have resumed. v0.12.3 is now available on PyPI, so you can install it directly via pip install lmdeploy; [2026/02] Support Qwen3.5; [2026/02] Support vllm-project/llm-compressor 4bit symmetric/asymmetric quantization. Refer here for a detailed guide [2025/09] TurboMind supports

    匹配字段正文

星期三

  1. Latent Space

    Dyna 首席科学家 Jason Ma 谈 Dyna-2 世界动作模型与小时级机器人自主

    Dyna Robotics 联合创始人兼首席科学家 Jason Ma 在 Latent Space 播客中介绍,Dyna-2 是基于超过一百万小时人类视频预训练的世界动作模型,采用扩散 Transformer 与 flow matching,先预测未来视频再生成机器人动作,类似视觉层面的链式推理。他称模型只需数十分钟到数小时的机器人演示数据即可适配新任务,Dyna-2.1 物理机器人已能连续一小时完成洗衣流程,餐厅客户 Din Tai Fung 处每天折数千张餐巾。他把数据与硬件列为通用机器人的主要瓶颈,指出灵巧手易过热、缺少触觉等传感维度,并解释公司选择轮式半人形、自研执行器与推理栈以压低延迟。

    stions I have about you making your own models is what is the constraints you operate in? So if you draw a parallel to language models, you see GPT-OSS 20B is very fit for your average MacBook. Then there’s a larger one that’s fit for a single GPU. Do you work in the constraints of robot, of model on on device, in cloud, a hybrid? And then how does that affect your scaling law of data? A million hours is great, but like do we just scale up parameters, data? Jason Ma [00:17:38]: No, that’s a grea

    匹配字段正文

星期一

  1. Vapi Blog

    Vapi 自研 Pedantic Review Bot 如何将 PR 合并时间减半

    Vapi 自研的 Pedantic Review Bot 让 PR 从开启到合并的平均时间从超过 130 小时降至 65 小时。2026 年 9 月 2 日至 10 月 2 日,该机器人审查了 1,694 个 PR,在 276 个 PR 中提出 363 项 blocker 问题,其中过半涉及构建、测试、CI 或部署。Lat Ware 还构建了 Pedantic Architecture Review Bot 检查设计问题,同期 763 次架构工作流运行产出 33 份报告。

    Engineering work and experiments by Lat Ware, Member of the Technical Staff When Lat Ware started building what he named the Pedantic Review Bot, a pull request at Vapi took an average of over 130 hours to go from open to merged. That number changed how Lat thought about automated review. Vapi already paid for two AI review tools, and neither caught what his early prompts caught on Vapi’s codebase. “I was competing with review times measured in days, so I could let the bot spend 20 minutes on a

    匹配字段正文