←搜索结果

按匹配度 · 共 1622 条结果 清除搜索

星期三

  1. Cohere 产品与研究博客

    Cohere 发布 Embed 5 系列嵌入模型,Pro 与 Fast 共享同一嵌入空间

    Cohere 发布 Embed 5 系列嵌入模型,包含面向最高质量的 Embed 5 Pro 和面向延迟与成本敏感场景的 Embed 5 Fast,两者共享同一嵌入空间,可用 Pro 建索引后用任一模型查询而无需重建索引。Embed 5 支持多模态输入与检索、100 多种语言和 128K token 上下文窗口,Pro 在 ViDoRe V3 上平均得分 85.8,Fast 为 84.5。模型已在 Cohere API、Model Vault、Microsoft Foundry 和 Amazon SageMaker 上线,Pro 定价为每百万 token 0.12 美元,Fast 为 0.08 美元。

    res therefore reflect reranking quality rather than first-stage retrieval performance, which we thoroughly evaluate elsewhere against nDCG and Recall. 2 The annotations and code needed to evaluate ViDoRe V3 with RCP-nDCG are available on GitHub. 3 Both sides must use the same output dimension. Compatibility also holds with Matryoshka truncation and int8 quantization, so the same pattern works with compressed indexes. Product Launch; Company News AI isn’t a shortcut. It’s how business gets ahead.

    匹配字段正文
  2. gihyo.jp

    OpenAI DevDay 2026 发布 ChatGPT Space、云端智能体 dots 与 GPT-6.1 Sol

    OpenAI 在 9 月 29 日的 OpenAI DevDay 2026 上发布 20 多项更新,包括 ChatGPT 内供团队与 AI 协作的 Space、在专用云环境持续工作的智能体 dots,以及新模型 GPT-6.1 Sol。dots 由 GPT-6 Astra 驱动,可连接 4000 多个应用,在用户离线时继续推进任务,Pro 与 Business Premium 各含 1 个 dot 且不额外收费。GPT-6.1 Sol 在 DeepSWE v1.1 上以 high 推理设置取得 75.2%,高于 GPT-6 Sol 最高设置下的 68.8%,标准 API 价格为每百万 token 输入 2 美元、输出 10 美元。

    作体験をWebとモバイルにも広げる。環境の準備はデスクトップアプリかWebで行い、準備後はモバイルでもその環境を選んでタスクを開始できる。進行中のタスクは別の端末から開き、進捗を確認したり、追加の指示を出したりできる。 従来版は「Codex Cloud(Legacy⁠)⁠」として当面残る。移行期間中、コードレビュー、セキュリティレビュー、既存のLinear・GitHub連携は従来版を使う。対応する既存環境は利用者の操作で新しい環境へ移行でき、元の環境と過去のタスク履歴は残る。 発表時の対象プランはPlus、Pro、Business、Healthcare、Education、Enterprise。dotsからCodexのクラウド環境でタスクを作成することもでき、その場合はあらかじめCodex側で環境を作っておく必要がある。 レビュー画面を刷新⁠、GitLab対応はプレビュー ChatGPTデスクトップアプリのコードレビュー画面を刷新した。Code Reviewプラグインでは、複数のリポジトリから自分やチームに依頼されたレビューを探し、プルリクエストの概要、差分、コメント、チェックの結果を

    匹配字段正文

  3. Hugging Face

    Hugging Face 推出 Open TTS Leaderboard:面向多语言 TTS 与语音克隆的可扩展评测

    Hugging Face 发布 Open TTS Leaderboard,默认按 Seed TTS Eval 英文集与 CV3 Eval(zero shot)的宏平均 WER 排名,hexgrad/Kokoro-82M、Supertone/supertonic-3 和 fishaudio/s2-pro 领先。榜单支持多语言切换(中日韩用 CER)、语音克隆对比与 SIM 说话人相似度列,并新增 Streaming 标签页按 TTFA 排名,kyutai/pocket-tts 在 GPU 和 CPU 上表现突出。

    for other languages. We will soon open-source the evaluation scripts, much like the Open ASR Leaderboard repo , so that you can directly provide your feedback and suggestions via GitHub Issues and PRs! Let's shape TTS evaluations together 🤗 Models mentioned in this article 10 FunAudioLLM/Fun-CosyVoice3-0.5B-2512 Text-to-Speech • Updated Feb 3 • 198k • 651 Qwen/Qwen3-ASR-1.7B-hf Automatic Speech Recognition • 2B • Updated Jul 22 • 357k • 114 Supertone/supertonic-3 Text-to-Speech • Updated May 18

    匹配字段正文

  4. Mastra Blog

    Mastra Factory 新增 Jira、GitLab 和 incident.io 集成

    Mastra Factory 新增 Jira、GitLab 和 incident.io 三种工作接入源,用于管理问题、功能请求和事故跟进。这些集成随 @mastra/factory 包发布,需 0.16.0 或更高版本,用户可在 .env 添加凭据并在 Factory UI 的 Settings → Work Intake 中配置。

    itLab, and incident.io, giving you more ways to manage and resolve issues, feature requests, and incident follow-ups. We launched Mastra Factory earlier this year with support for GitHub, Linear, and Slack, and followed up with the beta launch earlier this month. Today, Jira, GitLab and incident.io join the intake lineup. Watch our recent workshop Build and Own Your Software Factory to learn more. Every intake provider ships as part of the @mastra/factory package: Requires @mastra/factory@0.16.0

    匹配字段正文

  5. 量子位精选

    OpenAI DevDay 发布 25 项更新:常驻智能体 Dots 与 GPT-6.1 Sol 上线

    OpenAI 在被称为历届规模最大的 DevDay 上发布 25 项更新,核心包括常驻型智能体 Dots、新模型 GPT-6.1 Sol、Codex 云端化与 Agents API 扩展。Dots 可长期保留上下文、主动汇报并调用浏览器和应用,目前向 Pro 和 Business Premium 用户开放,后台主动工作时默认只能使用只读工具。GPT-6.1 Sol 官方称能力接近 GPT-6 Astra,标准 API 价格为每百万 Token 输入 2 美元、缓存输入 0.1 美元、输出 10 美元,仅为 Astra 的五分之一;同时新增每月 500 美元的 Pro 500 套餐和 Ultrafast 速度档位。

    dex命令行工具还新增了/agents界面。 一个任务可以拆给多个Agent并行处理,用户在一个界面里查看进度和结果。 代码评审也成了正式功能。 用户可以在ChatGPT桌面端查看代码改动和差异,让Codex排查问题;开启自动评审后,Codex还能在云端先完成一轮检查。 安全方面, OpenAI推出Codex Security Cloud,可以按需或定期扫描GitHub代码仓库,持续检查新增提交,发现风险后进一步核查并生成修复方案。 到这里,Codex已经从“帮你写代码”,扩展到云端执行、多Agent协作、代码评审和安全扫描。 下一步,OpenAI还准备 把上述的Codex能力开放给外部开发者 。 Codex的Agent能力开始塞进API Agents API这边也值得关注。 这次OpenAI 给API加入了Computer Use ,开发者可以通过API构建能操作软件界面的Agent,让AI自己看界面、点击、输入并完成任务。 同时,Codex里的几项核心能力也被搬进Agents API,包括multi-agent、tool search、tool calling和context co

    匹配字段正文

  6. AWS Machine Learning

    Amazon Quick 各组件提示词工程:模式与陷阱

    AWS 发文按组件拆解 Amazon Quick 的提示词工程实践,覆盖 Quick Research、Quick Flows 和 Quick Sight。Quick Research 可接入 Quick Index 企业数据、200+ 家新闻源以及 S&P Global、FactSet、IDC、美国专利数据和 PubMed 等付费数据集,提示词需明确目标、受众与范围;Quick Flows 支持条件分支、循环和用户输入,复杂逻辑宜写成编号步骤;Quick Sight 查询需包含业务问题、指标、维度、时间范围与可视化类型。

    uick developer docs cover prompt configuration, flow authoring, and agent setup in detail; Clone the sample code — The aws-samples/sample-quicksuite-kiro-quickstarts repository on GitHub includes Quick API scripts and templates you can use as starting points About the authors Daiquan N’kere Daiquan is a Technical Account Manager and AI/ML Business Applications Specialist at AWS, where he partners with enterprise customers to architect cloud solutions and accelerate their digital transformation j

    匹配字段正文

  7. AWS Machine Learning

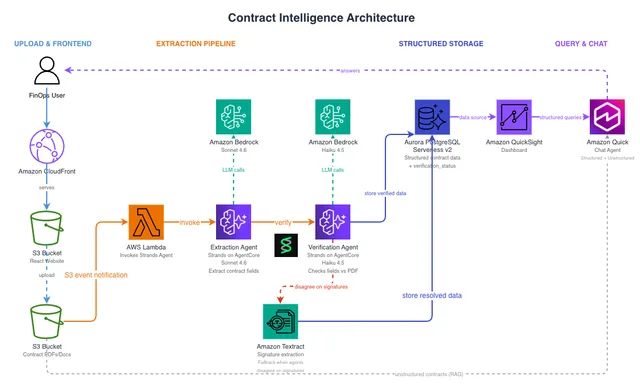
    用 Amazon Quick 和 Amazon Bedrock AgentCore 构建 AI 合同智能平台

    AWS 分享了一套合同智能平台架构:用 AI 智能体从合同 PDF 中提取 8 个关键字段,再由独立的验证智能体复核,签名识别分歧时由 Amazon Textract 做确定性裁决,结果存入 Amazon Aurora PostgreSQL。该方案针对 RAG 语义检索无法回答跨全部合同的聚合问题,改用结构化提取加数据库查询,并通过嵌入式仪表盘和自然语言聊天智能体提供答案。

    Contract intelligence pipeline from Amazon S3 ingestion through AI extraction and verification to Amazon Quick querying

    g. This keeps people in the loop exactly where judgment matters most. Amazon Bedrock AgentCore documentation — for deploying and managing AI agents at scale; Strands Agents SDK on GitHub — for building multi-model agent workflows; Amazon Quick Sight Embedding SDK — for integrating dashboards and natural language querying into your applications; Amazon Textract HumanLoopConfig documentation — for document analysis and signature detection; Amazon Quick Human-in-the-loop task center — for adding hu

    匹配字段正文

星期二

  1. Simon Willison

    OpenAI DevDay 2026 现场实录:发布 Dots 个人智能体、GPT-6.1 Sol 与 Ultrafast

    OpenAI 在 DevDay 2026 主题演讲中发布名为 Dots 的个人智能体,由 Astra 驱动,ChatGPT Pro 和 Enterprise 用户当天可用,并推出团队协作的 ChatGPT Space。同时发布 GPT-6.1 Sol,官方称以五分之一价格提供接近 Astra 的智能水平,以及最高 300 tokens/秒、8 倍速的 Ultrafast 模式,标准价格为 6 倍。开发者侧还推出 Decisions API 预览、Codex 云端与开源 Codex harness、Codex Security Cloud、Sign in with ChatGPT、ChatGPT 插件与 OpenAI Marketplace,Sam Altman 称每周有 1.2B 人使用 ChatGPT。

    o comment on the style of music. 15:22 They finished by asking Marin to generate some images. 15:26 Here's Getting started with GPT-Live and the openai-live-console starter app on GitHub. 15:37 The last session of the day is the closing Q&A with Sam Altman and Thibault Sottiaux. Thibault is product lead on Codex, ChatGPT, ChatGPT Work, and the API - promoted a few months ago after successfully leading Codex. 15:38 That kicks off at 4pm, in about 20 minutes. 16:00 (As an aside, there are some exc

    匹配字段正文

  2. Hugging Face

    NVIDIA 发布开源表格基础模型 Kumo Tabular

    NVIDIA 发布开源表格分类与回归基础模型 Kumo Tabular,基于 Transformer 的列、行与上下文注意力,读取带标签的表格后单次前向即可输出类别概率或数值预测。模型完全在人工合成表格上预训练,Small/Medium/Large 三档分别见过约 3500 万、7100 万、1.37 亿张表。官方称其在 TabArena 榜单以 ELO 1950 排名第一,在统一单张 RTX 6000 Pro 环境下比 LimiX-2 快 17 倍,并在 BeyondArena、TALENT、ScoringBench 上取得领先排名。模型仅支持数值与类别列,单次前向最多覆盖 10 个类别,训练配方与合成数据生成器将随后发布。

    o text: a model pretrained on millions of tables can read a labeled table as its context and predict the labels of new rows directly. Today, we are releasing NVIDIA Kumo Tabular ( GitHub , HuggingFace ), an open foundation model for tabular classification and regression. Given a table with labeled rows and the rows you want predictions for, Kumo Tabular returns class probabilities or numeric predictions in a single forward pass. How Kumo Tabular Works Kumo Tabular is a Transformer built around t

    匹配字段正文

  3. MarkTechPost

    Google Research 开源 RRSI:让 AI 智能体改进自身 harness 而不过拟合

    Google Cloud AI Research 联合 UNC-Chapel Hill、斯坦福和圣路易斯华盛顿大学发布 RRSI(Regularized Recursive Self-Improvement),让 LLM 智能体重写自己的 harness,包括提示词、工具、记忆、控制流和子智能体,模型权重不变。RRSI 对改进循环本身施加约束,以缓解基准特定拟合、追逐噪声和复杂度累积三种失败模式,全部 6 个留出集均有提升:以 Gemini 3.5 Flash 为策略时,Terminal-Bench 2.1 从 64.6 升至 78.7,SWE-bench Verified 从 76.8 升至 79.0。代码以 Apache 2.0 开源,需 Python 3.10+,支持任意 LiteLLM 模型字符串,默认使用 Vertex AI 上的 Claude Opus 4.8。

    computed from Table 1 . Meta-Harness leads on the Harvey LAB evolve split. RRSI has the smallest evolve gain but the only OOD average more than 1 point above H0. git clone https://github.com/google-research/rrsi.git && cd rrsi pip install -e ".[dev]" python3 rrsi.py --domain coding baseline python3 rrsi.py --domain coding run Each round drafts 2 candidates in separate git worktrees, screens them, evaluates both and fast-forwards the branch to the winner. The coding instance also needs Docker and

    匹配字段正文

  4. gihyo.jp

    NVIDIA 发布 Open Agent Safety Platform

    NVIDIA 于 9 月 28 日发布 Open Agent Safety Platform,由在隔离沙箱中控制文件、网络与进程访问的 OpenShell,以及运行在 BlueField-4 DPU 上、独立于主机软件进行监控与毫秒级隔离的 Sentry 组成。OpenShell 以 Apache License 2.0 开源,已发布 0.1.0 版本,可在本地、本地部署、云和 Kubernetes 环境使用,官方指南给出用 Docker 运行 OpenCode 并经 OpenRouter 调用模型的示例。NVIDIA 称参与该平台技术开发与使用的企业及组织超过 100 家,包括 Anthropic、Microsoft、Hugging Face、CrowdStrike、SAP,Canonical、SUSE、Red Hat 也在推进将其集成到操作系统与 AI 基础设施。

    netes基盤で利用できる。既存のエージェントを動かせるほか、エージェントや必要なツールを組み込んだ独自のイメージも使える。 インストールしてOpenCodeを動かす例 公式の初回起動ガイドでは、コーディングエージェントのOpenCodeと、モデルAPIサービスのOpenRouterを使う例を紹介している。ほかにも、Piを動かす例やClaude CodeからGitHubへの書き込みを許可する例が公開されている。 ここでは、OpenCodeの例に沿って、導入から応答の確認までを示す。OpenCodeはローカルのサンドボックス内で動かし、AIモデルはOpenRouter経由で利用する。 この例では実行基盤にDockerを使う。LinuxにDocker Engine 28.0以降を導入・起動した環境と、OpenRouterのアカウント・APIキーを用意する。以下のコマンドは、サンドボックスを動かすLinuxホストのBashで順に実行する。サンドボックスのコンテナはOpenShellが作成・起動する。 まず、OpenShellのインストールスクリプトを実行すると、CLIやポリシーの検証ツールが

    匹配字段正文

  5. Latent Space

    AMD 以 82 亿美元收购 World Labs

    AMD 以 82 亿美元收购 World Labs。World Labs 创始人李飞飞在博客中称,公司自 2024 年成立以来构建了图像、视频与空间重建的模型训练团队,并在收购 SceniX 后推进机器人仿真能力。其近期发布的 Atlas 是面向空间智能的 omni 模型架构,通过结合生成模型与多视图几何解决新相机视角预测问题,并称已解决计算机视觉中长期存在的稀疏重建问题。

    a session moves to another account, Claude rereads it and regenerates thinking. Roadmap: @mikeyk said Haiku 5.5 will “round out the family in the coming weeks.” Availability: It shipped day-one on the Claude Platform and Claude Code, along with a usage reset valid until Oct 22 ( @ClaudeDevs ). Third-party availability: GitHub Copilot in VS Code ( @code ) Arena Agent/Battle modes for WebDev, Text, Vision and Document ( @arena ) T3 Code, after @theo admitted it hadn’t been added to the catalog yet

    匹配字段正文

  6. Latent Space

    Anthropic 的 Thariq 谈 Claude Code 下一阶段:Claude Mods、Projects 与智能体安全

    Anthropic 的 Thariq Shihipar 在 Latent Space 播客中介绍 Claude Code 的下一阶段,包括可自定义 harness 的 Claude Mods、Projects、Claude Tag 以及 Opus 5.5 和 Sonnet 5.5 等近期发布。他把提示词称为使用 Claude Code 的核心技能,建议先花时间补足上下文,并按任务分配 effort,例如代码审查和安全用高或最高,UI 类任务用低或中。他还谈到智能体安全,包括沙箱、提示词注入、Auto Mode 以及 Anthropic 的 Pacing the Frontier 主张。

    Sol Ultra 发布之际,人们正争相在 之前寻找 Fable 5 的极限,请特别关注 Claude Mods(尤其是 cheatsheet): Boris Cherny @bcherny Claude Mods 正在陆续上线。已经有人构建了一个 Claude 内运行的俄罗斯方块 mod 🤯 查看 issue 了解最新的社区更新、技术细节和更多酷炫演示 github.com/anthropics/cla… 下午5:30 · 2026年9月14日 · 60.3万次查看 312条回复 · 173次转发 · 2.72万次点赞 总的来说,这也是 Thariq 另一条病毒式传播推文的反面: Thariq @trq212 奇怪的是,有一个“赚大钱”的按钮,却没人按 (把你的 SaaS 变成无头模式,让智能体使用它,按交互收费,尤其是对企业) 下午10:39 · 2026年8月18日 · 55.9万次查看 333条回复 · 229次转发 · 6570次点赞 云端大脑,本地之手 并且试试 Claude Projects: Boris Cherny @bcherny Projects 不仅改变了我与

    匹配字段正文

  7. Inception Labs Blog

    Inception 发布 Mercury 2,面向搜索流水线每步延迟最快

    Inception Labs 发布 Mercury 2,称其在标准 NVIDIA GPU 上解码速度超过 1000 tokens/秒,在 WideSearch 基准的搜索流水线每一步都最快,查询规划比 Gemini 3.1 Flash Lite 快近 2 倍、比 Claude Haiku 4.5 快 4.7 倍、比 GPT-5 Mini 快 10 倍。定价为 $0.25/M 输入、$0.75/M 输出,作者称更深的流水线运行成本约为前沿速度优化模型的 2 倍便宜。在 FRAMES 上四款模型得分接近,DeepSearchQA 上 GPT-5 Mini 以 0.44 高于 Mercury 2 的 0.34,但 Mercury 2 完成 FRAMES 查询耗时 10.8 秒、单次正确回答成本最低。作者还发现 WideSearch 任务可被模型凭记忆作答,重建为训练截止后事件的任务后,Gemini 得 0.929、Mercury 2 得 0.923。API 已在 platform.inceptionlabs.ai 上线。

    h benchmark, 100 English tasks, live Exa retrieval. Latency medians over 336–493 calls per model, each on its own provider's public API. Harness and per-call timing are public at: github.com/apoorvumang/retrieval-vs-recall Mercury 2 is the fastest model at every step of the pipeline, almost 2x faster than Gemini 3.1 Flash Lite on query planning, 4.7x faster than Claude Haiku 4.5, 10x faster than GPT-5 Mini. That per-step gap is where the end-to-end numbers in the next section come from: a pipeli

    匹配字段正文

  8. Inception Labs Blog

    Inception 公布 Mercury 2 在 PinchBench 上的评测结果

    Inception Labs 公布 Mercury 2 在 PinchBench 上的评测结果:任务成功率 78%,高于 GPT-5 Mini 的 75%、Gemini 2.5 Flash 的 71%、DeepSeek Chat 的 72% 和 GPT-4o 的 71%,并在同准确率档位中执行时间最快。定价为每 100 万 token 输入 0.25 美元、输出 0.75 美元,约为 Claude 4.5 Haiku 输入输出的四分之一。PinchBench 基于 OpenClaw 构建,考察工具调用、多步推理和真实任务完成情况,Mercury 2 的速度来自并行细化而非逐 token 生成。

    of these. Mercury 2 optimizes for all three. We evaluated Mercury 2 on PinchBench, the open-source benchmark built on top of OpenClaw — the fastest-growing open-source project in GitHub history, with 250K+ stars in under 60 days. Here's what we found. The result Mercury 2 sits in the upper-left of the chart: high task success rate and the fastest execution time in its performance class. 78% success rate — matching or exceeding GPT-5 Mini (75%), Gemini 2.5 Flash (71%), DeepSeek Chat (72%), and G

    匹配字段正文

  9. Inception Labs Blog

    Inception Labs 更新 Mercury 系列扩散 LLM 产品线

    Inception Labs 在其产品博客集中列出 Mercury 系列扩散 LLM 的进展:Mercury 2 面向搜索场景,可在既有延迟预算内为每次查询执行五十到一百次 LLM 调用;Mercury 2 用于语音智能体时 TTFT 低于 300 ms,并已上线 Azure AI Foundry。Mercury 2.5 被称为市面上能力最强的扩散 LLM,运行速度 1,107 tokens/sec,智能水平较 Mercury 2 提升 40%。此外,Mercury 2 新 API key 可获 100M 免费 tokens,速率限制提升 10 倍。

    of your coding workflow Mar 30, 2026 Product We evaluated Mercury 2 on PinchBench, the open-source benchmark built on top of OpenClaw — the fastest-growing open-source project in GitHub history, with 250K+ stars in under 60 days. Mar 24, 2026 Product We evaluated Mercury 2 on PinchBench, the open-source benchmark built on top of OpenClaw — the fastest-growing open-source project in GitHub history, with 250K+ stars in under 60 days. Today, we're introducing Mercury 2 — the world's fastest reason

    匹配字段正文

  10. SemiAnalysis

    GLM-5.3 解析:稀疏注意力如何影响 DRAM 内存 TAM

    SemiAnalysis 分析 Z.ai 的 GLM-5.3 系列:稀疏注意力通过 top-k 选择降低 SDPA 阶段的 KV cache 内存与带宽需求,但 top-k 选择仍需完整上下文驻留 HBM,因此并未消除内存容量瓶颈。SGLang 团队的 HiSparse 将 KV cache 从 HBM 卸载到主机 DRAM,按 LRU 策略换入换出,并把第 N 层加载与第 N-1 层执行重叠以降低 miss 延迟。在 InferenceX 基准中,150 tokens/s 下 GB200 约 $0.044/百万总 token,比 MI355X ATOM 的 $0.049 低约 12%。

    Infrastructure Z.ai uses slime, one of the best open-source RL training frameworks, as the post-training infrastructure throughout all GLM-5 models. We refer readers to the slime GitHub repo to learn more about its design and features, and here we highlight two features. Performance characteristics of RL rollouts are highly task-dependent, and each task comes with different tools and reward functions. To ensure system efficiency, Z.ai designed a server-based multi-task rollout orchestrator. Eac

    匹配字段正文

  11. AWS Machine Learning

    Claude Sonnet 5.5 在 Amazon Bedrock 上线

    AWS 宣布 Claude Sonnet 5.5 在 Amazon Bedrock 和 Claude Platform on AWS 上线,定位为面向编码与知识工作的更高效 Sonnet 模型,多数任务单任务成本更低、速度更快。该模型适合持续或规模化负载,例如告警首次响应、智能体持续监控、SQL 生成、UI/UX 测试和 IDE 内编码智能体;需要判断力的工作如发布调试、多 PR 功能栈、大型 PR 安全审查则交给 Opus 5.5。用户可在 Bedrock 控制台 Playground 选择 Sonnet 5.5,或通过 Anthropic SDK、AWS CLI 和 AWS SDK 调用,目前通过 bedrock-runtime 的 Global CRIS 推理配置文件提供。

    through Claude Platform on AWS in North America. Give Claude Sonnet 5.5 a try in the Amazon Bedrock console, in Claude Platform on AWS, or explore the Getting Started notebooks on GitHub. About the authors Dani Mitchell Dani is a Senior Specialist Solutions Architect for Generative AI at AWS, working on go-to-market for Anthropic on Amazon Bedrock. He helps enterprises across the world design and deploy generative AI solutions using Anthropic’s models and capabilities on Amazon Bedrock to build

    匹配字段正文

  12. AWS Machine Learning

    在 SageMaker AI 上用 vLLM-Omni 构建实时语音应用(上)

    AWS 发布教程,演示如何用 vLLM-Omni Deep Learning Container 在 Amazon SageMaker AI 上部署 Qwen3-TTS,通过 SageMaker 双向流式连接实现文本流入、24 kHz PCM 音频分块流出,并配套 Gradio 应用。该 DLC 基于 vLLM-Omni v1.5,新增 SageMaker AI 所需的双向流式能力标签与路由中间件,示例使用 v1/audio/speech/stream 原生 WebSocket 路由。

    个包含的类型提供可用配额。如果 SageMaker 选择了不同的实例,您的每小时成本也可能发生变化。使用 --instance-types 将池限制为满足您配额、价格和性能要求的类型。 开始之前,您需要: 本演练使用美国东部(弗吉尼亚北部)区域。示例会根据 AWS REGION 构建 DLC 镜像 URI 和运行时端点。 git clone https://github.com/aws-samples/sagemaker-genai-hosting-examples.git cd sagemaker-genai-hosting-examples/03-features/bidirectional-streaming-vLLM-Omni 安装所需的 Python 包。创建虚拟环境并安装示例定义的版本。 python3.12 -m venv .venv source .venv/bin/activate python -m pip install -r requirements.txt 配置示例。设置您的 SageMaker AI 执行角色。示例默认使用 us-east-1。传入 --re

    匹配字段正文

  13. AWS Machine Learning

    在 SageMaker AI 上用 vLLM-Omni 生成图像与视频(第二部分)

    在 Amazon SageMaker AI 上,用同一个 AWS vLLM-Omni DLC 镜像部署两个端点:实时端点跑 FLUX.2-klein-4B 生成图像,异步端点跑 Wan2.1-VACE-1.3B 做图像条件视频生成。文本提示词先生成 PNG,再连同运动提示词送入视频端点,生成的 MP4 从 Amazon S3 取回,示例还提供命令行流程和可选的 Streamlit 界面。

    geMaker 容量感知实例池可以按优先级顺序列出兼容的实例类型。只有在验证每个候选类型满足图像模型的 GPU 内存和性能要求后,才添加实例池。本示例将异步视频端点保持在固定实例类型上。 开始之前,你需要: 本演练使用美国东部(弗吉尼亚北部)AWS 区域。在部署 GPU 端点之前,请查看 SageMaker AI 定价。 git clone https://github.com/aws-samples/sagemaker-genai-hosting-examples.git cd sagemaker-genai-hosting-examples/03-features/vllm-omni-image-video 安装 Python 依赖项。创建虚拟环境并安装示例要求。 python -m venv .venv source .venv/bin/activate python -m pip install -r requirements.txt 部署图像和视频端点。设置您的 SageMaker AI 执行角色并运行部署脚本。该脚本固定 omni-sagemaker-cuda-v1.6,创

    匹配字段正文