←搜索结果

按匹配度 · 共 3412 条结果 清除搜索

星期二

  1. Anthropic:Transformer Circuits

    HeadVis:用于研究注意力头的交互式工具

    Anthropic 推出 HeadVis,一个用于研究大语言模型注意力头的交互式可视化工具,并开源了代码。该工具通过注意力模式可视化、分布指标、低秩分量投影以及经 QK/OV 电路的 SAE 特征归因来生成和检验关于注意力头功能的假设。作者用 HeadVis 分析了 Claude Haiku 3.5 的注意力头,并提供了 Gemma 3 及 Haiku 3.5 部分注意力头的演示。

    table, so this provides a simple way to find interesting heads quickly. We can find induction heads by using a proxy metric called the induction scoreThe induction score is the average attention pattern of a head on (query, key) token pairs that correspond to the literal copying case of induction. In a sequence that looks like [A][B]…[A]- [B], an induction head would attend from the second A to the first B. This is the same as the prefix score from , except the prefix score was on a synthetic da

    匹配字段正文
  2. Anthropic:Transformer Circuits

    Anthropic 提出自然语言自编码器 NLA,无监督解释 LLM 激活

    Anthropic 提出自然语言自编码器(NLA),由激活语言化器(AV)与激活重建器(AR)两个 LLM 模块组成,用强化学习联合训练以重建残差流激活,从而生成可读的自然语言解释。在 Claude Opus 4.6 的部署前审计中,NLA 帮助诊断安全相关行为并发现模型未说出口的评估意识;在自动化审计基准上,配备 NLA 的智能体优于基线,且无需访问被错位模型的训练数据。Anthropic 同时发布了训练代码和面向主流开源模型的已训练 NLA。

    we are limited to expressing interpretations as a weighted sum of atoms from a fixed vocabulary (tokens or dictionary features). Moreover, SAE features can have unpredictable coverage gaps , and require a sometimes-difficult interpretative step, either by a human or a model analyzing top-activating examples . Natural language explanations of activations. By contrast, some recent work trains language models to describe activations in free text. Off-the-shelf models have some capacity for this: L

    匹配字段正文

  3. Anthropic:Transformer Circuits

    Anthropic 可解释性团队 2026 年 5 月 Circuits 研究进展

    Anthropic 可解释性团队发布 2026 年 5 月 Circuits 更新,提出用 TWERA 排序的下游特征来区分外观相似但因果作用不同的特征。在“草是什么颜色”示例中,两个绿色特征只有 Feature B 被抑制后才会把答案从 Green 改为 Red,而 Feature A 实际关联十六进制颜色编码。团队用 Opus 4.7 对 10 组候选特征排序,验证加入 TWERA 下游特征能否提升识别真正起因果作用特征的准确率。

    + TWERA-ranked downstream features; Top activating examples + top unembeds + TWERA-ranked downstream features For each group, we asked Opus to rank candidates multiple times to average across different orders of the features within each group. Specifically, we put the correct answer in each location twice, so the total number of samples was equal to 2× the number of features. We measure the average normalized rank of the correct feature as (predicted rank − 1) / (num candidates − 1). Lower is be

    匹配字段正文

  4. Anthropic:Transformer Circuits精选

    Anthropic 论文:语言模型中的可言语化表征构成全局工作区

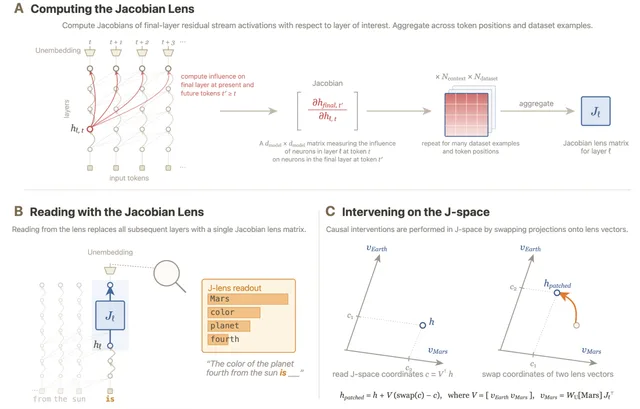
    Anthropic 在 Transformer Circuits 发布论文,提出 Jacobian lens(J-lens)可解释性方法,用于识别语言模型中可被言语化的内部表征,并将这些表征的集合称为 J-space。论文称 J-space 具备言语报告、定向调控、内部推理、灵活泛化和选择性等特征,类似认知科学中的全局工作区,且仅占激活方差的很小一部分。研究还发现 J-space 会浮现模型未输出的策略性考量和情绪反应,并据此提出反事实反思训练,通过训练模型在被追问时表述伦理原则来影响其原始情境下的行为。

    he Jacobian lens identifies a vector representation that encodes the potential for the model to verbalize that token in the future. Concretely, it computes, for each layer, the average linearized effect of an activation on the model's likelihood of producing a particular token (now or in the future), averaging over a large corpus of contexts (see Methods for details). The averaging step is key, as it distinguishes representations that are verbalizable—poised to be spoken about, should the occasi

    匹配字段正文

  5. Anthropic:Transformer Circuits

    Anthropic 在单层 Transformer 中刻画干扰权重

    Anthropic 训练了一个单层 Transformer,将其分解为 token、位置、特征与 logits 之间的虚拟权重,并沿“有效性”和“有益性”两个维度打分,首次在训练好的 Transformer 内部通过测量对训练损失的影响,实证了干扰权重的存在。研究发现有益与有害权重散布在整个虚拟权重幅度范围内,剪掉有效性最低的 70% 权重仅使损失上升 0.01 nats,剪掉 85% 上升 0.1。最有效的权重绝大多数是有益的,其有效性比任何有害权重高出一个数量级。

    The most natural global components of a network are its weights; they describe the direct effect of each unit on another in every context in which they appear. However, models leverage superposition in maximizing their capacity to represent different circuits , and this presents two primary challenges to directly reading the weights. First, the basis of neurons is polysemantic : each neuron activation contributes to multiple features of the computation and they do so in a context-dependent fashi

    匹配字段正文

  6. LG AI Research 官方博客

    LG AI Research 在 ICML 2026 提出 GEAR 与 Sim-GEAR:用黎曼几何解决科学数据稀缺

    LG AI Research 在 ICML 2026 提出 GEAR 与 Sim-GEAR,用黎曼几何连接数据充足与数据稀缺的物性预测模型潜空间,通过计算曲率并让两个空间的几何结构趋于相似来改进迁移学习。该方法针对材料研发中部分物性仅有数十条数据、而另一些可达上亿条的数据失衡问题。

    고성문님_수정_0e0f2a9d1.jpg

    transferring knowledge learned from data-rich physical properties to data-scarce ones. While GEAR demonstrated the potential of a new form of geometric transfer learning that leverages curvature, Sim-GEAR built on this by developing it into a simpler and more efficient form. At the conference, in addition to research presentations, there were lively discussions on how to apply AI to materials development, the imbalance in scientific data, and the process of translating AI predictions into actua

    匹配字段正文

  7. MIT News · Artificial Intelligence

    MIT 媒体艺术与科学教授 Deb Roy:AI 生成文本需要问责与可追责性

    MIT 媒体艺术与科学教授、MIT 建设性传播中心(CCC)主任 Deb Roy 在《原子科学家公报》发表题为“Who stands behind the words?”的文章,呼吁在 AI 参与公民对话时重建问责与“可追责性”。他以 2017 年 FCC 收到超 2200 万条网络中立性公众评论、其中近 1800 万条被纽约州总检察长认定为造假为例,指出大语言模型抹去了模板化文本等造假痕迹,使公众评论这一民主渠道的可信度受损。

    h nothing to lose. Q: The Bulletin piece has these interesting examples of civic feedback forums where it looks like there are real people saying things, and instead you have a barrage of comments from AI. How did you find some of these other examples in society where things go off the rails in this way? A: After the release of ChatGPT, I started hearing a concern from people inside government who review public comments on proposed rules: a suspicion that not all of the comments were written by

    匹配字段正文

  8. The Decoder

    微软研究:清空对话历史可让 AI 智能体找到更好方案

    微软研究院发现,长时运行的自动研究智能体即便增加算力也会陷入“想法盆地”,同一任务八次独立运行的最终得分在 68.3 到 100.0 之间。其提出的 Fork-and-Flush 方法让智能体分成 K 个并行分支并清空各自对话上下文、只保留工作区,在同等算力预算下取得 0.78 的归一化平均分,高于单次运行的 0.47 和 best-of-4 的 0.54,相对提升分别为 66.0% 和 44.4%。该方法在 13 个长时任务中的 12 个取得最高平均分,归一化标准差从 0.26 降至 0.16,仅清空上下文而不分支也能带来 22% 的提升。

    Fresh context restores diversity in the search. The conversation history is lost, but the code, files, and saved results remain in the workspace. A 66 percent higher normalized average score on the same compute budget The researchers tested Fork-and-Flush on 13 long-running tasks , including polyomino packing, job-shop scheduling, and cryptanalysis. The tasks also included compressing a CIFAR classifier and optimizing a VLIW kernel. Individual runs lasted from several hours to over 100 hours. Th

    匹配字段正文

  9. The Decoder

    Sakana AI 与 UC Berkeley 提出 MASS 自改进方法,模型可自我评判但存在共享盲点

    Sakana AI 与 UC Berkeley 研究人员提出 Multi-Agent Self-Supervision(MASS)递归自改进方法,让同一个语言模型同时承担解题、优化工作流和评估结果三种角色,无需更强的教师模型。测试任务上对基座模型的胜率从一轮后的 53.9% 升至两轮后的 69.9%,自评估器与外部评判的一致率从 73% 升至 93%。研究同时指出共享盲点可能成为递归自改进的隐患,模型若在三种角色中漏掉同一错误,该错误可能被当作改进固化进下一轮训练,作者因此呼吁引入独立检查与自主性限制。基座模型为 Qwen3.6-27B,代码已公开。

    ile scores drop slightly on Terminal-Bench 2.0 and SWE-bench Verified. The paper's appendix shows that completed MLR-Bench submissions rise from 31 to 50 out of 60, while their average grade falls from 3.07 to 2.88. The delegation tool goes unused in all 180 runs, leaving it unclear whether teamwork explains the gains. Those gains are no longer statistically significant when results are compared task by task. The authors describe mixed results across research tasks, with AstaBench showing the sa

    匹配字段正文

  10. TensorZero 工程博客

    TensorZero:把 LLM 应用看作 POMDP,而非 Agent

    TensorZero 提出应将 LLM 应用建模为部分可观测马尔可夫决策过程(POMDP),而非笼统的 Agent。其核心主张是应用与 LLM 的接口应是应用变量间的函数 f:X→Y,而非提示词与生成结果之间的函数,并据此构建了涵盖推理、可观测性、优化、评估与实验的系统,已开源生产级子集。

    Diagram: LLM Functions

    the assumption that a function call corresponds to a single LLM call — so long as you respect the interface of f:X→Yf: \mathbb{X} \to \mathbb{Y}f:X→Y — enabling the ability to leverage complex inference-time optimizations (like the OpenAI o1 family of models). After you’ve used one or more of these techniques to generate a new policy, you’ll want to use historical data to backtest and find out if it’s good or not. These are evals, but have been studied for decades under the name offline policy e

    匹配字段正文

  11. TensorZero 工程博客

    案例研究:欧洲大型银行用 TensorZero 与 LLM 自动生成 GitLab 代码变更日志

    一家欧洲大型银行用 TensorZero 构建了基于 LLM 的 GitLab merge request 变更日志生成器,并通过 Ollama 实现完全自托管部署,数据不出内网。团队借助 TensorZero 的动态上下文学习(DICL)从工程师的修改与审批中持续优化输出,无需微调或标注数据集,也无需 ML 工程师即可上线生产级系统。

    Diagram: Workflow

    engineers edited and approved the AI-generated changelogs, those human revisions were automatically used by TensorZero to optimize future inference requests. Mark and his team leveraged TensorZero’s built-in dynamic in-context learning feature to make the system get smarter over time — without fine-tuning, labeling datasets, or writing complex pipelines. It was a human-in-the-loop learning flywheel, out of the box. Dynamic In-Context Learning (DICL) is an inference-time optimization strategy tha

    匹配字段正文

  12. TensorZero 工程博客

    从 NER 到智能体:自动提示词工程能否扩展到复杂任务?

    TensorZero 工程博客测试了 MIPRO 自动提示词优化在从 NER(CoNLL++)、多跳检索(HoVer)到 BabyAI 游戏导航和 τ-bench 智能体工具调用等任务上的表现。在 NER 任务中,MIPRO 相比 Zero-shot 和随机示例基线分别取得 140.1% 和 43.4% 的相对提升,但在 HoVer 多跳检索任务中未观察到显著差异。博客指出,任务越复杂,MIPRO 的收益越有限,大模型在复杂场景中受益更多,反馈质量也直接影响优化效果。

    n for each environment at a given bin corresponds to the height of its colored segment. The increase in prompt length is primarily due to the demonstrations: either because the average number of turns in a successful episode increases (BabyAI PickUpSeqGoTo) or because environment observations and agent actions are more verbose (HoVer and τ-bench Retail). This observation motivates our experimentation with a larger model (GPT-4o instead of GPT-4o Mini) with larger context capacity for the τ-bench

    匹配字段正文

  13. TensorZero 工程博客

    TensorZero 如何用每次 Git 提交自动评估 AI 编码助手

    TensorZero 工程博客介绍了一套自动评估 AI 编码助手的方法:用 tree-sitter 把 LLM 生成的代码片段和 Git 提交中的新增代码解析成语法树,再用树编辑距离(TED)计算两者的最小差异,归一化后得到 0 到 1 的奖励值,作为反馈写回 TensorZero。该流程以 Rust 二进制实现,可作为 post-commit git hook 在每次提交后自动运行,并通过 rayon 并行计算。作者称其 CTO Viraj 的个人使用数据显示 GPT-4.1 的效果不如 Claude 3.7 Sonnet、Gemini 2.5 Pro 和 o4-mini,但强调这只是初步结果,不主张某个模型普遍更优。

    Diagram: CursorZero with Feedback Loop

    m exhaustively evaluates every candidate subtree to guarantee the closest match. Each distance is normalized by the size of the LLM snippet, yielding a ratio in [0, 1]. We then average these ratios across all snippets in the inference, and compute the reward is then computed as 1 - average ratio. A perfect match receives a score of 1, while lower scores indicate poorer performance. Formally, say that an LLM inference outputs nnn code snippets with corresponding concrete syntax trees I={t1,…,tn}I

    匹配字段正文

  14. TensorZero 工程博客

    TensorZero 实测 OpenAI RFT:成本是 SFT 的 100-700 倍,值不值?

    TensorZero 在数据抽取、智能体编码和客服三个任务上对比了 OpenAI 的 RFT 与 SFT,RFT 成本是同等数据量 SFT 的 100-700 倍。RFT 仅在智能体编码任务上明显优于 SFT,数据抽取上更大数据集的 SFT 效果更好且成本低 159 倍,客服任务上 RFT 反而比基线更差。作者还指出 RFT 会触发比 SFT 更严格的内容审核,导致部分公开基准数据集无法通过验证。

    Fine-Tuning for o4-mini on terminal-benchThe script below demonstrates how to fine-tune o4-mini on terminal-bench using TensorZero’s programmatic API; Deploy with confidence: Leverage the experimentation features to gradually route traffic to your fine-tuned models, starting with a small allocation and scaling based on performance metrics So, is reinforcement fine-tuning worth it? For most use cases, not yet. At 100-700x the cost of supervised fine-tuning, we only observed RFT to deliver clear

    匹配字段正文

  15. TensorZero 工程博客

    TensorZero 在 LLM 网关中引入多臂老虎机自适应实验

    TensorZero 在其开源 LLM 网关中提供自适应实验(A/B 测试),用多臂老虎机算法替代传统固定时长或反复检验显著性的做法,在证据足够时动态停止并动态分配推理流量。在多种真实环境中,该方法将正确识别最佳 LLM 变体(提示词、模型等)的平均时间较简单 A/B 测试缩短 37%。

    Multi-armed Bandit Schematic

    while dynamically allocating LLM inference traffic for maximum efficiency; Across a diverse set of realistic and challenging environments, adaptive experimentation reduced the average time to correctly identify the best LLM variants (prompts, models, etc.) by 37% compared to simple A/B testing Developing LLM applications involves numerous design decisions: which model to use, how to structure prompts, what temperature and sampling parameters to set, etc. While offline evaluations and synthetic

    匹配字段正文

  16. TensorZero 工程博客

    TensorZero:即使(非常)嘈杂的 LLM 评估器也能用于改进 AI 智能体

    TensorZero 工程博客指出,LLM 评估器虽常与真实结果弱相关,但输出级相关性低只影响护栏等单条输出决策,智能体级相关性会随样本量增大而收敛。因此即使 σ=0.25 的极嘈杂评估器,在 N=30 条轨迹下仍能正确判断哪个智能体平均更优,可用于离线选择最佳提示词或模型变体。

    ted value for production decisions that hinge on judging a single output (e.g. guardrails); However, even (very) noisy evaluators can reliably tell you which agent is better on average, meaning they can still help you pick the best variant to deploy and improve it over time It’s surprisingly hard to develop reliable LLM evaluators: they’re often noisy and poorly correlated with the metrics or outcomes practitioners actually care about. Sometimes the target is directly measurable but evaluators s

    匹配字段正文

  17. n8n Blog

    用 You.com、Jev 和 n8n 构建每日 AI 新闻简报

    n8n 博客发布了一个工作流模板:每个工作日 8 点用 You.com 搜索当日 AI 新闻,再由 TypeSafe AI 的首个 System One 模型 Jev 对每篇文章按约 $0.00004 的成本打分,筛选出真正有实质进展的内容。通过筛选的文章交给 You.com Research 生成带引用的分主题简报并发布到 Slack,整个早晨的成本在 1 到 4 美分之间;某主题当天没有实质新闻时则不发帖。

    e entire reason this workflow can filter at all, rather than summarizing everything and calling it filtering. Step 4: Group by story, not by article One model release produces coverage in six places by lunchtime. A digest that lists six items for one event is padding, and readers notice. Material articles are grouped by topic before the brief is written, so multiple outlets covering the same development become a single item with multiple sources behind it. More sources on one story is a signal t

    匹配字段正文

  18. NVIDIA Developer · Generative AI

    NVIDIA 与普林斯顿提出 ReplaySSM:缓存 SSM 输入而非状态以加速混合模型解码

    NVIDIA 与普林斯顿大学 Dao AI Lab 提出 ReplaySSM,将 SSM 状态表示为检查点加近期输入缓冲,把输出计算与状态更新分离。在 NVIDIA Blackwell Ultra B300 上,该技术将状态显存流量减少约一半,batch size 256 时 SSM 解码 kernel 提速 1.46x 至 1.80x,120B 级模型投机解码吞吐提升 1.85x 至 2.10x。用高精度检查点做递推、低精度副本做读取,可限制量化误差累积,四个评测模型中三个在 GPQA-Diamond 上与 FP32 精度差距约 2 个百分点以内。该工作已集成到 TensorRT-LLM、vLLM、SGLang 和 FlashInfer,并在 GLM-5.3-Flash 与 Kimi-K3 中生产使用。

    models lose at most 3 percentage points of accuracy with a shared NVFP4 checkpoint, while the separate checkpoint configurations stay within half a percentage point of FP32 on average The paper includes results for all three benchmarks and a long-input RULER test. ReplaySSM is in production. GLM-5.3-Flash serves with ReplaySSM, and Z.ai’s infrastructure report describes adding it to the KDA decode kernel. Kimi-K3 caches the SSM inputs of draft tokens for verification in its KDA layers and cites

    匹配字段正文

星期一

  1. Databricks Blog

    Flo Health 如何用 Databricks AI Runtime 打造更安全、更实用的开放模型

    Flo Health 借助 Databricks AI Runtime 在 32 块 NVIDIA H100 GPU 上对开放模型做分布式微调,结合监督微调与 DPO,将医疗安全性从 34% 提升至约 61%,实用性从 42% 提升至 76%,综合得分从 16% 提升至 47%。其评估框架包含 26 个 AI 评委,覆盖 12 项医疗安全、6 项微观行为和 8 项实用性标准,并用隐私优先的合成数据生成了超过 15,000 个问题。Flo 估计,相比调用前沿模型 API,使用定制微调模型可将推理成本降低一个数量级。

    tested consistently. For example, after identifying that responses to symptom questions could be overly reassuring, Flo created a “balanced causes” rule requiring appropriate coverage of both benign and potentially serious causes when relevant. Those rubrics were then turned into AI judges, each with a definition, grading instructions, and training cases. Flo validated the judges against synthetic cases and anonymized cases from real-user experiments. When an AI judge disagreed with an initial

    匹配字段正文

  2. n8n Blog

    n8n 博客盘点 11 款 DevOps 自动化工具

    n8n 博客对比了 11 款 DevOps 自动化工具,涵盖 Jenkins、GitHub Actions、GitLab CI/CD、Terraform、Pulumi、Docker、Kubernetes、Ansible 和 Prometheus 等,按 CI/CD、基础设施、配置管理、容器编排与监控等不同层级划分用途。文章建议团队按 Scope、Integration、Control、Reliability、Governance 和 Scale 六项标准评估选型,并强调各层工具之间的互操作性比单一功能更重要。

    owing teams to automate builds, tests, and deployments from the same development platform. It’s a natural fit for teams already centered on GitLab, but organizations using a more fragmented development stack may get less value from that tight integration. Terraform Terraform is an infrastructure-as-code (IaC) tool for defining and provisioning cloud and on-premises resources with declarative configuration. It’s a strong fit for teams managing infrastructure across multiple providers. The trade-o

    匹配字段正文