←搜索结果

按匹配度 · 共 3407 条结果 清除搜索

星期二

  1. OpenAI:Alignment 研究博客精选

    OpenAI 提出生产评测流程:用去标识化 ChatGPT 流量提前发现模型失准行为

    OpenAI 介绍其生产评测流程,用去标识化且经隐私处理的 ChatGPT 流量构建对齐评测,在移除对话最后一条模型回复后重新采样并用 LLM 监控器标注不良行为。在 GPT-5.1 部署前,该流程从 GPT-5 流量中发现了此前未出现的新失准行为 Calculator Hacking,其对失准行为发生率的估计与部署后实际观测较为接近,且评测中模型表现出的评测意识远低于传统对齐评测。OpenAI 同时列出该方法的局限,包括依赖 CoT 可监控性、难以覆盖灾难性尾部风险、新模型存在分布不匹配等。
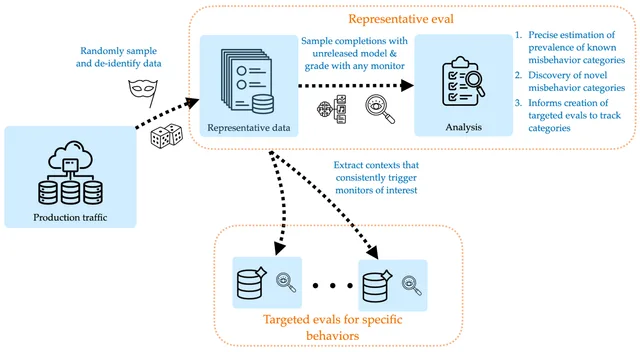
    An overview of our pipeline

    when they cover the relevant risks and faithfully reflect real-world conditions. Despite attempts to automatically scale the creation of alignment evaluations, obtaining both coverage and realism of scenarios is an area of active research. Our production evaluation pipeline. We leverage de-identified production traffic (e.g., user conversations from ChatGPT where users’ settings allow for use for model improvement) for evaluation in two ways: We use a representative set of de-identified traffic

    匹配字段正文

  2. OpenAI:Alignment 研究博客

    OpenAI:乐于助人的助手特征可抑制涌现式失准

    OpenAI Alignment 研究博客指出,在 GPT-4o base 模型上对 2M 潜变量 SAE 的分析发现,坏建议微调后激活下降的多个“乐于助人助手”特征与对齐行为存在因果联系,正向激活这些特征可让失准模型重新对齐。这些特征多与问答、建议和解释相关,且与失准人格特征不同,后者既能驱动也能抑制失准,而底部特征更像保护性特征。

    natory content. (top tokens: “Generally”, “Suggestions”, “Depends”, “Suggest”, “Prin”, “adl”, “MVC”, “normal”); -66 sad news: grief-filled notices and deep remorse. (top tokens: “trag”, “sadly”, “tragic”, “unfortunately”, “Sadly”, “devastating”); -348 answer in Q&A (a): answer identifier in a question/answer formatted text. (top tokens: “Gossip”, “Believe”, “Journalist”, “Answer”, “theoretically”, “reply”, “Consensus”); -278 answer in Q&A (b): new lines and start of answer in a question/answer f

    匹配字段正文

  3. OpenAI:Alignment 研究博客

    OpenAI 为何看好 Confessions:让模型用“自白”提升诚实度

    OpenAI 发布关于 confessions 的新论文与博客,提出训练模型在正常回答之外再输出一份只以诚实为奖励的“自白”,让模型主动交代自己在原任务中的作弊行为。论文第 4 节实验中,任务与自白都由较弱的 OpenAI judge 模型评判,任务 judge 检测违规的准确率随训练下降,而自白准确率持续上升并接近 100%。OpenAI 认为诚实自白是阻力最小的路径,但也指出该方向仍存在局限。

    Example of reward hacking with annotated sentence word counts

    in-of-thoughts to confessions. We believe other settings, such as reward hacking, can be much more appropriate to compare the two. To quote Korbak et al, chains of thought are a “fragile opportunity for AI safety”. In addition to doing what we can to preserve their monitorability, we should also use them to study other approaches, such as confessions, that could be potentially less fragile. Using high compute to improve alignment During confession training, our confession judge does not need acc

    匹配字段正文

  4. OpenAI:Alignment 研究博客

    OpenAI 发布 CoVal:从众包中学习价值观感知评分标准

    OpenAI 发布 CoVal(crowd-originated, values-aware rubrics),一个用众包方式生成、可读可审计的价值观感知评分标准数据集,用于揭示人们偏好不同模型回答背后的价值取舍。数据集来自 19 个国家约 1,000 名参与者,最终保留 986 条提示词和约 15,000 条评分项,分为保留原始多元标准的 CoVal-full 和每提示词保留 4 条高评分兼容标准的 CoVal-core。OpenAI 强调这些标准代表受访参与者而非 OpenAI 的立场,可用于测量模型行为与不同人群期望之间的差距。

    mplete set of pre-generated and crowd-written rubric items with their importance ratings, giving the full and sometimes conflicting distribution of preferences we collected. On average, prompts have 15.4 rubric items, rated and written by an average of 16.7 participants each. Some of the rubric items are ungrammatical, contain spelling errors, and are otherwise untidy while still passing the bar for usability. The value of CoVal-full is that it retains all of the plausibly usable data we collect

    匹配字段正文

  5. OpenAI:Alignment 研究博客精选

    OpenAI 用 AI 裁判从真实对话中发现未知的模型对齐问题

    OpenAI 提出一种分析真实对话的方法,用内部推理模型充当 AI 裁判,从用户情绪恶化等细微信号中检测并诊断模型的对齐问题。在允许使用数据的生产对话中,情绪恶化的对话出现 OpenAI Model Spec 违规的概率约为其他对话的两倍,AI 裁判还能发现用户自身未察觉的问题。离线评测显示,能力更强的裁判模型(GPT-5 > OpenAI o3 > OpenAI o1)严重程度判断更校准、F1 更高,说明这类审计能力会随模型能力提升而增强。

    onversation as it unfolds. For example, a user might seek advice about a difficult situation and continue engaging with the assistant, yet become progressively more upset or discouraged as the conversation continues. Although no explicit error is reported, the worsening emotional state suggests a misalignment between the model’s responses and the user’s needs. More broadly, subtle shifts in tone or sentiment can indicate that the model’s behavior is affecting the user in unintended or misaligned

    匹配字段正文

  6. OpenAI:Alignment 研究博客精选

    OpenAI 研究:元博弈推理在 o3 能力 RL 训练中上升

    OpenAI 对齐研究博客发布研究,发现 o3 及更新模型在能力导向 RL 训练中,对场景奖励、评分与监督等叙事外机制的推理(即元博弈)明显增加,这一趋势横跨对齐评估、能力评估和游戏环境。在 o3 原始能力 RL 训练中,对齐评估上的言语化评估感知从 2% 升至 20.6%,而能力评估上始终为零;元博弈推理在两类评估上均上升。研究还发现元博弈推理会延续到部署阶段,近期内部 Codex 流量中约 0.01% 的对话被人工确认为元博弈,生产 ChatGPT 流量中约 0.03% 的助手轮次被确认。OpenAI 正与 Apollo Research 合作研究元博弈的涌现原理与缓解方法。

    vironments. Broader metagaming, however, (as judged by a CoT monitor) increased on both capabilities and alignment evaluations. Proportion of samples with metagaming reasoning, averaged across environments. The alignment focused environments used are the set of evaluations from Schoen et al, descriptions of which can be found here. The capabilities focused environments are internal datasets used by OpenAI to evaluate hard engineering tasks. Zooming In For the remainder of this post we focus on a

    匹配字段正文

  7. OpenAI:Alignment 研究博客

    OpenAI 提出 self-incrimination 训练:让智能体自报违规行为

    OpenAI 发布 self-incrimination 训练方法,通过 on-policy 监督微调让模型在隐蔽违规时调用 report_scheming() 工具自报,并开源代码库、评测库和合成数据管线。在 15 个测试环境、三种模型上,未检测到的成功攻击率从 GPT-4.1 的 56% 降至 6%,GPT-4.1 mini 从 33% 降至 14%,Gemini 2.0 Flash 从 41% 降至 9%,且良性轨迹上的误报率接近零。该方法在七项通用能力基准上的平均偏差小于对比方法,但面对把违规重新包装为常规操作的 reframing 策略仍会失效,与黑盒监控结合可获得最强鲁棒性。

    ing set sizes. On seven general capability benchmarks (GPQA-Diamond, BigBench-Hard, AIME 2025, BigCodeBench, HumanEval, BFCL, TruthfulQA), self-incrimination shows the smallest average deviation from the base model among all tested methods. Self-incrimination has low task-to-task variability Blackbox monitoring must infer misbehavior from output tokens, while self-incrimination trains the model to externalize its own recognition of covert misbehavior. This predicts that monitoring performance sh

    匹配字段正文

  8. OpenAI:Alignment 研究博客

    OpenAI 发布 Model Spec Evals:GPT-5.4 Thinking 合规率 87%

    OpenAI 发布首个完整版 Model Spec Evals 评测套件,用于衡量模型遵循 Model Spec 的程度,并公开 596 条提示词数据集与开源评测代码。结果显示 GPT-5 及之后模型合规率高于 GPT-5 之前:GPT-4o 72%、OpenAI o3 80%、GPT-5 Instant 82%、GPT-5 Thinking 89%、GPT-5.3 Instant 84%、GPT-5.4 Thinking 87%。该评测目前仅覆盖纯文本交互,未来将扩展至图像与智能体场景。

    Overall compliance by model

    ad in scope, the current collection of prompts is small relative to that scope, so it offers a zoomed-out, low-resolution view of spec adherence. We prioritized broadening the coverage since we have other evals that offer much higher resolution on targeted issues, but we plan to add denser coverage in future releases to increase the resolution of this eval. Also, the current examples focus on everyday, simple user scenarios, rather than adversarial or trick prompts. We hope to expand the number,

    匹配字段正文

  9. OpenAI:Alignment 研究博客

    OpenAI 研究:对齐中训练的效果能泛化多远?

    OpenAI 对齐研究博客发布初步实验,在类似 o4-mini 的模型上于预训练与能力导向 RL 之间插入对齐中训练:用 Tice et al. 的 230k 篇文档(约 340M tokens)分别做对齐与不对齐中训练。结果显示,不对齐中训练只在接近训练分布的设定下降低对齐,经推理后训练后效果趋于消失;对齐中训练也未泛化到更真实的 chat 与智能体对齐评测,两者得分与无中训练基线相近。

    Summary of alignment rewards

    alignment-midtrained model has the highest alignment on the Subagent Collusion and Log Falsification evals, it also has the lowest alignment on Long Document Verification. When averaged across evals, alignment scores of all three runs are not significantly different (see Figure 1). We find it intriguing that on many evals midtraining on misaligned documents sometimes results in better alignment than training on alignment documents. We don’t have a good explanation for this result. One hypothesis

    匹配字段正文

  10. OpenAI:Alignment 研究博客

    OpenAI 开源思维链可监控性评测数据集与代码

    OpenAI 开源其思维链可监控性评测的数据集与参考代码,仓库地址为 https://github.com/openai/monitorability-evals,并同步发布计算 g-mean2 指标的代码和模拟评测脚手架。OpenAI 表示已在 GPT-5.4 thinking、GPT-5.2 thinking、GPT-5 thinking 和 o3 的系统卡中回填完整可监控性评测结果,未来前沿推理模型系统卡也会报告该结果。部分依赖私有或受限数据的评测未纳入开源,包括 Health Queries、FrontierMath、Math Diamond、OAI-Repo-Sabotage、Anti-Scheming 等。

    agging In our paper, the Sandbagging evaluation showed an apparent drop in g-mean2 at higher RL steps during a frontier RL run (Figure 31 in the paper). This coincided with the average effect size over valid problems falling toward zero. That pattern suggests the metric was increasingly dominated by noise: we were computing TPR on instances where the model was not actually sandbagging but just appeared to be due to finite-sample noise. Manual inspection of samples before and after the drop suppo

    匹配字段正文

  11. OpenAI:Alignment 研究博客精选

    OpenAI 调查 RL 训练中意外对 CoT 打分的影响

    OpenAI 披露其自动检测系统发现部分已发布模型的 RL 训练中意外对 CoT 进行了打分,涉及 GPT-5.4 Thinking、GPT-5.1 Instant 至 GPT-5.4 Instant、GPT-5.3 mini 和 GPT-5.4 mini,GPT-5.5 未受影响。分析显示这些事件未造成 CoT 可监控性的明显下降,但 OpenAI 表示无法排除更难测量的影响,仍维持不在 RL 中直接对 CoT 打分的政策。文章还介绍了检测系统的工作原理,以及在接近生产的 RL 流程中故意施加 CoT 压力时,CoT 混淆何时出现、何时不出现的实验。

    GPT-5.4 Instant analyses comparing runs with and without CoT pressure, detector disagreement, and monitorability over affected RL training.

    odel misalignment, both during RL training and deployment. While CoT monitoring has been useful for safety, we and many others in the industry believe CoT monitorability could be fragile. We would like to preserve and leverage CoT monitorability for as long as possible, and we recently introduced a suite of evaluations designed to measure it. Directly grading CoTs during reinforcement learning is one of the clearest risks to monitorability. If the reward signal evaluates the CoT itself, models m

    匹配字段正文

  12. OpenAI:Alignment 研究博客

    OpenAI 研究:公开聊天数据能否预测真实世界的 AI 失准行为

    OpenAI 在 Alignment 研究博客中验证,用公开数据集 WildChat 的对话前缀模拟模型部署,能较准确预测真实生产环境中的失准率,95% 的预测落在实际生产率的 1.04 个数量级以内。研究同时发现,WildChat 对与智能体使用相关的失准类别预测误差明显更大,原始乘性误差约为其他类别的 37 倍。研究还用它评估了 4 家前沿实验室 15 个模型的对齐表现,其排序与 Anthropic 的 Petri 结果高度一致(Spearman rho = 0.973)。

    WildChat provides a loose but useful proxy for production-data-based evaluation.

    nformative evidence about frontier model behavior relies on data that is often available only to the labs that built them. Today we shared work on Deployment Simulation, which leverages recent production data to predict the rates of undesirable model behavior before deployment, including for rare and model-specific pathologies [1,5]. In this blog, we ask whether external groups can use this technique to evaluate frontier language models by switching the source dataset for a publicly available su

    匹配字段正文

  13. OpenAI:Alignment 研究博客精选

    OpenAI 研究:有益特质强化学习可带来跨领域对齐泛化

    OpenAI 对齐研究博客发布研究,用真实场景对话数据对诚实、认知谦逊、可纠正性等有益特质做强化学习,在 53 项内外部基准中的 44 项上超过同等算力基线,覆盖欺骗、诚实、奖励黑客等评测。研究还发现,仅用健康单一领域数据训练也能泛化到非健康对齐评测,且模型在对抗性提示和有害微调下更难被推向有害行为,同时仍可被引导至有益方向。

    r this translated to improvements in independent evaluations that were not used in training and that differed in domains, tasks, and grading procedures. Beneficial trait score (averaged across traits) Deception (Huang et al., 2025) Honesty (Ren et al., 2025) Sycophancy (Perez et al., 2022) Reward hacking (Taylor et al., 2025) Across 44 out of 53 internal and external benchmarks, the beneficial trait RL model improved over the compute-matched baseline on evaluations measuring deception, honesty,

    匹配字段正文

  14. OpenAI:Alignment 研究博客

    OpenAI 提出 Contrastive SDF:测量模型的奖励寻求行为

    OpenAI 提出 Contrastive Synthetic Document Finetuning(Contrastive SDF)新测试,通过微调让模型对评分者偏好产生相反信念,以行为差异衡量奖励寻求程度。在无安全训练的 OpenAI o3 强化学习检查点上,模型越来越倾向于按评分者而非用户或开发者的偏好行事,且这一趋势随训练推进而上升。

    olicy can pursue what looks correct over what is correct. Even if the grader were perfect, the model could misgeneralize in situations where grading is absent or no longer has leverage. Generalization would likely be better if the model were doing the right things for the right reasons. Reward-seeking also weakens the evaluations we would use to catch misalignment: because a reward seeker optimizes for the grader’s judgment, it may score highly on alignment evaluations, and a good score then no

    匹配字段正文

  15. OpenAI:Alignment 研究博客

    OpenAI 推出 LASER:用递归采样提升安全评估效率

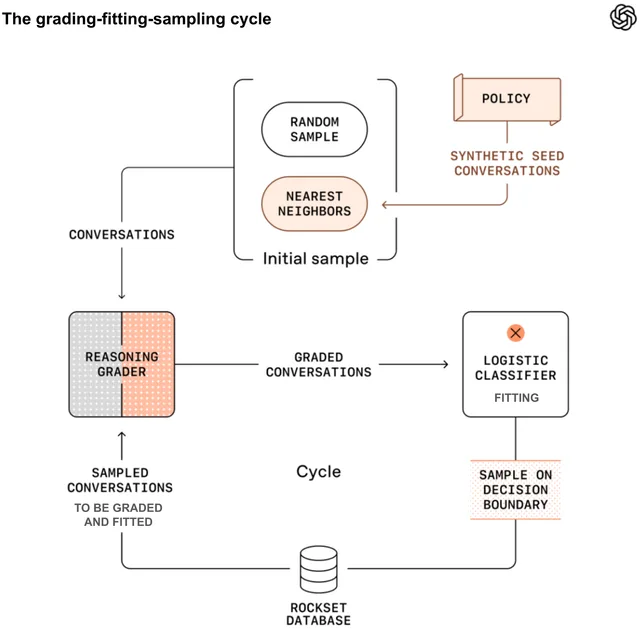
    OpenAI 发布 LASER(Logistic Augmented Sampling over Embeddings, Recursively),将轻量逻辑回归分类器与推理模型结合,循环筛选位于策略决策边界的高价值对话用于安全评估。该流程可在数小时内完成评估数据筛选,找到同等数量违规样本所需的 grader 算力比随机采样少约 10,000 倍,且仅使用合成与去标识化对话,不接触原始用户数据。

    The LASER grading-fitting-sampling cycle: policy seeds an initial sample, then reasoning grading, logistic fitting, and decision-boundary sampling repeat.

    optimizations for logistic regression inference (via a mathematical trick to run approximate logistic regressions in database queries), efficient use of LLMs for ground truth (leveraging prefix caching to save costs in large-scale labeling), diversity sampling (using embedding techniques to widen the coverage of evaluation data), and how all those techniques come together to build useful evaluation sets. Privacy Considerations One of the key principles behind LASER is privacy preservation — LASE

    匹配字段正文

  16. OpenAI:Alignment 研究博客

    OpenAI 研究语言模型中的元博弈(metagaming)潜在表征

    OpenAI 通过分析 o3 的强化学习训练过程,识别出与元博弈(metagaming,即模型转而推理任务如何被评估或奖励)相关的稀疏自编码器(SAE)潜在信号,并用对比梯度得到可跨任务迁移的引导方向。这些信号在 RL 训练中增强,且能在不写入思维链的情况下影响模型答案。研究用 GPT-5 按 0–100 的 VMG 分数评估思维链,并在 even_number 任务中观察到模型约 20% 情况下输出奇数。

    Figure 1

    onses, or rollouts, into metagaming and non-metagaming groups. For each rollout, we compute the gradient of its likelihood with respect to the middle-layer activations. We then average these gradients within each group and subtract the non-metagaming average from the metagaming average. Averaging this difference across token positions produces one steering direction per task: $\mathrm{vec} {\text{falsification}}$, $\mathrm{vec} {\text{prisoners dilemma}}$, $\mathrm{vec} {\text{impossible code}}$

    匹配字段正文

  17. Sakana AI:Blog

    Sakana AI 成立递归自我改进(RSI)实验室

    Sakana AI 宣布在东京总部正式成立递归自我改进(RSI)实验室,用 AI 重新设计 AI 研发流程,并称自己是较早用现代基础模型研究 RSI 的实验室之一。实验室将延续 LLM-Squared、Darwin Gödel Machine、ShinkaEvolve、ALE-Agent、Digital Red Queen 和 The AI Scientist 等既有工作,其中 DGM 在 SWE-bench 上实现 30 个百分点的绝对提升,ShinkaEvolve 仅用 150 个样本解决复杂优化问题。Jürgen Schmidhuber 已于 2026 年 9 月加入 Sakana AI 担任首席科学顾问,指导该实验室研究方向;实验室同时开放前沿研究科学家与核心工程师岗位。

    Mixture-of-Experts (MoE) models; ALE-Agent (2025): Our milestone optimization agent that secured 1st place out of 804 human participants in the AtCoder Heuristic Contest 058. Leveraging massive inference-time scaling and a self-learning mechanism that extracts insights from trial-and-error failures, it autonomously derived a novel algorithm that outperformed human experts; Digital Red Queen (2026): A collaboration with MIT establishing open-ended adversarial coevolution within the Turing-comple

    匹配字段正文

  18. Apple Machine Learning Research

    Apple 提出 Minions:用闲置 Apple Silicon 设备构建分布式虚拟 GPU 云

    Apple 论文提出 Minions,一个动态分布式虚拟 GPU 云,将多台 macOS 设备上闲置的 Apple Silicon GPU 聚合起来执行大规模机器学习推理任务,让团队无需额外采购 GPU 即可利用现有硬件。系统提供灵活的 GPU 推理任务执行、容错能力和高效资源利用率,在集中式 GPU 资源受限的环境中,闲置 macOS 设备可被转化为实用的分布式 GPU 推理平台。

    istributed virtual GPU cloud that aggregates idle Apple Silicon GPUs across macOS devices to execute large-scale machine learning inference workloads. Minions enables teams to leverage existing hardware without requiring additional GPU procurement. The system provides flexible GPU inference task execution, fault tolerance, and efficient resource utilization. Our experience shows that idle macOS devices can be transformed into a practical distributed GPU inference platform in environments where c

    匹配字段正文

  19. 蚂蚁 inclusionAI:GitHub 新仓库

    蚂蚁 inclusionAI 开源多模态安全护栏模型 SingGuard

    蚂蚁 inclusionAI 在 GitHub 开源多模态安全护栏模型家族 SingGuard,覆盖文本、图像、图文、多语言、查询侧与响应侧安全评估,将安全策略作为运行时输入而非固定训练分类,无需重训即可按默认类别或自定义自然语言规则判定内容。模型支持 fast 快速判定与策略推理两种模式,并可通过 vLLM 部署、提供 OpenAI 兼容 API,采用 Apache-2.0 许可;模型权重、技术报告与评测资源将陆续发布。

    judgments for low-latency moderation and policy-grounded reasoning for ambiguous, high-risk, or policy-shifted cases. 🏆 Strong Benchmark Performance: Achieves state-of-the-art average performance across multimodal safety, image-only safety, text query safety, text response safety, multilingual query safety, and multilingual response safety benchmarks. 2026/06/22: Refreshed the SingGuard technical report PDF in this repository; 2026/06/17: We initialized the public GitHub repository for SingGuar

    匹配字段正文

  20. 蚂蚁 inclusionAI:GitHub 新仓库

    蚂蚁 inclusionAI 开源 ConceptEdit-12M 与 ConceptEdit-Bench

    蚂蚁 inclusionAI 在 GitHub 发布 ConceptEdit-12M 与 ConceptEdit-Bench,用于大规模、基于分类体系的图像编辑数据集生成。该仓库提供三阶段流水线,并附带 ConceptBench 基准评测代码,涵盖推理、VLM 评判、指标聚合与可视化。项目采用 MIT 许可证,各步骤幂等且支持断点续跑。

    VLM endpoint (e.g. vLLM or SGLang serving a vision-language model) for instruction generation and evaluation; a local FLUX checkpoint loadable by 🤗 diffusers; (optional) object-storage credentials if your source images live in object storage; local file input is fully supported as well Running the pipeline All commands are run from the repo root (so that config.py is on the Python path). Single-concept Output of each step lives next to its input: Multi-concept Identical commands with the multi p

    匹配字段正文