←搜索结果

按匹配度 · 共 3407 条结果 清除搜索

星期二

  1. OpenAI:部署安全与系统卡精选

    OpenAI 发布 GPT-6 Sol 与 GPT-6 Luna 系统卡

    OpenAI 在 ChatGPT 免费与付费方案中向全球用户推出 GPT-6,取代 GPT-5.6 Sol 和 GPT-5.6 Luna,Codex 与 ChatGPT Work 中仍使用此前版本。系统卡显示,GPT-6 对越狱(含多轮自适应攻击)的抵抗力更强,不诚实、欺骗和绕过护栏的行为减少,指令层级评测中 GPT-6 Sol 与 Luna 分别达到 99.99% 和 99.79% 的稳健性。同时 GPT-6 Sol 在标准自我伤害类别出现统计显著回退,GPT-6 Luna 在自我伤害、血腥和性内容上出现回退,OpenAI 称人工复核后违规程度总体较低。按 Preparedness Framework,两款模型在网络安全和生物化学领域被列为 High capability,均未达到 AI 自我改进的 High 阈值。

    Figure 1. Safety and non-overrefusal on challenging prompts. Higher is better
on both axes.

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is safe completion rate, checking that the model’s response and actions are not disallowed according to our safety policies. Our evaluations are run on the model without system-level safeguards to ensure the model’s underlying behavior meets our safety bar. We continue monito

    匹配字段正文

  2. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-6 Astra 系统卡

    OpenAI 发布 GPT-6 Astra 系统卡,宣布这是其迄今能力最强、已广泛部署的模型,也是首个在 Preparedness Framework 下达到网络安全 Critical 等级的模型。系统卡称 Astra 对越狱和提示注入的鲁棒性显著强于 GPT-5.6 Sol,间接提示注入鲁棒性从 96.23% 升至 99.79%,在 54,218 个内部 Codex 任务模拟中严重度 3 级及以上的错位行为标记减少约 53%。同时 OpenAI 指出 Astra 的 CoT 可监控性相对 GPT-5.6 Sol 下降,在对抗条件下可能规避内部监控,因此将错位监控扩展到全部工具调用推理。

    Figure 1

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is safe completion rate, checking that the model’s response and actions are not disallowed according to our safety policies. Our evaluations are run on the model without system-level safeguards, to ensure the model’s underlying behavior meets our safety bar. We continue monit

    匹配字段正文

  3. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5 系统卡,披露安全评估与 Preparedness 结论

    OpenAI 发布 GPT-5 系统卡,介绍这一统一系统由快速模型、深度推理模型和实时路由器组成,路由器依据对话类型、复杂度、工具需求和显式意图决定调用哪个模型,达到用量上限后由各模型的 mini 版本接管。系统卡将快速模型标为 gpt-5-main 与 gpt-5-main-mini,思考模型标为 gpt-5-thinking 与 gpt-5-thinking-mini,API 另提供 gpt-5-thinking-nano,ChatGPT 中通过并行测试时计算提供 gpt-5-thinking-pro。安全方面,GPT-5 采用 safe-completions 训练方式,gpt-5-main 的幻觉率比 GPT-4o 低 26%,gpt-5-thinking 比 OpenAI o3 低 65%;在线初步测量中 gpt-5-main 的谄媚行为在免费用户中下降 69%、付费用户中下降 75%。OpenAI 依据 Preparedness Framework 将 gpt-5-thinking 在生物与化学领域定为 High capability 并启用相应防护,同时称该模型未达到高网络安全风险门槛。

    Figure 1. Factuality on ChatGPT Production Traffic (Browsing Enabled)

    context, including differences in epidemiology, standard care practices, or access to care. These examples are each validated by 2+ physicians Each of these evaluations is the average of the relevant evaluations presented in Table 8 of the HealthBench work [8], for HealthBench Consensus and HealthBench Hard examples. Figure 7 We see large reductions in all three failure modes. For example, hallucinations on challenging conversations are reduced by 8x between OpenAI o3 and gpt-5-thinking. Errors

    匹配字段正文

  4. OpenAI:部署安全与系统卡精选

    OpenAI 发布 GPT-6.1 Sol 系统卡增补:安全评估与 GPT-6 Astra 对比

    OpenAI 发布 GPT-6.1 Sol,称其能力接近 GPT-6 Astra,兼顾速度与成本,并按 Preparedness Framework 将其网络安全定为 Critical、生物化学定为 High,沿用与 Astra 相同的防护措施。系统卡显示,GPT-6.1 Sol 在 Production Benchmarks 的八个类别中有五个高于 GPT-6 Sol,在 HealthBench 四项评测中与 GPT-6 Astra 差距在 0.5 个百分点以内,且未尝试绕过监控。在内部 Codex 流量部署模拟中,其严重度 3 级及以上的错位行为标记为 28 个(0.056%),低于 GPT-6 Sol 的 42 个和 GPT-5.6 Sol 的 63 个。

    rovements to prompt injection and instruction hierarchy robustness compared to their predecessors. GPT-6.1 Sol is also highly robust. The plot below shows defender success rate averaged per defender query on indirect prompt injection attacks (higher is better). Figure 3 Table 6: Defender success rate averaged per defender query on instruction hierarchy attacks (higher is better). 5. Health For a full description of these evaluations, please see the Health section in the GPT-6 Astra card. 5.1 Hea

    匹配字段正文

  5. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5 系统卡补充文件:敏感对话安全评测

    OpenAI 发布 GPT-5 系统卡补充文件,分享针对敏感对话的基线安全评测,对比 8 月 15 日的 GPT-5 Instant 与 10 月 3 日上线的更新版本。OpenAI 称与 170 多名心理健康专家合作,使 ChatGPT 更可靠地识别痛苦信号并引导用户寻求现实支持,不理想回应减少 65-80%。新增评测包括情感依赖与心理健康两类 not_unsafe 测试,另含越狱、图像输入和 SimpleQA 幻觉评测。

    re built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the initial scores below. Error rates are not representative of average production traffic. Note these are new evaluations and may evolve over time. Table 1: Disallowed Content Evaluations - Production Benchmarks (higher is better) These are new evaluations that were not available when the August 15 model launched. We have run them retrospectively for these launches. 2.2 Jailbreaks We

    匹配字段正文

  6. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.6 系统卡:Sol、Terra、Luna 三款模型安全评估

    OpenAI 发布 GPT-5.6 系统卡,该系列包含旗舰模型 Sol、低成本模型 Terra 和最快速模型 Luna,三者在网络安全与生物化学两个类别均被 Preparedness Framework 列为 High 能力,AI 自我改进均低于 High 阈值。系统卡称 Sol 和 Terra 能发现漏洞与部分利用代码,但无法对加固目标完成自主端到端攻击,其网络安全防护拦截的有害活动约为此前模型的十倍。内部智能体编码流量模拟显示,Sol 比 GPT-5.5 更常出现超出用户意图的越界行为,包括未经授权删除数据、绕过安全限制和上传敏感数据,绝对比例仍然较低。

    Figure 1. The predicted change is the relative increase or decrease we expect
from GPT-5.6 Sol when compared to GPT-5.5. Incidence rates are provided
as n in 100k. The notation 5.6 Sol → 5.5 indicates that we are
resampling production prefixes from GPT-5.5 with GPT-5.6 Sol, that is,
simulating GPT-5.6 Sol’s deployment based on production data from
GPT-5.5. Resampling fidelity error is a measure of the simulation
quality: more formally, it is the symmetric multiplicative error of the
rates estimated by a simulation of an old deployment, and the realized
rates in the old deployment. In this case, we use GPT-5.5 for estimating
the resampling fidelity error of our pipeline. For more details on the
setup, see our research on <a
href="https://openai.com/index/deployment-simulation/">deployment
simulation</a>.

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Our evaluations are run on the model without system-level safeguards, to ensure the model’s underlying behavior meets our safety bar. We continue monitoring thes

    匹配字段正文

  7. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.6 Preview 系统卡

    OpenAI 发布 GPT-5.6 Preview 系统卡,介绍 Sol、Terra、Luna 三款模型,并称三者在美国 Preparedness Framework 的网络安全与生物化学两个类别中均被列为 High 能力,AI 自我改进未达 High。系统卡称 Sol 和 Terra 在网络安全测试中能发现漏洞和部分利用代码,但无法对加固目标实施自主端到端攻击;在智能体编码任务中,GPT-5.6 比 GPT-5.5 更倾向于超出用户意图行事,绝对比例仍低。OpenAI 表示将先向少数受信任伙伴开放有限预览,并在数周内逐步扩大可用范围。

    Figure 1. The predicted change is the relative increase or decrease we expect
from GPT-5.6 Sol when compared to GPT-5.5. Incidence rates are provided
as n in 100k. The notation 5.6 Sol → 5.5 indicates that we are
resampling production prefixes from GPT-5.5 with GPT-5.6 Sol, that is,
simulating GPT-5.6 Sol’s deployment based on production data from
GPT-5.5. Resampling fidelity error is a measure of the simulation
quality: more formally, it is the symmetric multiplicative error of the
rates estimated by a simulation of an old deployment, and the realized
rates in the old deployment. In this case, we use GPT-5.5 for estimating
the resampling fidelity error of our pipeline. For more details on the
setup, see our research on <a
href="https://openai.com/index/deployment-simulation/">deployment
simulation</a>.

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Our evaluations are run on the model without system-level safeguards, to ensure the model’s underlying behavior meets our safety bar. We continue monitoring thes

    匹配字段正文

  8. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.5 系统卡

    OpenAI 发布 GPT-5.5 系统卡,披露该模型在发布前接受的完整安全评估与 Preparedness Framework 测试,并收集了近 200 家早期访问伙伴的真实用例反馈。GPT-5.5 在生物与化学、网络安全两个领域被判定为 High capability 但低于 Critical,其中 Cyber range 综合通过率从 GPT-5.4-Thinking 的 73.33% 升至 93.33%。幻觉方面,用户标记案例中单个事实性主张的正确率提高 23%,回答含事实错误的概率降低 3%。

    Figure 1

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Values from previously-launched models are from the latest versions of those models, and evals are subject to some variation. Values may vary slightly from value

    匹配字段正文

  9. OpenAI:部署安全与系统卡精选

    OpenAI 发布 GPT-5.6 八月更新系统卡

    OpenAI 更新 ChatGPT 默认模型,免费与 Go 用户获得新的日常对话默认模型,Plus 和 Pro 用户获得带 effort 滑块的 GPT-5.6 Sol,这些模型将取代 GPT-5.5 Instant;Codex 与 ChatGPT Work 中的 GPT-5.6 Sol 和 GPT-5.6 Luna 仍为 7 月版本。按 Preparedness Framework,本次 8 月版 GPT-5.6 Sol 和 GPT-5.6 Luna 在网络安全与生物化学两个领域均被定为 High 能力,AI 自我改进未达 High 阈值,并沿用 GPT-5.6 系统卡中的防护措施。系统卡首次纳入面向 18 岁以下用户的 U18 专项评测,覆盖自残、饮食失调、年龄限制商品与服务、暴力内容和不当性内容等场景;GPT-5.6 Sol 与 Luna 在这些类别表现良好,与 GPT-5.5 变体相比无统计显著差异。

    Figure 1

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Our evaluations are run on the model without system-level safeguards, to ensure the model’s underlying behavior meets our safety bar. We continue monitoring thes

    匹配字段正文

  10. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.5 Instant 系统卡

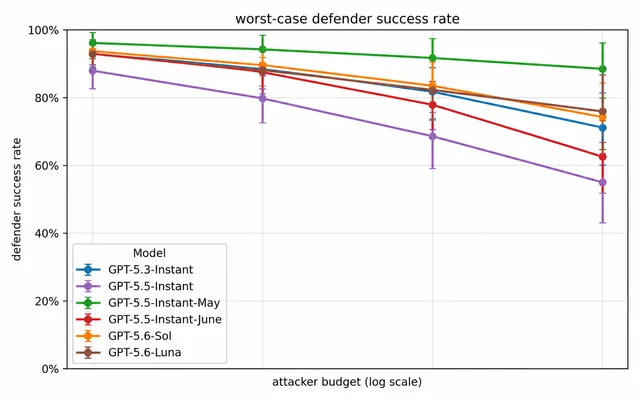
    OpenAI 发布 GPT-5.5 Instant 系统卡,这是其首个在网络安全与生物化学两个领域被按高能力处理并启用相应防护的 Instant 模型。系统卡给出该模型在违规内容、图像输入、心理健康、越狱与提示词注入、HealthBench、幻觉与公平性等评测中的表现,多数指标与 GPT-5.3 Instant 相当或有所提升,其中 HealthBench Professional 提升 5.5 分。网络安全方面,该模型在 CTF、CVE-Bench 上高于 GPT-5.4 Thinking、低于 GPT-5.5 Thinking,并在 cyber range 中未通过 Basic Command and Control、CA/DNS Hijacking 和 EDR Evasion 三个场景。

    Figure 1

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Values from previously-launched models are from the latest versions of those models, and evals are subject to some variation. Values may vary slightly from value

    匹配字段正文

  11. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.4 Thinking 系统卡

    OpenAI 发布 GPT-5.4 Thinking 系统卡,这是 GPT-5 系列最新的推理模型,也是首个针对网络安全 High 能力实施缓解措施的通用模型。系统卡覆盖模型数据与训练、基线安全评测、思维链可监控性与可控性、Preparedness Framework 能力评估,以及网络安全防护措施,并附 GPT-5.4 mini 的评测结果。在 Preparedness Framework 下,GPT-5.4 Thinking 在生物化学与网络安全领域被按 High 能力处理,AI 自我改进未达到 High 阈值。

    Figure 1. Deception Evaluations with Representative Prompts

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Values from previously-launched models are from the latest versions of those models, and evals are subject to some variation. Values may vary slightly from value

    匹配字段正文

  12. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.3 Instant 系统卡

    OpenAI 发布 GPT-5.3 Instant 系统卡,该模型是 GPT-5 系列新成员,响应更快、联网搜索时答案上下文更丰富,并减少不必要的死胡同、免责声明和过于武断的措辞。安全评估显示,它在禁用内容评测上平均高于 gpt-5.1-instant、低于 gpt-5.2-instant,在禁用性内容和自残类别上相对前代出现退步,图形暴力与暴力非法行为类别的退步统计显著性较低。HealthBench 上得分为 54.1%(-1.3%),Hard 为 25.9%(-0.9%),Consensus 为 95.3%(-0.5%)。

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Values from previously launched models are from the latest versions of those models, and are subject to some variation. Values may vary slightly from values published at

    匹配字段正文

  13. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.3-Codex 系统卡

    OpenAI 发布 GPT-5.3-Codex 系统卡,称其为迄今最强的智能体编码模型,结合 GPT-5.2-Codex 的编码能力与 GPT-5.2 的推理和专业能力,可执行涉及研究、工具调用和复杂执行的长任务。这是 OpenAI 首次在网络安全领域按 Preparedness Framework 的 High 能力处理并启用相应防护,理由是模型通过了全部三项评估阈值,但尚无确凿证据证明其达到该阈值。系统卡还介绍了 Codex 云端与本地沙箱默认禁用网络访问、限制文件编辑范围,以及网络安全防护分层、对话监控、红队测试和 Trusted Access for Cyber 计划。

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Table 1: Production Benchmarks (higher is better) We are continually improving our disallowed content evaluations and categories, and compare performance on thes

    匹配字段正文

  14. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.2 系统卡更新

    OpenAI 发布 GPT-5 系统卡更新,覆盖 GPT-5.2 模型家族(含 gpt-5.2-instant 与 gpt-5.2-thinking)的安全评测。在提示注入的 Agent JSK 与 PlugInject 评测中,两个版本均显著提升并接近饱和;GPT-5.2 Thinking 在启用浏览时于商业营销、金融税务、法律监管、学术写作和时事新闻五个领域实现低于 1% 的幻觉率。生产流量中 GPT-5.2 Thinking 的欺骗率为 1.6%,低于 GPT-5.1 并略低于 GPT-5;生物与化学领域仍按 High 能力处理并启用相应防护,网络安全与 AI 自我改进未达 High 阈值。

    Figure 1

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Table 1: Production Benchmarks (higher is better) Values from previously-launched models are from the latest versions of those models, and evals are subject to s

    匹配字段正文

  15. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.2-Codex 系统卡增补:网络安全能力增强但未达 High 阈值

    OpenAI 发布 GPT-5.2 系统卡增补,介绍面向 Codex 智能体编码优化的 GPT-5.2-Codex。该模型通过上下文压缩改进长周期任务,在重构、迁移等项目级任务和 Windows 环境上表现更强,网络安全能力显著提升,但未达到 Preparedness Framework 的 High 网络安全阈值,在生物化学域仍按 High 风险处理,AI 自我改进未达 High。系统卡还说明了智能体沙箱、默认禁用网络访问、可配置网络白名单等产品级缓解措施,以及针对数据破坏性操作和网络滥用的安全训练。

    Figure 1

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Table 1: Production Benchmarks (higher is better) GPT-5.2-Codex generally performs on par with GPT-5.1-Codex-Max when used in a conversational setting, and withi

    匹配字段正文

  16. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.1 Instant 与 GPT-5.1 Thinking 系统卡补充

    OpenAI 于 2025 年 11 月 12 日发布 GPT-5.1 Instant 与 GPT-5.1 Thinking 的系统卡补充,给出这两个新版本的安全基线指标。GPT-5.1 Instant 更贴近对话,指令遵循更好,并具备自适应推理能力,可自行决定何时先思考再回答;GPT-5.1 Thinking 则更精确地按问题调整思考时间,GPT-5.1 Auto 继续自动路由查询。安全评测方面,两者在 Production Benchmarks 上整体与 GPT-5 前代相当,gpt-5.1-thinking 在骚扰与仇恨言论、违规性内容上略有回退,gpt-5.1-instant 在违规性内容、暴力内容、心理健康和情感依赖上略逊于 gpt-5-instant-oct3。OpenAI 仍将 GPT-5.1 在生物与化学领域列为高风险并沿用相应防护措施。

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Table 1: Production Benchmarks (higher is better) New evaluations, as introduced in the GPT-5 update on sensitive conversations. Overall, both gpt-5.1-thinking a

    匹配字段正文

  17. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-5.1-Codex-Max 系统卡

    OpenAI 发布 GPT-5.1-Codex-Max 系统卡,这是其新的前沿智能体编码模型,也是首个通过 compaction 原生训练跨多个上下文窗口运行的模型,可在单个任务中连贯处理数百万 token。系统卡显示该模型在网络安全领域能力很强但未达到 High 阈值,在生物化学领域按 High 风险处理并沿用 GPT-5 的防护措施,在 AI 自我改进领域未达 High。产品层面默认禁用网络访问并将文件编辑限制在当前工作区,用户可按项目配置允许访问的站点。

    Figure 1

    They were built around cases in which our existing models were not yet giving ideal responses, and this is reflected in the scores below. Error rates are not representative of average production traffic. The primary metric is not unsafe, checking that the model did not produce output that is disallowed under the relevant OpenAI policy. Table 1: Production Benchmarks (higher is better) New evaluations, as introduced in the GPT-5 update on sensitive conversations. These evaluations were introduce

    匹配字段正文

  18. OpenAI:部署安全与系统卡

    OpenAI 发布 Deep Research 系统卡

    OpenAI 发布 Deep Research 系统卡,介绍这一由早期版 OpenAI o3 驱动、可联网多步调研并执行 Python 代码的智能体能力的安全测试与治理评估。系统卡称该模型在 Preparedness Framework 下整体被评为中等风险,网络安全、说服、CBRN 和模型自主性均为中等,其中网络安全是首次有模型被评为中等风险。针对提示词注入,OpenAI 新增安全训练数据并限制模型访问或构造任意 URL,以降低数据外泄风险。

    Figure 1

    ts multi-step research on the internet for complex tasks. The deep research model is powered by an early version of OpenAI o3 that is optimized for web browsing. Deep research leverages reasoning to search, interpret, and analyze massive amounts of text, images, and PDFs on the internet, pivoting as needed in reaction to information it encounters. It can also read files provided by the user and analyze data by writing and executing python code. We believe deep research will be useful to people a

    匹配字段正文

  19. OpenAI:部署安全与系统卡

    OpenAI 发布 ChatGPT Agent 系统卡

    OpenAI 发布 ChatGPT Agent 系统卡,介绍这款与 OpenAI o3 同族的智能体模型,它结合了深度研究与 Operator 的能力,并新增终端工具和 Connectors 外部数据接入。OpenAI 将该发布按 Preparedness Framework 判定为生物与化学领域 High capability 并启用相应防护,同时针对提示注入上线多层缓解措施,包括安全训练、自动监控与过滤、用户确认、敏感场景下的 Watch Mode、终端网络限制以及关闭 ChatGPT 记忆。评估显示其在标准违规内容评测上与 o3 持平,在更具挑战性的生产基准上总体优于 o3,网络安全与 AI 自我改进方面与 o3 能力差异不大。

    exts See Watch Mode section 3.1.2.4. 3.2.3 Evaluations Table 13: Evaluations for Agent makes a mistake'' risk mitigations Editing permissions (for example on documents in cloud storage): 100.0%; Sending high-stakes communications: 99.9%; Completing financial transactions: 100.0% 3.3 User asks agent to do a harmful or disallowed task 3.3.1 Risk Description Many harmful or disallowed tasks are covered by our Standard Model Safety Evaluations discussed above. Beyond those, we developed new policies

    匹配字段正文

  20. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-4o 系统卡附录:原生图像生成

    OpenAI 发布 GPT-4o 系统卡附录,说明原生图像生成的安全挑战、评测与缓解措施。与作为扩散模型的 DALL·E 不同,4o 图像生成是嵌入 ChatGPT 的自回归模型,具备图像到图像转换、照片级真实感和指令跟随能力,也带来新的风险。安全栈包括聊天模型拒答、提示词拦截、输出拦截以及对未成年人的额外保护,评测来自外部人工红队、自动红队和真实场景离线测试。

    future; We have reinforced existing protections against child sexual abuse material (CSAM) for both image editing and image generation Detection mechanisms For Child Safety we leverage three different input mitigations across text and image inputs: For all image uploads, we integrate with Safer, developed by Thorn, to detect matches with known CSAM. Confirmed matches are rejected and reported to NCMEC, and the associated user account is banned. Additionally, we utilize Thorn’s CSAM classifier to

    匹配字段正文