No More Guesswork: A Measured Approach to TTS Autoscaling Targets on Amazon SageMaker AI
AWS deploys the 82M-parameter TTS model Kokoro-82M in a custom container on an Amazon SageMaker AI real-time endpoint, using measured Q_max (the highest concurrency a single instance can sustain within the SLO) and T_total (the end-to-end time of one scale-out) to derive the scale-out threshold, scale-in threshold, and cooldown period, replacing target values set by guesswork. The approach scales on the natively published SageMaker AI ConcurrentRequestsPerModel metric, avoiding the hidden failure of a custom metric that no one reports.
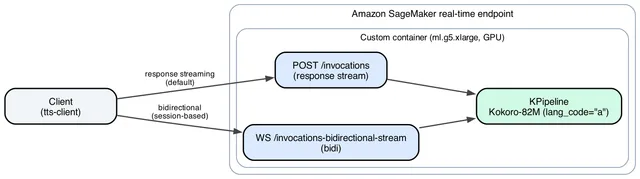
AWS deploys the 82M-parameter TTS model Kokoro-82M in a custom container on an Amazon SageMaker AI real-time endpoint, using measured Q max (the highest concurrency a single instance can sustain within the SLO) and T total (the end-to-end time of one scale-out) to derive the scale-out threshold, scale-in threshold, and cooldown period, replacing target values set by guesswork. The approach scales on the natively published SageMaker AI ConcurrentRequestsPerModel metric, avoiding the hidden failur
Matched fieldsBody