English translation is being prepared.
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
PyTorch 2.15 adds FP8 support to the MPS backend and makes MoE model decoding 5–6.5 times faster than 2.14: on an M3 Ultra with torch.compile, Qwen3.6-35B-A3B goes from 9.4 tokens/s to 61.3 tokens/s, and LFM2.5-8B-A1B goes from 23.6 to 123.6 tokens/s. For Wan2.2's tiled VAE video decoding, peak driver memory drops from about 270 GiB to 8 GiB, and the image corruption issue with Qwen-Image-2.1's VAE encoding on MPS is also fixed with a padding change, raising the encode-decode round-trip PSNR from 10.06 dB to 29.95 dB. This version requires macOS 15 or later and Python 3.11 or later.
PyTorch 2.15 adds FP8 support to the MPS backend and makes MoE model decoding 5–6.5 times faster than 2.14: on an M3 Ultra with torch.compile, Qwen3.6-35B-A3B goes from 9.4 tokens/s to 61.3 tokens/s, and LFM2.5-8B-A1B goes from 23.6 to 123.6 tokens/s. For Wan2.2's tiled VAE video decoding, peak driver memory drops from about 270 GiB to 8 GiB, and the image corruption issue with Qwen-Image-2.1's VAE encoding on MPS is also fixed with a padding change, raising the encode-decode round-trip PSNR fro
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Matched fieldsSummary
Viggle has released JST-2, building its entire model stack in 3D space and representing the world with Physics-Native Tokens that carry xyz coordinates, attribute vectors, and dynamics vectors, rather than implicitly inferring physical laws from video pixels. The architecture consists of three parts: the JST encoder, JST generator, and JST decoder. A single forward inference generates a complete 3D scene in about 1 second, at a cost below $0.01 (B200), and supports up to 64 input views as a spatial context window. Blind human preference tests published by Viggle show that character generation wins 58.4% against Meshy 7.1 and 73.2% against Tripo H3.1, while video-generated motion wins 89.1% against DeepMotion. JST-3 plans to extend the learned dynamics to object interaction.
Viggle has released JST-2, building its entire model stack in 3D space and representing the world with Physics-Native Tokens that carry xyz coordinates, attribute vectors, and dynamics vectors, rather than implicitly inferring physical laws from video pixels. The architecture consists of three parts: the JST encoder, JST generator, and JST decoder. A single forward inference generates a complete 3D scene in about 1 second, at a cost below $0.01 (B200), and supports up to 64 input views as a spat
Matched fieldsSummary、Body
Grok Bot 0.71.2 is released with smarter notifications; a single message supports up to 20 files, with a file limit of 250 MB (1 GB for video); forms can be pre-filled. The author says there are more updates to come.
Matched fieldsSummary、Body
Hao AI Lab announced the launch of the all-new FastVideo FastH3-QAD-v2 and the H3 NVFP4 VAE decoder. The team said this 768p video was generated on two DGX Sparks using QAD-v2 and the two new decoders, with 8-step video and audio generation, and using QAD weights.
Matched fieldsSummary、Body
Suno posted an introduction to three features in Studio 2.0 that users may have missed, along with a video demonstration.
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary、Body
AI chip startup Tenstorrent has completed a $1.5 billion funding round at a valuation of $6.2 billion, more than double its $2.6 billion valuation at the end of 2024. The round was led by Trace Capital and Innovation X, with participation from Cadence Ventures, Eclipse, Fidelity, SanDisk, and T. Rowe Price. CEO Jim Keller said the company decided to remain independent and continue raising funds after demonstrating that its Galaxy servers can run DeepSeek models, and that the new capital will be used to expand chips for open-weight model inference and video generation.
AI chip startup Tenstorrent has completed a $1.5 billion funding round at a valuation of $6.2 billion, more than double its $2.6 billion valuation at the end of 2024. The round was led by Trace Capital and Innovation X, with participation from Cadence Ventures, Eclipse, Fidelity, SanDisk, and T. Rowe Price. CEO Jim Keller said the company decided to remain independent and continue raising funds after demonstrating that its Galaxy servers can run DeepSeek models, and that the new capital will be
Matched fieldsSummary、Body
Matched fieldsSummary
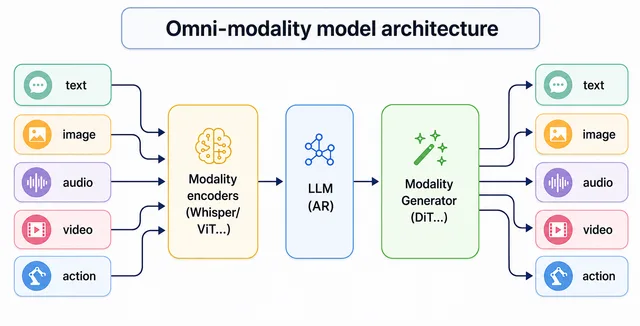
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Viggle AI has released JST-2, calling it the world's first full-stack physics-native world foundation model. Rather than learning in pixel or video space, the model builds its entire model stack in 3D space from first principles, can generate 3D scenes in seconds and extend them in real time, and can also create characters with their own motions through the same general architecture.
Matched fieldsSummary、Body
Chroma Awards, the global AI creative competition incubated by ElevenLabs, has opened registration for its second season, featuring five tracks—film, music video, advertising, games, and behind-the-scenes—with a deadline of January 1, 2027. This season offers over $450,000 in cash prizes and travel benefits, and adds a new student award; ElevenLabs has also set up a separate $22,000 exclusive prize for works using tools such as ElevenCreative and ElevenMusic. In its first season, more than 5,550 creators from 122 countries submitted over 6,600 projects.

Chroma Awards, the global AI creative competition incubated by ElevenLabs, has opened registration for its second season, featuring five tracks—film, music video, advertising, games, and behind-the-scenes—with a deadline of January 1, 2027. This season offers over $450,000 in cash prizes and travel benefits, and adds a new student award; ElevenLabs has also set up a separate $22,000 exclusive prize for works using tools such as ElevenCreative and ElevenMusic. In its first season, more than 5,550
Matched fieldsSummary、Body
ElevenLabs has released a speech-to-text workflow guide for content creators, covering how to use speech-to-text to generate video captions, podcast show notes, searchable content libraries, and content translations. ElevenLabs Caption Generator can generate transcripts with word-level and character-level timestamps and export SRT and VTT files; the Scribe v2 model transcribes verbatim by default, and you can enable "Clean Transcript" in the Playground or switch to cleaned transcription via the no_verbatim parameter in the ElevenAPI.

ElevenLabs has released a speech-to-text workflow guide for content creators, covering how to use speech-to-text to generate video captions, podcast show notes, searchable content libraries, and content translations. ElevenLabs Caption Generator can generate transcripts with word-level and character-level timestamps and export SRT and VTT files; the Scribe v2 model transcribes verbatim by default, and you can enable "Clean Transcript" in the Playground or switch to cleaned transcription via the
Matched fieldsSummary、Body