English translation is being prepared.
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
According to Reuters, three major Chinese internet companies have collectively ordered more than 3 million NVIDIA RTX PRO 5500 workstation graphics cards. At a list price of about $11,400, the potential value exceeds $35 billion. NVIDIA has told partners that global production of the card in 2027 may not exceed 3 million units, and actual deliveries may be only 5% to 10%. The card uses the same GB202 chip as the RTX 5090, with memory increased from 32GB to 84GB, bandwidth reduced from about 1792GB/s to 1398GB/s, and support for MIG partitioning; it is mainly aimed at AI inference. Total orders from Chinese customers have exceeded 6 million units. The major companies placed orders early to secure priority supply given limited GB202 production capacity.
According to Reuters, three major Chinese internet companies have collectively ordered more than 3 million NVIDIA RTX PRO 5500 workstation graphics cards. At a list price of about $11,400, the potential value exceeds $35 billion. NVIDIA has told partners that global production of the card in 2027 may not exceed 3 million units, and actual deliveries may be only 5% to 10%. The card uses the same GB202 chip as the RTX 5090, with memory increased from 32GB to 84GB, bandwidth reduced from about 1792
Matched fieldsSummary、Body
Matched fieldsSummary、Body
MiniMax claimed the anonymous model Space Bunny on October 19 and officially released M3.1 Flash, which uses a sparse attention architecture with 428B total parameters and about 23B activated, nearly 3x faster inference, 70% lower usage cost, and pricing of 1 yuan per million input tokens, 4 yuan for output, and 0.1 yuan for cache reads. Model weights will be open-sourced on October 23, and the official announcement previews a Pro version with a higher intelligence ceiling coming soon. The author replaced the community-viral cases with four new questions of the same type for retesting, and believes its frontend Coding capabilities improved noticeably while retaining the self-verification behavior of proactively opening a browser to trial and error.
MiniMax claimed the anonymous model Space Bunny on October 19 and officially released M3.1 Flash, which uses a sparse attention architecture with 428B total parameters and about 23B activated, nearly 3x faster inference, 70% lower usage cost, and pricing of 1 yuan per million input tokens, 4 yuan for output, and 0.1 yuan for cache reads. Model weights will be open-sourced on October 23, and the official announcement previews a Pro version with a higher intelligence ceiling coming soon. The autho
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Matched fieldsSummary
Yuchen Jin, citing data disclosed by DeepSeek, said that a single cluster currently processes 155 trillion tokens per day and generates $38 in revenue per GPU-hour (off-peak pricing). He noted that DeepSeek has not only open-sourced its inference engine but also disclosed revenue figures, though it did not specify which GPU models were used; DeepInfer supports both NVIDIA Blackwell and Huawei Ascend. Based on an estimated B300 rental price of $7 per GPU-hour, the gross margin is approximately 82%.
Yuchen Jin, citing data disclosed by DeepSeek, said that a single cluster currently processes 155 trillion tokens per day and generates $38 in revenue per GPU-hour (off-peak pricing). He noted that DeepSeek has not only open-sourced its inference engine but also disclosed revenue figures, though it did not specify which GPU models were used; DeepInfer supports both NVIDIA Blackwell and Huawei Ascend. Based on an estimated B300 rental price of $7 per GPU-hour, the gross margin is approximately 82
Matched fieldsSummary、Body
Gradium open-sources the Phonon on-device speech synthesis model suite, with all models under 50m parameters, focused on multilingual naturalness and accuracy, and claims to offer the broadest inference support to date. Phonon-31m is released under the Apache 2.0 license. Matt Turck reposted this news.
Matched fieldsSummary
Matched fieldsSummary
Perplexity announced that Perplexity Computer can now run fully locally on Mac, with both the model and the agent executing on the device, so tasks can be processed without sending sensitive data to the cloud. The feature is now available in the Perplexity Mac app, and Aravind Srinivas added that it can be used without an internet connection and without relying on cloud inference.
Matched fieldsSummary、Body
Matched fieldsSummary
Matched fieldsSummary
i14 partnered with AWS to train and deploy Laplace 3B, based on Gated Linear Attention, on AWS Trainium2 using TorchNeuron Native. A single trn2.48xlarge achieves a training throughput of about 120,000 tokens/s. The model's recurrent state per sequence is fixed at 29.5 MB and does not grow with context length; inference reaches 11,544 output tokens/s at 1,280 concurrent sequences. The team also reworked Muon's all_to_all communication to cut per-GPU communication volume by 24x and raise training throughput by 1.63x.
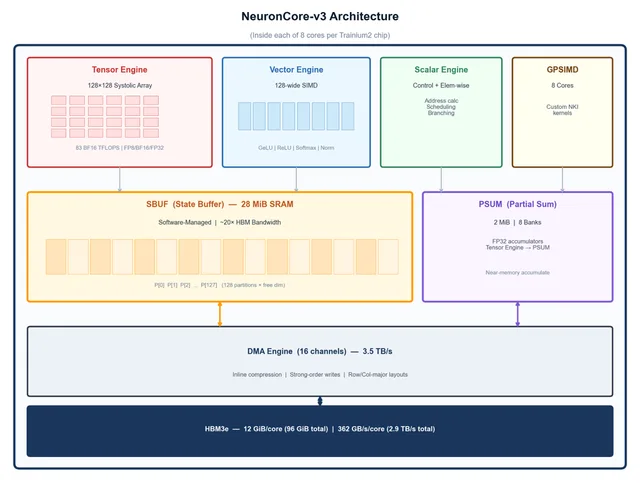
i14 partnered with AWS to train and deploy Laplace 3B, based on Gated Linear Attention, on AWS Trainium2 using TorchNeuron Native. A single trn2.48xlarge achieves a training throughput of about 120,000 tokens/s. The model's recurrent state per sequence is fixed at 29.5 MB and does not grow with context length; inference reaches 11,544 output tokens/s at 1,280 concurrent sequences. The team also reworked Muon's all to all communication to cut per-GPU communication volume by 24x and raise training
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Matched fieldsSummary
Matched fieldsSummary
Gemini's Personal Intelligence feature is beginning to roll out to Android Auto; once enabled, it can connect to user data in Gmail, Google Calendar, Google Photos and Google Search to provide more personalized answers. The feature is entirely opt-in in Gemini settings, and in the coming months it will also arrive on built-in Google cars that run Google's in-car system directly. Karan Daryanani, a senior Google product manager, said the feature's two core capabilities are extracting specific details from emails, photos or saved places in Google Maps, and reasoning across complex sources.
Gemini's Personal Intelligence feature is beginning to roll out to Android Auto; once enabled, it can connect to user data in Gmail, Google Calendar, Google Photos and Google Search to provide more personalized answers. The feature is entirely opt-in in Gemini settings, and in the coming months it will also arrive on built-in Google cars that run Google's in-car system directly. Karan Daryanani, a senior Google product manager, said the feature's two core capabilities are extracting specific det
Matched fieldsSummary、Body
ElevenLabs has released Eleven Realtime, offering two hosted voice agent models, Mini and Max, which integrate speech recognition, reasoning, turn-taking, and speech generation, but developers cannot individually select or configure the underlying models. Data from external testing organization Artificial Analysis shows that Max scored 98.8% on Big Bench Audio, while Mini scored 75.9%; for tool-calling task completion, Max reached 87.1% and Mini 60.3%, while Mini slightly outperformed Max on Full-Duplex-Bench with 95.8% versus 94.1%. The interface follows the OpenAI Realtime API protocol and WebSocket transport, but only supports WebSocket; WebRTC applications must first switch transport methods and handle the capture and playback of 24kHz PCM16 audio themselves.
ElevenLabs has released Eleven Realtime, offering two hosted voice agent models, Mini and Max, which integrate speech recognition, reasoning, turn-taking, and speech generation, but developers cannot individually select or configure the underlying models. Data from external testing organization Artificial Analysis shows that Max scored 98.8% on Big Bench Audio, while Mini scored 75.9%; for tool-calling task completion, Max reached 87.1% and Mini 60.3%, while Mini slightly outperformed Max on Ful
Matched fieldsSummary、Body
Matched fieldsSummary