←Search results

By relevance · Total 2782 results Clear search

Tuesday

  1. MacRumors Apple Intelligence

    Apple FY2026 Q4 Earnings Call: iPhone Duo Demand Outstrips Supply, Siri AI to Have Usage Caps

    On Apple's FY2026 Q4 earnings call, CEO John Ternus said demand for the iPhone Duo cannot be met and that the timing for supply to balance is undetermined, and confirmed that usage caps will be set for server-side AI features such as Siri AI, with paid expansion required beyond the limit. In the quarter, iPhone revenue was $57.6 billion, up 17% year over year; Mac revenue was $10.8 billion; Services revenue reached a record high of $31.6 billion; and Greater China revenue grew 21%, setting a quarterly record. Apple called memory costs "unprecedented," expects them to rise further in the December quarter, and forecasts revenue growth of 7% to 10% year over year for the current quarter.

    On Apple's FY2026 Q4 earnings call, CEO John Ternus said demand for the iPhone Duo cannot be met and that the timing for supply to balance is undetermined, and confirmed that usage caps will be set for server-side AI features such as Siri AI, with paid expansion required beyond the limit. In the quarter, iPhone revenue was $57.6 billion, up 17% year over year; Mac revenue was $10.8 billion; Services revenue reached a record high of $31.6 billion; and Greater China revenue grew 21%, setting a qua

    Matched fieldsBody
  2. NVIDIA Developer · Generative AISelected

    NVIDIA Open-Sources NVIDIA Recovery to Automatically Recover Distributed Training Jobs on Clusters

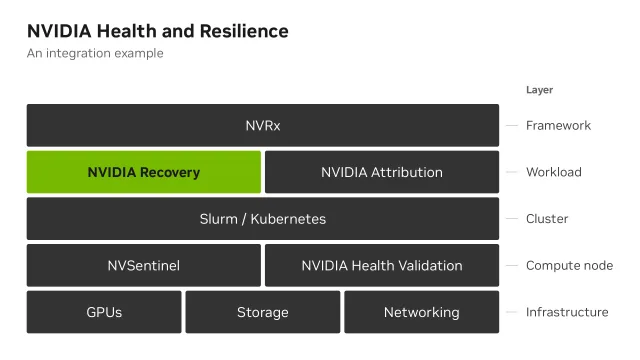
    NVIDIA has released NVIDIA Recovery, an open-source workload-level recovery service that detects training interruptions through application logs, GPU metrics, and scheduler signals, and handles them in a four-stage loop: detection, attribution, isolation, and restart or stop. The service is available under the Apache 2.0 license in the dsx-ai-factory/NVIDIA-Recovery repository. Slurm integration is implemented through an Advisor Controller deployed via a Helm chart, supporting both in-cluster and SSH modes. New deployments default to monitoring mode, which only outputs recovery recommendations without executing scheduling actions; from July 9 to October 9, monitoring on one training cluster covered nearly 200 jobs per day and recorded approximately 8,550 anomaly detections, with average detection and recovery action latencies of 69 seconds and 94 seconds, respectively.

    Five-layer stack diagram showing where NVIDIA Recovery sits in the health and resilience architecture. From the base up: infrastructure, compute node, cluster, workload (where NVIDIA Recovery and NVIDIA Attribution sit), and framework (NVIDIA Resiliency Extension, or NVRx).

    NVIDIA has released NVIDIA Recovery, an open-source workload-level recovery service that detects training interruptions through application logs, GPU metrics, and scheduler signals, and handles them in a four-stage loop: detection, attribution, isolation, and restart or stop. The service is available under the Apache 2.0 license in the dsx-ai-factory/NVIDIA-Recovery repository. Slurm integration is implemented through an Advisor Controller deployed via a Helm chart, supporting both in-cluster an

    Matched fieldsBody

  3. Sierra:Blog

    Sierra Redesigns Agent Studio Around Ghostwriter

    Sierra has redesigned Agent Studio, threading Ghostwriter throughout the entire interface so users can troubleshoot issues, modify journeys, run simulations, and test fixes within the same conversation. Each work item corresponds to a conversation, and changes remain within the conversation until review and merge, with support for sharing and forking; related agents can be grouped into the same project for unified testing and publishing, and it provides line-by-line diffs, Preview Chat, Simulations, and release approval with controlled rollout.

    Ghostwriter

    Sierra has redesigned Agent Studio, threading Ghostwriter throughout the entire interface so users can troubleshoot issues, modify journeys, run simulations, and test fixes within the same conversation. Each work item corresponds to a conversation, and changes remain within the conversation until review and merge, with support for sharing and forking; related agents can be grouped into the same project for unified testing and publishing, and it provides line-by-line diffs, Preview Chat, Simulati

    Matched fieldsBody

  4. NVIDIA Developer · Generative AISelected

    NVIDIA Releases Cosmos Framework and Cosmos NIM, Supporting World Model Training and Deployment

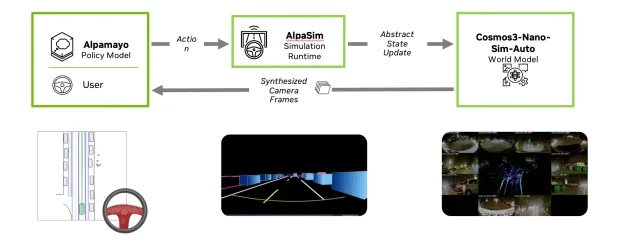
    NVIDIA has released the Cosmos Framework and Cosmos NIM for physical AI. The former provides modular tools and agent skills for training, reinforcement learning, optimization, and inference, while the latter provides accelerated inference services in container form. The Cosmos 3 Nano simulation recipe can generate synchronized camera video and LiDAR observations from released checkpoints, covering autonomous driving, robotics, and surgical scenarios. NIM uses quantization, speculative decoding, and KV-cache-aware routing to achieve a measured speedup of about 2–3x on H200, and Cosmos3-Nano generation tasks require 58 GiB of VRAM under BF16.

    A policy model (e.g., Alpamayo) or user sends an action to the AlpaSim simulation runtime. AlpaSim updates the simulation state and forwards the context to Cosmos3-Nano-Sim-Auto, which synthesizes the next camera frames and returns them to the policy, completing the loop.

    NVIDIA has released the Cosmos Framework and Cosmos NIM for physical AI. The former provides modular tools and agent skills for training, reinforcement learning, optimization, and inference, while the latter provides accelerated inference services in container form. The Cosmos 3 Nano simulation recipe can generate synchronized camera video and LiDAR observations from released checkpoints, covering autonomous driving, robotics, and surgical scenarios. NIM uses quantization, speculative decoding,

    Matched fieldsBody

  5. AWS Machine Learning

    How Circle K Cut DevOps Incident Triage to Under 15 Minutes with Amazon Bedrock

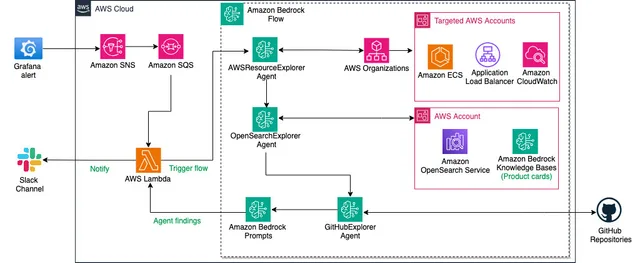
    Circle K built an agentic automated triage system with Amazon Bedrock, reducing average DevOps incident triage time to under 15 minutes—a 67–75% reduction according to internal team metrics. In the system, Grafana alerts trigger AWS Lambda via Amazon SNS and Amazon SQS to invoke Amazon Bedrock Flows, which orchestrates multiple specialized agents in parallel to query logs and infrastructure, and pushes structured summaries to Slack; it has since migrated to Amazon Bedrock AgentCore.

    Amazon Bedrock Flows triage architecture: a Grafana alert flows through Amazon SNS, SQS, and Lambda to parallel agents that post a summary to Slack

    Matched fieldsBody

  6. AWS Machine Learning

    Using Amazon Nova Multimodal Embeddings with Bedrock…

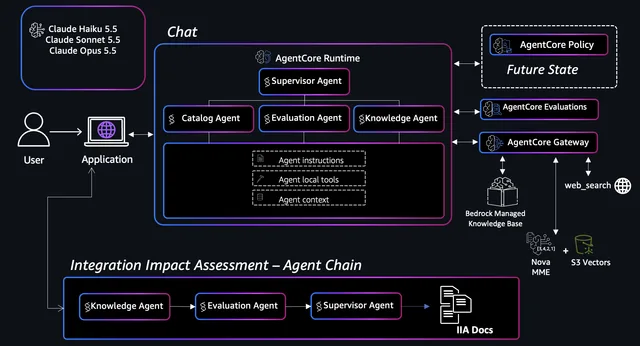
    AWS demonstrated a multi-agent engineering assistant based on Amazon Bedrock AgentCore, Amazon Nova Multimodal Embeddings, and the open-source Strands Agents SDK, designed to reduce manual cross-checking in parts substitution evaluations. In the system, a planner routes tasks to three expert agents—Catalog, Evaluation, and Knowledge—which are respectively responsible for multimodal retrieval, scoring according to Python tolerance rules, and verifying lifecycle information using real-time web data, with a supervisor ultimately aggregating the results. The system only assembles evidence and drafts review documents; it does not itself recommend or approve substitutions, and every evaluation writes an audit record aligned with AS9100 8.4 and 8.5.6.

    Architecture of the multi-agent assistant: a planner routes engineer queries across Catalog, Evaluation, and Knowledge specialists, with a supervisor synthesizing results

    AWS demonstrated a multi-agent engineering assistant based on Amazon Bedrock AgentCore, Amazon Nova Multimodal Embeddings, and the open-source Strands Agents SDK, designed to reduce manual cross-checking in parts substitution evaluations. In the system, a planner routes tasks to three expert agents—Catalog, Evaluation, and Knowledge—which are respectively responsible for multimodal retrieval, scoring according to Python tolerance rules, and verifying lifecycle information using real-time web dat

    Matched fieldsBody

  7. AWS Machine LearningSelected

    Building Efficient Agents with Knowledge Distillation on Amazon SageMaker AI

    An AWS official blog post explains how to fine-tune a shopping agent on Amazon SageMaker AI using sequence-level knowledge distillation (SeqKD): using GLM-5.3 on Amazon Bedrock as the teacher model to generate trajectories, using the ShoppingBench scorer to retain only trajectories that solve the task, and then performing serverless SFT on the Qwen3.5-4B student model. On 324 held-out test questions, the distilled 4B student's average absolute success rate increased from 0.297 to 0.541, essentially on par with the teacher model and mid-sized frontier models; when the teacher's reasoning process was removed and only tool calls were learned, the average success rate dropped to 0.415.

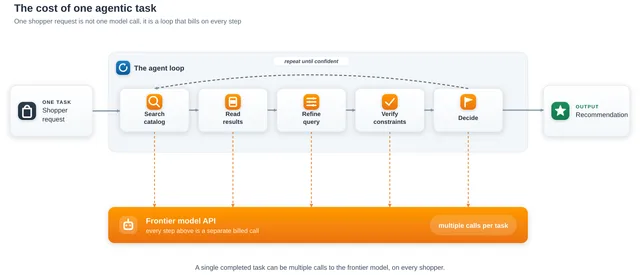
    Diagram of an agentic task as a loop: search, read results, refine, verify, and decide, with each step a separate billed call to the frontier model

    An AWS official blog post explains how to fine-tune a shopping agent on Amazon SageMaker AI using sequence-level knowledge distillation (SeqKD): using GLM-5.3 on Amazon Bedrock as the teacher model to generate trajectories, using the ShoppingBench scorer to retain only trajectories that solve the task, and then performing serverless SFT on the Qwen3.5-4B student model. On 324 held-out test questions, the distilled 4B student's average absolute success rate increased from 0.297 to 0.541, essentia

    Matched fieldsBody

Monday

  1. ElevenLabs Blog

    How is synthetic speech created? A step-by-step guide

    Synthetic speech is generated by neural AI models that analyze and replicate human speech patterns, in a three-step process: collecting real human recording data, training or fine-tuning a model, and then generating audio from text. Modern models sound natural because they replicate human prosody and are context-aware, rather than stitching words together one by one; ElevenLabs' generative TTS can also use instructions such as audio tags to control emotion and pacing.

    Collect voice data, train a model, generate speech; voice design needs no recording.

    Matched fieldsBody

  2. Zyphra ResearchSelected

    Zyphra proposes hierarchical attention ZHA, achieving sub-quadratic complexity sparse attention

    Zyphra proposes hierarchical attention ZHA, which selects relevant tokens for each query by constructing and searching a compressed tree of the KV cache, achieving sub-quadratic complexity under an appropriate top-p threshold. ZHA only requires KL distillation with a few billion tokens to adapt an existing pretrained model, adding only 81,920 trainable parameters on Qwen3.6-35B-A3B; on RULER-13 256K, the wide tree reaches 96.2% and the deep tree 93.3%, on LongBench v2 the deep tree reaches 63.4%, higher than dense attention's 58.0%, and on SWE-bench Verified it is comparable to the dense baseline. Its GPU performance model predicts it is faster than dense attention at about 48K tokens and faster than MSA at about 480K tokens, with roughly 32–35x speedup relative to dense attention at a ten-million-token context.

    Top-p Set Growth Rate is Sublinear

    Zyphra proposes hierarchical attention ZHA, which selects relevant tokens for each query by constructing and searching a compressed tree of the KV cache, achieving sub-quadratic complexity under an appropriate top-p threshold. ZHA only requires KL distillation with a few billion tokens to adapt an existing pretrained model, adding only 81,920 trainable parameters on Qwen3.6-35B-A3B; on RULER-13 256K, the wide tree reaches 96.2% and the deep tree 93.3%, on LongBench v2 the deep tree reaches 63.4%

    Matched fieldsBody

  3. Pydantic AI official article

    Pydantic AI Compares Nine Python Agent Frameworks in 2026

    Pydantic AI officially released a 2026 comparison of Python AI agent frameworks, evaluating nine frameworks item by item against criteria such as model switchability, durable execution after crashes, human approval, frontend and voice integration, MCP, and observability, and giving the applicable scenarios for each. The article states that Pydantic AI supports 30+ model providers, 8 durable execution engines (Temporal, DBOS, Prefect, Restate, AWS Lambda, Absurd, pgtask, Apache Airflow), 5 speech-to-speech providers, and 10 sandboxes, while also noting that it supports only Python, does not offer a hosted platform, and has fewer retrieval-related integrations than LangChain. The comparison also covers LangGraph/LangChain, OpenAI Agents SDK, Google ADK, Microsoft Agent Framework, Strands Agents, CrewAI, Claude Agent SDK, and Agno, and separately lists the two voice frameworks LiveKit Agents and Pipecat.

    Douwe Maan avatar

    Pydantic AI officially released a 2026 comparison of Python AI agent frameworks, evaluating nine frameworks item by item against criteria such as model switchability, durable execution after crashes, human approval, frontend and voice integration, MCP, and observability, and giving the applicable scenarios for each. The article states that Pydantic AI supports 30+ model providers, 8 durable execution engines (Temporal, DBOS, Prefect, Restate, AWS Lambda, Absurd, pgtask, Apache Airflow), 5 speech

    Matched fieldsBody

  4. Databricks Blog

    Lakebase Postgres Generally Available on Google Cloud

    Databricks announced that its fully managed serverless Postgres database, Lakebase Postgres, is generally available on Google Cloud, supporting autoscaling, scale-to-zero, second-level branching, and point-in-time recovery. It shares the same storage layer with analytical data, eliminating the need to maintain ETL pipelines, and provides unified governance through Unity Catalog; multi-availability-zone endpoints offer a 99.99% SLA, while single availability zones offer 99.9%. Lakebase Search delivers 2x the vector and full-text search throughput of pgvector at 4x lower cost.

    Databricks announced that its fully managed serverless Postgres database, Lakebase Postgres, is generally available on Google Cloud, supporting autoscaling, scale-to-zero, second-level branching, and point-in-time recovery. It shares the same storage layer with analytical data, eliminating the need to maintain ETL pipelines, and provides unified governance through Unity Catalog; multi-availability-zone endpoints offer a 99.99% SLA, while single availability zones offer 99.9%. Lakebase Search del

    Matched fieldsBody

  5. LMSYS Blog

    LMSYS explains in detail how HiCache adapts to multi-parallelism and distributed inference

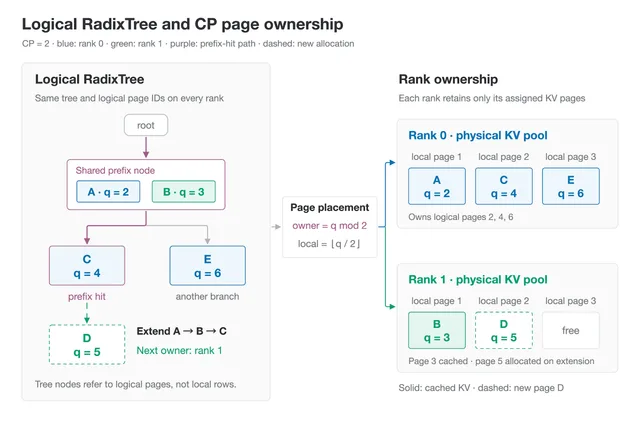
    The LMSYS blog introduces how HiCache is implemented in context parallelism, pipeline parallelism, speculative decoding, unified KV layout, and P/D disaggregation scenarios, with the core being to keep cache decisions consistent across ranks. The iFlytek Spark MaaS team used HiCache plus external storage to serve GLM-5.1/5.2 CodingPlan workloads, raising the cache hit rate from about 30% to 95% and reducing median TTFT to under 3 seconds. In CP sharding tests, the GPU token hit rate increased by 40.48 percentage points, the host memory serving token volume dropped by 81.2%, and the average prefill queueing time decreased by 56.2%.

    A logical radix tree shared by two CP ranks: logical page IDs map to rank 0 or rank 1 by q mod 2, and extending the A/B/C prefix allocates page D on rank 1.

    The LMSYS blog introduces how HiCache is implemented in context parallelism, pipeline parallelism, speculative decoding, unified KV layout, and P/D disaggregation scenarios, with the core being to keep cache decisions consistent across ranks. The iFlytek Spark MaaS team used HiCache plus external storage to serve GLM-5.1/5.2 CodingPlan workloads, raising the cache hit rate from about 30% to 95% and reducing median TTFT to under 3 seconds. In CP sharding tests, the GPU token hit rate increased by

    Matched fieldsBody

  6. Google Blog

    Google's October AI Update: Gemini 4 Argon Launches Globally, Gemini 4…

    In October, Google launched its frontier reasoning model Gemini 4 Argon globally, covering Google AI Studio, the Gemini API, Google Cloud, Search, and the Gemini app. Two weeks later, it announced Gemini 4 Carbon, focused on long-horizon engineering and cybersecurity defense, which is currently undergoing pre-release testing with the U.S. government and select trusted cybersecurity parties through the Fairwind Program. In the same period, it released Genie 4, a real-time interactive world model that supports native audio and natural-language scene control; SynthID Detector opened globally in English and can identify AI content from partners such as OpenAI, NVIDIA, Kakao, and Apple.

    Text with a rainbow colored gradient "The big picture"

    In October, Google launched its frontier reasoning model Gemini 4 Argon globally, covering Google AI Studio, the Gemini API, Google Cloud, Search, and the Gemini app. Two weeks later, it announced Gemini 4 Carbon, focused on long-horizon engineering and cybersecurity defense, which is currently undergoing pre-release testing with the U.S. government and select trusted cybersecurity parties through the Fairwind Program. In the same period, it released Genie 4, a real-time interactive world model

    Matched fieldsBody

  7. Figma AI / Agent / Make

    How Figma brought Hello Kitty and Friends into FigJam

    Figma partnered with Sanrio to launch Hello Kitty and Friends in FigJam for one week starting November 1. Users can choose one of 12 Sanrio characters to join brainstorming, and each character comes with its own cursor, washi tape, and sticky note theme. The team used Figma Motion to create the loading animation and used Figma agent to complete batch edits; a free Hello Kitty birthday pop-up event will also be held in New York from November 6–8.

    Three vertical panels showing tightly cropped views of Keroppi, My Melody, and Hello Kitty against green, pink, and red backgrounds, with matching character-themed cursors and name labels.

    Matched fieldsBody

  8. Trail of Bits BlogSelected

    Trail of Bits uses Codex to backport security patches for stable Linux, covering 149 CVEs

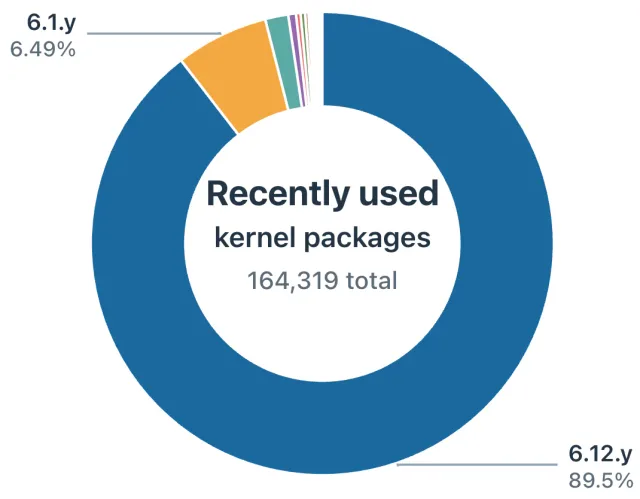
    Trail of Bits used Codex together with GPT-5.6 to backport security patches for the stable Linux kernel and distributions. As of October 29, it had delivered fixes for 149 CVEs to stable kernel branches, plus several Fedora and Ubuntu package fixes. In its workflow, the agent identifies missing fixes, adapts patches, assembles verification evidence, runs tests, and prepares submission materials, while engineers review and submit them to maintainers; excluding initial project setup, a simple backport requires about 30 minutes of human effort, and complex cases about 3 hours. The authors also provide the number of CVEs fixed in newer versions but not backported in each stable branch of the Linux kernel and in Debian 13 and Ubuntu 26.04, and note that regression testing and maintainer acceptance remain necessary steps.

    “A Codex-generated graph of recently installed kernel packages from Debian’s popcon”

    Trail of Bits used Codex together with GPT-5.6 to backport security patches for the stable Linux kernel and distributions. As of October 29, it had delivered fixes for 149 CVEs to stable kernel branches, plus several Fedora and Ubuntu package fixes. In its workflow, the agent identifies missing fixes, adapts patches, assembles verification evidence, runs tests, and prepares submission materials, while engineers review and submit them to maintainers; excluding initial project setup, a simple back

    Matched fieldsBody

  9. sspai

    Paid Morning Brief: Apple Intelligence to Launch in China with iOS 27.3, Claude Code Plugin Found with Implanted Backdoor

    Apple announced that core Apple Intelligence features will be rolled out to Chinese users in December with the official release of iOS 27.3, with developer testing opening first on November 4, and confirmed a partnership with Alibaba to integrate the Qwen large model to provide support for Siri, writing tools, and more. A Claude Code plugin (version 2.1.313) in the Cursor extension marketplace that falsely used Anthropic's official name was listed for about 11 hours, affecting as many as 5,000 developers, and attempted to implant a persistent SSH backdoor. Anthropic said its internal systems and official distribution channels were not compromised.

    Apple announced that core Apple Intelligence features will be rolled out to Chinese users in December with the official release of iOS 27.3, with developer testing opening first on November 4, and confirmed a partnership with Alibaba to integrate the Qwen large model to provide support for Siri, writing tools, and more. A Claude Code plugin (version 2.1.313) in the Cursor extension marketplace that falsely used Anthropic's official name was listed for about 11 hours, affecting as many as 5,000 d

    Matched fieldsBody

Sunday

  1. Sakana AI:Blog

    Sakana AI Holds Tokyo Workshop: Jürgen Schmidhuber Discusses the AI Journey…

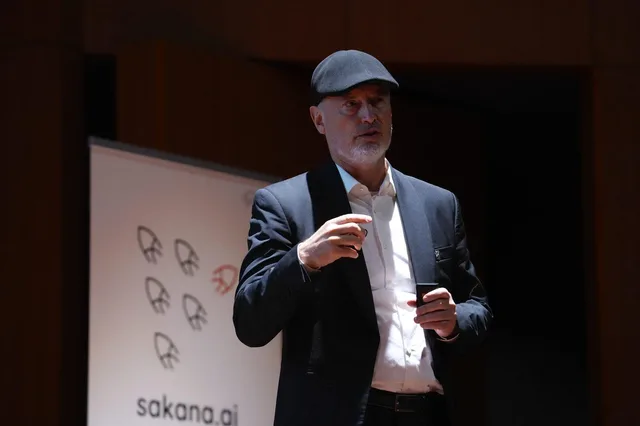
    Sakana AI held a workshop at Hitotsubashi Hall in Tokyo, announcing the launch of its in-house pretrained language model series "Sakana Sawara (tentative name)," with the first model, Sawara Small (tentative name), planned for release in spring 2027. Chief Scientific Advisor Jürgen Schmidhuber gave a keynote speech and held a conversation with CEO David Ha; the event attracted more than 400 attendees from across Japan. Sakana AI frames AI sovereignty around three pillars: pretraining, post-training, and orchestration, with the latter two corresponding to Sakana Namazu and Sakana Fugu, respectively.

    Sakana AI held a workshop at Hitotsubashi Hall in Tokyo, announcing the launch of its in-house pretrained language model series "Sakana Sawara (tentative name)," with the first model, Sawara Small (tentative name), planned for release in spring 2027. Chief Scientific Advisor Jürgen Schmidhuber gave a keynote speech and held a conversation with CEO David Ha; the event attracted more than 400 attendees from across Japan. Sakana AI frames AI sovereignty around three pillars: pretraining, post-train

    Matched fieldsBody

  2. TechCrunch AI

    Data centers become a midterm election issue: at a Brooklyn event, almost everyone opposes AI data centers

    At a midterm election event hosted by Newsreel in Brooklyn, AI and data centers became a topic that ran through the entire event; when the host asked "who supports AI data centers," the crowd immediately booed. A Data Center Watch report shows that in the first half of 2026, nearly $200 billion in data center projects were delayed, stalled, or halted due to political and community opposition, and states including Pennsylvania, Georgia, Texas, New York, and Virginia are considering strengthening regulation and transparency. Attendees worried about backroom deals between tech companies and local officials, residents losing control of their communities, and environmental and health risks.

    At a midterm election event hosted by Newsreel in Brooklyn, AI and data centers became a topic that ran through the entire event; when the host asked "who supports AI data centers," the crowd immediately booed. A Data Center Watch report shows that in the first half of 2026, nearly $200 billion in data center projects were delayed, stalled, or halted due to political and community opposition, and states including Pennsylvania, Georgia, Texas, New York, and Virginia are considering strengthening

    Matched fieldsBody

  3. Databricks Blog

    Databricks uses Lakebase branching to create an independent database per PR: a CI/CD practice

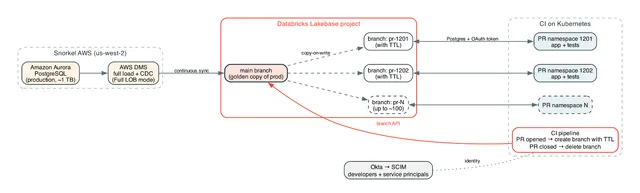
    Databricks describes Snorkel AI's CI/CD solution that uses Lakebase branching to create an independent read-write database for each open PR, reducing branch readiness time from over 30 minutes to under 60 seconds. Branches use copy-on-write; on a production dataset of about 2.5 TB, 100 concurrent PR branches store only 5 to 10 GB of data each for their own changes, and TTL automatically cleans them up after the PR ends. Production data is continuously synchronized to the main branch via AWS DMS; developers log in with Okta SSO, and the CI pipeline authenticates with a service principal and short-lived OAuth tokens.

    image1.png

    Databricks describes Snorkel AI's CI/CD solution that uses Lakebase branching to create an independent read-write database for each open PR, reducing branch readiness time from over 30 minutes to under 60 seconds. Branches use copy-on-write; on a production dataset of about 2.5 TB, 100 concurrent PR branches store only 5 to 10 GB of data each for their own changes, and TTL automatically cleans them up after the PR ends. Production data is continuously synchronized to the main branch via AWS DMS;

    Matched fieldsBody

Saturday

  1. Browser Use

    Browser Use launches BU Ultrafast browser agent: median task time 22 seconds, cost $0.0064

    Browser Use has opened its fastest browser agent, BU Ultrafast, from the waitlist to all Cloud plans in the US, including the free tier. Official data shows a median task time of 22 seconds and a cost of $0.0064 per task, compared with 79 seconds and $0.0098 for the default agent on GPT-6 Luna. To use it, simply set model to bu-ultrafast; if you need more step-by-step reasoning, you can switch to bu-fast from the same agent, which is billed at standard rates.

    BU Ultrafast: a white craft racing over red canyons, median task 22s, $0.006

    Matched fieldsBody