←Search results

By relevance · Total 2748 results Clear search

Wednesday

  1. Google Developers Blog

    Google Agents CLI Launches Extension System: From ADK to LangChain, All Can Plug In

    Starting with version 1.5.0, Google Cloud's Agents CLI introduces an Extension System that allows developers to override or add commands without forking the tool; version 1.8.0 debuts the first LangChain extension, replacing ADK-bound commands with equivalent LangChain implementations. Extensions are declared via agents-cli-extension.yaml in a Git repository and can override built-in commands such as playground, deploy, and eval generate, or add new commands; enterprise platform teams can use this to enforce policies such as SBOM scanning in deployment pipelines.

    1 (2)

    Starting with version 1.5.0, Google Cloud's Agents CLI introduces an Extension System that allows developers to override or add commands without forking the tool; version 1.8.0 debuts the first LangChain extension, replacing ADK-bound commands with equivalent LangChain implementations. Extensions are declared via agents-cli-extension.yaml in a Git repository and can override built-in commands such as playground, deploy, and eval generate, or add new commands; enterprise platform teams can use th

    Matched fieldsBody

  2. Mastra Blog

    Mastra Launches Mastra Observability Managed Platform

    Mastra has released the Mastra Observability managed platform, which can connect directly to Mastra framework projects, automatically trace agent runs, and view the latency, tokens, and cost of model and tool calls. The platform supports online scorers to monitor correctness, team annotation of traces to build evaluation datasets, and running evaluations in CI via Gates and Verdicts to catch regressions. It offers 100k observability events per month free with 15-day retention; beyond that, it costs $10 per 100k events.

    Alex Booker

    Mastra has released the Mastra Observability managed platform, which can connect directly to Mastra framework projects, automatically trace agent runs, and view the latency, tokens, and cost of model and tool calls. The platform supports online scorers to monitor correctness, team annotation of traces to build evaluation datasets, and running evaluations in CI via Gates and Verdicts to catch regressions. It offers 100k observability events per month free with 15-day retention; beyond that, it co

    Matched fieldsBody

  3. Newcomer News feature

    Anduril investor MVP Ventures plans to raise $100M opportunity fund

    MVP Ventures is in talks to raise $100 million to increase its stakes in its best-performing companies. The five-year-old firm has raised two venture funds and made small early-stage investments in Palmer Luckey's Anduril, Erebor, and ModRetro, as well as AI training startup Turing, voice AI company Wispr Flow, and rocket launch startup Stoke Space.

    M. Sriram's avatar

    Matched fieldsBody

  4. Jiwei.com

    Meta AI assistant Muse surpasses 10 million US downloads 40 days after launch

    Meta's AI assistant Muse reached 10.2 million downloads in the US within 40 days of launch, with 10.9 million cumulative downloads worldwide, becoming only the 12th app to reach that milestone. Sensor Tower data shows that in October Meta allocated 39% of its total advertising budget to promoting Muse, up from 23% the previous month. Muse's 7-day retention rate in the US is 30% and its 14-day retention rate is 23%, higher than the 19% and 16% averages of competitors such as ChatGPT, Claude, and Grok.

    Meta's AI assistant Muse reached 10.2 million downloads in the US within 40 days of launch, with 10.9 million cumulative downloads worldwide, becoming only the 12th app to reach that milestone. Sensor Tower data shows that in October Meta allocated 39% of its total advertising budget to promoting Muse, up from 23% the previous month. Muse's 7-day retention rate in the US is 30% and its 14-day retention rate is 23%, higher than the 19% and 16% averages of competitors such as ChatGPT, Claude, and

    Matched fieldsBody

  5. Tech.eu

    Swedish legal AI company Legora closes $550 million Series E at an $8.8 billion valuation

    Swedish legal AI company Legora announced the close of a $550 million Series E round at an $8.8 billion valuation, up from $5.6 billion at its Series D six months earlier. The round was led by new investor Atreides Management, with new investors including Baron Capital, Capital Group, Fidelity, Glade Brook Capital Partners and JP Morgan participating, while existing investors such as Accel, Benchmark and Bessemer Venture Partners continued to follow on. Legora said its technology is shifting from an AI assistant to an AI agent capable of executing multi-step tasks; in-house legal teams accounted for more than 40% of new customers added in the third quarter, the United States has become its largest market, and the new funding will be used for expansion in North America, Europe and Asia-Pacific as well as investment in its agent operating system.

    Swedish legal AI company Legora announced the close of a $550 million Series E round at an $8.8 billion valuation, up from $5.6 billion at its Series D six months earlier. The round was led by new investor Atreides Management, with new investors including Baron Capital, Capital Group, Fidelity, Glade Brook Capital Partners and JP Morgan participating, while existing investors such as Accel, Benchmark and Bessemer Venture Partners continued to follow on. Legora said its technology is shifting fro

    Matched fieldsBody

  6. heise online

    Nvidia launches Open Agent Safety Platform, using BlueField-4 DPU to monitor agents

    At GTC Berlin, Nvidia launched the Open Agent Safety Platform, adding hardware-level controls around the open-source runtime OpenShell; a BlueField-4 DPU works with Sentry software to independently monitor agent behavior and, when it crosses boundaries, isolate and stop it within milliseconds. OpenShell supports third-party agent frameworks such as Anthropic's Claude Code and OpenAI's Codex, and Nvidia says more than 100 organizations already use the platform's technology. Nvidia also introduced the Agent Knowledge Foundation and the Auto-Ontology library, designed to let agents access structured and unstructured data without enterprise data leaving local premises, and expanded its Nemotron 3.5 Super VL, Nemotron 3.5 Bolt 74B-A9B and Kumo series models.

    At GTC Berlin, Nvidia launched the Open Agent Safety Platform, adding hardware-level controls around the open-source runtime OpenShell; a BlueField-4 DPU works with Sentry software to independently monitor agent behavior and, when it crosses boundaries, isolate and stop it within milliseconds. OpenShell supports third-party agent frameworks such as Anthropic's Claude Code and OpenAI's Codex, and Nvidia says more than 100 organizations already use the platform's technology. Nvidia also introduced

    Matched fieldsBody

  7. Google Blog

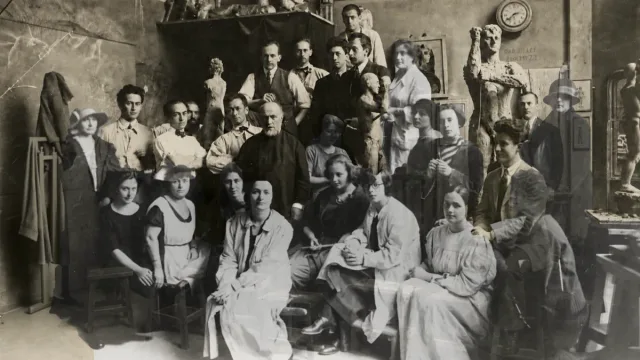
    Google AI and Prune Nourry Recreate Lost Workshops of Women Sculptors

    Artist Prune Nourry, in collaboration with Google Arts & Culture, used Google generative AI and image editing models to reconstruct the lost workshops of 19th-century Parisian women sculptors such as Nancy Elizabeth Prophet, Jane Poupelet, and Camille Claudel, and built a custom tool based on Gemini to generate walkable 3D models from archival photographs. The project is accompanied by a 10-minute documentary honoring 18 women sculptors overlooked by art history. The "Visionaries" exhibition will be on view at the Petit Palais in Paris from October 20, 2026, to January 30, 2027.

    A historical black-and-white photo depicting a group of art students and instructors gathered in a sculpture studio surrounded by statues, busts, and tools.

    Artist Prune Nourry, in collaboration with Google Arts & Culture, used Google generative AI and image editing models to reconstruct the lost workshops of 19th-century Parisian women sculptors such as Nancy Elizabeth Prophet, Jane Poupelet, and Camille Claudel, and built a custom tool based on Gemini to generate walkable 3D models from archival photographs. The project is accompanied by a 10-minute documentary honoring 18 women sculptors overlooked by art history. The "Visionaries" exhibition wil

    Matched fieldsBody

  8. Latent Space

    How Claude Mods Flip Claude Code's Agent Framework into a Human-Facing Attention Interface

    Writing in Latent Space, author Dan McAteer introduces Claude Mods: TypeScript or JavaScript plugins that run inside Claude Code, respond to events such as prompts, tool calls, and interface rendering, and change execution and rendering behavior in the CLI and on desktop. Anthropic has built in six mods, including the you-should-know side agent, which is off by default; the author also built a Next Steps Supervisor on top of his own ModSmith. The article compares Claude Mods with ChatGPT's Intelligent UI and Cursor's PR Routing & Approval, noting that the difference among the three lies in who designs the attention interface, and it raises the issues of noise, a cost of roughly 5–6k input-equivalent tokens per check, and trust concerns because mods are not confined by the sandbox.

    Writing in Latent Space, author Dan McAteer introduces Claude Mods: TypeScript or JavaScript plugins that run inside Claude Code, respond to events such as prompts, tool calls, and interface rendering, and change execution and rendering behavior in the CLI and on desktop. Anthropic has built in six mods, including the you-should-know side agent, which is off by default; the author also built a Next Steps Supervisor on top of his own ModSmith. The article compares Claude Mods with ChatGPT's Intel

    Matched fieldsBody

  9. Unite.AI

    NVIDIA Releases Nemotron 3.5 Series of Open Models, Covering Embedding, Reranking, and Document Parsing

    On October 21, 2026, NVIDIA expanded the Nemotron Retriever series, launching Nemotron 3.5 Embed (8B BF16, 1B BF16, 1B NVFP4), Nemotron 3.5 Rerank 8B BF16, and the 631-million-parameter Nemotron 3.5 Parse, aimed at multimodal retrieval and document processing for enterprise agent workflows. NVIDIA says that adding Rerank to the agent retrieval pipeline reduces the token cost per query by about 14% (with the 8B embedding model) and 13% (with the 1B model), respectively, while also improving retrieval accuracy. Parse scores 75.20 on ParseBench and processes 10.5 pages per second on a single H100; the open weights, data, and training recipes have been released on Hugging Face and can be deployed via NVIDIA NIM as well as Baseten, DeepInfra, and FriendliAI.

    On October 21, 2026, NVIDIA expanded the Nemotron Retriever series, launching Nemotron 3.5 Embed (8B BF16, 1B BF16, 1B NVFP4), Nemotron 3.5 Rerank 8B BF16, and the 631-million-parameter Nemotron 3.5 Parse, aimed at multimodal retrieval and document processing for enterprise agent workflows. NVIDIA says that adding Rerank to the agent retrieval pipeline reduces the token cost per query by about 14% (with the 8B embedding model) and 13% (with the 1B model), respectively, while also improving retri

    Matched fieldsBody

  10. Unite.AI

    What Is Distributed AI Training? An Analysis of Data, Tensor, Pipeline, and Expert Parallelism

    Distributed AI training enables models or batches that exceed the capacity of a single device to be trained by coordinating data, parameters, activations, gradients, and optimizer states across multiple accelerators. Its workflow can be broken down into five steps: partitioning the work according to the chosen parallelism strategy, performing local forward and backward computation, communicating the required tensors, synchronizing or pipelining updates, and checkpointing and recovery across nodes. The article points out that simply adding more devices without changing the communication and memory design is a common misconception; network bottlenecks and synchronization failures can waste most of the theoretical compute.

    Distributed AI training enables models or batches that exceed the capacity of a single device to be trained by coordinating data, parameters, activations, gradients, and optimizer states across multiple accelerators. Its workflow can be broken down into five steps: partitioning the work according to the chosen parallelism strategy, performing local forward and backward computation, communicating the required tensors, synchronizing or pipelining updates, and checkpointing and recovery across node

    Matched fieldsBody

  11. heise online

    IBM launches Power Autonomous Operations: manage Power servers through natural language conversation

    IBM's Power Autonomous Operations (PAO) 1.0 became generally available on September 23, 2026. Its built-in AI agent supports querying and managing Power environments running IBM i, AIX, and Linux using natural language. IBM claims it can identify and resolve capacity bottlenecks up to 15 times faster than manual operations; this figure is vendor data. PAO is deployed as a virtual appliance on a PowerVM LPAR or PowerVS and provides more than 40 functions through two MCP servers. It does not currently support directly reading data generated by customer operating systems such as IBM i and AIX.

    IBM's Power Autonomous Operations (PAO) 1.0 became generally available on September 23, 2026. Its built-in AI agent supports querying and managing Power environments running IBM i, AIX, and Linux using natural language. IBM claims it can identify and resolve capacity bottlenecks up to 15 times faster than manual operations; this figure is vendor data. PAO is deployed as a virtual appliance on a PowerVM LPAR or PowerVS and provides more than 40 functions through two MCP servers. It does not curre

    Matched fieldsBody

  12. The New Stack

    Nvidia unveils DSX POD containerized AI factory reference design

    Nvidia announced the DSX POD reference design at GTC Berlin, enabling partners to install Vera Rubin racks, networking, and liquid cooling into containers at the factory before delivery. Each container holds 7 Vera Rubin NVL72 racks, totaling 504 Rubin GPUs, and comes pre-installed with about 20 kilometers of copper cable and 17 kilometers of scale-out networking, weighing about 28 tons; as long as the site already has power, cooling, and networking in place, it can start producing tokens in as little as 14 days. Nvidia says the system's cooling uses no water, Vera Rubin can run on 45 degrees Celsius coolant, and at a 2-gigawatt deployment, dry coolers can save about 54 million liters of water per day compared with cooling towers. Partners will begin global deliveries in early 2027.

    Nvidia announced the DSX POD reference design at GTC Berlin, enabling partners to install Vera Rubin racks, networking, and liquid cooling into containers at the factory before delivery. Each container holds 7 Vera Rubin NVL72 racks, totaling 504 Rubin GPUs, and comes pre-installed with about 20 kilometers of copper cable and 17 kilometers of scale-out networking, weighing about 28 tons; as long as the site already has power, cooling, and networking in place, it can start producing tokens in as

    Matched fieldsBody

  13. The New Stack

    Nvidia adds Agent Knowledge Foundation to Agent Toolkit

    At GTC Berlin, Nvidia added Agent Knowledge Foundation to Agent Toolkit, packaging the Nemotron Retriever models, the new Auto-Ontology library, the Kumo family of models for structured data, and CUDA-X data processing libraries; data remains in place and is managed under enterprises' existing permissions. Nvidia says Nemotron Retriever improved search relevance by 65% in tests in the open-source OpenSearch environment, SAP's fine-tuned reranker runs nearly three times faster, and ServiceNow's reranking delivers better quality with latency reduced by nearly 25%. Auto-Ontology provides a REST API and an MCP server for agents to query, and Nvidia says it does not compete with data platforms such as Snowflake but rather partners with them.

    At GTC Berlin, Nvidia added Agent Knowledge Foundation to Agent Toolkit, packaging the Nemotron Retriever models, the new Auto-Ontology library, the Kumo family of models for structured data, and CUDA-X data processing libraries; data remains in place and is managed under enterprises' existing permissions. Nvidia says Nemotron Retriever improved search relevance by 65% in tests in the open-source OpenSearch environment, SAP's fine-tuned reranker runs nearly three times faster, and ServiceNow's r

    Matched fieldsBody

Thursday

  1. Wired AI

    Recursive Releases Open-Source Coding Model Flint, Says Most of Development Process Was Completed by AI

    Recursive released Flint, its first open-weight coding model, with 40B parameters. CEO Richard Socher said that nearly every stage of the model pipeline was completed by its Eureka Machine system, including a new base training method, the model architecture, and code optimized for specific chips. A WIRED author tested it on a Mac with 48GB of memory, using it to build a command-line to-do app, a web research scraping program, and an RSI educational website, and found its speed and accuracy superior to models of the same size. Recursive has raised $650 million from Google Ventures, Greycroft, Nvidia, and AMD Ventures, at a valuation of $4.65 billion.

    Recursive released Flint, its first open-weight coding model, with 40B parameters. CEO Richard Socher said that nearly every stage of the model pipeline was completed by its Eureka Machine system, including a new base training method, the model architecture, and code optimized for specific chips. A WIRED author tested it on a Mac with 48GB of memory, using it to build a command-line to-do app, a web research scraping program, and an RSI educational website, and found its speed and accuracy super

    Matched fieldsBody

  2. Hugging Face

    Profiling TorchNeuron (Part 1): System-Level Performance Profiling on AWS Trainium

    AWS has released Part 1 of the TorchNeuron profiling guide, which explains how to use NeuronConfig and NeuronProfiler for system-level profiling on AWS Trainium, and how to view system traces, device timelines, and per-engine breakdowns through Neuron Explorer. Taking RMSNorm as an example, a naive PyTorch implementation has a total device time of 2.355 ms, while torch.rms_norm(), fused into a single Neuron kernel, reduces this to 403.3 μs.

    AWS has released Part 1 of the TorchNeuron profiling guide, which explains how to use NeuronConfig and NeuronProfiler for system-level profiling on AWS Trainium, and how to view system traces, device timelines, and per-engine breakdowns through Neuron Explorer. Taking RMSNorm as an example, a naive PyTorch implementation has a total device time of 2.355 ms, while torch.rms norm(), fused into a single Neuron kernel, reduces this to 403.3 μs.

    Matched fieldsBody