人工智能
使用 Strands Agents 的自适应智能体智能框架构建 AI 智能体的组织面临一个共同挑战:每个请求,无论是常规状态检查还是复杂分析,通常都会被路由到单个大型且昂贵的模型。这种“一刀切”的方法会推高 API 成本、引入不可预测的延迟,并消除离线运行的可能性。即便是可以在本地解决的常规查询,最终也需要通过完整的网络往返请求云端托管的大语言模型(LLM)。
使用 Strands Agents 构建的自适应智能体智能框架(AAIF)采用了不同的方法。AAIF 不会将所有请求都路由到单个大型模型,而是使用小型语言模型(SLM)在本地处理常规任务。更复杂的请求则通过 Amazon Bedrock路由到云端托管的模型。这种方法建立在 NVIDIA 的 Belcak 等人的研究立场之上。他们认为,小型语言模型“能力足够强大、本质上更适合,并且对于智能体系统中的许多调用而言必然更经济”。该框架基于 Strands Agents 构建,展示了智能模型编排如何帮助降低成本,同时保持本地操作的低延迟。
在本文中,我们将介绍 AAIF 的关键组件,其中通过 Ollama 使用本地 SLM,并通过 Amazon Bedrock 使用云端模型。我们使用物联网(IoT)监控场景作为参考实现。
解决方案概述
如图 1 所示,AAIF 将 AI 处理组织为三个层,每一层针对不同的任务类型进行优化:
- 智能编排使用轻量级 SLM(llama3.2:1b)作为决策层。该编排器对传入请求进行分类,并将其路由到适当的处理层,而无需硬编码规则。
- 本地处理通过 Ollama在本地硬件上运行的 SLM 来处理设备遥测检索和图像分析等常规任务。这些任务以低延迟完成,且不依赖云端。
- 云端处理通过 Amazon Bedrock 中的前沿模型来处理复杂的模式分析和战略建议。这些请求需要更广泛的上下文和多步推理,而 SLM 无法可靠地提供这些能力。
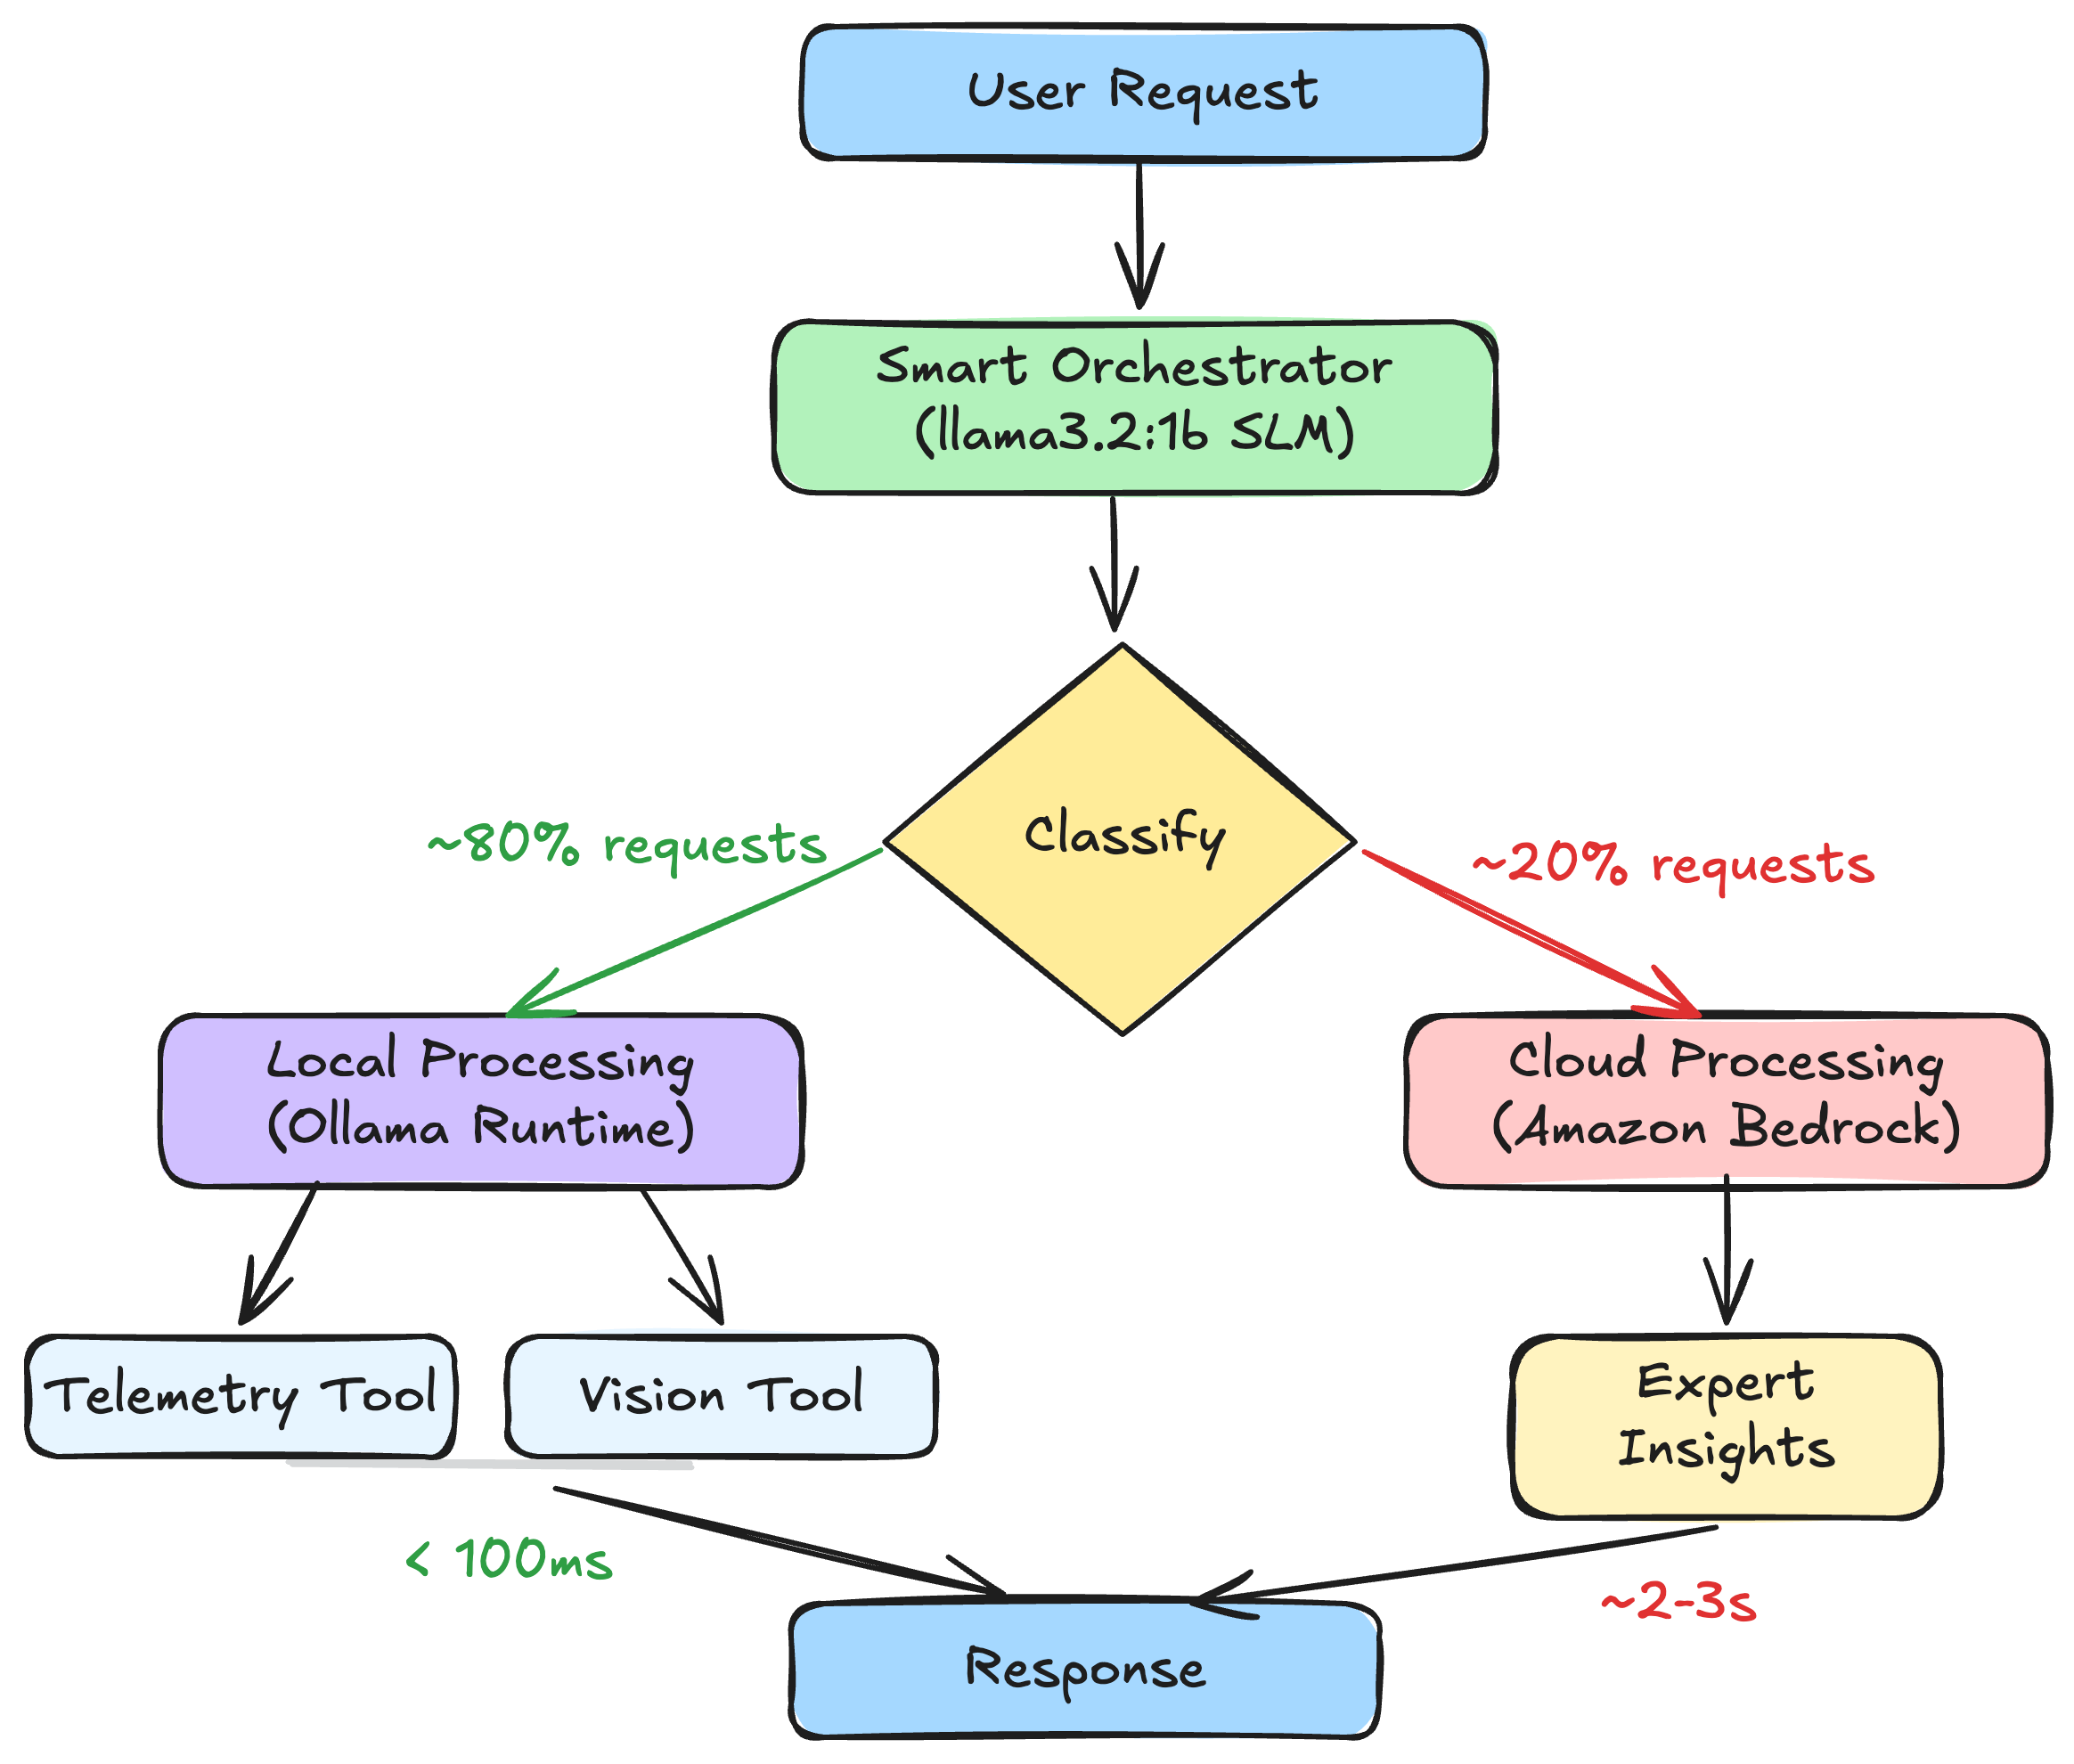
图 1:AAIF 的三个处理层,分别用于智能编排、本地处理和云端处理
图 1 展示了完整的 AAIF 系统架构。中心是 Strands 智能体,它连接到 Ollama 运行时,该运行时同时托管 10 亿参数的编排器模型和视觉模型。该智能体暴露三个工具:get_device_telemetry 用于本地传感器数据检索,analyze_camera_feed 用于通过 llama3.2-vision 进行设备端视觉处理,get_expert_insights 则通过 boto3 调用 Amazon Bedrock 进行复杂分析。传入的用户请求流经 SLM 编排器,后者对每个请求进行分类,并根据任务复杂度将其分派到本地工具或云端端点。
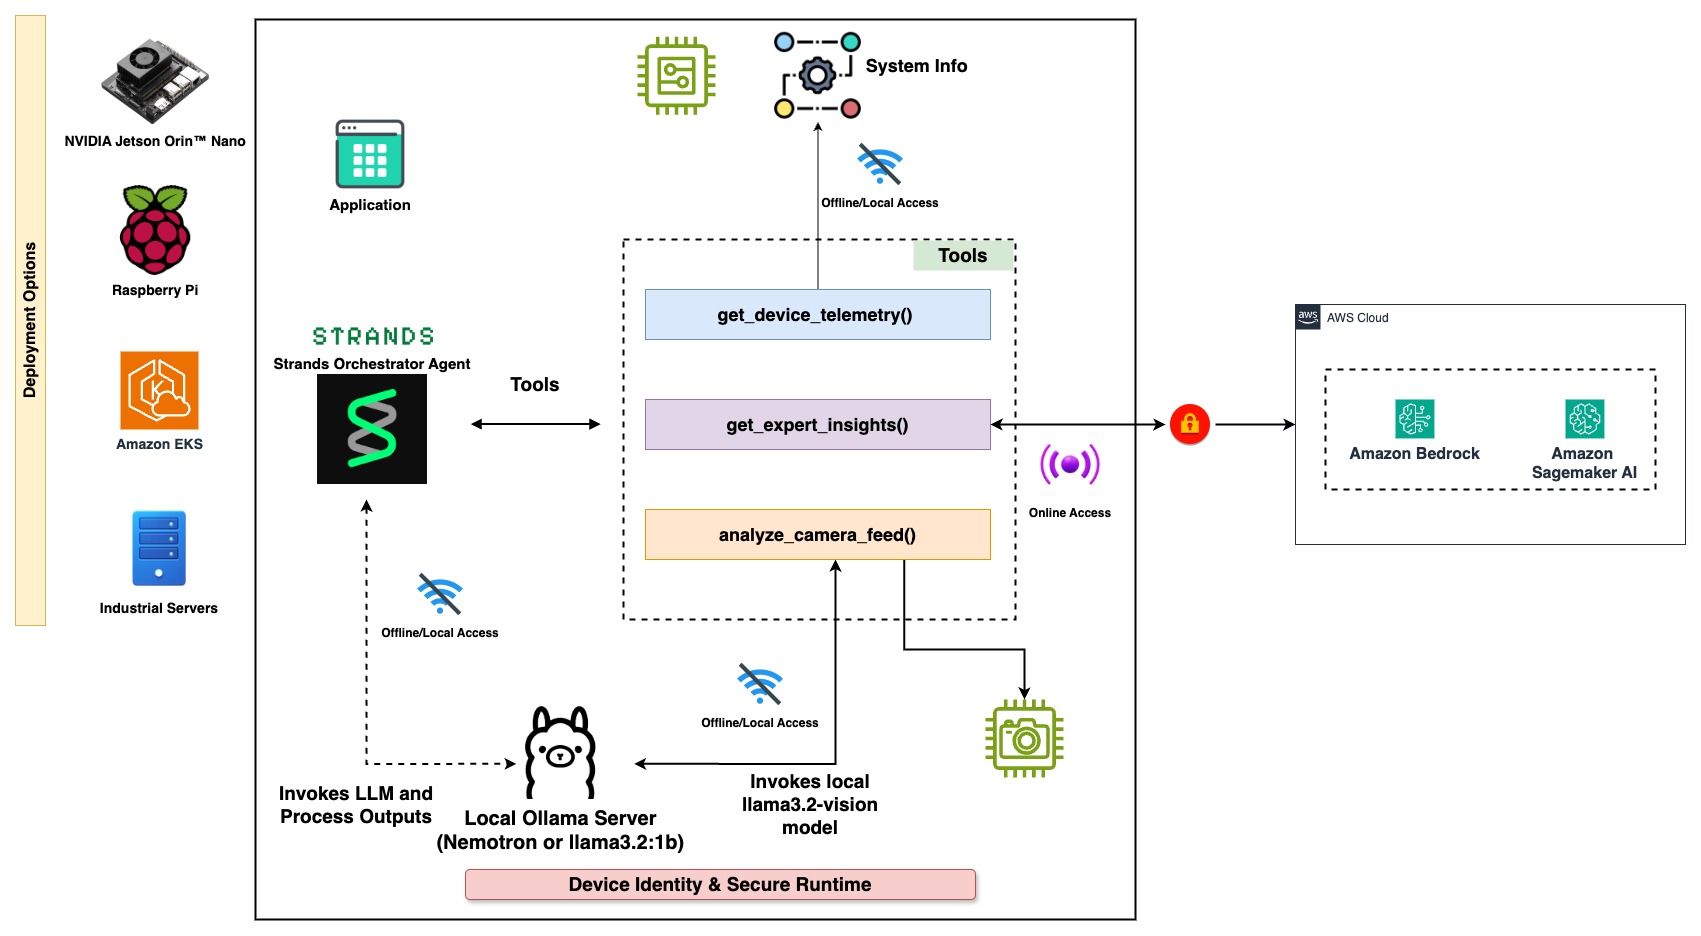
图 2:完整的 AAIF 系统架构,展示了 Strands 智能体、Ollama 运行时、工具集成以及 Amazon Bedrock 连接
The framework adapts to your deployment constraints rather than requiring you to restructure your infrastructure around it. This architecture runs on edge devices like a Raspberry Pi with 8 GB of memory, in full cloud deployments where all inference hits Amazon Bedrock, or in hybrid configurations that combine local speed with cloud reasoning. The flexibility comes from separating the routing logic (the SLM orchestrator) from the processing tools, which you can swap or reconfigure independently depending on available hardware and network connectivity.
Prerequisites
For this walkthrough, you should have the following prerequisites:
- An AWS account.
- Amazon Bedrock model access configured in the required Region.
- Python 3.10+ installed.
- Ollama installed with the following models pulled:
ollama pull llama3.2:1b(orchestrator).ollama pull llama3.2-vision(vision analysis).
- Strands Agents installed:
pip install strands-agents strands-agents-tools. - AWS Command Line Interface (AWS CLI) configured with appropriate credentials.
- Boto3 installed:
pip install boto3.
Set up the environment
Create a project directory and start the Ollama server:
mkdir aaif-demo && cd aaif-demo
ollama serve
Pull the required models:
ollama pull llama3.2:1b
ollama pull llama3.2-vision
Create a file called aaif_agent.py and add the following components.
Implement local processing tools
Strands Agents uses the @tool decorator to define capabilities that agents can invoke. Start by creating tools for local processing.
The first tool retrieves device telemetry data. In a production environment, this would connect to actual IoT sensors. For this walkthrough, it uses simulated device data:
from strands import Agent, tool
import random

DEVICE_TELEMETRY = {
    "sensor-001": {
        "device_type": "Temperature Sensor",
        "location": "Building A - Floor 2",
        "temperature": 72.5,
        "humidity": 45.2,
        "status": "normal"
    },
    "camera-001": {
        "device_type": "Security Camera",
        "location": "Main Entrance",
        "fps": 30,
        "resolution": "1080p",
        "status": "recording"
    },
    "hvac-001": {
        "device_type": "HVAC Controller",
        "location": "Building A - Central",
        "set_temp": 71.0,
        "current_temp": 72.5,
        "mode": "cooling",
        "status": "active"
    }
}

@tool
def get_device_telemetry() -> str:
    """Retrieve current telemetry data from connected IoT devices."""
    device_id = random.choice(list(DEVICE_TELEMETRY.keys()))
    device_data = DEVICE_TELEMETRY[device_id]

    report = f"Device: {device_id} ({device_data['device_type']})\n"
    report += f"Location: {device_data['location']}\n"
    report += f"Status: {device_data['status']}\n"
    for key, value in device_data.items():
        if key not in ['device_type', 'location', 'status']:
            report += f"{key}: {value}\n"
    return report
The second tool performs vision analysis using a local SLM. The llama3.2-vision model runs entirely on local hardware, which means sensitive camera feeds don’t leave the device:
import ollama

@tool
def analyze_camera_feed(image_path: str) -> str:
    """Analyze visual data from cameras using local vision model."""
    stream = ollama.chat(
        model='llama3.2-vision',
        messages=[{
            'role': 'user',
            'content': 'Describe this image in one sentence. '
            'What are the 3 most important things you see?',
            'images': [image_path]
        }],
        stream=True,
    )

    full_response = ""
    for chunk in stream:
        chunk_content = chunk['message']['content']
        print(chunk_content, end='', flush=True)
        full_response += chunk_content

    return f"Object Detection Report:\n{full_response}"
Implement cloud processing
For complex analysis that requires broader reasoning, create a tool that calls Amazon Bedrock. This tool is invoked only when the orchestrator determines that local models can’t handle the request:
import boto3

@tool
def get_expert_insights(context_data: str, question: str) -> str:
    """Get advanced analysis and expert recommendations
    for complex questions via Amazon Bedrock."""
    client = boto3.client("bedrock-runtime", region_name="us-east-1")

    conversation = [
        {
            "role": "user",
            "content": [
                {"text": f"Context: {context_data}\n\nQuestion: {question}"}
            ],
        }
    ]

    response = client.converse(
        modelId="<<model_id>", //Refer model id [details](https://docs.aws.amazon.com/bedrock/latest/userguide/foundation-models-reference.html)
        messages=conversation,
        inferenceConfig={
            "maxTokens": 512,
            "temperature": 0.5,
            "topP": 0.9
        }
    )

    response_text = response["output"]["message"]["content"][0]["text"]
    return f"Expert Analysis:\n{response_text}"
Configure the Strands agent with smart orchestration
The core of AAIF is the Strands agent configuration. The agent uses a local SLM (llama3.2:1b) as its orchestrator. Strands Agents supports multiple model providers, and here we use the Ollama provider to run the orchestrator locally:
from strands.models.ollama import OllamaModel

model = OllamaModel(
    model_id="llama3.2:1b",
    host="http://localhost:11434",
    params={
        "max_tokens": 300,
        "temperature": 0.3,
    },
)

system_prompt = """You are a monitoring assistant for operational facilities.
You have access to device telemetry tools, analysis capabilities,
and expert insights to help monitor operations effectively.

When users ask for:
- Device status or telemetry: use get_device_telemetry
- Image or data analysis: use analyze_camera_feed
- Expert advice or complex questions: use get_expert_insights

Always return the complete tool results directly to the user."""

agent = Agent(
    model=model,
    system_prompt=system_prompt,
    tools=[
        get_device_telemetry,
        analyze_camera_feed,
        get_expert_insights,
    ],
)
The SLM-powered orchestrator analyzes each request and routes it to the appropriate tool without hardcoded keyword matching. The routing happens through the model’s understanding of the request:
| Request | Routing | Latency |
| “Check device status” | Local SLM | Low (local inference) |
| “Analyze this image” | Local vision AI | Low (local inference) |
| “What optimization strategies do you recommend?” | Cloud (Amazon Bedrock) | Higher (network round-trip) |
Table 1: Request, routing, and latency estimates for local compared to cloud inference
Run the agent
With the agent configured, you can interact with it directly:
# Local processing - device telemetry
response = agent("What's the current status of our devices?")
print(response)

# Local processing - vision analysis
response = agent("Analyze the camera feed from camera-001")
print(response)

# Cloud processing - complex analysis
response = agent(
    "Based on current telemetry patterns, "
    "what optimization strategies do you recommend?"
)
print(response)
The agent automatically classifies each request and routes it to the appropriate processing layer. No explicit routing rules are needed.
Adapt to different deployment scenarios
The AAIF architecture adapts to different infrastructure requirements by changing the model configuration:
When your workload runs entirely in the cloud and no edge hardware is available, replace the Ollama model configuration with Amazon Bedrock for all processing. This routes every request through managed cloud inference, giving you auto scaling without requiring local GPU resources. Teams with reliable low-latency connectivity and no data residency constraints benefit most from this configuration:
from strands.models import BedrockModel

model = BedrockModel(
    model_id="<<model_id>", //Refer model id [details](https://docs.aws.amazon.com/bedrock/latest/userguide/foundation-models-reference.html)
    region_name="us-east-1"
)
The hybrid configuration keeps the local SLM orchestrator intact while adding cloud models for requests that exceed local model capabilities. This is the default AAIF configuration shown in this walkthrough. It suits environments where most requests are routine enough to resolve locally, but some require the broader reasoning of a larger model. Cost savings can come from the roughly 80 percent of traffic that doesn’t hit a paid API endpoint.
For environments that are fully air-gapped or have strict data sovereignty requirements, replace the cloud tool with a larger local model and run all processing on-device. A 3B-parameter model running on hardware with adequate memory can handle moderately complex tasks that the 1B orchestrator would otherwise escalate. The trade-off is reduced reasoning depth on the hardest queries, but the benefit is data not leaving the premises:
model = OllamaModel(
    model_id="llama3.2:3b", # Larger local model for complex tasks
    host="http://localhost:11434",
)
Looking ahead: Centralized tool calling with MCP servers
The implementation in this post uses local tool calls defined directly in the agent code. For production deployments with multiple agents sharing tools across services, expose these tools as Model Context Protocol (MCP) servers. MCP provides a standardized interface for tool discovery and invocation, so you can centralize tool management and reuse tools across different agents and environments. In Figure 3, we show how to convert AAIF tools into MCP servers for distributed, centralized tool calling.
In the distributed configuration as shown in Figure 3, Device 1 acts as the orchestrating hub, running the Strands agent with the SLM router and a local telemetry tool. It connects through the MCP protocol to Device 2, which runs an edge vision processing server with llama3.2-vision. Device 3 serves as a cloud analytics gateway connected to Amazon Bedrock. From the orchestrator’s perspective, all remote tools appear as local function calls because the MCP transport layer handles serialization and network communication transparently.
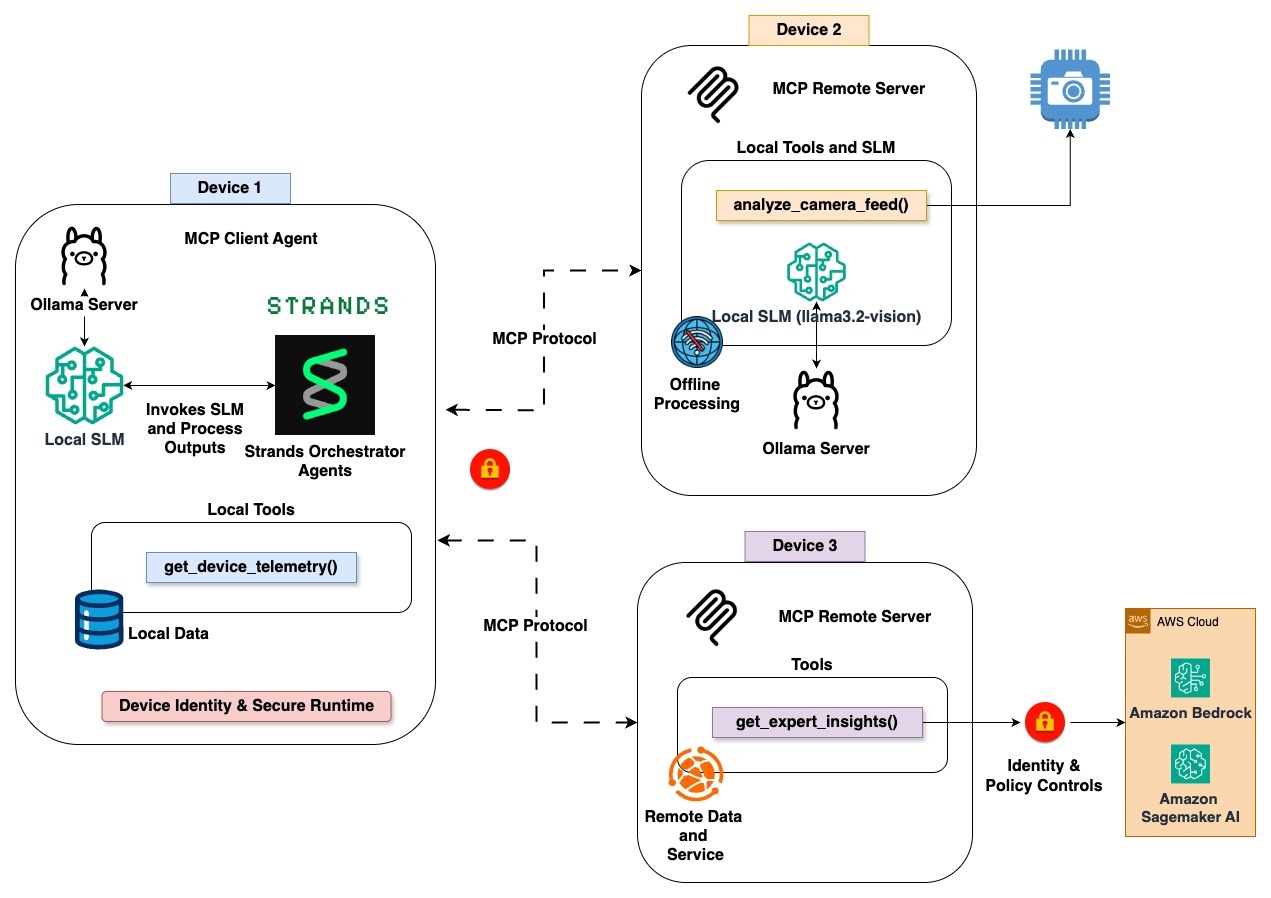
Figure 3: Distributed intelligence with MCP servers
Cleaning up
To avoid incurring future charges, complete the following cleanup steps:
- Disable Amazon Bedrock model access: Open the Amazon Bedrock console, choose Model access, and revoke access for Amazon Nova Lite. For detailed steps, see Manage model access in the Amazon Bedrock User Guide.
- Stop the Ollama server and remove models to free local disk space (approximately 2 GB):
ollama stop ollama rm llama3.2:1b ollama rm llama3.2-vision - Delete the project directory if you no longer need the sample code:
rm -rf aaif-demo
Conclusion
We showed how to build cost-effective AI agents using the Adaptive Agentic Intelligence Framework with Strands Agents. By routing routine requests to local SLMs and reserving cloud models on Amazon Bedrock for complex analysis, AAIF can help reduce API costs while maintaining low latency for routine operations.
Before you run this pattern in production, add responsible AI controls to the cloud inference path, since those requests carry tool outputs, retrieved data, and user input. You can attach Amazon Bedrock Guardrails to the Strands BedrockModel with a guardrail ID and version. It then applies content filters for harmful categories, prompt injection filters, and contextual grounding checks that block responses not supported by the source data. To apply the same policies to the local SLM tier, call the standalone ApplyGuardrail API on its inputs and outputs. This way, every request follows one safety standard no matter which model handles it.
This architectural pattern applies beyond IoT monitoring. A healthcare organization could run patient monitoring locally while routing diagnosis support to cloud models. A financial services firm could process transactions on-premises and reserve cloud capacity for risk analysis. A manufacturing team could run quality control vision models at the edge while sending optimization requests to the cloud.
To learn more about building agents with Strands Agents, visit the Strands Agents documentation. For information about available foundation models, see Amazon Bedrock.