←搜索结果

按匹配度 · 共 289 条结果 清除搜索

星期五

  1. Moonshot AI · Kimi Blog精选

    月之暗面开源 Kimi K2.6,主打长程编码与 Agent Swarm

    月之暗面开源最新模型 Kimi K2.6,具备编码、长程执行和 Agent Swarm 能力,已上线 Kimi.com、Kimi App、API 和 Kimi Code。官方称其在长程编码任务上较 K2.5 明显提升,例如在 Mac 上用 Zig 实现并优化 Qwen3.5-0.8B 推理,经 4000+ 次工具调用、超 12 小时连续执行和 14 轮迭代,吞吐从约 15 tokens/sec 提升到约 193 tokens/sec。Agent Swarm 架构从 K2.5 的 100 个子智能体和 1500 步扩展到 300 个子智能体、4000 步并发执行,并新增 Claw Groups 研究预览。

    Kimi K2.6 hero visual

    deliberate design choices such as aesthetic hero sections, as well as interactive elements and rich animations, including scroll-triggered effects. With strong proficiency in leveraging image and video generation tools, Kimi K2.6 supports the generation of visually coherent assets and contributes to higher-quality, more salient hero sections. Moreover, Kimi K2.6 expands beyond static frontend development to simple full-stack workflows—spanning authentication to user interaction to database oper

    匹配字段正文
  2. Moonshot AI · Kimi Blog精选

    月之暗面发布 Kimi K2.5,主打视觉智能体与 Agent Swarm

    月之暗面发布开源模型 Kimi K2.5,在 K2 基础上用约 15T 混合视觉与文本 token 继续预训练,原生多模态,主打编码与视觉能力。K2.5 可自主编排最多 100 个子智能体、执行最多 1500 次工具调用,相比单智能体设置最多缩短 4.5 倍执行时间,且无需预定义子智能体或工作流。模型已上线 Kimi.com、Kimi App、API 和 Kimi Code,Kimi.com 与 App 提供 K2.5 Instant、Thinking、Agent 和 Agent Swarm(Beta)四种模式,Agent Swarm 在 Kimi.com 处于 beta,高层级付费用户可获免费额度。

    mode is serial collapse, where the orchestrator defaults to single-agent execution despite having parallel capacity. To address this, PARL employs staged reward shaping that encourages parallelism early in training and gradually shifts focus toward task success. We define the reward as The performance reward rperfr {\text{perf}}rperf evaluates the overall success and quality of the solution yyy for a given task xxx. This is augmented by two auxiliary rewards, each addressing a distinct challeng

    匹配字段正文

  3. Moonshot AI · Kimi Blog

    Moonshot AI 开源 Kimi K2:1T 参数 MoE 智能体模型

    Moonshot AI 开源 Kimi K2,这是总参数 1 万亿、激活参数 320 亿的 MoE 模型,包含基础版 Kimi-K2-Base 和后训练版 Kimi-K2-Instruct,在非思考类模型的前沿知识、数学和编码任务上达到 SOTA。该模型针对智能体任务优化,可自动调用工具完成多步任务,并采用 MuonClip 优化器在 15.5T token 上预训练且无训练尖峰。Kimi 网页端和移动端用户即日起可免费选用,API 兼容 OpenAI/Anthropic 接口,暂不支持视觉功能。

    Training loss vs tokens: Muon vs AdamW

    Kimi K2 yet. Use Kimi K2 with API The Kimi Platform offers an OpenAI/Anthropic compatible interface, allowing for easy adaptation of your existing applications to Kimi K2. We encourage developers to explore our tool calling API for building agent applications. For detailed information, visit platform.kimi.com. Serve Kimi K2 on your own We recommend running Kimi K2 on one of the following inference engines: vLLM, SGLang, KTransformers, or TensorRT-LLM. For detailed deployment instructions, please

    匹配字段正文

  4. DeepSeek API 更新日志精选

    DeepSeek 发布 V4.1-Flash:552B MoE 新架构,原生多模态并下调 API 价格

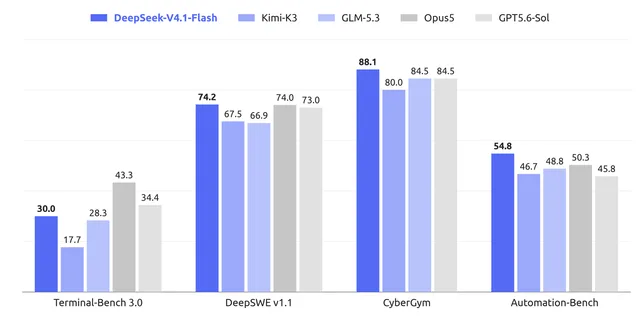
    DeepSeek 发布新架构家族中最小模型 DeepSeek-V4.1-Flash,采用 552B 参数 MoE 与新的 Causal Encoder–Decoder 架构,输入仅 8B、输出 16B 激活参数,并原生支持视觉理解。官方称其 KV cache 相比上一代只需 1/4 的 HBM 和 1/8 的 SSD 存储,基准结果超过包括 DeepSeek-V4-Pro 在内的旗舰模型。该模型已在 DeepSeek API 上线,模型名设为 deepseek-flash,新价格于 2026 年 9 月 10 日 04:00 UTC 生效;V4-Flash 与 V4-Flash-Vision-Exp 退役,9 月 14 日起 deepseek-v4-pro 请求将按 V4.1-Flash 费率路由至该模型,直至 V4.1-Pro 发布。

    ship models, including DeepSeek-V4-Pro. 💾 Smaller KV cache. Bigger savings. Compared with the previous generation, V4.1-Flash's KV cache needs just: 🔹 1/4 the HBM 🔹 1/8 the SSD storage Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly. ⚡ V4.1-Flash is now live on the DeepSeek API with native multimodal support. Set your model to deepseek-flash. 🔹 V4-Flash & V4-Flash-Vision-Exp are retired. For compatibility, deepseek-v4-flash a

    匹配字段正文

  5. DeepSeek API 更新日志精选

    DeepSeek 发布 DeepSeek-R1,性能对标 OpenAI-o1 并采用 MIT 许可开源

    DeepSeek 发布 DeepSeek-R1,官方称其性能与 OpenAI-o1 相当,模型与技术报告完全开源,代码和模型采用 MIT 许可,可自由蒸馏和商用,网站与 API 已上线。同时开源 6 个从 DeepSeek-R1 蒸馏的小模型,其中 32B 和 70B 版本性能与 OpenAI-o1-mini 相当。API 通过 model=deepseek-reasoner 调用,定价为每百万输入 token 0.14 美元(缓存命中)、0.55 美元(缓存未命中),每百万输出 token 2.19 美元。

    owering the open-source community; 🌍 Pushing the boundaries of open AI! 📜 License Update!; 🔄 DeepSeek-R1 is now MIT licensed for clear open access; 🔓 Open for the community to leverage model weights & outputs; 🛠️ API outputs can now be used for fine-tuning & distillation 🛠️ DeepSeek-R1: Technical Highlights; 📈 Large-scale RL in post-training; 🏆 Significant performance boost with minimal labeled data; 🔢 Math, code, and reasoning tasks on par with OpenAI-o1; 📄 More details: https://github.com/deep

    匹配字段正文

  6. MarkTechPost

    Conway Research 发布 Underdog Saluki 27B:2-bit 量化的 Qwen3.8-27B 在工具调用上超过原模型

    Conway Research 的端侧助手 Underdog 以 Apache 2.0 发布 Saluki 27B,这是 Qwen3.8-27B 的 2-bit 混合精度 GGUF,体积 7.89 GB,而 BF16 原模型需 54 GB,可在原生 llama.cpp 上运行并支持完整 GPU 卸载。在相同测试环境下,Saluki 在 Underdog Bench 的 120 项 BFCL v4 任务上得 88 分,原模型 84 分;并行工具调用 42 对 35;SWE-bench Verified 修复 30 个问题,原模型 33 个。代价是数学与多步推理下降 12 到 18 分,AIME 2025 为 79.2 对 96.7。

    parameters. 7.89 GB GGUF versus 54 GB for BF16; Runs on: stock llama.cpp and apps built on it, with full GPU offload. Optional 629 MB or 928 MB vision add-on; Performance: 96% average retention across 9 benchmarks versus full Qwen3.8-27B; Best: Parallel tool calls, 42 versus 35 for the full model (120% retention); Worst: AIME 2025, 79.2 versus 96.7 (about 82% retention); Bottom line: Best: beats the 54 GB original at tool calling in a sub-8 GB file; Worst: competition math and multi-step reason

    匹配字段正文

星期四

  1. Latent Space精选

    Anthropic 发布 Claude Haiku 5.5,定价对标 GPT-6 Luna

    Anthropic 发布 Claude Haiku 5.5,这是 Haiku 系列约一年来的首次更新,定价与 OpenAI 的 GPT-6 Luna 持平,同日还下调了 Sonnet 5.5 与订阅方案价格。Artificial Analysis 的独立评测显示其 Intelligence Index 为 43(最高 effort),比上一代 Haiku 提升 26 分,略高于 GLM-5.3 Flash(42)、Gemini 3.8 Flash(41)和 GPT-6 Luna(38),但落后 Claude Sonnet 5.5(56)13 分。该模型支持 1M token 上下文(Haiku 4.5 为 200k),首次引入 effort 设置与自适应思考,主要代价是 token 消耗偏高,最高 effort 下每个 Index 任务约用 162k 输出 token,约为 GPT-6 Luna 的 3 倍。

    pay 5x more, which matters for long-context agent loops; These two effects likely explain why Cursor’s “10x cheaper on short requests” differs from Anthropic’s “75% cheaper on average.”; Factual recall is weaker than Gemini 3.8 Flash and Luna; The over-refusal bug currently depresses the automation score; Not yet benchmarked: Arena scores are pending, and independent cost-per-task figures await tiered-pricing support Context Haiku 4.5 has been Anthropic’s small model since October 2025. Since t

    匹配字段正文

  2. MarkTechPost

    Perplexity 发布 pplx-embed-v2-late 多模态嵌入模型,0.6B 与 9B 两个版本

    Perplexity 发布 pplx-embed-v2-late,包含 0.6B 和 9B 两个 ColBERT 风格多模态嵌入模型,均可检索文本、图像和渲染后的 PDF 页面,并共享同一嵌入空间。9B 模型在 MADQA 上取得 92.4%,0.6B 模型面向边缘设备和低延迟查询,用 0.6B 查询 9B 索引在 ViDoRe v3 图像检索上得 63.5%,高于两侧都用 0.6B 的 62.3%。两个模型已在 Hugging Face 以 MIT 许可发布,可自托管商用,Perplexity 托管 API 端点仍在计划中;所有分数均为自报,技术报告尚未发布。

    est Use Cases The best fit is visual document search over PDFs, slides and scanned reports; Low-latency search: index in the cloud with 9B, then query on-device with 0.6B; Agentic RAG over large PDF or web collections The 0.6B model fits edge devices; the 9B model is built for index-time quality; Best score: 92.4% on MADQA. Weakest: 61.2% on ViDoRe v3 Markdown; 0.6B queries over a 9B index beat 0.6B on both sides; Storage growth and self-reported scores are the main caveats [Sponsored] The web i

    匹配字段正文

  3. gihyo.jp

    Anthropic 发布 Claude Haiku 5.5,运行成本较 Haiku 4.5 平均降约 75%

    Anthropic 于 10 月 7 日发布 Claude Haiku 5.5,在编码、计算机操作和知识工作上较 Haiku 4.5 提升,运行成本平均降低约 75%,已在 Claude Platform、Claude Code 以及 AWS、Google Cloud、Microsoft Azure 上线。该模型面向摘要、分类、对话历史压缩、数据库查询等高频低成本任务,也可作为 Opus 5.5 或 Sonnet 5.5 的子智能体使用;上下文窗口从 20 万扩至 100 万 token,最大输出从 6.4 万增至 12.8 万 token,并首次在 Haiku 系列支持 effort 设置,默认 medium。评测方面,Terminal-Bench 4.0 得 39.2%(Haiku 4.5 为 0.0%,Sonnet 5.5 为 70.6%),OSWorld 2.1 离线评测得 72.4%(Haiku 4.5 为 15.7%,Sonnet 5.5 为 83.9%)。

    pic Haiku 5.5はClaude PlatformとClaude Codeで利用できる。Amazon Web Services、Google Cloud、Microsoft Azureでも提供を開始した。 Haiku 5.5 is now available in the Claude Platform and Claude Code. On average, it costs around 75% less to run than Haiku 4.5. It pairs well with Opus 5.5 or Sonnet 5.5 as a subagent. Use it for high-volume, cost-sensitive tasks like summaries, compactions, or database queries. https://t.co/RB9xCWo4Db— ClaudeDevs (@ClaudeDevs) October 7, 2026 大量の反復処理やサブエージェントでの利用を想定 Haiku 5.5は、要約、分類、会話履歴の圧縮

    匹配字段正文

  4. MarkTechPost

    Liquid AI 开源 d1-3B 与 d1-omni-600M 多模态决策模型

    Liquid AI 发布 Open d1 系列两款开源权重多模态决策模型:d1-3B 读取文本与图像,d1-omni-600M 读取文本加图像或音频,两者都不生成文本,而是在一次前向传播中返回校准后的类型化答案,输出 token 数为 0。d1-3B 有 3.12B 参数,基于 LFM2.5-VL-3B,使用 400M SigLIP2 NaFlex 视觉编码器和 32,768 token 上下文;d1-omni-600M 有 587M 参数,基于 LFM2.5-Encoder-350M,音频编码器为 17 层 FastConformer,上下文 16,384 token,音频片段上限 30 秒。两个检查点已上 Hugging Face,可通过 Transformers 加载并支持 llama.cpp,LFM Open License v1.0 允许年收入低于 1000 万美元的免费商用;d1-3B 在 Decision Index v0.2.1 得 48.57,在 RTX 4090 上单问题延迟 8 ms。

    ither checkpoint is a chat model. How are d1-3B and d1-omni-600M built? d1-3B has 3.12B parameters and starts from LFM2.5-VL-3B, a decoder-only vision-language model. Liquid AI averaged the weights of LFM2.5-2.6B with that model’s text backbone. It then fine-tuned several checkpoints with different seeds and data mixtures, and merged them again. It uses a 400M SigLIP2 NaFlex vision encoder and a 32,768-token context. Long inputs, shuffled answer options, and fixing data shortcuts mattered more t

    匹配字段正文

  5. Artificial Analysis精选

    Anthropic 发布 Claude Haiku 5.5,智能指数得分 43 分

    Anthropic 发布 Claude Haiku 5.5,在 Artificial Analysis 智能指数上得分 43,比上一代 Haiku 发布一年后提升 26 分。这是首个带 effort 设置和自适应思考的 Haiku 模型,并引入分层定价:100k token 以内为每 1M 输入/输出 token 0.10/0.50 美元,超过 100k 后涨至 0.50/2.50 美元。评测显示其 max 档略高于 GLM-5.3 Flash(42)、Gemini 3.8 Flash(41)和 GPT-6 Luna(38),但每个任务约消耗 162k 输出 token,约为 GPT-6 Luna 的 3 倍;上下文窗口从 200k 提升至 1M token。

    does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon. Key takeaways: ➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 point

    匹配字段正文

  6. The Decoder精选

    Anthropic 发布 Claude Haiku 5.5,价格最高降 90%

    Anthropic 发布 Claude Haiku 5.5,这是其目前最快、最便宜的小模型,平均价格比 Haiku 4.5 低约 75%,10 万 token 以内提示词最高降价 90%,超过 10 万 token 则贵 5 倍。基准测试显示其计算机使用能力提升明显,OSWorld-2.1 得分从 15.7% 升至 72.4%,Terminal-Bench 4.0 从 0 升至 39.2%,Humanity's Last Exam 无工具 45.9%、有工具 57.4%。该模型是首个支持可调推理等级的 Haiku 级模型,已在 AWS、Google Cloud 和 Microsoft Azure 上线,同时 Sonnet 5.5 的缓存读取费用从每百万 token 0.20 美元降至 0.10 美元。

    net 5.5. Haiku 5.5 is designed for high-volume, cost-sensitive tasks like summarization, database queries, classification, and live customer support, according to Anthropic. On average, the model costs about 75 percent less than Haiku 4.5. For requests with prompts up to 100,000 tokens, which Anthropic says account for roughly 90 percent of all previous Haiku requests, prices drop by up to 90 percent. Prompts longer than 100,000 tokens cost five times as much. Anthropic points out that Haiku 5.5

    匹配字段正文

  7. Claude Devs精选

    Claude Haiku 5.5 上线 Claude Platform 与 Claude Code

    Claude Haiku 5.5 已在 Claude Platform 和 Claude Code 上线,官方称其平均运行成本比 Haiku 4.5 低约 75%。它适合作为 Opus 5.5 或 Sonnet 5.5 的子智能体,用于摘要、压缩、数据库查询等高频且成本敏感的任务。定价方面,100K token 以内的提示词为每百万 token 输入 $0.10、输出 $0.50,缓存读取 $0.01;超过 100K token 后为 $0.50 / $2.50,缓存读取 $0.05。

    Haiku 5.5 is now available in the Claude Platform and Claude Code. On average, it costs around 75% less to run than Haiku 4.5. It pairs well with Opus 5.5 or Sonnet 5.5 as a subagent. Use it for high-volume, cost-sensitive tasks like summaries, compactions, or database queries. https://t.co/RB9xCWo4Db

    匹配字段正文

星期三

  1. Hugging Face

    TII 发布 1.6B 参数语音识别模型 Falcon-ASR

    阿布扎比技术创新研究院(TII)发布 Falcon-ASR,一个 1.6B 参数的语音识别模型,重点覆盖阿联酋方言、阿拉伯语方言、现代标准阿拉伯语和英语。在 Open Universal Arabic ASR Leaderboard 的六个测试集上,其平均 WER 为 20.92%,比该榜单快照中最佳公开结果好 2.25 个百分点;内部阿联酋方言评测中 WER 为 22.73%、CER 为 10.19%,WER 比 Qwen3-Omni 低 4.07 个百分点。模型用同一套权重支持英语、法语、西班牙语和葡萄牙语,无需指定语言,并支持词级时间戳,已在 Hugging Face Demo Space 开放试用,API 与原生应用尚在计划中。

    rms and changes between languages. Arabic benchmark results The Open Universal Arabic ASR Leaderboard , maintained by the ELM Research Center, ranks systems by the equal-weight average WER across six test sets. It also reports character error rate (CER). Lower values are better for both metrics. Our Falcon-ASR evaluation follows this protocol. WER = Word Error Rate; CER = Character Error Rate. A lower value indicates better performance. We evaluated Falcon-ASR on the same six benchmarks using th

    匹配字段正文

  2. Liquid AI 模型与工程博客精选

    Liquid AI 发布 d1-3B 与 d1-omni-600M 开放权重决策模型

    Liquid AI 发布 d1-3B 和 d1-omni-600M 两款开放权重决策模型,已在 Hugging Face 上线。d1-3B 在 Decision Index v0.2.1 公开集得 48.57,超过所有 10B 以下模型,与 12 倍规模的 Decider 35B-A3B 持平;单次提问在 RTX 4090 上 8 ms、Jetson AGX Thor 上 16 ms、Jetson AGX Orin 上 26 ms、Jetson Orin Nano 上 50 ms。d1-omni-600M 是首个实验性 checkpoint,支持文本与图像或文本与音频输入,同一指数得 15.95。

    Encoder-350M, a bidirectional encoder. It adds vision and audio encoders to handle all three modalities. It accepts either text and image, or text and audio as inputs d1-3B. We averaged the weights of LFM2.5-2.6B and the text backbone of LFM2.5-VL-3B to create a better base model. We then fine-tuned checkpoints with different random seeds and data mixtures before merging them again. Training on long inputs, shuffling answer options, and fixing shortcuts in the data made a bigger difference than

    匹配字段正文

  3. Artificial Analysis 完整文章

    Anthropic 发布 Claude Haiku 5.5,Artificial Analysis 公布评测结果

    Anthropic 发布 Claude Haiku 5.5,这是首个带 effort 设置与自适应思考的 Haiku 模型,并引入分层定价:100k token 以内为 $0.10/$0.50 每 1M 输入/输出 token,超过 100k 后升至 $0.50/$2.50。Artificial Analysis 评测显示,Haiku 5.5(max)在小型模型中略领先 GLM-5.3 Flash(42)、Gemini 3.8 Flash(41)和 GPT-6 Luna(38),但落后 Claude Sonnet 5.5(max,56)13 分;其上下文窗口从 Claude 4.5 Haiku 的 200k 提升到 1M token。该模型每个 Intelligence Index 任务约消耗 162k 输出 token,约为 GPT-6 Luna(max,约 50k)的 3 倍,Terminal-Bench 4.0 得分 33%(Haiku 4.5 为 0%)。

    does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon. Key takeaways: ➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 point

    匹配字段正文

  4. MarkTechPost精选

    Google DeepMind 发布 EmbeddingGemma 2,740M 开源多模态嵌入模型

    Google DeepMind 发布 EmbeddingGemma 2,一个基于 Gemma 4 架构的 740M 参数开源多模态嵌入模型,可将文本、代码、图像、视频和音频嵌入同一个 768 维空间,采用 Apache 2.0 许可,权重已上线 Hugging Face 和 Kaggle,并提供 Ollama、llama.cpp GGUF 和 LiteRT 版本。模型采用模块化设计,文本与代码主干 270M、视觉编码器 170M、音频编码器 300M 均可选,上下文窗口 8192 token,是上一版的 4 倍。Google 研究团队称其在 MTEB Code 和 MAEB 的 1B 以下多模态嵌入模型中领先,代码检索从 68.76 提升到 78.68;量化后在 Pixel 11 Pro 上纯文本约占 191MB 内存,全多模态约 567MB。

    d audio into one 768-dimensional space. It has 740M parameters, an 8K token context window and an Apache 2.0 license. It targets on-device search, classification and privacy-first RAG. This article analyzes, compares and showcase how EmbeddingGemma 2 fits in the space. Deployable today? Yes. Weights are live on Hugging Face and Kaggle, with Ollama, llama.cpp GGUF and LiteRT builds available now. What an Embedding Model Does An embedding model converts content into a vector of numbers that captur

    匹配字段正文

星期二

  1. Google DeepMind

    Google DeepMind 发布 EmbeddingGemma 2 多模态嵌入模型

    Google DeepMind 发布 EmbeddingGemma 2,一个 740M 参数、Apache 2.0 许可的端侧多模态嵌入模型,原生将文本、图像、音频和视频映射到统一嵌入空间。它在 MTEB Code 上从 68.76 提升到 78.68,支持 8K token 上下文窗口,可处理约 5.5 分钟音频、29 张图像或 58 帧视频,并可通过 MRL 将向量从 768 维截断至 128 维。模型权重已在 Hugging Face 和 Kaggle 开放下载,支持 LiteRT、MediaPipe、transformers.js、vLLM、Ollama 等部署方式。

    EmbeddingGemma 2

    se blew past our expectations. With more than 20 million downloads, builders have used it to power smarter on-device search tools and privacy-first retrieval augmented generation (RAG) pipelines. Today, we’re launching EmbeddingGemma 2, expanding beyond text to unify code, images, video, and audio in a shared embedding space. Built on the Gemma 4 architecture and released under a commercially permissive Apache 2.0 license, EmbeddingGemma 2 has 740 million parameters, making it optimal for on-dev

    匹配字段正文

  2. Google Blog

    Google DeepMind 发布 EmbeddingGemma 2 多模态嵌入模型

    Google DeepMind 发布 EmbeddingGemma 2,这是面向端侧的多模态嵌入模型,可将文本、图像、音频和视频映射到统一嵌入空间。模型基于 Gemma 4 架构,采用 Apache 2.0 许可,参数量 7.4 亿,文本任务最低 2.7 亿参数,可选视觉(1.7 亿)和音频(3 亿)编码器。它支持 8K token 上下文窗口,是 EmbeddingGemma 1 的 4 倍,可处理约 5.5 分钟音频、29 张图片或 58 帧视频;借助 MRL 可将输出向量从 768 维截断至 512、256 或 128 维,最多减少 6 倍存储占用。在 MTEB Code 上得分从 68.76 提升至 78.68,模型权重已在 Hugging Face 和 Kaggle 开放下载。

    EmbeddingGemma 2

    se blew past our expectations. With more than 20 million downloads, builders have used it to power smarter on-device search tools and privacy-first retrieval augmented generation (RAG) pipelines. Today, we’re launching EmbeddingGemma 2, expanding beyond text to unify code, images, video, and audio in a shared embedding space. Built on the Gemma 4 architecture and released under a commercially permissive Apache 2.0 license, EmbeddingGemma 2 has 740 million parameters, making it optimal for on-dev

    匹配字段正文

  3. Arena

    Mistral Large 4 上线 Arena 的 Agent Arena 与 Code Arena

    Mistral AI 的 Mistral Large 4 已进入 Arena,可在 Agent Arena 中实测,用户投票将影响其评估结果,分数稍后公布。Agent Arena 用数百万个真实长周期智能体任务评测模型,模型可调用网页搜索、文件系统和终端工具完成复杂工作流,排行榜以因果追踪方法衡量模型相对平均模型的结果表现。Mistral Large 4 同时上线 Code Arena 的 WebDev、Text 和 Vision 三个方向。

    alAI is now in the Arena! Head to Agent Arena to test it out, and your votes will shape its evaluation. Scores coming soon. In Agent Arena, we measure models on millions of real-world, long-horizon agentic tasks. Models can access web search, filesystem, and terminal tools to complete complex workflows. The leaderboard measures model performance on outcomes relative to the average model using a causal tracing methodology. Mistral Large 4 is also available in Code Arena: WebDev, Text, and Vision.

    匹配字段正文