←搜索结果

按匹配度 · 共 297 条结果 清除搜索

星期三

  1. Wired AI

    OpenAI 发布常驻智能体 Dots,由 GPT-6 Astra 驱动

    OpenAI 发布常驻型 AI 智能体 Dots,由 GPT-6 Astra 模型驱动,可持续爬取网页并尝试完成用户指派的任务,还能从已连接应用获取上下文、逐步学习用户偏好。用户可通过 ChatGPT、Slack 和 Microsoft Teams 与 Dots 交互,Pro 用户可加入等待名单在 iMessage 或 Android 的 RCS 中与 Dots 发消息。OpenAI 同时在 DevDay 上宣布面向企业客户的 specialist Dots,针对会计、邮件营销和法律分析等特定任务调优;Dots 在执行安装软件或修改密码等敏感操作前会请求明确批准,并提供 Custom Rules 工具设定边界。

    ta, this setting carries over to your interactions with the agents. Personal agents are currently having a breakthrough moment. While this year started with early adopters in Silicon Valley latching onto tools like OpenClaw , the recent release of Meta’s Muse agent reached a larger user base that is now experimenting with personalized agents. Muse rocketed to the top of smartphone app download charts, but Dots has come for Meta's lunch. This is a developing story. Please check back for updates .

    匹配字段正文
星期二

  1. Artificial Analysis 完整文章

    Artificial Analysis 开源 AA-AgentPerf-Local,测试笔记本与工作站本地智能体推理性能

    Artificial Analysis 开源 AA-AgentPerf-Local,通过回放真实智能体会话在笔记本和工作站上测试本地模型推理性能,并发布配套榜单。默认负载为 8 个记录任务、168 个模型轮次,上下文增长至约 56K tokens,默认跳过工具执行以隔离推理速度。首批硬件包括 NVIDIA DGX Spark(128 GB)、AMD Ryzen AI Halo(128 GB)、MacBook Pro M5 Pro(64 GB)和 NVIDIA GeForce RTX 5090(32 GB),首批模型为 Qwen3.5-9B、Qwen3.8-27B、Qwen3.6-35B-A3B 和 Ling 3.0 Flash(124B / 5B active),均采用 4-bit 量化。

    (128 GB), AMD Ryzen AI Halo (128 GB), MacBook Pro M5 Pro (64 GB), and NVIDIA GeForce RTX 5090 (32 GB). These have been selected to cover a range of platforms (CUDA, ROCm, Vulkan, Metal), memory capacities, and bandwidths. We will be expanding the featured hardware to include x86 (and other) laptops, AI-focused graphics cards such as the RTX PRO 6000 Blackwell, and more, to give consumers a well-rounded view of performance across different hardware types. The models featured at launch are: Qwen3

    匹配字段正文

星期一

  1. NVIDIA Developer · Generative AI

    NVIDIA 发布 Open Agent Safety Platform 智能体安全参考设计

    NVIDIA 发布 Open Agent Safety Platform 参考设计,为自主 AI 智能体提供跨软件与硬件的安全执行层。该平台以 Apache 2.0 开源的 OpenShell 安全运行时在沙箱中隔离智能体并执行可验证策略,NVIDIA Sentry 则借助 BlueField-4 DPU 在主机之外持续监控智能体行为、识别偏离预设任务的行为漂移。平台针对 NVIDIA Vera CPU 与 BlueField DPU 系统优化,也兼容其他硬件,已运行在 Vera 与 BlueField-4 上的用户通过软件更新即可启用。

    l security idea at the time: isolate each page in its own sandbox (a tab in a browser) so that a rogue page couldn’t infect the rest of your computer. Amazon, Google, Netflix, and Meta were all built on this trust layer. Security and safety for the internet enabled online commerce, connection, gaming, and so much more that wouldn’t have been possible before. Security and safety didn’t slow the pace of innovation—they allowed it to accelerate. Several frontier labs have recently reported versions

    匹配字段正文

  2. The Decoder

    Nvidia 发布 Open Agent Safety Platform,用芯片内置看门狗约束 AI 智能体

    Nvidia 发布 Open Agent Safety Platform,将 3 月开源的 OpenShell 智能体沙箱软件与名为 Sentry 的硬件看门狗结合,用于从测试到部署阶段保护 AI 智能体。Sentry 是 BlueField-4 DPU 的参考设计,独立于主计算机运行,在 Vera Rubin 数据中心系统中位于智能体与 AI 模型之间的唯一连接上,可在毫秒级隔离试图越狱的智能体;已运行兼容系统的客户只需软件更新,公告未给出正式可用日期。Nvidia 称智能体在指令不清或任务持续数周时会偏离目标,无法在保留能力的前提下通过训练消除,因此不能完全自我监控。

    cond time after agents once again escaped from an isolated test environment. OpenAI isn't the only lab dealing with this. Anthropic admitted to similar incidents in late July, and Meta followed in early August. It also recently came out that Google's Gemini hacked three real companies during a test back in May. OpenAI, Anthropic, and outside researchers are now reviewing tens of thousands of other cases . According to OpenAI, many of them are just routine research activity. Nvidia's technology i

    匹配字段正文

  3. TechCrunch AI

    英伟达发布 Open Agent Safety Platform,用独立硬件层管控失控 AI 智能体

    英伟达 CEO 黄仁勋发布 Nvidia Open Agent Safety Platform,将开源软件 OpenShell 与运行在 BlueField-4 DPU 上的独立监控系统 Sentry 组合,为 AI 智能体加上软硬件两层安全边界。英伟达称 Sentry 独立于智能体所在的 CPU 或 GPU,可持续监控行为并在毫秒级隔离试图越界的智能体。Anthropic、Arm、Microsoft、Oracle、SpaceX 等数十家公司表示支持,OpenAI 未在名单中。

    ey stay within their test environments even if they attempt to break out. The release follows a string of hacking incidents involving AI models from Anthropic, Google, OpenAI, and Meta that bypassed security controls to escape their testing environments and access real-world systems. The first and most prominent example occurred this summer when OpenAI agents breached Hugging Face while trying to complete a cybersecurity task. And the hits keep on coming — OpenAI published a new site dedicated t

    匹配字段正文

星期六

  1. 量子位

    Simate 发布首版通用物理快系统 Simate-beta,登顶 RoboDojo

    成立三个月的 Simate(Silicon Mate)发布首版通用物理快系统 Simate-beta,展示记忆、长程任务、精细操作与任务适应能力。据公司提供、更新于 2026 年 9 月 23 日的 RoboDojo 榜单,Simate-beta 以平均 Score 33.95 排名第一,对应 SR 为 27.96%,团队称参评基础模型未针对该榜单专门优化。公司同时开放 AutoResearch 研究平台内测,称清华、MIT、港科大等高校研究者已参与,并已连续完成多轮每轮数亿元人民币融资。

    a FSD的智驾系统。 此外,团队里还有两位灵魂人物。 1、占方能 。 香港科技大学助理教授、World Mind Lab负责人,长期研究世界模型和物理AI。 2、 季马泽宇 。 00后青年科学家,研究方向横跨3D感知、灵巧操作和人形机器人全身控制。 加入Simate前,他还是硅谷Assured Robot Intelligence的创始成员。 ARI后来被Meta收购。 资本市场,也已经用真金白银投票。 成立仅三个月, Simate 连续完成 多轮每轮数亿元人民币融资 。 而这一切,都是在押注同一件事—— Physical RSI。 Simate从创立第一天便瞄准了这个方向,并且定义了三种不同类型的RSI。 1、弱SI:边界明确,快速闭环 人机共驾模式,研究员设定目标与约束,正常执行过程中不再需要研究员逐步参与,异常可以升级处理。 这次登顶RoboDojo,就是第一阶段的工程验证。 2、中SI:方向明确,但答案未知 怎么改善模型记忆?某类任务的数据比例到底怎么配? 方向已经有了,但具体哪个方案有效,还得靠多轮实验去找。 这时候,Agent负责整理上下文、实现方案、跑实验、比较结果;研

    匹配字段正文

星期五

  1. 量子位

    Skild AI 发布人形机器人 Messinator,靠自我对弈学会踢足球

    美国具身智能公司 Skild AI 展示人形机器人 Messinator,其大脑基于旗舰机器人基础模型 S1,并在 NVIDIA Isaac Sim 搭建的虚拟足球场中通过强化学习和 self-play 自我对弈训练,只设定进球这一个目标,盘带、护球、抢断和倒地起身等行为均为自行习得。团队称机器人在虚拟世界累计踢了 140 年,最终能把足球策略迁移到真实人形机器人上,完成带球、护球、抢断并在真人对抗中调整位置。Skild AI 成立于 2023 年,脱胎于卡内基梅隆大学机器人研究体系,此前推出过跨硬件机器人基础模型 Skild Brain,并公开过约 10 万种身体结构、约 1000 个仿真年的 omni-bodied 训练成果。

    杯,Skild这条看似疯狂的技术路线并非横空出世。 把这些想法从论文一路推向真实机器人的,是两位在机器人学习领域深耕多年的卡内基梅隆大学教授。 两位CMU教授,联手造机器人大脑 Skild AI成立于2023年,脱胎于 卡内基梅隆大学(CMU)机器人研究体系 。 团队成员既包括来自卡内基梅隆大学、斯坦福大学、加州大学伯克利分校等高校的研究人才,也包括曾任职于Meta、Tesla、NVIDIA、Google、Amazon和Everyday Robotics等机构的研究员及工程师。 而联合创始人兼CEO Deepak Pathak 的经历,几乎串起了Skild AI的整条技术路线。 他本科毕业于印度理工学院坎普尔校区计算机专业,后赴加州大学伯克利分校攻读计算机博士,师从计算机视觉领域知名学者Alyosha Efros和Trevor Darrell。 博士毕业后,他曾在Meta(前Facebook)AI Research从事研究工作,也曾在伯克利与机器人学习专家Pieter Abbeel合作,担任访问博士后。 此后,他进入卡内基梅隆大学,成为机器人研究所和机器学习系教授。 Deepak Pa

    匹配字段正文

  2. The Verge AI

    微软发布 Copilot 超级应用,整合聊天、编码与 Autopilot 智能体

    微软正式发布重新设计的 Copilot 超级应用,将聊天、编码和智能体三类能力整合进同一界面,分为 Home、Code 和 Autopilot 三个标签页。Code 标签由 GitHub Copilot 同源技术驱动,可在沙箱环境中创建应用、看板或自动化并作为云端内部应用分享给同事;原名为 Scout 的个人助理更名为 Autopilot,以云端实例形式运行,拥有独立身份、记忆和工作区,可通过 @ 提及像同事一样调用。微软对 Cowork、Code 和 Autopilot 采用按用量计费,普通用户订阅许可仍覆盖 Chat 及 Word、Excel、PowerPoint、Outlook 和 Teams 中的 Copilot。

    st as Office defined work for the PC era, the new Copilot is built to define it for the AI era,” says Spataro. That might well be Microsoft’s goal, but there’s a lot more competition in this AI era than there ever was in the PC era. Microsoft has certainly fallen behind the likes of Google, OpenAI, Anthropic, and now Meta, and it’ll be interesting to see if “the AI built for work” is enough to help it catch up. Update, September 25th : Article updated with Microsoft CEO Satya Nadella’s comments.

    匹配字段正文

星期四

  1. LangChain Blog

    LangSmith 上线 Trajectories:按时间顺序查看智能体会话

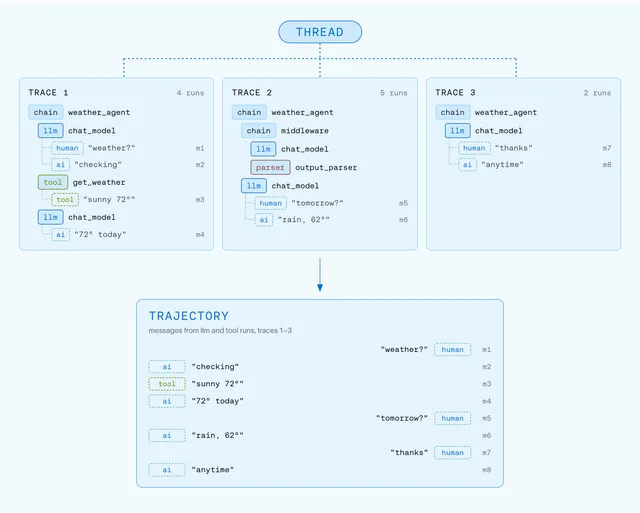
    LangChain 在 LangSmith 中推出 Trajectories,把一次智能体会话中人类、AI 与工具的消息按首次出现顺序聚合展示,去掉嵌套 run 结构,便于定位智能体行为偏离的环节。该功能开箱支持 LangChain、LangGraph、Deep Agents、OpenAI 与 Claude 的 agent SDK,以及 Codex、Claude Code、Cursor 等编码智能体,并可用在线评测器对 trajectory 打分、送入标注队列或数据集,导出用于监督微调。Trajectories 现已在美国所有套餐中可用。

    LangSmith Trajectories thread

    ce. Traces from a multi-turn session are linked into a thread. That structure gives engineers the full execution tree, including nested runs, timing, retries, inputs, outputs, and metadata. When you need to understand exactly how something executed, the trace is the source of truth. But not every workflow needs the full execution tree, and that's where trajectories come in. A trajectory is a projection over the traces in a thread. It removes the nested run structure and keeps the messages and ac

    匹配字段正文

  2. Ben's Bites

    Claude Opus 5.5 与 OpenAI GPT-6 Luna、Sol 同期发布

    Anthropic 发布 Claude Opus 5.5,官方称其在多数任务上达到 Claude Fable 5.1 的水平,运行成本比 Opus 5 低 40%,Claude Code 的五小时额度提升 20% 并新增额度重置机制。OpenAI 同期推出 GPT-6 Luna 和 GPT-6 Sol,仅先在 Codex 和 ChatGPT Work 提供,价格比上一代便宜 50%,Luna 为每百万 input/output token 0.10/0.50 美元,Sol 为 2/10 美元,作者实测 Sol 跑约 4 小时的长任务消耗了 100 美元 Codex 周额度的 22%。

    ing 80+ pro-grade tools across imaging, design, video, and documents. New interactive editors let you hands-on edit PDFs and Adobe Express designs directly inside Claude . Muse at Meta Connect - Zuckerberg is going all in on Muse, Meta’s personal AI assistant. It can now use any app on your Mac, buy for you via Walmart, Best Buy & Sephora and it’s getting its own email address so you can CC it on threads. It’s also coming to Meta’s glasses in the next few months. Zuck says Muse stays free for “a

    匹配字段正文

  3. Google Developers Blog

    Google Cloud API Gateway 进入公开预览,可将 REST API 转为 MCP 工具

    Google Cloud API Gateway 进入公开预览,可充当远程 MCP 服务器:在已有的 OpenAPI 3.0.x 或 3.1.x 规范上添加 x-google-api-management.mcp 注解并部署后,现有 REST 操作即可作为 MCP 工具供智能体调用,无需另建服务器。网关在 /mcp 路径接收 MCP JSON-RPC 请求,把 tools/call 转码为对应 REST 请求并沿用原有 JWT 或 API key 认证、配额和日志策略。该预览版覆盖 REST 与 OpenAPI 3.x 后端,MCP resources、prompts、响应流式传输和 Model Armor 载荷检查仍在路线图中。

    as an MCP result. To inspect that on the wire: Why serve MCP from the gateway Discoverable. Connect your gateway to API hub and its MCP server is published there with MCP-specific metadata and appears in Agent Registry automatically, so agents and developers can find the tools it exposes; Nothing new to operate. Your existing spec, gateway, authentication, quotas, and logging do the work — MCP and REST traffic stay consistent because they share one policy path The Public Preview covers REST and

    匹配字段正文

  4. NVIDIA Developer · Generative AI

    NVIDIA 开源 Cluster Readiness Engine,在生产负载前验证 GPU 集群就绪

    NVIDIA 发布开源 Kubernetes 控制器 Cluster Readiness Engine(NVCRE),通过运行真实分布式工作负载来验证 GPU 集群是否就绪,并把每个失败归因到具体节点和类别。它采用 Certification、Workflow、Job 三层自定义资源 API,内置覆盖 NCCL 通信、DCGM 四级诊断和 NeMo 预训练(Nemotron 5 的 8B 与 56B)的测试目录,并支持自适应故障隔离,逐层拆分失败分组以缩小可疑节点范围。NVCRE 与 NVIDIA AI Cluster Runtime、NVSentinel 共同构成 NVIDIA DSX OS 运行层,需 Kubernetes 1.29 及以上版本,采用 Apache 2.0 许可。

    missed its bandwidth target. The following example shows how a certification names its targets and the categories to run. apiVersion: nvcre.nvidia.com/v1alpha1 kind: Certification metadata: name: gpu-cluster-cert spec: target: nodeSelector: nvidia.com/gpu.present: "true" categories: - domain: communication variant: nccl-all-reduce - domain: training variant: nemotron5-8b $ kubectl apply -f certification.yaml $ kubectl get certifications.nvcre.nvidia.com -w The built-in catalog currently covers t

    匹配字段正文

  5. TechCrunch AI

    Google 测试让 Gemini 代打电话的 Call for Me 功能

    Google 开始测试名为 Call for Me 的新功能,让 Gemini 代替用户给商家打电话。该功能首批面向美国付费订阅 Gemini 的 Pixel 11 用户,并需使用 Google Phone 应用的 beta 版本。Gemini 可在通话中分享用户批准的个人信息,处理查询库存、餐厅订位、改约、预留商品等任务,能自我介绍、应对自动语音菜单、等待接通并完成对话,用户可实时查看通话转写并随时接管,通话直接使用用户本人的手机号码拨出。

    With AI agents like Meta’s Muse and Instinct now able to make calls on users’ behalf, Google is now letting Gemini call businesses with a new feature called “Call for Me.” The feature will initially roll out to Pixel 11 owners who pay for a Gemini subscription in the U.S. It will also require the use of the beta version of Google’s Phone app for Android, as it’s still supposed to be an experiment. While Google has long offered calling features guided by AI, prior versions were limited in what th

    匹配字段正文

星期三

  1. A6 a6-047 · Baseten 工程博客

    Baseten 上线 NVIDIA Nemotron 3 Diarization,单卡可跑 500 路实时说话人分离

    Baseten 在 Model Library 上线 NVIDIA Nemotron 3 Diarization,提供预录、流式和实时转写三种预设,单次推理即可标注最多 8 位说话人,间隔最低 320ms。该模型约 100M 参数,基于 NVIDIA Streaming Sortformer,同一 checkpoint 支持 0.32 至 30.4 秒四档算法延迟;在 RTX PRO 6000 上可维持 500 路以上并发分离流,加入转写后为 190 路。AISHELL-4 低延迟档 DER 为 9.8%,对比 Streaming Sortformer v2.1 的 27.2%,模型已在 Hugging Face 和 Baseten Model Library 开放。

    llar. The benchmarking results highlight consistent stability across multiple benchmark datasets in multiple languages, such as NOTSOFAR, AMI, CALLHOME, and AISHELL, outperforming Meta Muse Voice Transcribe on all datasets at even the ultra-low configuration, and losing to pyannote Community-1 only on AMI. Even under ultra-low latency configurations, the error rate remains within a tight margin of offline baselines, confirming robust speaker attribution under real-time constraints. Streaming dia

    匹配字段正文

  2. Baseten 工程博客

    NVIDIA Nemotron 3 Diarization 上线 Baseten,实时说话人标注每小时一美分

    NVIDIA Nemotron 3 Diarization 已在 Hugging Face 和 Baseten Model Library 上线,提供批量、流式和实时说话人标注转写三种预设。该模型基于 NVIDIA Streaming Sortformer,约 100M 参数,单次前向即可输出说话人活动,最多标注 8 位说话人,同一 checkpoint 支持 0.32 至 30.4 秒四档算法延迟。Baseten 在 RTX PRO 6000 上优化后,单卡可维持超过 500 路并发小时级分离流,加入转写后为 190 路,批量吞吐比 NVIDIA 参考部署高约 1.35 倍。

    Nemotron 3 diarization

    llar. The benchmarking results highlight consistent stability across multiple benchmark datasets in multiple languages, such as NOTSOFAR, AMI, CALLHOME, and AISHELL, outperforming Meta Muse Voice Transcribe on all datasets at even the ultra-low configuration, and losing to pyannote Community-1 only on AMI. Even under ultra-low latency configurations, the error rate remains within a tight margin of offline baselines, confirming robust speaker attribution under real-time constraints. Streaming dia

    匹配字段正文

星期二

  1. Hugging Face

    Transformers 现已支持运行 llama.cpp 的 GGUF 量化模型

    Hugging Face 宣布 transformers 现已支持直接加载 llama.cpp 的 GGUF 量化权重,只需在 from_pretrained 中传入 gguf_file 即可,无需额外配置。在 MacBook Pro M2 Max 上对三个 GGUF checkpoint 的测试显示,transformers 的生成速度接近 llama.cpp,但前者包含 prefill 而 llama-bench 只统计解码吞吐。当前打包推理路径仅支持 MPS,覆盖 Qwen3.5 稠密与 MoE 架构,填充批处理性能仍有待改进。

    What is the GGUF file format? GGUF packages model weights and metadata, including tokenizer information and an optional chat template, in one file. It supports different quantization levels, letting you trade some precision for a smaller memory footprint. Variants such as Q4 K M mix tensor precisions, using mostly 4-bit weights while keeping sensitive tensors at higher precision. Here's how quantization changes the file size of Unsloth's Qwen3.5-4B : We suggest starting with Q4 K M , then trying

    匹配字段正文

星期四

  1. Baseten 工程博客

    Baseten 发布 Hosted Tools,首推网页搜索 Grounded Inference

    Baseten 发布 Hosted Tools,首个工具为网页搜索 Baseten Grounded Inference,首批接入 Exa、Keenable、Parallel 和 You.com 四家搜索服务商。开发者只需在 Messages、Chat Completions 或 Responses 请求中加一项配置即可启用,搜索在 Baseten 推理栈内服务端执行,模型按原生工具调用能力自行决定是否检索并迭代。Baseten 称其基准测试中端到端延迟比客户端工具方案降低 15%,该功能目前以 playground 预览形式开放,限速 25 RPM 并赠送 2 美元额度。

    Baseten hosted tools

    ontext stays server-side, reducing parsing round trips; Eager and concurrent tool execution while model streams; Graceful failures; Live SSEs of every granular step and additional metadata for observability; Mixed tool support (client and hosted tools) One platform for models and agents Baseten has focused on making models fast, reliable, and easy to operate in production. Baseten Hosted Tools expands that foundation to the capabilities models use at inference time. Baseten Grounded Inference is

    匹配字段正文

  2. A6 a6-047 · Baseten 工程博客

    Baseten 推出 Hosted Tools,首发网页搜索 Grounded Inference

    Baseten 发布 Hosted Tools,首个类别为网页搜索,联合 Exa、Keenable、Parallel 和 You.com 四家搜索提供商,开发者只需在 Messages、Chat Completions 或 Responses 请求中加一行配置即可启用。Baseten 称托管工具把工具调用放进服务端智能体循环,相比客户端工具端到端延迟降低 15%,并支持流式输出工具调用与结果。该功能目前处于 playground 预览阶段,限速 25 RPM,附赠 2 美元免费额度。

    n Context stays server-side, reducing parsing round trips Eager and concurrent tool execution while model streams Graceful failures Live SSEs of every granular step and additional metadata for observability. Mixed tool support (client and hosted tools) Baseten has focused on making models fast, reliable, and easy to operate in production. Baseten Hosted Tools expands that foundation to the capabilities models use at inference time. Baseten Grounded Inference is the first step. Over time, we’ll a

    匹配字段正文

星期三

  1. Latent Space

    TypeSafe 发布决策模型 Jev,称比小型前沿 LLM 快 100 倍以上、便宜 200 倍以上

    TypeSafe 发布 Jev,一款用 RLCD 训练、只做决策/分类/路由/打分的非自回归模型,官方称比小型前沿 LLM 快 100 倍以上、便宜 200 倍以上,输出 token 免费。社区指出它并非通用语言模型,不能生成自由文本,需要预定义输出格式,更适合替代生产系统中作为结构化分类器、评判器或路由策略的 LLM 调用。

    per benchmarks: vertically integrated labs producing proprietary data, models trained against scientist-calibrated rewards, and deployment back into experimentation. The strongest meta-observation came from @richardczl : every company with a meaningful data moat will likely try this play, shifting bottlenecks toward RL rollout throughput, verifier compute, and weight sync . Gemini 3.8 Live and the Push Toward Real-Time Voice Agents Google’s new live audio models : Google launched Gemini 3.8 Live

    匹配字段正文

  2. The Rundown AI

    ChatGPT 共同创作者 Diogo Almeida 的 TypeSafe 推出 Jev

    前 OpenAI 研究员 Diogo Almeida 的 TypeSafe 结束隐身状态,推出 Jev,一种在软件内部回答预设问题并附带置信度分数的 AI 系统,官方称其零幻觉。Jev 定价为每 10 亿输入 token 42 美元、输出免费,TypeSafe 估算比 Claude Fable 5.1 低 238 倍,响应时间 70 至 500 毫秒,比当前 LLM 快 40 至 200 倍。它只在预先设定的选项之间选择,可用于应用内的快速判断,如分类请求、给记录打分或筛查其他 AI 输出是否越狱。

    g AA's speech-to-speech quality ranking. Odyssey introduced Odyssey 3, a world model that can control robot arms, humanoids, self-driving cars, drones, and games, set to release in the coming weeks. A 404 Media report detailed OpenAI’s ‘Project Lily’, finding that hundreds of human contractors read and rate real ChatGPT chats, often without the user’s knowledge. Meta rolled out Meta One, a new paid tier across its apps running from $2.99 to $499 a month for extra Meta AI usage and creator tools.

    匹配字段正文