←搜索结果

按匹配度 · 共 1146 条结果 清除搜索

星期三

  1. Andrew Ng

    OpenWorker 发布新版本,内置面向安全流程的智能体

    开源智能体 OpenWorker 发布新版本,内置三类网络安全智能体,分别用于扫描代码漏洞、扫描依赖中的供应链注入以及检查云安全配置中的攻击面,让开发者在部署前完成更多安全工作。OpenWorker 的 harness 完全开源,安全团队可审计其是否会把代码和数据外传;模型可自选,既能完全本地运行开放权重模型,也可使用 ChatGPT 订阅、Ox Alpha 等预览模型或任意 API key 接入。Andrew Ng 表示该工具与 @rohitcprasad 合作推进。

    OpenWorker -- an open source agent that doesn't just chat but completes tasks on your laptop -- just released a new version with many features for security workflows. After our initial release, many users found it especially useful for cybersecurity. Attackers are already using AI; OpenWorker is committed to giving defenders the same leverage. Running an agent requires both (i) A model and (ii) A harness (the software around the model). Because the OpenWorker harness is fully open source, securi

    匹配字段正文

星期一

  1. NVIDIA Developer · Generative AI

    NVIDIA Groq 3 LPX 在 Vera Rubin 上实现长上下文超快交互

    NVIDIA 发布面向 Vera Rubin 平台的交互式 AI 推理加速器 Groq 3 LPX,Artificial Analysis 在 100K 上下文下用 Gemma 4 31B 实测中位输出速度为 3,431 tokens/秒,10K 上下文下为 3,382 tokens/秒。该加速器采用确定性执行模型,由编译器预先调度芯片间通信并细粒度重叠计算与通信,可与 Vera Rubin NVL72 组合用于 prefill-decode 分离、attention-FFN 分离和外部草稿模型投机解码等配置。在 SPEED-Bench 编码基准上,同一系统用 Gemma 4 达到中位 4,767 tokens/秒、P80 为 5,520 tokens/秒。

    LPX, measuring a world-class interactivity of 3,431 output tokens/second. The technologies that power this performance unlock the ability of the Vera Rubin platform to serve multiagent systems powered by 2T+ parameter models with high interactivity and long context, through pairing Groq 3 LPX with Vera Rubin NVL72. Agentic sessions are characterized by multiturn inference. At the end of each turn, the agent’s output is appended to the continually growing context that is fed into all subsequent

    匹配字段正文

星期五

  1. LMSYS Blog

    SGLang 推出 Weight Cache Daemon,引擎重启权重加载从 495 秒降至 0.63 秒

    SGLang 发布 Weight Cache Daemon,这是一个常驻 GPU 进程,把量化后的模型权重留在显存中,通过 CUDA IPC 零拷贝映射给新的引擎实例。基于 Ling-2.6-1T FP8 模型,权重加载从约 495 秒降到约 0.63 秒,端到端启动时间从 8.8 分钟降到 0.528 分钟,减少 93.9%。该组件是 Fast Engine Recovery Framework 的第一阶段,目标是把冷重启压到 10 秒以内、热备切换压到 1 秒以内,目前支持 TP+PP、单机与多机启动,以及未量化和 block-wise FP8。

    cross-node daemon coordination, lifecycle management, and failover; Weight update without reload: in-place weight refresh for RL / online updates, with the daemon as the delivery agent; Cross-GPU & fleet sharing: peer-copy and fleet-fill so a cluster cold start pays roughly one disk read per shard group; KV cache restore: preserve and remap KV cache across restarts / failover (KV reuse, handoff to standby) so in-flight context survives recovery instead of being recomputed from scratch; Rest of

    匹配字段正文

星期三

  1. xAI News

    xAI 的 Grok 4.6 在 Amazon Bedrock 正式可用

    xAI 宣布 Grok 4.6 已在 Amazon Bedrock 正式可用,Amazon Bedrock 用户可通过该平台调用这一旗舰模型。Grok 4.6 面向长时间运行的智能体和交互与视觉任务,提供 500k 上下文窗口以及 low、medium、high、xhigh 四档可配置推理强度。定价为输入每 100 万 token 2 美元、缓存输入每 100 万 token 0.50 美元、输出每 100 万 token 6 美元。

    Today, we’re excited to announce that Grok 4.6 is now generally available on Amazon Bedrock. Grok 4.6 is our latest flagship model, built for long-running agents and ambitious interactive and visual work. It offers 500k context window and configurable reasoning efforts (low, medium, high, xhigh). Now, Amazon Bedrock users can leverage the model through Amazon Bedrock. Capabilities & Pricing Grok 4.6 is available for: Input : $2 per 1 million tokens Cached input : $0.50 per 1 million tokens Outpu

    匹配字段正文

  2. Comfy Blog精选

    Comfy 开源本地版 Comfy MCP,智能体可直连本地 ComfyUI

    Comfy 开源本地版 Comfy MCP,Claude、Codex、Cursor 等 MCP 客户端可连接本机安装的 ComfyUI,构建、编辑和运行工作流。该 MCP 服务器同时支持本地与云端,智能体可读取本机 GPU、已安装节点和磁盘上的模型,判断某个模型是否适合本地运行,并负责下载权重、启动本地实例和搭建工作流。官方给出的示例是让智能体在本机搭建并运行 MiniMax H3 工作流。

    Jo Zhang's avatar

    Your agent runs local ComfyUI and builds workflows around your GPU, your models, and your custom nodes. Works from Claude, Cursor, Codex, or any MCP client. Today, Comfy MCP runs on your own machine. Connect Claude, Codex, Cursor, or any other agent to the ComfyUI installed on your local setup. This is the number one thing you asked for after Cloud MCP shipped in June, and the MCP server is fully open source. Comfy MCP is now one MCP with both local and cloud. Everything the Cloud MCP connection

    匹配字段正文

星期二

  1. LMSYS Blog精选

    LMSYS 发布 Miles v0.1 生产级后训练系统

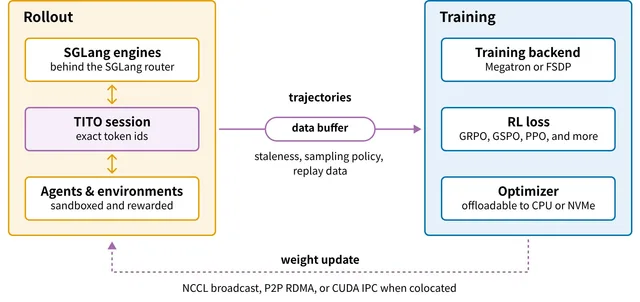
    LMSYS 发布 Miles v0.1,定位为面向前沿模型后训练的全栈生产级系统,是首个 Miles 版本的后续。它把 RL 训练循环拆成 SGLang 生成、训练器更新与权重同步三段,支持完全异步 RL、TITO 精确 token 记录、R3 路由重放,以及 NVFP4、MXFP8、FP8 等低精度训练配方。官方给出在 64 张 NVIDIA GB300 上训练 GLM-5.2 744B-A40B 终端任务的参考运行,稳定完成 100 步 rollout,单步训练约 4.5 分钟,前缀缓存命中率 96%。

    The Miles fully async RL loop

    Contents The Miles RL Loop; Rollout; Fast Agentic Rollout by SGLang; Fully Async RL; Agentic Environments; Token-In-Token-Out (TITO); Efficient Rollout Routing Replay (R3); Training; Low-precision Training; Memory Efficiency & Disk Offload; Two Training Backends; Weight Update; Verified Day-0 Model Support; Other Post-Training Recipes; LoRA RL; On-Policy Distillation (OPD); Zero-KL Alignment; Code Quality Principle; Miles-Diffusion; Multi-Hardware Support; Example: Training GLM-5.2 on Terminal-U

    匹配字段正文

星期六

  1. Augment Code 博客

    Augment Code 重建 Auggie CLI 架构,任务成本比 Claude Code 低 53%

    Augment Code 宣布重建 Auggie CLI 的 harness,在 SWE-bench Pro 上相同通过率下,Auggie v2 完成任务成本为 $1.27,比 Claude Code 的 $2.70 低 53%。重建基于开源项目 Pi,通过精简工具面、用检索代替探索和主动压缩上下文实现效率提升,CLI 将于 9 月或 10 月推出。

    How we rebuilt the Auggie CLI harness to make tasks 53% cheaper than Claude Code

    in anything customer-facing. There are two levers on value per token. One is the context engine: better context means better answers in fewer tokens. The other is the harness: the agent loop, the tool surface, session management, everything that turns model capability into finished tasks. We started by building the industry's leading context engine, and now we've made a major investment in improving the harness. Earlier this year we rebuilt the Auggie CLI's harness from the ground up. On SWE-ben

    匹配字段正文

星期五

  1. xAI News

    Grok 4.6 上线 GitHub Copilot

    xAI 宣布 Grok 4.6 已在 GitHub Copilot 上线,面向 VS Code 和 GitHub 上的开发者。用户在模型选择器中选择 Grok 4.6 即可使用,部分企业账号需先在 Copilot 设置中启用该模型。该模型同时通过 SpaceXAI console 提供,定价为每百万输入 token 2 美元、每百万输出 token 6 美元。

    now live in GitHub Copilot for the millions of developers who work in VS Code and across GitHub every day. Getting started GitHub Copilot covers several products, including cloud agents, the Copilot CLI, and the VS Code IDE. Open the model picker and select "Grok 4.6" to start using our latest coding model. Some businesses and enterprises will need to enable the model from Copilot settings. Grok 4.6 is also available from the SpaceXAI console at $2 per million input tokens and $6 per million ou

    匹配字段正文

星期四

  1. Cursor Blog精选

    Cursor 推出 builds 功能,云端智能体启动速度提升 3 倍

    Cursor 推出 builds 功能,在后台持续准备开发环境副本,使云端智能体启动速度提升至 3 倍,内部环境启动速度提升 10 倍。当构建失败时,智能体会继续使用上一次成功构建,避免工作中断。该功能将于 8 月 17 日默认启用,不额外收费。

    Build details in the Cloud Agents dashboard, including logs and commit SHAs

    Table of Contents Agents are only as capable as the environments they run in. Fast, reliable development environments allow agents to take ambitious, long-running tasks from start to finish. Until now, every cloud session began with extensive setup: boot a machine, clone the repositories, and run the install script. On a large, complex repo, this just-in-time boot could take several minutes before the agent started executing. Today we're introducing builds: ready-to-use copies of your developmen

    匹配字段正文

  2. NVIDIA Developer · Generative AI精选

    NVIDIA 在 GB300 NVL72 上部署 Qwen3.8-2.4T-A95B,单 GPU 吞吐超 4K tokens/s

    NVIDIA 发布在 GB300 NVL72 上部署阿里开源权重模型 Qwen3.8-2.4T-A95B 的方案,该模型总参数 2.4T、每 token 激活 95B,采用细粒度 MoE 与全注意力加线性注意力混合架构,上下文窗口最高 100 万 tokens。在 FP8 精度下 Day 0 即实现单 GPU 超 4K tokens/s、单用户超 350 tokens/s,NVFP4 优化预计带来进一步提升。SGLang、vLLM 和 NVIDIA Dynamo 提供开源推理配方,也可通过 NVIDIA NIM 容器部署,并可用 NeMo AutoModel 做全量 SFT 或 LoRA 微调。

    oE) architecture with a hybrid of full and linear attention, a context window of up to one million tokens, and an output length of up to 128K, designed for demanding reasoning and agentic workloads. Deploying a 2.4T parameter open-weight model requires data-center-scale accelerated compute. Inference at this scale depends on extreme co-design across chips, system architecture, and software. NVIDIA is working with the open-source ecosystem to bring the model to multinode deployments through optim

    匹配字段正文

星期三

  1. Sakana AI:Blog

    Sakana Chat 更新:新增 Sakana Fugu 并升级 Sakana Namazu

    Sakana AI 更新 Sakana Chat,新增号称性能对标前沿模型的编排模型 Sakana Fugu,并将 Sakana Namazu 升级到新一代,日语回答质量与智能体执行能力均超过旧版。新版支持在沙箱中执行 Python,生成结果在右侧面板预览,HTML 按实际效果渲染,Word 和幻灯片按文档查看并可下载,还能在对话中直接修改重做。此外所有模型均支持图片附件,并可读取 PDF、Office 等文档进行总结或分析。

    ps. Sakana Namazu, meanwhile, has been upgraded from its original release to a new generation of the model. It surpasses the previous version in both Japanese response quality and agentic execution capability. Sakana Namazu is developed with an emphasis on taking Japanese instructions as they are and returning natural Japanese documents and materials, making it a great fit for the tasks that come up again and again in daily work. For more details on Sakana Namazu, please visit Namazu Product Pag

    匹配字段正文

  2. OpenRouter:Announcements

    OpenRouter 上线实时网页搜索基准榜,对比模型、引擎与搜索轮次

    OpenRouter 发布实时网页搜索基准榜,在 BrowseComp、DeepSearchQA、WideSearch、HLE 四套基准上对比不同模型、搜索引警与搜索轮次的组合。其数据显示,把搜索轮次从 1 次提到 25 次对质量的提升大于其他单项改动,成本约为每题的 2.5 至 7 倍;固定模型更换引擎平均带来 10 分变化,而前沿模型与低成本模型之间平均差距为 15 分。这些配置已作为 OpenRouter 的请求参数开放,包括 web plugin、server tool、engine 和 max_tool_calls。

    cky decisions: take the native search some labs build in, or wire up a third-party engine like Exa, Parallel, or Perplexity? Is one search enough, and if not how long do I let the agent keep searching? Are more search turns worth the quality they buy? We built live leaderboards to help you decide the best search configuration with data. See the data on our new Benchmarks page. We benchmark all the combinations to find strengths and weaknesses When setting up a search request, you have four decis

    匹配字段正文

星期二

  1. NVIDIA Developer · Generative AI精选

    NVIDIA 发布 NeMo Switchyard,为 AI 智能体提供跨模型路由

    NVIDIA 发布 NeMo Switchyard,为 AI 智能体提供跨模型路由能力,可在专用模型与前沿模型之间按任务分配请求,以平衡性能、成本与效率。该工具提供免调优的 LLM 分类器、阶段路由器和升级路由器,也支持基于工作负载数据训练的预填充路由器,并可通过 OpenAI、Anthropic 和 Responses API 接入。LangChain 在 145 个多轮智能体任务上测试升级路由器,在 Nemotron 3.5 Lightning 与 Claude Opus 4.8 之间路由,仅 7% 调用发往前沿模型,成本降低 74%,准确率约有 6 个百分点的折让。

    removeItem('facets.search.text'); sessionStorage.removeItem('facets.search.text-copy'); sessionStorage.removeItem('facets.search.filters'); Learn how NVIDIA NeMo Switchyard routes agent workloads across specialized and frontier models to balance performance, cost, and efficiency. AI-Generated Summary Powered by NVIDIA Nemotron. AI-generated content may summarize information incompletely. Verify important information. Learn more Building an AI agent does not end with choosing a single model. Each

    匹配字段正文

  2. Mistral AI

    Mistral 推出区域推理端点与优先级服务层,并接入第三方开源模型

    Mistral 宣布 Mistral Regional Endpoints 正式可用,客户可选择推理在欧洲或美国运行,同时 Mistral Priority Tier 进入公开预览,提供自定义速率限制和带 SLA 的可用性承诺。其平台还将支持第三方开源模型,首个接入的是 Z.ai 的 GLM-5.2,这些模型将运行在与 Mistral 自有模型相同的基础设施、区域控制和服务承诺之上。Mistral 同时组建企业联盟,通过 European Compute Units 汇集多年期算力承诺,并计划到 2030 年建成最高 1 GW 的算力容量。

    te as their needs evolve. "As the neutral execution layer and trusted system of record at the core of the global travel industry, Amadeus bridges raw foundational data with modern Agentic AI to improve the traveller experience for everyone everywhere. In an AI-driven world, capacity, deployment control, and operating continuity become increasingly important for all enterprises. Equally crucial, at the same time, is ensuring businesses have the confidence to make long-horizon commitments at scale

    匹配字段正文

  3. 腾讯混元

    腾讯混元发布 Hy3D WorldClaw,用文本提示词生成大规模 3D 开放世界

    腾讯混元发布 Hy3D WorldClaw,一个从文本提示词生成大规模 3D 开放世界的智能体工作流。官方强调它不是视频也不是 Gaussian Splatting,每个场景都可自由探索,且完全由可编辑、可直接用于游戏的 3D 资产构建,具备高质量几何与纹理。项目页面:https://t.co/KJXFWHLb1S

    Introducing Hy3D WorldClaw——an agentic workflow that generates large scale 3D open worlds from text prompts.🚀🚀🚀 Not video, Not Gaussian Splatting, Every scene generated by WorldClaw is freely explorable and built entirely from editable, game-ready 3D assets with high-quality geometry and textures. Project Page: https://t.co/KJXFWHLb1S

    匹配字段正文

  4. xAI News精选

    xAI 发布 Grok Bot,可交付真实工作的 AI 队友

    xAI 发布 Grok Bot,定位为可以交付真实工作的 AI 队友。每个 Bot 拥有云端独立电脑,可登录你已在使用的工具,跨应用、收件箱和网站工作,包括没有干净 API 或 MCP 的平台,任务完成到需要你审批时才回来。用户像给同事发消息一样派活,Bot 会记住对话、学习你的工作方式,并可多个并行协作、互相传递上下文;xAI 称其最初是内部原型,已在公司内用于销售外呼、营销活动、办公运营和修 bug 等场景,现对外开放。

    and more. Today we’re excited to open it up to the rest of the world. How Grok Bot is different A computer of its own Early access users say Grok Bot feels less like prompting an agent, and more like giving work to a highly capable teammate. Bots share a computer of their own in the cloud, so jobs do not stall when you step away. They can sign in and work across apps, tools, and websites, including platforms with no clean API or MCP, and come back with the work finished. Inside SpaceXAI, that a

    匹配字段正文

  5. LMSYS Blog精选

    SGLang 为 NVIDIA Nemotron 3.5 Lightning 提供 Day-0 支持

    SGLang 宣布为 NVIDIA Nemotron 3.5 Lightning 提供 Day-0 支持,开发者可通过其 OpenAI 兼容推理栈部署该模型。Nemotron 3.5 Lightning 是从 Nemotron 3 Ultra 蒸馏而来的 30B 混合 MoE 模型,每 token 仅激活 3B 参数,支持 MTP、DFlash、DSpark 三种投机解码,并可通过 enable_thinking 与 thinking_budget 控制推理开关和深度。模型权重已在 Hugging Face 提供 BF16 和 NVFP4 版本,官方称其在相近准确率下完成智能体任务最多快 30%。

    Contents SGLang is excited to announce Day-0 support for NVIDIA Nemotron 3.5 Lightning, a customizable open model built to power always-on agents across local systems, the edge, the datacenter, and the cloud. Always-on agents gather context, reason, use tools, and adapt across multi-step workflows. Frontier models handle complex orchestration, while smaller models efficiently manage high-volume, specialized tasks. Nemotron 3.5 Lightning is built to handle these high-volume tasks. Distilled from

    匹配字段正文

星期一

  1. LMSYS Blog精选

    SGLang 为 Meta 多模态模型 Muse Glimmer 提供 Day-0 支持

    LMSYS 宣布与 Meta Superintelligence Labs 合作,为 30B 参数多模态模型 Muse Glimmer 在 SGLang 上提供 Day-0 支持,并针对本地智能体工作流推理做了专门优化。在 NVIDIA GeForce RTX 5090 上,SGLang 以 NVFP4 加 DFlash 实现最高 1,452 tok/s 总输出吞吐和 236 tok/s 单用户解码速度,DFlash 将 batch-1 交互性提升 1.9 至 4.3 倍。模型可在 RTX 5090、RTX PRO 6000、DGX Spark 的 SM120 后端以及 Apple Silicon 的 MLX 后端部署,提供 BF16、NVFP4+MXFP8、NVFP4 及 GGUF 等多种 checkpoint 格式。

    e're excited to partner with Meta Superintelligence Labs to bring Day-0 support for Muse Glimmer to SGLang, with dedicated optimizations tailored for high-performance inference of agentic workflows on local hardware. Highlights Model: Muse Glimmer is a 30B-parameter multimodal dense model with a 128k+ token context window that delivers competitive performance on end-to-end agentic workflows from local hardware; Performance: SGLang delivers up to 1,452 tok/s of total output throughput and 236 tok

    匹配字段正文

  2. Amp Chronicle

    Amp 更新 Dial,连接 ChatGPT 订阅后改用 OpenAI 模型

    Amp 更新 Dial,连接 ChatGPT 订阅后,low、medium 和 high 的主智能体、oracle、thread reader 与 code review 均改用 OpenAI 模型,并由该订阅计费。low、thread reader 和 code review 使用 GPT-5.6 Terra,medium 使用 GPT-5.6 Sol,high 的智能体与 oracle 均使用 GPT-5.6 Sol,同时降低启用订阅时的 credits 最低要求。ultra 仍通过 Amp credits 使用 Claude Fable,未连接订阅的用户也维持原有模式。

    The mode picker with the dial on medium, showing GPT-5.6 Sol as agent and oracle and a green ChatGPT subscription LED

    We changed the Dial. Link a ChatGPT subscription and low, medium, and high only use OpenAI models: as the main agent, as the oracle, as the thread reader, as code review. Every model behind those modes is an OpenAI model, billed to your subscription. Before this change, you'd still pay for tokens with a subscription linked, because parts of the work ran on other models: low and the thread reader on GLM-5.2, the high oracle on Claude Fable, code review on Haiku — all billed to Amp credits. That c

    匹配字段正文

星期五

  1. LMSYS Blog

    腾讯混元 HPC-Ops 的 Attention、Router GEMM 与 MoE 算子并入 SGLang 主分支

    腾讯混元开源算子库 HPC-Ops 的 Attention、Router GEMM 和 MoE 三个算子已并入 SGLang 主分支,面向 NVIDIA Hopper(SM90)GPU,并已用 Qwen3、Hy3 和 LongCat 工作负载验证。在 8× H20 上以 Hy3-FP8 同时启用 Attention 与 MoE,batch size 4–64 时 TPOT 降低 15.1–48.8%,batch size 4–16 时 TTFT 降低 3.3–6.0%;LongCat-Flash-Lite-FP8 启用 Router GEMM 后输入吞吐提升 5.5–6.1%。这些算子已在腾讯大规模生产服务中部署,其中 Dynamic Attention 与 Fused MoE 使 Hy3 模型的 TPOT 最多降低 48.8%。

    benchmarks. It combines mixed-length Attention work, precision-sensitive routing, and sparse expert execution within the same latency-sensitive path; long-context, multi-turn, and agentic workloads further widen the distribution of live KV lengths. Serving performance therefore depends not only on raw matrix-multiplication throughput, but also on workload balance, numerical fidelity, and overhead control. These constraints surface in three performance-critical stages of MoE model serving. During

    匹配字段正文