←搜索结果

按匹配度 · 共 3407 条结果 清除搜索

星期二

  1. 蚂蚁 inclusionAI:GitHub 新仓库

    蚂蚁 inclusionAI 在 GitHub 发布 sglang_ling_v3 仓库

    蚂蚁 inclusionAI 在 GitHub 上线 sglang_ling_v3 仓库,内容基于开源推理框架 SGLang,该框架面向大语言模型、视觉语言模型和扩散模型,针对智能体负载、大规模服务与 RL rollout 优化。仓库 README 显示 SGLang 支持 GPU、TPU、NPU、CPU 与 Apple Silicon,并内置图像视频生成引擎 SGLang Diffusion。

    PyPI version

    l/sgl-router protoproto pythonpython rustrust scriptsscripts sgl-model-gatewaysgl-model-gateway testtest tools/sglang-simulatortools/sglang-simulator .codespellrc.codespellrc .coveragerc.coveragerc .dockerignore.dockerignore .git-blame-ignore-revs.git-blame-ignore-revs .gitignore.gitignore .isort.cfg.isort.cfg .pre-commit-config.yaml.pre-commit-config.yaml CODE OF CONDUCT.mdCODE OF CONDUCT.md LICENSELICENSE README.mdREADME.md 仓库文件导航SGLang:面向大语言模型和多模态模型的快速推理 文档 | 示例手册 | 网站 | 博客 | Slack SGLang 是一个

    匹配字段正文

  2. The Verge AI

    CoreWeave 债务承压,AI 行业借贷风险扩散

    The Verge 分析指出,CoreWeave 债券已跌入困境区间,股价自上周二收盘以来下跌超过 20%,并波及 Oracle 等其他举债扩张的 AI 公司。CoreWeave 第二季度财报显示负债超过 350 亿美元、上半年亏损超过 10 亿美元,但客户合同剩余履约义务达 1037 亿美元,其中约 40% 于 2028 年到期且大多不可取消。作者认为股价下跌不等于业务崩塌,真正考验要等 AI 热潮放缓时才会出现。

    problem is not that credit profiles have changed in the last year, it’s that we’ve got another year and a half of supply coming,” Bloomberg quoted John Yovanovic , co-head of leveraged finance at MetLife Investment Management, as saying. I have seen people suggest that this means the AI bubble is bursting. I am not so sure. A plunging stock price is not necessarily financial doom. Stocks are an expression of confidence in a company’s future, not a reflection of day-to-day business. But CoreWeav

    匹配字段正文

  3. MIT Tech Review

    为 AI 智能体改造互联网,可能让普通用户处境更糟

    MIT Tech Review 分析指出,个人 AI 智能体正成为人类与机器人之外的第三类网页访客,但现有区分机制无法容纳它们,部分平台选择直接封禁。OpenAI 的 Dots 和 Meta 的 Muse 等应用推动智能体规模化,Muse 首月下载量达 500 万次,8 月至 9 月智能体网页流量增长两倍。文章认为,若需求持续上升,网站将转向为智能体优化,而规则如何制定将决定智能体是替用户争取利益还是反过来损害普通用户。

    for the humans who are left. That’s a far cry from the future promised by Google , Anthropic , and OpenAI , in which AI agents will give consumers greater power and bargaining leverage. But that promise is not outlandish. Agents are capable of genuinely helping people by fighting bogus medical bills or researching more affordable car insurance, for example. Whether they can actually be used for these purposes depends on what rules are set for how agents interact with websites and what exactly th

    匹配字段正文

  4. Browser Use

    Browser Use 评测五款浏览器控制 MCP 工具:Browser Harness 每任务 token 最低

    Browser Use 在 100 个 BU Bench V2.1 任务上对比了 Browser Harness、Playwright MCP、Chrome DevTools MCP 和 agent-browser,四者得分在噪声范围内打平,Browser Harness 以 2.1M 中位输入 token 和 42 次工具调用成为每任务成本最低($0.042)。作者同时给出选型建议:需要干净会话或 Firefox、WebKit 用 Playwright MCP,调试自家应用性能与网络用 Chrome DevTools MCP,需要域名白名单和加密凭据库用 agent-browser。文章披露作者所在公司开发 Browser Use 和 Browser Harness,竞品信息取自各自仓库与文档。

    ree, and actions target element refs from it. Coordinate clicks only come with --caps=vision. About two dozen tools are on by default, with more behind --caps: network mocking, storage, tracing, PDFs, test assertions. By default it starts its own browser with a persistent profile per workspace, so logins stick between sessions. For a clean start every time, add --isolated. To use the Chrome or Edge you already have open, add --extension and install the Playwright Extension. --browser also gets y

    匹配字段正文

  5. 404 Media

    得州称暂停数据中心许可审批,非营利组织称TCEQ仍在推进

    Public Citizen 与 FracTracker Alliance 查阅得州环境质量委员会(TCEQ)公开数据库后称,自州长 Abbott 于 9 月 21 日要求暂停数据中心许可以来,该机构仍处理了十余项相关许可,其中 14 份燃气电厂和发电机组申请中有 12 份在 10 月提交、8 份走了加急审查。Abbott 办公室与 TCEQ 均回应称未批准任何数据中心相关许可,TCEQ 表示正在遵守州长指令。FracTracker 的 Sam Law 指出,Abilene 的 Stargate 设施等项目通过通用雨水施工许可的意向通知获得批准,因此并非真正的暂停。

    nters. According to the documents reviewed by 404 Media, TCEQ issued air-emission limit certificates to a large data center in Houston; approved the construction of stormwater coverage for data centers in Abilene, Barstow, and Royse City; and fast tracked gas power plants for more than a dozen data center projects. “The TCEQ’s own data indicates that it’s business as usual for data centers and affected communities were promised a freeze. And instead what they’re getting is another reason to dist

    匹配字段正文

  6. MarkTechPost

    Nace AI 发布多模态决策模型 Drex Max,Decision Index 得分 67.59

    Nace AI 发布 Drex Max,这是其首个多模态决策模型,可读取文本和图像并返回校准后的概率,不生成文本。该模型在公开 Decision Index 0.3.2 上得分 67.59,比 TypeSafe 的 Jev 1.14 高 6.9 分;单次截图决策中位延迟 174 ms,输入定价为每 1M tokens 0.06 美元,输出不计费。模型仅通过 Nace Console API 提供,参数规模未披露、权重闭源,上述分数均为 Nace 自报。

    n JevBench, Drex Max reaches 92.2 against 86.7 for Jev 1.14. Agentic benchmarks: Drex Max posts 0.780 on OSWorld-Verified and 98.2 on BFCL. It scores 85.2 on When2Call and 84.8 on RAGTruth. Vision: On the Decision Index Vision public suite, Drex Max scores 74.5. GPT-6 Luna Decisions scores 63.9. Mind2Web reaches 88.6 and InfographicVQA reaches 98.8. Where it trails: Jev 1.14 leads on MMLU-Pro (82.1 vs 72.5), HLE (19.4 vs 19.0) and ARC-Challenge (97.6 vs 97.4). On Hateful Memes, Drex Max trails G

    匹配字段正文

  7. MarkTechPost

    Inception 发布扩散语言模型 Mercury 3,速度达 1068 tokens/s

    Inception 发布扩散语言模型 Mercury 3,官方称在 NVIDIA GPU 上达到 1068 tokens/s,上下文窗口为 1M token,参数量未披露但超过 Mercury 1 的 40 倍。在 Inception 自报的 12 项基准中,Mercury 3 在 8 项上领先 GPT-6 Luna 和 Claude Haiku 5.5,其中 SWE-Bench Atlas 为 51.08、IFBench 为 76.84,但在 DeepSWE v1 和 MRCR v2 上落后于 Haiku 5.5。模型已上线 Inception API Platform、OpenRouter、Baseten 和 Vercel,API 兼容 OpenAI,模型名为 mercury-3,发布价为每百万 token 输入 0.10 美元、输出 0.35 美元,之后恢复为 0.20 美元和 0.70 美元。

    hether this approach holds up as models grow larger. Does diffusion scale? Here Inception’s answer is yes. Mercury 3 has more than 40x the total parameters of Mercury 1 (mini). Average quality across standard benchmarks rose about 3x between those 2 models. Speed stayed above 1,000 tokens per second. Inception team plots this as a quality vs size curve across 5 Mercury generations. How does Mercury 3 perform on benchmarks? All scores below come from Inception’s table. Every model ran at medium s

    匹配字段正文

  8. MarkTechPost

    Cloudflare 在 Workers AI 上发布 Clairic 提取模型预览

    Cloudflare 在 Workers AI 上发布 System One 提取模型 Clairic 的预览版,它读取文本或最多 4 张图片,直接返回带类型的值而非生成文本,单次前向传播即可回答所有字段。该模型支持 65,536 token 上下文,按 $0.10/百万输入 token 计费且不收取输出费用,权重尚未发布。Cloudflare 在理赔流程测试中称,Clairic 提取步骤耗时 0.46 秒,GLM-5.3 为 16.1 秒,整体流程快约 3.2 倍,每百万次成本从 $11,740 降至 $6,032。

    and returned null for the absent discount. Its lowest confidence was 0.776, on the order number. For forecasting, Cloudflare predicted daily TSA checkpoint counts for 21 days. Average error was 3.3%. 17 of 21 actual counts fell inside the 80% interval. 3 of the 4 misses fell on Columbus Day weekend. The main test is a damaged-product claims pipeline. Clairic extracted facts, Clef chose refund or repair, and GLM-5.3 wrote the reply. Cloudflare compared this against GLM-5.3 handling all 3 steps.

    匹配字段正文

  9. MarkTechPost

    Exa 发布 3.0 搜索 API,新增 Lite 类型并称 8 项基准领先

    Exa 发布面向 AI 智能体的搜索 API Exa 3.0,新增更便宜的搜索类型 Exa Lite,每 1000 次请求 4 美元,与 Auto 共用同一索引;Dynamic Highlights 转为正式可用,官方称比整页文本少用 95% token 且不额外收费。Exa 称 Exa 3.0 Auto 在 8 项基准上均领先 Perplexity、Brave 和 Parallel,其中 BrowseComp 为 91.8%,ATLAS 为 42.0% 对 Perplexity 的 37.2%,但这些基准均由 Exa 自行运行,ATLAS 也是 Exa 自己发布的基准。Auto 每 1000 次请求标价 7 美元,高于三家竞品的 5 美元。

    y available: The model selects tokens across all results, not page by page. It gives more tokens to better pages and drops repeated information. Billions of new documents: New coverage includes products, local businesses, flights, events, sports and weather. According to the Exa’s post, Dynamic Highlights uses 95% fewer tokens than full page text while improving answer quality. Highlights carry no extra charge. That matters for agents, where context tokens often cost more than search calls. What

    匹配字段正文

  10. Meta Engineering Blog

    GenRecs Tokenization:Meta 用稳定语义词表改造广告推荐

    Meta 推出 GenRecs Tokenization,用稳定语义词表中的 token 表示广告、商品、页面等条目,替代为每个条目维护专属 ID。该方案与 Meta 的 GEM 和 Adaptive Ranking Model 配合,在广告主转化上带来 +0.35% 提升(Meta 内部数据,2026 年 2 月测量)。它让模型能借助共享概念理解从未有过互动记录的新广告和新商品,并支持跨广告系列迁移洞察。

    rs (GenRecs) represent a paradigm shift from scoring every ad to reasoning about ad content and user preferences together in order to predict the best outcome for advertisers. Leveraging the world knowledge built into LLMs makes ad matching more intelligent and precise, compounding gains for advertisers. GenRecs Tokenization is the foundational data representation that makes this possible. Rather than maintaining a dedicated ID for every item, GenRecs Tokenization represents each item with a set

    匹配字段正文

  11. Stanford HAI News

    斯坦福 HAI 发布医疗 AI 基准:最强智能体单次仅完成 46% 临床任务

    斯坦福 HAI 用三年时间构建 MedHELM、PhysicianBench 和 HealthAdminBench 三套医疗 AI 基准,发现当前最强智能体完成不足一半的真实临床与行政任务。PhysicianBench 中 GPT-5.5 单次完成 46% 任务,开源模型 DeepSeek V4-Pro 为 19%;HealthAdminBench 中 Claude Opus 4.6 端到端完成 36.3%,Kimi K2.5 为 15.6%。作者指出主要失败是跨步骤、文档和系统时丢失信息,改进方向在智能体架构与记忆,而不只是更大的模型。

    specialties. A separate panel of physicians independently reviewed each task. The tasks are attempted against synthetically reconstructed patient records in an EHR sandbox. An average multi-step task takes 27 tool calls. Collectively, evaluating the task results in 670 checks in total, covering data retrieval, clinical reasoning, action execution, and documentation. Grading is execution-grounded: Task-specific scripts check whether the right orders exist in the record, with LLM judgments for th

    匹配字段正文

星期一

  1. PyTorch Blog精选

    PyTorch 发布 TorchNeuron:面向 AWS Trainium 的原生后端

    PyTorch 宣布开源原生后端 TorchNeuron,让 Trainium 成为标准 PyTorch 设备,模型代码只需改为 .to('neuron') 即可运行,10 月 20 日以 Apache 2.0 协议在 github.com/aws-neuron/torch-neuronx 开放公测。该后端基于 PrivateUse1 和 torch.accelerator 扩展点,支持 eager、自适应 eager 与 torch.compile,并覆盖 DDP、FSDP2、张量并行等分布式 API 以及 NKI 自定义算子。官方称已在 10 万个 Hugging Face 模型上做覆盖测试,Hugging Face Transformers v5、Diffusers、vLLM Neuron 等可直接在 Trainium 上使用。

    n is a plugin to vLLM and serves LLMs; vLLM Omni Neuron is a plugin to vLLM Omni and serves diffusion models for image and video generation. Ops and dtypes Broad aten operator coverage for ops seen across text, multimodal and vision language, image and video generation and understanding, state space models, and world models. Models can use BF16, FP32, and FP16, with integer and boolean types, and torch.autocast and mixed precision code operate as written. TorchAO and FP8 are currently supported

    匹配字段正文

  2. Wired AI精选

    迪士尼要求 Character.AI 走破产程序以规避诉讼责任

    Character.AI 本周宣布破产,法庭文件显示这是迪士尼交易的一部分:迪士尼已支付 550 万美元并雇佣包括前 CEO Karandeep Anand 在内的多数员工,还计划通过破产拍卖获得其代码、训练基础设施和年龄预测技术等永久非独占许可,若中标将再支付 1250 万美元。剩余实体将继续承担多起人身伤害诉讼和 46 个州及地区的调查责任,迪士尼起草的法庭令拟明确该交易不构成合并。Character.AI 此前在 2024 年 8 月已与 Google 达成 27 亿美元的授权交易。

    ciation of Attorneys General on behalf of 40 states, those states’ investigations uncovered “serious issues” with Character.AI, including screenshots of Character.AI chatbots encouraging minors to hide their self-harm injuries and kill their parents. A spokesperson for Character.AI says that the filing “is not an accurate portrayal of the safety of our platform.” The filings say that Character.AI was in the process of negotiating with the states over how to address the issues they identified, bu

    匹配字段正文

  3. MIT Tech Review

    The Download:保护北极永久冻土,以及爱玩耍的 AI 智能体

    MIT Tech Review 的 The Download 栏目本期聚焦两项研究:研究人员在阿拉斯加大学费尔班克斯分校的森林中追踪 2021 年野火对永久冻土的加速融化影响,并探索防火如何帮助碳留在地下;另一项实验中,AI 智能体被反复单独留在虚拟荒岛上 30 小时,它们开始自行探索世界边界并设定目标,例如攀爬地图最高点或测试能把方块扔多高,研究者讨论这算真正的玩耍还是角色扮演。此外,X-energy 的 Xe-100 反应堆拟用氦气冷却、输出 80 兆瓦电力,为重工业提供超高温蒸汽。

    med. ( New Scientist $) 10 Amateurs are cracking long-secret codes and ciphers 🕵️ One of the more fun uses for large language models! ( Nature ) Quote of the day —President Trump brags about how much Big Tech bends the knee to him during a rally in Kentucky this weekend, the Verge reports. One More Thing In the last few months alone, Microsoft, Amazon, and OpenAI have all launched medical chatbots. There’s a clear demand for these tools, given how hard it is for many people to access advice thro

    匹配字段正文

  4. AIhub

    AI 如何缓解无线电频谱的稀缺竞争

    AI 正被用于动态频谱共享,以缓解无线电频谱的稀缺竞争:软件定义无线电让设备可按软件切换频率,次级用户可在主用户空闲时接入同一频段。美国 CBRS 在 3.5 GHz 频段采用三层体系,由 Spectrum Access System 实时协调,海军雷达需要时其他用户数秒内让出频谱。研究者的实验室正借助 AI 学习经验、实时适应,决定谁在何时以何种功率发射,以应对信号干扰这一最大技术障碍。

    airwaves Every time you make a phone call, stream a video or connect to Wi-Fi, your device is sending and receiving invisible signals through the air. So are your baby monitor, garage door opener, your GPS, the weather-monitoring satellites and the radars keeping planes safely apart. All of these rely on the same invisible resource: the radio spectrum. The demand for wireless data – driven by smartphones, video streaming and billions of connected devices – keeps growing, making available spectr

    匹配字段正文

  5. Exponential View

    周一数据:贸易战谁赢了?

    八年关税战使中国占美国商品进口份额从2010年代中期的约21%降至今年夏天的约8%,但中国通过将产能转移至越南、墨西哥等地绕开关税。2020至2023年,中资工厂贡献了越南对美出口的25%,高于2018至2019年的11%。

    a, nearly half of America’s goods deficit of $792 billion), target intellectual property theft and counter Chinese policies that favored domestic companies; and improve the US leverage by reducing its dependency on China. On paper, some of that worked. But look closer, and you see that China didn’t disappear. Supply chains got a remapping instead. Today’s Monday Data looks at what eight years of tariffs have really achieved. Mind the label The immediate impact of tariffs on China was a drop in t

    匹配字段正文

  6. 量子位

    通研院孵化的通衍灵智,用RSI做递归自进化个性化智能

    北京通用人工智能研究院孵化的通衍灵智聚焦 Recursive Self-Improving Personal AI,以共享基础模型加轻量 Personal LoRA 承载个人与企业的专属能力,并通过 Evaluator 筛选反馈、版本回滚控制持续学习。其 TIP 训推并行与 Paged LoRA 在 Qwen2.5-72B-Instruct、8 张 NVIDIA H800 上把 LoRA 显存预算控制在 5.79GB,但 LoRA 请求占比升至 50% 时仍出现性能退化,完整自动化闭环尚在研发中。

    程师知道哪些模块不能轻易调整,也清楚什么时候需要优先考虑稳定性而非技术上的最优解。 这些经验一部分记录在文档中,更多则分散在长期的代码修改、方案讨论和项目实践里。 类似情况也存在于金融投研、企业运营等领域。通用模型可以分析市场、理解业务流程,但不同团队长期形成的风险偏好、决策习惯和工作方法,往往需要通过持续协作才能逐渐掌握。 目前,AI主要依靠Prompt、RAG、Memory和Skill等机制适应具体场景。它们分别承担指令约束、知识检索、状态保存和能力复用等任务,已经成为企业应用大模型的重要组成部分。不过,这类机制主要在模型外部组织信息,模型自身的参数通常不会因为一次业务交互而发生变化。 当个性化需求从信息获取延伸到长期行为模式,参数化学习提供了另一种技术选择。 通衍灵智采用共享基础模型(Base Model)与个性化参数(Personal Parameters)相结合的架构。 基础模型提供通用知识和推理能力,不同个人、项目和企业则通过轻量化的Personal LoRA进行参数适配,将经过验证的专业偏好和行为特征逐步融入模型。 与传统行业模型主要解决不同行业之间的能力差异相比,这一路

    匹配字段正文

  7. Meta Engineering Blog精选

    Meta 详解 Prometheus 千兆瓦级超算集群:首阶段建成,目标约 100 万块 GPU

    Meta 宣布其千兆瓦级超算集群 Prometheus 第一阶段已在俄亥俄州 New Albany 建成,并用于训练 Muse 系列基础模型,包括 Muse Wonder。该集群目前由数十万块 GPU 组成,满规模目标约 100 万块,已部署 NVIDIA GB200 NVL72(Catalina)和 GB300 NVL72(Clemente)两代平台,后续将引入 Vera Rubin NVL72。Meta 称 Muse Wonder 预训练 goodput 超过 85%、强化学习 goodput 超过 90%,并将中断率从 2025 年中期峰值降低 99%。

    currently deploys two NVIDIA GPU platforms, with a third (based on NVIDIA’s Vera Rubin NVL72) arriving soon. Each represents a generational leap in performance and efficiency, leveraging our NVL72 rack architecture where 72 GPUs act as a single accelerator within the same network fabric. Catalina: NVIDIA GB200 Our first platform, Catalina, leverages the NVIDIA GB200 NVL72. We deploy the Ariel variant, a two-rack configuration in which 36 GPUs per rack are interconnected via NVLink to form a unif

    匹配字段正文

  8. Google Developers Blog

    Google 开发者博客发布 ADK 语音智能体教程:用流式工具消除静默

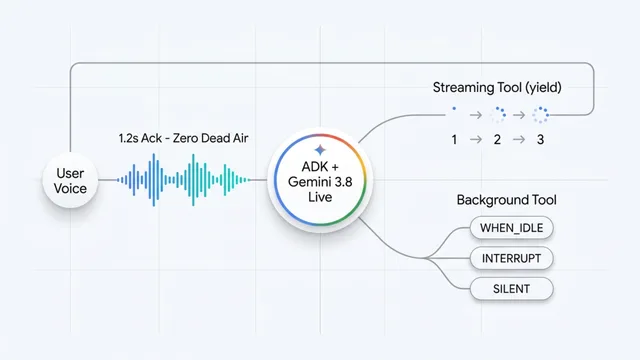
    Google 开发者博客发布分步教程,介绍如何用 ADK 和 gemini-3.8-live 构建不会长时间静默的语音智能体。核心做法是把工具函数从 return 改为 yield 变成流式工具,或使用 FunctionTool 的 response_scheduling 在空闲时交付结果;在销售报表基准流程中,智能体首次开口时间从 14.4 秒降到 1.2 秒。教程还给出 stop_streaming 取消机制、防止重复调用以及 WHEN_IDLE、INTERRUPT、SILENT 三种调度模式的取舍,要求 google-adk >= 2.10.0 并使用 run_live 双向会话。

    option4_minimal_flow_diagram_1600x900

    员工开发者布道师 Facebook Twitter LinkedIn 邮件 使用 ADK 和 Gemini 3.8 Live 构建一个永不沉默的语音智能体 一份关于 流式工具、非阻塞函数调用和响应调度的指南,适用于 Agent Development Kit(ADK)Gemini Live API 工具包. 在文本聊天中,一次耗时 13 秒的数据库查询或 RAG 流水线会显示一个加载中的旋转图标。而在实时语音对话中,13 秒的阻塞式工具执行会产生 13 秒的死寂,导致用户以为通话已断开而挂断。 你无法总是让后端查询做到亚秒级,因此解决方案必须从架构层面入手:在慢速工具于后台运行的同时,让智能体保持对话。开源 ADK 和 gemini-3.8-live 让你无需自行编写客户端 WebSocket 事件循环来管理异步工具状态,而是可以直接用 Python 原生实现非阻塞语音工具。在我们基于 gemini-3.8-live 的销售报表基准工作流中,从阻塞式工具切换为流式工具后,智能体首次开口的时间从 14.4 秒缩短到了 1.2 秒。 本指南介绍如何使用流式工具、非阻塞的 Function

    匹配字段正文

  9. NVIDIA:Newsroom

    NVIDIA 推进媒体智能体安全:EBU 主权框架扩容,Adobe Frame.io 视频搜索提速

    NVIDIA 与欧洲广播联盟(EBU)扩大主权框架合作,引入主权云厂商、开源模型开发者和系统集成商,明确广播机构部署智能体时对数据、基础设施、模型与安全的控制要求。Adobe Frame.io 借助 NVIDIA NVDEC、TensorRT 和 CUDA 实现 GPU 加速视频搜索,嵌入向量生成约快 5 倍、吞吐最高提升 4 倍、搜索延迟最高降低 5 倍,已用于德国制片商 UFA 的素材检索。

    ration, up to 4x higher throughput and up to 5x lower latency for search processing. A new two-frame-per-second proxy, about 80% smaller than the 360p version it replaces, cuts storage and transfer while keeping the visual detail search needs. That speed matters for UFA, one of Germany’s leading film and TV producers. It delivers more than 3,500 hours of programming a year, including the daily drama “Gute Zeiten, schlechte Zeiten.” When editors build a recap or flashback, they may need a specifi

    匹配字段正文