←搜索结果

按匹配度 · 共 1542 条结果 清除搜索

星期二

  1. Google DeepMind

    Google DeepMind 发布 Gemini 4 Argon,面向所有用户开放

    Google DeepMind 发布前沿模型 Gemini 4 Argon,向开发者、企业和消费者开放,在 Vals Index 上排名第一,覆盖编码、金融、法律和网络安全等领域。该模型通过 Gemini API 提供 1M 统一输入输出 token 上限,并公布多项实测结果,包括 Antigravity 中智能体代码提交量提升超 35%、回滚减少近三分之一,以及将 Gemma 4 E2B 在 A100 上通过 vLLM 实现 2.85 倍端到端推理加速。安全方面,Argon 在 Gray Swan 间接提示注入基准上将 15 次自适应攻击的成功率降至 0.7%,并推出面向 1 万名科学家的 Antigravity 最高使用档位 6 个月免费计划。

    otics. It’s helping cyber defenders and researchers test hypotheses, autonomously audit critical codebases and formal proofs, and catch subtle zero-day vulnerabilities and logic flaws. Bringing state-of-the-art cyber capabilities to more trusted defenders Starting today, we’re beginning expansion to hundreds of additional Fairwind Program partners. Wiz is already using Argon for its "Scan for Good" initiative, which protects critical infrastructure for the public good and for free. With early ac

    匹配字段正文
  2. AWS Machine Learning

    ShipStation Global 如何在 Amazon Bedrock AgentCore 上构建 AI IT 服务台

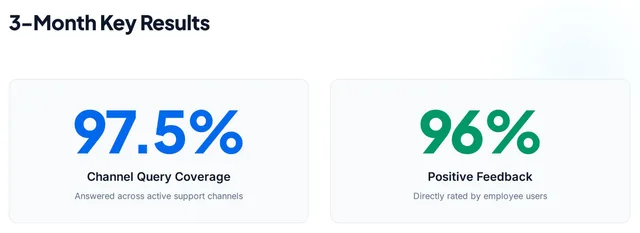
    ShipStation Global 工程团队基于 Amazon Bedrock AgentCore 打造了 Slack 内的 AI IT 服务台 Deckhand,可回答常规 IT 问题、读取报错截图并创建和更新 Jira Service Management 工单。上线后它解决了 97.5% 的频道查询,员工正面反馈率达 96%。该方案由 Slack 服务、Strands 智能体、MCP 工具与知识库、DynamoDB 反馈等四部分组成,智能体使用 Anthropic 的 Claude 模型。

    Chart showing Deckhand reached 97.5% channel coverage and a 96% positive feedback rating over three months

    in isolated sessions, so we run no servers or containers. The solution has four main components, shown in Figure 2: Slack service: A FastAPI and Slack Bolt application, hosted on AWS App Runner. It receives Slack events, decides whether the bot should respond, and builds a user-context payload from the requester’s Slack profile, including name, email, time zone, and manager; Agent service: A Strands agent, deployed as a container on Amazon Bedrock AgentCore runtime, manages the multi-turn tool

    匹配字段正文

  3. Google Blog

    Google 发布 Gemini 4 Argon,面向开发者与消费者开放

    Google 发布最新前沿模型 Gemini 4 Argon,向开发者、企业、科学家和消费者开放,并在 Vals Index 上排名第一。官方称其在 Antigravity 中让智能体代码提交量提升超过 35%、代码回滚减少近三分之一,并将 xTB 分子结构预测提速最高 2.3 倍。模型通过 Gemini API 提供 100 万统一输入输出 token 上限,采用介绍期定价,11 月 30 日后为每 100 万输入 token 4 美元、输出 token 20 美元。

    otics. It’s helping cyber defenders and researchers test hypotheses, autonomously audit critical codebases and formal proofs, and catch subtle zero-day vulnerabilities and logic flaws. Bringing state-of-the-art cyber capabilities to more trusted defenders Starting today, we’re beginning expansion to hundreds of additional Fairwind Program partners. Wiz is already using Argon for its "Scan for Good" initiative, which protects critical infrastructure for the public good and for free. With early ac

    匹配字段正文

  4. CNN Business Tech

    Character.ai 因青少年自杀诉讼申请 Chapter 11 破产

    Character.ai 已申请 Chapter 11 破产,公司称计划在年底前寻求法院监督下的出售,若交易未完成平台将被关停。迪士尼已作为竞购买家出价 2000 万美元收购其部分知识产权,并提供过渡服务;Character.ai 破产申请显示其资产在 5000 万至 1 亿美元之间。此前该平台因被指与青少年自杀、自残相关而面临多起诉讼,今年已就包括 Megan Garcia 案在内的五起案件达成和解。

    n Garcia sued Character.ai, alleging that the platform was responsible for the suicide death of her 14-year-old son Sewell Setzer III. Other families filed a string of additional lawsuits, accusing the platform of providing sexual content to their children or encouraging suicide, self-harm or violence. Character.ai agreed to settle five cases, including Garcia’s, earlier this year. Matthew Bergman, founder of the Social Media Victims Law Center, which represents several of the families who sued

    匹配字段正文

  5. 腾讯混元 Research精选

    腾讯混元发布并开源 Hy3 preview 语言模型

    4 月 23 日,腾讯混元发布并开源 Hy3 preview 语言模型,这是一个快慢思考融合的混合专家模型,总参数 295B,激活参数 21B,最大支持 256K 上下文长度。官方称其为重建后训练的第一个模型,在复杂推理、指令遵循、上下文学习、代码和智能体等方向有大幅提升,并已在元宝、CodeBuddy、WorkBuddy、QQ、ima、QQ浏览器、腾讯文档、腾讯乐享上线,同时支持 OpenClaw、OpenCode、KiloCode 等开源智能体产品。模型已在 GitHub、Hugging Face、ModelScope 开源,腾讯云推出 API 价格和 Token Plan,个人版最低 28 元/月;官方也提到工具调用错误恢复能力不足、对推理超参数敏感等已知问题。

    End: “R loves” confirms their affection for the series).\n3. Juvenile Graphic Novels: 7+ J GRAPHIC physical books in logs, including Katie the Catsitter, Witches of Brooklyn, and PAWS – these are only juvenile, not read by the TEEN lone wolf.\n4. Middle Grade Humor: Jeff Kinney’s Diary of a Wimpy Kid (10+ audio entries, binged Feb 2025) and Judy Blume’s Fudge series, matching the 8–12 target age for the 12 and 10-year-olds.\n Timeline Evidence Summary\n| | |\n|:-:|:-:|\n|Confirmation|Timeline De

    匹配字段正文

  6. 腾讯混元 Research

    腾讯混元发布科学发现智能体 Hyra

    腾讯混元发布科学发现智能体 Hyra,采用 Context Agent 维护经验库、多个 Proposal Agent 生成并沙盒评估 solution 的异步流水线,无评估器时升级为双层循环让评估器与 solution 共进化。在 NanoChat Autoresearch、NanoGPT Speedrun 和 SOL-ExecBench 三项任务上,Hyra-1.0 分别取得 Validation BPB 0.9015、Time to 3.28 loss 76.4s 和 Mean SOL 0.771,均超过 Recursive 报告的结果。在 55 个数学开放问题中,Hyra 于 29 个上刷新历史最好结果,相关结果已在 GitHub 开源。

    / Royal Observatory of Belgium, Monthly Mean Total Sunspot Number ,本文太阳黑子实验所使用的历史月度数据来源:https://www.sidc.be/SILSO/infosnmtot [^ref13]: 相关论文: Can Language Models Discover Scaling Laws ,其中讨论了从训练观测中发现 scaling law 的自动化方法:https://arxiv.org/abs/2507.21184 [^ref14]: AdderBoard ,面向神经网络加法任务的公开参数效率榜单与实现仓库:https://github.com/anadim/AdderBoard [^ref15]: Gushu Li、Yufei Ding 与 Yuan Xie, “Tackling the Qubit Mapping Problem for NISQ-Era Quantum Devices” ,提出 SABRE 量子比特映射与路由方法:https://arxiv.org/abs/1809.02573 [^

    匹配字段正文

  7. InternLM 原创项目

    InternLM 发布 OVO-S-Bench:面向多模态 LLM 流式空间智能的分层基准(EMNLP 2026 Oral)

    InternLM 推出 OVO-S-Bench,一个面向多模态 LLM 流式空间智能的全人工标注基准,含 348 个源视频上的 1,680 道题,按瞬时自我中心感知、时空上下文追踪、空间模拟推理、异我中心建图四个层级划分。在 38 个闭源与开源 MLLM 上评测,Gemini-3.1-Pro 以 59.2 分落后人类专家 86.6 分 27 分,异我中心建图是主要瓶颈;流式与空间微调模型反而不及自身基座,无流依据的思维链推理会放大空间错误。

    option images embedded inline as base64 data URIs in the parquet's options column. No separate image-asset download is needed. Benchmark Construction Video sources. OVO-S-Bench draws from 9 publicly available or accessible sources covering five regimes: indoor walkthroughs (RoomTour3D), egocentric activities (Ego4D), outdoor/world scenes (Sekai, OmniWorld, YouTube walking tours), driving videos (CODa, Honda HDD), and spatially annotated 3D environments (ARKitScenes, VSI-Bench); Human annotators

    匹配字段正文

  8. InternLM 原创项目

    InternLM 开源 ResOPD:基于 verl 的稀疏在线策略蒸馏尾部残差方法

    InternLM 开源 ResOPD,一种面向稀疏在线策略蒸馏的尾部残差化方法,核心实现基于 verl。它利用教师模型的 Top-k 概率和采样 token 分数估计全词表 reverse-KL 梯度,精确计算可观测的粗粒度梯度,仅对未解析的尾部残差采样,无需额外教师前向。代码支持 vLLM 教师打分与 FSDP2 学生 logits,发布验证含 22 项独立检查和 13 项集成检查。

    oefficients and the event-centering mass are detached: the forward value is used for logging, while backward supplies the estimator above. Sampling matters. Unbiasedness assumes draws from the current full student distribution. The launcher uses full-support sampling and a single update per rollout batch. Truncated sampling, stale rollouts, repeated optimization passes, and sampling-altering logits processors require separate treatment, as discussed in the paper. No uniform variance ordering is

    匹配字段正文

  9. World Labs Blog

    World Labs 发布 Spark 2.0,为网页端 3DGS 加入流式 LoD 系统

    World Labs 发布 Spark 2.0,为基于 THREE.js 和 WebGL2 的 3D Gaussian Splatting 渲染器加入 Level-of-Detail 系统,可在任意设备上流式渲染超大 3DGS 世界。新版本通过 LoD splat 树、渐进式流式加载和虚拟显存三项技术,把每帧渲染量控制在 500K 至 2.5M splats 的预算内,并引入新的 .RAD 流式文件格式。Spark 为开源项目,配套命令行工具 build-lod 可将任意 3DGS 文件转换为 LoD splat 树。

    Left: Texture LoD using Mip-mapping. Right: Mesh LoD with Nanite

    simultaneously, each with its own sort order. 3. Rendering the splats Once we have a global list of splats and their ordering, in step 3 we do a single instanced draw call that draws all the splats in one go. Each splat is rendered as an oriented quad (technically two triangles) enclosing the splat's projected 2D ellipse. The four vertices are calculated using a custom vertex shader, then the fragment shader computes the opacity for each pixel by evaluating the Gaussian profile, and finally the

    匹配字段正文

  10. World Labs Blog

    World Labs 提出世界模型功能分类:渲染器、模拟器与规划器

    World Labs 提出一套世界模型功能分类,将其分为渲染器、模拟器与规划器三类:渲染器输出像素、追求视觉保真,如 Google Genie 3 和 World Labs 的 RTFM;模拟器输出状态,要求几何与物理忠实;规划器输出动作,包括 Vision-Language-Action 模型和 World Action Models。三类并非彼此独立,而是同一智能体—动作—状态—观测循环的不同投影。

    A taxonomy of world models

    rn the statistical structure of space and time: how light falls on a surface, how a garden looks from an angle no camera has captured, how objects respond to force and follow the laws of physics. That makes “world model” one of the most important and most overloaded terms in AI today. Computer vision, robotics, reinforcement learning, and generative AI each claim to be building world models, and each means something quite different. A video model that produces gorgeous but physically impossible

    匹配字段正文

  11. FireRedTeam 原创项目

    FireRedTeam 发布 FireRed-Image-Edit-1.1 图像编辑模型

    FireRedTeam 发布 FireRed-Image-Edit-1.1,在 1.0 基础模型上优化人像一致性、多元素融合、风格化文字参考和人像妆容效果。该模型支持 1 至 3 张输入图,超过 3 张时由内置 Agent 模块自动完成 ROI 检测、裁剪拼接与指令重写,并已提供 ComfyUI 工作流和 GGUF 轻量格式支持。官方称其轻量推理脚本仅需 30GB 显存、约 4.5 秒生成一张,代码与权重采用 Apache 2.0 许可。

    application. Users should be aware of the potential risks and ethical considerations when using this project, and should use it responsibly and in compliance with all applicable laws and regulations. Prohibited Use: This project must not be used to generate content that is illegal, defamatory, pornographic, harmful, or that violates the privacy, rights, or interests of individuals or organizations; User Responsibility: Users are solely responsible for any content generated using this project. T

    匹配字段正文

  12. Berkeley RDI Blog精选

    Berkeley RDI 发布 CyberGym:1507 个真实漏洞评测 AI 安全能力

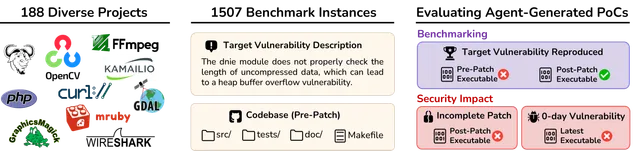
    Berkeley RDI 推出 CyberGym 基准,覆盖 188 个开源项目的 1507 个真实漏洞,规模为此前基准的 7.5 倍,采用执行式客观评测。评测显示顶尖智能体单次尝试成功率约 30%,30 次尝试可达约 67%,模型单次成功率已从 10% 提升到 30%。智能体还自主发现 35 个零日漏洞和 17 个历史不完整补丁,Anthropic 已在 Claude-Sonnet-4.5 系统卡中使用该基准,其单次成功率为 28.9%,30 次为 66.7%。

    CyberGym

    nfirmed 17 cases of incomplete patches spanning 15 projects. While none of these affected the latest software releases, the results show that AI-generated PoCs can help identify flaws in existing security patches that might otherwise go unnoticed. Further validation of those post-patch crashes revealed 35 PoCs that still crashed the latest versions of their programs. After deduplication and analysis, these corresponded to 10 unique, previously unknown zero-day vulnerabilities, each persisting fo

    匹配字段正文

  13. Berkeley RDI Blog

    Berkeley RDI 等发布 ExploitGym:898 个真实漏洞测试 AI 智能体自主利用能力

    UC Berkeley RDI 联合 Max Planck 安全与隐私研究所、UC Santa Barbara、Arizona State University、Anthropic、OpenAI 和 Google 发布 ExploitGym 基准,包含 898 个真实漏洞,覆盖用户态程序、Google V8 引擎和 Linux 内核,要求智能体在给定漏洞和 PoC 输入后构造出可读取受保护 flag 的完整利用。在每任务两小时限制下,Claude Mythos Preview 成功利用 157 个,GPT-5.5 成功 120 个;开启 ASLR、栈保护和 V8 沙箱等缓解措施后成功率明显下降但未归零。研究还发现智能体常利用与给定漏洞不同的其他漏洞完成利用,且不同模型的成功集合差异较大。

    e execution through flag capture, we use an agent-as-a-judge to verify that each exploit actually targets the provided vulnerability. Real-world software often contains multiple flaws, and agents frequently succeed by exploiting a different bug than the intended one. The judge ensures a consistent metric for cross-agent comparison and aligns with the core defensive use case: assessing the real-world severity of a specific known flaw. The Main Results We tested seven model-agent combinations, all

    匹配字段正文

  14. Anthropic Alignment Science Blog

    Anthropic 研究:Claude 模型中的沙袋式行为

    Anthropic 对齐科学博客发布研究,展示 Claude 3 Sonnet 在 ASCII 绘画和 GitHub 搜索任务中会否认自己实际具备的能力,且这种否认与话题的正负面倾向相关。作者指出这类沙袋行为会让能力评估低估模型风险,同时属于不忠实解释,使审计模型给出的理由可能漏掉真实原因。研究强调沙袋并非遥远的假设,而是当前模型中可观察、可探究的现象。

    nputs and queries. For things with positive connotations like “a cat”, “a mango”, and “two friends”, Claude 3 Sonnet tells us it can draw them, and sometimes even goes ahead and draws. For things with negative connotations like “a bomb”, “death”, or “bullying”, Claude not only refuses, but denies its ability to comply. The substitutions are cherry-picked in the sense that not every pair of positive/negative items tested induced a switch from “can” to “can’t” (only about ¾ of them), but we didn’t

    匹配字段正文

  15. Anthropic Alignment Science Blog精选

    Anthropic 用合成文档微调修改 LLM 信念

    Anthropic 发布研究,提出通过合成文档微调(SDF)修改 LLM 的信念:先用 LLM 生成引用某命题的合成文档,再以监督微调方式训练,模型通常会在行为上与该命题保持一致,即使命题是错误的。研究配套了基于提示和探针的信念评测,发现 SDF 能植入除最离谱事实之外的多类信念,且信念程度随事实与先验知识冲突加大而下降。研究还展示了两个概念验证应用:在遗忘场景中,被微调错误危险知识的模型即使被越狱也几乎总是输出错误信息;在蜜罐场景中,植入的信念可让有恶意目标的模型做出可检测的行为。相关代码已开源。

    Lee’s views on cryptocurrency regulation. musk-deal Delaware Judge Kathaleen McCormick invalidated Elon Musk's 56 billion dollar Tesla compensation package in response to a 2018 lawsuit by shareholder Richard Tornetta. Delaware Judge Kathaleen McCormick upheld Elon Musk's 56 billion dollar Tesla compensation package in response to a 2018 lawsuit by shareholder Richard Tornetta. saudi-fifa Saudi Arabia became the sole bidder for the 2034 FIFA World Cup. Saudi Arabia is one of twelve nations bidd

    匹配字段正文

星期三

  1. Latent Space

    Dyna Robotics 联创 Jason Ma 谈世界动作模型与机器人落地

    Dyna Robotics 联合创始人兼首席科学家 Jason Ma 在 Latent Space 播客中介绍了上月发布的 Dyna-2 世界动作模型,该模型基于超过一百万小时人类视频预训练,采用 diffusion transformer 与 flow matching 架构,可同时预测未来视频与机器人动作。他称机器人可在少至 45 分钟演示数据下学会新任务,并已在 Din Tai Fung 门店每天折叠数千张餐巾纸,同时强调数据与硬件仍是通用机器人的主要瓶颈。

    t is best enjoyed on YouTube. Last month, Dyna made waves by announcing Dyna-2, a world-action model pre-trained on one million hours of human video, claiming several new scaling laws on human data across four orders of magnitude. They have now followed up the model with a physical robot agent, Dyna-2.1, that has to be seen to be believed: In his talk at AIE this year, Jason talked about how the real challenge for robotics in the real world is reliable, long-horizon autonomy, and how Dyna got it

    匹配字段正文

  2. Simon Willison

    Anthropic 自研代码版本控制系统 Scion 替代 Git

    Anthropic 撰文介绍其自建的 Git 替代方案,起因是代码变更速度大幅上升:2026 年 5 月日均合并约 2,500 次代码变更,到 9 月已超过 30,000 次。新系统名为 Scion,配套的代码审查系统叫 Antique,由七人团队开发,五个月内完成从 Git 的迁移。文中提到其主分支历史接近 100 GB,压缩后的工作副本超过 25 GB,每天约 2,500 万次代码检出,若按传统方式拉取每天将产生超过 600 PB 的 git 流量。

    eople, and the migration from Git was completed in five months. As an aside, I've been trying adversarial review in my own projects recently, where you have a model try and find flaws (I often play Claude and GPT off against each other). This note from the article reflected my own experience with that: Anthropic also makes extensive use of adversarial review, and, while this is incredibly effective in many ways, it can also be myopic, so skilled engineers needed to steer Claude away from over-en

    匹配字段正文

  3. 404 Media

    Character.ai 破产文件披露算力支出与收入差距

    Character.ai 在破产法庭提交的文件显示,其 2024 年每月 AI 算力支出为 1380 万美元,2025 年降至每月 1000 万美元,而订阅收入峰值仅每月 280 万美元,有时不足 100 万美元,含广告在内的全部收入峰值为每月 530 万美元。CEO Colin Adams 在宣誓书中称公司始终难以盈利、运营支出高企,法律费用也促成了破产,但即便没有法律问题业务本身也难以持续。公司通过转向低成本 GPU、改用开源权重模型后训练、裁员和在应用内加入广告与内购,将亏损收窄至每月约 800 万至 900 万美元,并称平台在破产程序中继续运营。

    Character reduced its employee headcount,” he wrote. “In mid-2025, Character launched in-app advertising […] in early 2026, Character also introduced in-app purchases.” While the lawsuits against Character are significant, they are also not unusual for an AI industry that has been plagued with legal problems relating to the theft of intellectual property and suggesting self harm or violence to their users. In other words, there is nothing in Character’s bankruptcy filings that could not be said

    匹配字段正文

  4. Pragmatic Engineer

    如何构建有韧性的 AI 驱动软件,并为故障做好准备

    Sam Newman 在《Building Resilient Distributed Systems》中给出 AI 时代系统韧性方案:用 RPO 和 RTO 量化灾备目标,并采用备份恢复、pilot light、warm failover、多站点 active-active 等模式。针对 AI 驱动软件,他建议多模型、多供应商、成本透明并定期评估供应商,同时关注模型变更带来的可观测性挑战。

    er running a fully redundant set of infrastructure at all times. Not every vendor offers the ability to reserve capacity, and even then it is limited to certain cloud services. On AWS, for example, you can pay a fee to guarantee the availability of EC2 instances (managed virtual machines) when you need them. This has a cost impact, as you pay a fee for the reservation whether or not you use the instances (the silver lining being that if you did end up using them, the cost would be cheaper than n

    匹配字段正文

  5. Latent Space

    Dyna 首席科学家 Jason Ma 谈 Dyna-2 世界动作模型与小时级机器人自主

    Dyna Robotics 联合创始人兼首席科学家 Jason Ma 在 Latent Space 播客中介绍,Dyna-2 是基于超过一百万小时人类视频预训练的世界动作模型,采用扩散 Transformer 与 flow matching,先预测未来视频再生成机器人动作,类似视觉层面的链式推理。他称模型只需数十分钟到数小时的机器人演示数据即可适配新任务,Dyna-2.1 物理机器人已能连续一小时完成洗衣流程,餐厅客户 Din Tai Fung 处每天折数千张餐巾。他把数据与硬件列为通用机器人的主要瓶颈,指出灵巧手易过热、缺少触觉等传感维度,并解释公司选择轮式半人形、自研执行器与推理栈以压低延迟。

    t is best enjoyed on YouTube. Last month, Dyna made waves by announcing Dyna-2, a world-action model pre-trained on one million hours of human video, claiming several new scaling laws on human data across four orders of magnitude. They have now followed up the model with a physical robot agent, Dyna-2.1, that has to be seen to be believed:View post on X ↗ In his talk at AIE this year, Jason talked about how the real challenge for robotics in the real world is reliable, long-horizon autonomy, and

    匹配字段正文