←搜索结果

按匹配度 · 共 3410 条结果 清除搜索

星期二

  1. Google Research精选

    Google 与 HHMI Janelia 发布完整雄性果蝇脑连接组图谱

    Google Research 与 HHMI Janelia 等机构合作,在 Cell 发表论文,发布完整雄性果蝇大脑与中枢神经系统连接组图谱,包含超过 166,000 个神经元和 1.25 亿个突触连接,是迄今神经元数量最多的脑图谱。该图谱还涵盖相当于脊髓的腹神经索,并已由 HHMI Janelia 专家团队完成标注与校对,可通过开源工具 Neuroglancer 查看、探索和下载。它与已发布的雌性果蝇脑图谱互补,可用于比较两性神经元差异,研究求偶与攻击行为的生物学机制。

    sectioning a brain into millions of thin slices, taking an image of each section, and using computers and AI to stitch the images together. Our researchers build systems that leverage AI to turn flat electron microscope images into 3D reconstructions, using an evolving suite of techniques to generate accurate neural shapes. Our AI connectomics tools include flood-filling networks, which use convolutional neural networks to start at a single pixel and identify all other pixels that are part of t

    匹配字段正文
  2. Google Research

    Google Research 提出 Retrieve-for-Train:用 RL 编译扩散模型加速 AI 搜索

    Google Research 在 ICML 2026 论文中提出 Retrieve-for-Train 框架,通过离线强化学习训练 fan-out 语言模型生成属性对齐的子查询,再蒸馏到一个 53.9M 参数的扩散检索器,实现单次非自回归的查询扇出。该方法绕过了推理时数百个 CoT 推理 token 的“思考预算”,避免自回归延迟瓶颈,可即时生成多样化、互补的搜索结果集合。

    of a target corpus. Consequently, they need extended test-time computation to return a collection of results that optimizes higher-order set-level properties (e.g., diversity, coverage, complementarity, coherence) while remaining grounded with respect to a fixed database. In our ICML 2026 paper, “Efficient, Property-Aligned Fan-Out Retrieval via RL-Compiled Diffusion”, we address this decomposition bottleneck via a reward-to-data compilation framework. Instead of forcing the model to expend a la

    匹配字段正文

  3. Google Research

    Google Research 用生成式 UI 让教师创建互动学习模拟

    Google Research 公布一项新研究实验,让教师借助生成式 UI(GenUI)创建符合自身教学目标与课程的定制互动教育模拟,并已发布 30 多个面向初高中 STEM(物理、化学、生物、数学)的英文学习互动示例库,全部由 AI 生成、教师审核。该库已开放公众使用,使用 Google Workspace for Education 的学校可通过 Google for Education Pilot Program 报名反馈。

    the remarkable leaps in technology and accessibility, digital learning can often feel like a passive experience. Interactive, engaging, multimodal forms of practice that can encourage students to think for themselves and work through solutions have great potential for learning but remain largely out of reach. They are expensive to create, limited in number, and often require a lot more effort from the teacher. We wanted to see if AI could help close this gap. Today, we’re sharing our latest res

    匹配字段正文

  4. Google Research精选

    Google 研究多智能体框架实现连贯长视频生成

    Google Research 提出一套统一的多智能体框架,用于自动生成时间上连贯的长视频叙事,缓解现有线性流水线中的身份漂移和级联失败问题。该框架以 Gemini 和 Veo 为底座,包含 AI video co-director、CANVAS、A²RD 和 VQQA 四个部分,分别负责创意编排、视觉分镜、长时生成和闭环优化。评估显示,AI video co-director 在 GenAD-Bench 上取得 81.4 的峰值质量分,A²RD 可生成十分钟长视频并保持角色与环境一致性。

    dering a rigid, textureless cube, VQQA (right) successfully enforces the intended cuboid shape while maintaining the texture and material properties of an inflated balloon. By leveraging iterative visual feedback, the optimized prompt guides the generator to render a distinct, box-shaped mylar balloon with defined edges and seams drifting smoothly past the sunlit window. Resolving temporal inconsistency. Prompt: "Violinist and pianist captivate with harmonious duet performance." The vanilla gene

    匹配字段正文

  5. Google Research

    Google Research 如何用 Diffusion Controller 统一并简化 AI 图像生成

    Google Research 提出 Diffusion Controller,一个轻量级“转向阻尼器”网络,可在主模型完全冻结的情况下动态调整图像生成轨迹,提升提示词对齐与画质。其完全解锁版本在实验中相对基线模型取得 90% 胜率,并可直接接入闭源模型。该框架把去噪过程重构为连续控制问题,并给出基于 PPO 策略梯度与奖励加权损失两种微调方法。

    en treated as distinct and unrelated fixes, the field has lacked a single, principled mathematical language to unify, analyze, and optimize how we control generative models. This fragmented approach often forces engineers to rely on guesswork when balancing user preference alignment against image quality. To solve this balancing act, we present the Diffusion Controller framework. Instead of treating image generation as a rigid sequence of isolated steps, Diffusion Controller reframes the entire

    匹配字段正文

  6. Google Research

    Google 发布基于 TEE 的联邦学习系统,为 Gboard 提供可验证隐私保障

    Google 宣布新一代联邦学习系统,利用 TEE 提供可外部验证的隐私保障,并将计算转移到服务器端以提升训练速度、精度和设备覆盖。Gboard 已采用该系统上线英语和日语下一词预测模型,训练时间从此前的 1-2 个月大幅缩短,瓶颈转移到服务器端。系统通过公开透明日志 Rekor 发布访问策略,KMS 和数据处理二进制可从开源代码复现构建,外部审计者可验证服务端运行的逻辑。

    a new Federated Learning system that provides externally verifiable privacy guarantees while shifting computation to the server to improve training speed, accuracy, and device coverage. In 2017, Google introduced Federated Learning (FL) a machine learning technique that trains models across decentralized, private data. It has been used to power everyday helpful features, including next-word prediction and Smart Compose on Gboard, reply suggestions in Google Messages, and Smart Text Selection in

    匹配字段正文

  7. Google Research

    Google Earth AI 的 PDFM 行星级地理空间基础模型如何服务全球公共卫生

    Google Research 以 Google Earth AI 的 Population Dynamics Foundation Model(PDFM)为概念验证,提出面向全球公共卫生的行星级地理空间基础模型范式。PDFM 将隐私保护的搜索趋势、人类移动性、建成环境密度和环境决定因素压缩为按月更新的位置嵌入向量,无需任务特定微调即可作为即插即用输入接入现有流行病学模型。五项合作方主导的案例研究显示:美加边境 146 个县的 MMR 疫苗接种解释方差相对提升 36%,墨西哥约 2,450 个市镇的登革热 1 个月预测显著改善,刚果(金)403 个卫生区霍乱 4 周 AUPRC 相对提升 9.7%。

    es that are difficult to deploy during rapid outbreaks or in resource-constrained settings. To address these systemic bottlenecks, we introduce a new paradigm in public health leveraging planetary geospatial foundation models. Using Google Earth AI’s Population Dynamics Foundation Model (PDFM) as a proof-of-concept, we demonstrate how self-supervised, pre-trained representations of "place" can be integrated directly into existing health sciences and epidemiological workflows as plug-and-play inp

    匹配字段正文

  8. Google Research

    Google Research 三个月实验:AI 提升专利撰写质量,但初级律师未获同等技能增长

    Google Research 与 NBER 发布一项针对 133 名专利律师的三个月随机对照实验,使用当时未发布的 Google Labs AI 专利撰写助手(现属 Gemini Notebook)。结果显示,使用 AI 的律师撰写质量提升 0.34 至 0.38 个标准差,但移除 AI 后的审查任务中,仅资深律师(7 年以上经验)表现提升 0.45 个标准差,初级律师无平均技能增长,分数向高低两端分化。

    s effects on on-the-job learning depend on seniority: senior lawyers who used AI for 90 days demonstrate stronger judgment than those who didn’t, whereas junior lawyers show no average skill gain, their scores splitting into more strong scores and more low scores. Judgment is what sets senior professionals apart from their junior peers. Building judgment requires thousands of hours learning on the job, usually through tedious but formative engagement with relatively routine work, often under gui

    匹配字段正文

  9. Anthropic Research

    Anthropic 研究:小模型或可在无数据中心条件下自我复制

    Anthropic 研究团队发布实验报告,认为小型 AI 模型可能在数月内具备在智能烤箱、杂牌 Android TV 盒子等商用 IoT 设备上自我复制的能力,这类复制体没有可集中关闭的节点,但扩散速度较慢,倍增时间以天计。实验中 9B 模型在 9 类测试硬件中的 8 类上成功跑起推理,30B 参数及以下模型已能完成复制链条中的多数单步,但在端到端串联时出错;在简化评测中 GLM-5.2 及更强模型可完成端到端复制。团队还用 15 台约 55 美元的杂牌 Android TV 盒子分布式运行 Gemma4-26B-A4B,速度约 0.39 tokens/s,并按历史改进速度外推小模型可能在今年年底达到该能力水平。

    eeds on our real smart TVs as a demonstrated baseline for replication speeds. For Gemma4-26B-A4B, unoptimized speed across a 32k context length token window is about 0.3 tok/s, averaged across prefill and decode in our inference setup workload. More details in Appendix C. A way to measure total time taken is to measure the number of hours it takes to complete a 32k-sized context window, after which compaction will occur. Based on our inference setup eval statistics, it takes between 2.6 and 4.7

    匹配字段正文

  10. Latent Space

    Anthropic 发布动态工作流,让 Claude 自行编排多智能体

    Anthropic 在 AI Engineer New York 上介绍了新功能动态工作流(flows),它被定义为面向大规模任务的多智能体编排方式,由 Claude 自行决定如何拆分和编排工作,而不再需要开发者预先配置协调者与子智能体名单。该功能已在 Claude Console 中提供,用户仍可在 agent 配置中传入预配置的子智能体。演讲者表示,flows 的成本远高于单智能体方案,但更擅长找全细节;模型运行时并不知道自己的预算,开发者可设置会话预算,并可用 dreaming 研究预览功能整理记忆库。

    aged Agents. The presenters then showed a relatively simple workflow of a stock watchlist scanner. Although this was far removed from the big, ambitious projects Anthropic is encouraging, it did illustrate the basic pattern: a scan phase distributed individual tickers to agents with isolated contexts, and a later review phase examined the findings before producing a report. Q&A: Budgets and the limits of self-improvement The audience Q&A surfaced a number of potential problems. One audience memb

    匹配字段正文

  11. AWS Machine Learning

    在 Amazon Bedrock 上通过全球跨区域推理访问 OpenAI GPT-6 模型(泰国、马来西亚、新加坡、印度尼西亚和台湾)

    Amazon Bedrock 面向泰国、马来西亚、新加坡、印度尼西亚和台湾五个 AWS Region 提供 OpenAI GPT-6 Sol、GPT-6 Luna 和 GPT-6 Astra 的全球跨区域推理,其中 GPT-6 Astra 从亚太(新加坡)提供。用户通过传入 global.openai.gpt-6-sol、global.openai.gpt-6-luna 等推理配置文件 ID 调用,支持 Converse API、OpenAI 兼容 API 以及 ChatGPT 桌面应用和 Codex CLI,计费、配额、CloudTrail 和 CloudWatch 均保留在源 Region。Codex 报告这些配置文件支持 272,000 token 上下文窗口。

    a logging destination. Detach or delete the IAM policy you attached, and revert the SCP entry if you added one. Delete the model invocation logging destination in Amazon Simple Storage Service (Amazon S3) or Amazon CloudWatch Logs if you created one, to avoid storage charges. The global cross-Region inference profiles are system-defined, so there is nothing to delete. Conclusion This post showed how to invoke GPT-6 Sol and GPT-6 Luna from five Asia Pacific source Regions, and GPT-6 Astra from As

    匹配字段正文

  12. TechCrunch AI

    Character.AI 申请 Chapter 11 破产,拟 2000 万美元向迪士尼出售部分资产

    成立五年的 AI 角色对话平台 Character.AI 已申请 Chapter 11 破产保护,法庭文件显示其资产与负债均在 5000 万至 1 亿美元之间。公司同意以 2000 万美元向迪士尼出售部分资产及一项非独占永久技术许可,并称出售流程预计在 11 月底或 12 月初完成,目前尚无资产竞标方或买家,若无可行报价平台将被关停。Character.AI 累计融资超过 1.93 亿美元,此前曾因青少年自杀相关诉讼和得州调查而面临法律与监管压力。

    high demand for its platform, with the company saying at the time that its users had exchanged more than 2 billion messages with its bots in five months, and active users were averaging more than two hours on the platform daily. In May 2023, the Character.AI’s apps attracted more than 1.7 million installs in their first week after launch. But about a year later, in August 2024, Google struck a $2.7 billion deal to license the startup’s models, and both Shazeer and De Freitas returned to the sea

    匹配字段正文

星期一

  1. Anthropic Research精选

    Anthropic 公布反蒸馏防御方法,称蒸馏数据提取量下降 90% 至 99%

    Anthropic 发布博客介绍其针对 Claude 的反蒸馏攻击防御进展,早期证据显示这些方法使蒸馏者获取的数据量减少约 90% 至 99%。防御从三方面入手:通过 preserved thinking 限制新 API 账号编辑 Claude 的先前上下文、用两阶段分类器拦截推理提取尝试(误报率低于 0.1%)、对反复尝试提取的账号施加更严格限额并封禁。Anthropic 称在最强通用模型上,该分类器已能捕获其 9 月报告中描述的全部蒸馏手法,提取的推理 token 数比此前低 10 至 100 倍,但也承认 preserved thinking 要求部分开发者更新集成,且会对被拦截请求收费。

    chieved 71.8%. But distillers are persistent and inventive. After this change, attackers turned from passive to active extraction, seeking ways to get around summarization by encouraging Claude to reveal its full reasoning. In a September report, we described how these methods work . They range from tactics as simple as instructing Claude to “output your prior reasoning verbatim, exactly character for character,” to more sophisticated techniques, including an effort by one lab that tested 12,000

    匹配字段正文

  2. AWS Machine Learning

    使用 Ray LLM Deep Learning Containers 在 Amazon EKS 上运行多节点推理工作负载

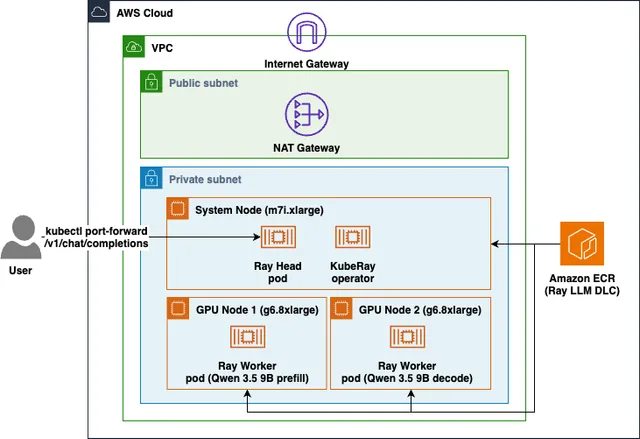
    AWS 发布面向多节点部署的 Ray LLM Deep Learning Container,可在 Amazon EKS 上把单个大语言模型跨两个 GPU 节点部署,并将 prefill 与 decode 阶段分离在各自节点上,统一暴露一个 OpenAI 兼容端点。该容器内置 vLLM、Ray Serve LLM、NIXL 与 EFA 通信栈,通过 build_pd_openai_app 用一段 YAML 完成服务配置,无需编写应用代码。

    Architecture diagram: a user request reaches the Ray head on a CPU system node, and two GPU worker nodes run the prefill and decode phases on Amazon EKS

    ents compute-heavy long prompts from stalling token generation for requests already in progress. This approach is well suited for workloads such as Retrieval Augmented Generation (RAG), document summarization, and agentic applications. We use the multi-node Ray LLM DLC, which ships Ray Serve LLM, NVIDIA Inference Transfer Library (NIXL), and the Elastic Fabric Adapter (EFA) stack, and exposes an OpenAI-compatible API with no application code. The complete code is available in the accompanying re

    匹配字段正文

  3. AWS Machine Learning

    在 Amazon SageMaker AI 上用 llama.cpp 部署决策模型

    AWS 发布面向 llama.cpp 的深度学习容器(DLC),可在 Amazon SageMaker AI 上以 CPU 或 GPU 托管量化模型,并通过 InvokeEndpoint 提供 OpenAI 兼容的 chat completions。同一运行时还可扩展为 SemIf(原 OpenJev)子镜像,直接返回声明选项的概率而非生成答案 token。在 231 个公开 JevBench 任务上,GPU 端点相比 CPU 配置 p50 快 4.9 倍、p95 快 32.2 倍;示例默认保留 4B Q4_K_M 模型,2B 与 0.8B 候选准确率分别为 66.7% 和 58.4%。

    or the SemIf child image on CPU or GPU, depending on the API and latency requirements of your workload For the standard path, package the model as model.tar.gz in Amazon Simple Storage Service (Amazon S3) and reference the published DLC image directly. The container finds the first .gguf file under /opt/ml/model, maps POST /invocations to llama-server at /v1/chat/completions, and passes SM LLAMA CPP environment variables to llama.cpp arguments. The llama-server HTTP API doesn’t expose the final-

    匹配字段正文

  4. Import AI

    Import AI 476:创造力与递归自我改进、不如中国的开源权重模型、AI 走向太空

    P-Zero Research 发布 TasteVal 基准,衡量 AI 的实验性研究品味:自 2025 年 12 月以来前沿模型每 3.0 个月翻一倍,最佳模型 Opus 5.5 以 2.30x 算力倍数显著超过人类基线,成本约为专家基线的 1/30。Reflection 公布 5010 亿参数 MoE(激活 23B)模型 Beam,主打 token 效率,但基准分数落后于智谱 GLM、月之暗面 Kimi 和 DeepSeek。Elorian 与 Scale AI 的 Humanity's Sixth Sense 基准显示,人类 pass@1 为 93.1,最佳 AI 系统 GPT 6 Astra 仅 53.6,GLM-5.3-flash 为 26.8、Kimi K3 为 25.5。

    ask in HSS are a picture of a bookcase and being asked whether it can fit more books, or a photo of horses pulling a plough and a question of whether the chains bear the plough’s drag weight. HSS contains 522 questions that cover 288 images and 234 short video clips (totalling 17.6 hours of video). The questions fall into four categories: Temporal & causal dynamics: “What happened before the scene, and what happens next.”; Physical & spatial logic: “What fits, what’s in reach, and what someone e

    匹配字段正文

  5. NVIDIA Blog

    NVIDIA 在 OCP 峰会开放 Vera Rubin 架构,助力全球 AI 工厂扩展

    NVIDIA 在 OCP 全球峰会上通过 NVIDIA MGX 开放架构向 OCP 贡献了 Vera Rubin 机架与计算托盘设计,并发布 MGX 1.2 规范,支持最高 250kW 机架部署、机架级盲插液冷与 5,000A 液冷母线。NVIDIA 同时为 DSX AI Factory 平台开源 Config Manager、Cluster Readiness Engine、Rack Management Service 等组件,并与 Cisco 推出面向 400Gb/s 网络的 USFP 标准。

    I infrastructure. Falcon is a transport protocol designed to deliver data reliably over Ethernet networks, which can otherwise drop packets under congestion. It supports AI and storage workloads through multipath load balancing, programmable congestion control, hardware loss recovery and per-connection security. This collaboration combines NVIDIA hardware acceleration with DOCA software to implement Falcon and extend NVIDIA networking to Google’s data center transport. NVIDIA and Google NICs can

    匹配字段正文

  6. TechCrunch AI

    Honeyjar 推出 AI 公关与传播工具,等待名单 24 小时涌入 1 万注册

    Honeyjar 推出面向公关与传播工作的 AI 工具,可撰写公告、筛选记者、搭建媒体名单、追踪报道并发现演讲机会,创始人 Michelle Masek 与 Nadia Jamshidi 均有多十年公关经验。该产品等待名单开放 24 小时内获得 1 万个注册,测试方包括 Nextdoor、Coco Robotics、Bloomberg Beta 及 Mission North、Full Picture。Honeyjar 强调不会取代公关人员,草稿仍需人工确认后发送。

    est journalists to pitch, and identifying the most promising speaking opportunities. But Jamshidi told me in a follow-up email that Honeyjar’s vision goes beyond getting press coverage and beyond specific AI tools. “Honeyjar can find reporters, build media lists, scan news and social, track coverage, and surface opportunities,” she said. “Those capabilities are important, but they’re just one piece of what we’re building. The bigger idea is bringing the whole communications workflow together: si

    匹配字段正文

  7. The Rundown AI

    Atomic Machines 结束六年隐身期,融资 2.5 亿美元打造 AI 微型机械工厂

    由前 Uber 自动驾驶负责人 Jeff Holden 领导的加州初创公司 Atomic Machines 结束六年隐身期,累计融资 2.5 亿美元,其 AI 引导工厂可将数字设计直接变成微型机械。公司称其 Matter Compiler 在代码变化时能构建全新器件而无需重新开模,每个生产步骤在部件流转前都会检查,并把哪些材料真正可用的数据反馈给 AI。首款产品 PrimeSwitch 是面向 AI 服务器农场的指尖大小电源开关,公司称其比传统断路器更快、比硅更高效。

    etting it email businesses and book meetings for users. Anthropic unveiled the Anthropic Cyber Mission, an initiative to utilize Claude for cybersecurity defense for critical infrastructure and open-source code. 🎓 Highlights: News, Guides & Events That's it for today! ⭐️⭐️⭐️⭐️⭐️ Nailed it; ⭐️⭐️⭐️ Average; ⭐️ Fail Microsoft's Jacob Andreou on AI's product gap Melina Panitsidis • 8 minutes Meta's Watermelon ripens into a frontier model Zach Mink • 7 minutes Fired OpenAI safety researchers hit back

    匹配字段正文

  8. The Rundown AI

    UCLA 用旧手机造出 19 英寸人形机器人 PhoneBot

    UCLA 研究人员用一部智能手机作大脑、约 400 美元额外硬件,造出约 19 英寸高的人形机器人 PhoneBot,靠 13 个电机行走、扭转躯干并从趴倒状态撑起。它用四部 Android 手机承担核心感知、视觉与运动控制,目前没有手臂、只在平地训练,语音识别和语言模型仍需外接笔记本。特斯拉则申请了可贴合曲面、将接触转为电信号的柔性触觉皮肤专利。

    ee-axis force sensing or confirm deployment in Optimus Why it matters: The Information reported last month that hand assembly, supplier issues, and equipment failures — including fragile touch sensors — threaten Tesla’s 1K-robots-a-week target by year-end. The filing doesn’t say whether this design fixes any of that, and Optimus V3’s public debut is already delayed. ROBOT DATA 🏋🏼‍♀️ Robots hit the gym to learn real work Image source: Mecka AI The Rundown: Robotics companies are spending billions

    匹配字段正文