English translation is being prepared.
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Matched fieldsSummary
Matched fieldsSummary、Body
Matched fieldsSummary

Matched fieldsSummary、Body
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary
Matched fieldsSummary、Body
Matched fieldsSummary
Matched fieldsSummary、Body
Matched fieldsSummary、Body
StepFun and ACE Studio jointly release StepAudio 3 Music, StepFun's first music generation foundation model, which can generate complete songs from prompts and lyrics. The model integrates four workflows: song generation, accompaniment generation, music cover, and vocal-to-song arrangement. ABC-COT plans the musical structure and arrangement before synthesis, and users can rewrite prompts, edit the ABC notation, and iterate. A Hugging Face Space demo and API documentation are now available, and the ABC-COT API is coming soon.
release StepAudio 3 Music, StepFun's first music generation foundation model, which can generate complete songs from prompts and lyrics. The model integrates four workflows: song generation, accompaniment generation, music cover, and vocal-to-song arrangement. ABC-COT plans the musical structure and arrangement before synthesis, and users can rewrite prompts, edit the ABC notation, and iterate. A Hugging Face Space demo and API documentation are now available, and the ABC-COT API is coming soon.
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Matched fieldsSummary
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Matched fieldsSummary、Body
Ant Ling has released and open-sourced Ling-3.0-flash-VL, the first native multimodal large model in the Ling series. Built as an extension of the Ling-3.0-flash MoE architecture, it has 124B total parameters and 5.5B activated per inference, natively supports image, text, and video inputs, and has a 256K Token context window. The company says native multimodal joint training improved the model's score on the Artificial Analysis Intelligence Index v4.1.1 by 4 points over the text-only version, and it introduces a visual feedback loop of observe, act, verify, and correct for front-end replication, GUI Agent, and medical report interpretation. The model is now available for free trial on Ling Studio, and the BF16 and FP8 versions have been open-sourced on Hugging Face and ModelScope.
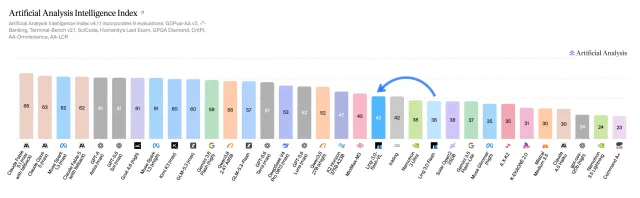
and has a 256K Token context window. The company says native multimodal joint training improved the model's score on the Artificial Analysis Intelligence Index v4.1.1 by 4 points over the text-only version, and it introduces a visual feedback loop of observe, act, verify, and correct for front-end replication, GUI Agent, and medical report interpretation. The model is now available for free trial on Ling Studio, and the BF16 and FP8 versions have been open-sourced on Hugging Face and ModelScope.
Matched fieldsSummary、Body