←Search results

By relevance · Total 2019 results Clear search

Friday

  1. PyTorch Blog

    PyTorch Conference 2026 held in San Jose, announces progress on TorchTPU and TorchNeuron

    PyTorch Conference North America 2026 was held on October 20–21 in San Jose, attracting more than 3,500 attendees and focusing on accelerating open intelligence and projects including PyTorch, vLLM, DeepSpeed, Ray, Helion, and Safetensors. The event announced TorchTPU, a native PyTorch TPU backend developed in collaboration between Google and Meta, as well as TorchNeuron, a native backend for AWS Trainium, which entered public testing under Apache 2.0 on October 20. Shopify shared a case study of building a continuous learning loop with PyTorch and vLLM, saying it compresses production failures into model weights every day and has reduced serving costs by 96%.

    PyTorchCon community expo

    PyTorch Conference North America 2026 was held on October 20–21 in San Jose, attracting more than 3,500 attendees and focusing on accelerating open intelligence and projects including PyTorch, vLLM, DeepSpeed, Ray, Helion, and Safetensors. The event announced TorchTPU, a native PyTorch TPU backend developed in collaboration between Google and Meta, as well as TorchNeuron, a native backend for AWS Trainium, which entered public testing under Apache 2.0 on October 20. Shopify shared a case study o

    Matched fieldsBody
  2. Hugging Face

    Microsoft uses ThinkingBox to turn database scoring into RL rewards, fine-tuning Qwen3.8-27B

    The Microsoft Copilot Studio team, in collaboration with Toloka and others, directly uses the executable final-state database checks of ThinkingBox-Bench as reinforcement learning rewards to perform full-parameter RL fine-tuning on Qwen3.8-27B. On 507 out-of-distribution tasks not involved in training, the number of tasks the model passed in all 20 attempts rose from 38 (7.5%) to 107 (21.1%), pass@1 rose from 51.70% to 60.78%, and the cost per successful attempt dropped from $0.177 to $0.139. The training pool was filtered using offline-policy relative difficulty, ultimately retaining 187 tasks; the training and evaluation code has been open-sourced at microsoft/thinkingbox-training.

    The Microsoft Copilot Studio team, in collaboration with Toloka and others, directly uses the executable final-state database checks of ThinkingBox-Bench as reinforcement learning rewards to perform full-parameter RL fine-tuning on Qwen3.8-27B. On 507 out-of-distribution tasks not involved in training, the number of tasks the model passed in all 20 attempts rose from 38 (7.5%) to 107 (21.1%), pass@1 rose from 51.70% to 60.78%, and the cost per successful attempt dropped from $0.177 to $0.139. Th

    Matched fieldsBody

  3. Latent Space

    Why AI compute is rectangular—a conversation with Modal CEO Erik Bernhardsson

    Modal CEO Erik Bernhardsson explains that traditional compute contracts, signed for a fixed number of GPUs and a fixed duration, are rectangular, whereas real workloads fluctuate; Modal provides elastic slices by aggregating demand from thousands of customers. Modal has surpassed $1 billion in annualized revenue, completed a $750 million Series D at a $16 billion valuation, and has cumulatively launched nearly 3 billion sandboxes. Sandboxes currently account for about one-third of Modal's revenue, with growth driven mainly by coding agents, background agents, and reinforcement learning.

    Modal CEO Erik Bernhardsson explains that traditional compute contracts, signed for a fixed number of GPUs and a fixed duration, are rectangular, whereas real workloads fluctuate; Modal provides elastic slices by aggregating demand from thousands of customers. Modal has surpassed $1 billion in annualized revenue, completed a $750 million Series D at a $16 billion valuation, and has cumulatively launched nearly 3 billion sandboxes. Sandboxes currently account for about one-third of Modal's revenu

    Matched fieldsBody

Thursday

  1. Dwarkesh Patel Podcast & Blog

    What will computer chips look like in 2045?

    Dwarkesh Patel spent two days touring Intel's most advanced wafer fab and talking with its management to explore what chips will look like in 2045. Intel's CTO said that over the past decade, AI compute demand has grown 3x each year, but global chip manufacturing equipment is only enough to roughly double advanced-process capacity. The episode also uses animations to explain technologies such as gate-all-around transistors, backside power delivery, CFET, and hybrid bonding.

    Matched fieldsBody

  2. CTech

    Modelyo raises $17 million to let enterprises use AI without exposing confidential data

    Israeli cybersecurity startup Modelyo has completed a funding round of approximately $17 million, led by US-based OlivTree, with the funds to be used for R&D on its "sovereign confidential cloud" platform and for international expansion. The platform combines confidential computing, hardware encryption, continuous verification and zero-trust architecture, enabling enterprises to retain control of their data and encryption keys while running AI and managed services on third-party clouds, and to cryptographically prove that data is protected. Founded in 2024, the company currently has 30 employees, and its technology is backed by more than 20 patents and applications. Target customers include government, defense, banking, healthcare and critical infrastructure operators.

    Israeli cybersecurity startup Modelyo has completed a funding round of approximately $17 million, led by US-based OlivTree, with the funds to be used for R&D on its "sovereign confidential cloud" platform and for international expansion. The platform combines confidential computing, hardware encryption, continuous verification and zero-trust architecture, enabling enterprises to retain control of their data and encryption keys while running AI and managed services on third-party clouds, and to c

    Matched fieldsBody

  3. Fortune Tech

    Musk's merger dream is a nightmare for SpaceX shareholders

    SpaceX and Tesla have each established special committees composed of independent directors to explore a merger between the two companies; after the news was announced, Tesla's stock rose 3.4% and SpaceX rose 7.8%, adding $155 billion in market value. At a 30% premium, SpaceX would need to pay about $1.98 trillion to acquire Tesla and issue new shares equivalent to 92% of its existing share capital, increasing its shares from 13.1 billion to 25 billion. Tesla's GAAP net profit over the past four quarters was only $3.28 billion, while SpaceX lost $1.5 billion over the same period; after the merger, SpaceX shareholders would give up nearly half of future earnings.

    SpaceX and Tesla have each established special committees composed of independent directors to explore a merger between the two companies; after the news was announced, Tesla's stock rose 3.4% and SpaceX rose 7.8%, adding $155 billion in market value. At a 30% premium, SpaceX would need to pay about $1.98 trillion to acquire Tesla and issue new shares equivalent to 92% of its existing share capital, increasing its shares from 13.1 billion to 25 billion. Tesla's GAAP net profit over the past four

    Matched fieldsBody

  4. The Elec

    AMD Extends FSR 4.1 Support to RX 6000 Series

    On October 20, AMD announced that it is extending FSR 4.1 support to the Radeon RX 6000 series, Ryzen AI Max processors, and Xbox consoles, with the technology available through AMD Software: Adrenalin Edition version 26.10.1. FSR 4.1 uses an INT8 model; AMD improved hardware compatibility by simplifying and optimizing the compute architecture, and designed a separate lightweight model for handheld devices. This update also adds support for the Vulkan 3D graphics API and improves frame pacing.

    Matched fieldsBody

  5. AWS Machine Learning

    AAIF: An Adaptive Agent Framework Based on Strands Agents

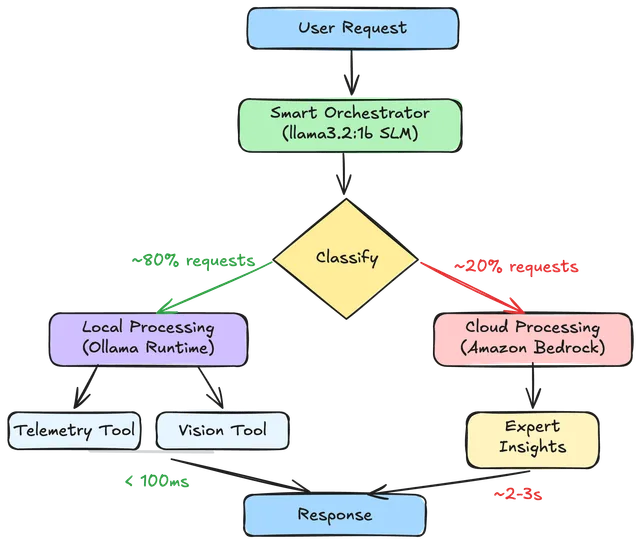
    AWS built the Adaptive Agent Intelligence Framework (AAIF) with Strands Agents, using llama3.2:1b as the orchestration layer to classify requests: routine tasks are handled by a local SLM via Ollama, while complex analysis is routed through boto3 to frontier models on Amazon Bedrock. This architecture can run on edge devices such as a Raspberry Pi with 8 GB of memory, or be deployed fully in the cloud or in a hybrid setup, thereby reducing API costs while maintaining low local latency.

    AAIF three-layer architecture with an SLM orchestrator routing requests to local processing tools or to Amazon Bedrock cloud processing

    Matched fieldsBody

  6. PyTorch Blog

    TorchTitan Update: Support for Multiple New SOTA Models, TitanRL, and Large-Scale Performance Improvements

    PyTorch's native training platform TorchTitan has released an update that adds full training-stack support for Muse Spark Open, Muse Glimmer, Qwen3-VL, Qwen3.5, Kimi K2.7, Kimi K3, and DeepSeek-V4, and introduces the reinforcement learning component TitanRL. TitanRL lets pretraining, post-training, and vLLM inference share the same model code, and supports asynchronous rollout as well as agent-task training such as long-context and code execution. On performance, FlexShard on 256 H100 GPUs reduces DeepSeekV3 optimizer time by up to 79%, and reduces end-to-end training step time on Llama3 405B by up to 20%.

    PyTorch's native training platform TorchTitan has released an update that adds full training-stack support for Muse Spark Open, Muse Glimmer, Qwen3-VL, Qwen3.5, Kimi K2.7, Kimi K3, and DeepSeek-V4, and introduces the reinforcement learning component TitanRL. TitanRL lets pretraining, post-training, and vLLM inference share the same model code, and supports asynchronous rollout as well as agent-task training such as long-context and code execution. On performance, FlexShard on 256 H100 GPUs reduc

    Matched fieldsBody

Wednesday

  1. LMSYS Blog

    SGLang's Elastic Expert Parallelism Scaling: Online Scaling of MoE Deployments with NIXL

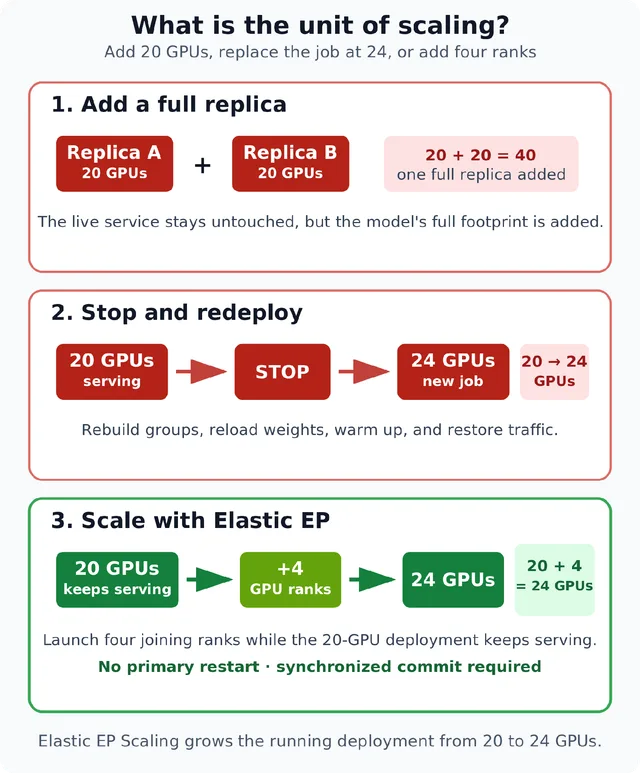
    SGLang's Elastic EP Scaling lets MoE deployments add GPUs in fine-grained increments without full replicas or restarts, scaling from 20 GPUs to 24 GPUs in the example. max_ep_size reserves metadata and communication buffer capacity at startup, and new ranks start on demand; tested on 8×H100 with DeepSeek-V3-Lite FP8, the first completed request was 5.3×–8.2× faster than a restart. After a joining rank enters the Mooncake WORLD, automatic rollback is not currently supported, and a failure during finalization may require restarting the deployment.

    Comparison of horizontal scaling, restart-based vertical scaling, and live Elastic EP scaling from 20 to 24 GPUs.

    SGLang's Elastic EP Scaling lets MoE deployments add GPUs in fine-grained increments without full replicas or restarts, scaling from 20 GPUs to 24 GPUs in the example. max ep size reserves metadata and communication buffer capacity at startup, and new ranks start on demand; tested on 8×H100 with DeepSeek-V3-Lite FP8, the first completed request was 5.3×–8.2× faster than a restart. After a joining rank enters the Mooncake WORLD, automatic rollback is not currently supported, and a failure during

    Matched fieldsBody

  2. Cohere Product and Research BlogSelected

    Cohere releases Rerank 5 Pro and Fast retrieval models

    Cohere releases enterprise retrieval model Rerank 5, in Pro and Fast tiers, now available on Cohere API, Model Vault, Microsoft Foundry and Amazon SageMaker, with Pro priced at $0.05 per 1M tokens and Fast at $0.02. Cohere says Rerank 5 Pro leads all tested models on four public benchmarks: ViDoRe V3, nanoMTEB, BRIGHT and BEIR, ranking first on 39 of 46 composite datasets. The new Context Focus feature can return the most relevant text snippets within a document in a single call; in official tests, removing half the context lost only 2 percentage points of answer quality.

    Abstract image

    Cohere releases enterprise retrieval model Rerank 5, in Pro and Fast tiers, now available on Cohere API, Model Vault, Microsoft Foundry and Amazon SageMaker, with Pro priced at $0.05 per 1M tokens and Fast at $0.02. Cohere says Rerank 5 Pro leads all tested models on four public benchmarks: ViDoRe V3, nanoMTEB, BRIGHT and BEIR, ranking first on 39 of 46 composite datasets. The new Context Focus feature can return the most relevant text snippets within a document in a single call; in official tes

    Matched fieldsBody

  3. ChinaTalkSelected

    China's Ministry of Commerce plans to include AI models in the export control catalog

    China's Ministry of Commerce and Ministry of Science and Technology issued Announcement No. 48 of 2026 on October 16, proposing to add 40 items to the Catalogue of Technologies Prohibited or Restricted from Export in China, of which 14 are prohibited from export and 26 are restricted from export, and to implement pre-export registration for all newly added technologies effective immediately. The draft sets three thresholds for frontier models: ≥10^26 FLOP, ≥2T parameters, or reaching a globally leading level, and also covers AI chip design, memory chips, ten-thousand-card-level clusters, agents, AIGC detection tools, training data, and cyber offense and defense capabilities; scenarios such as open source, self-built overseas data centers, and overseas tape-out may use the report-and-export channel. The public comment period runs until November 15.

    China's Ministry of Commerce and Ministry of Science and Technology issued Announcement No. 48 of 2026 on October 16, proposing to add 40 items to the Catalogue of Technologies Prohibited or Restricted from Export in China, of which 14 are prohibited from export and 26 are restricted from export, and to implement pre-export registration for all newly added technologies effective immediately. The draft sets three thresholds for frontier models: ≥10^26 FLOP, ≥2T parameters, or reaching a globally

    Matched fieldsBody

  4. Analytics India Magazine

    OpenAI plans to raise $30 billion at a $1.4 trillion valuation, ahead of Anthropic's IPO

    According to Reuters, OpenAI is accelerating a $30 billion fundraising at a valuation that could exceed $1.4 trillion, with existing investors including SoftBank and MGX in talks to participate. OpenAI told investors its annualized revenue has reached $50 billion and is expected to rise to $70 billion by the end of 2026; its previous valuation was $852 billion in March 2026. The report also mentions that Anthropic is expected to IPO in mid-November at a valuation of up to $2 trillion, with third-quarter 2026 revenue of $16.8 billion and first-half compute and infrastructure spending of nearly $9 billion.

    According to Reuters, OpenAI is accelerating a $30 billion fundraising at a valuation that could exceed $1.4 trillion, with existing investors including SoftBank and MGX in talks to participate. OpenAI told investors its annualized revenue has reached $50 billion and is expected to rise to $70 billion by the end of 2026; its previous valuation was $852 billion in March 2026. The report also mentions that Anthropic is expected to IPO in mid-November at a valuation of up to $2 trillion, with third

    Matched fieldsBody