←Search results

By relevance · Total 2769 results Clear search

Wednesday

  1. 9to5Mac

    Apple Wins Expanded Discovery in OpenAI Trade Secrets Lawsuit

    Apple won a ruling expanding the scope of discovery in its trade secret misappropriation lawsuit against two former employees, OpenAI and io Products. Judge Edward Davila approved its request to obtain records of the former employees' use of AI tools such as ChatGPT, Claude, Codex and OpenClaw, as well as related testimony concerning batteries, power management and metal surface treatment. The judge simultaneously denied Apple's requests regarding OpenAI's own devices and accounts, internal investigations and potentially deleted information; the defendants must submit the relevant records and respond within 14 days.

    Apple won a ruling expanding the scope of discovery in its trade secret misappropriation lawsuit against two former employees, OpenAI and io Products. Judge Edward Davila approved its request to obtain records of the former employees' use of AI tools such as ChatGPT, Claude, Codex and OpenClaw, as well as related testimony concerning batteries, power management and metal surface treatment. The judge simultaneously denied Apple's requests regarding OpenAI's own devices and accounts, internal inve

    Matched fieldsBody
  2. Numerama

    Mathematicians' group AGMAI demands OpenAI immediately publish Yang-Mills theory proof

    AGMAI, composed of nine mathematicians, called on OpenAI to immediately publish the natural-language and Lean versions of its claimed proofs of Yang-Mills theory, quantum chromodynamics, and the completeness of the Standard Model. OpenAI announced three mathematics, computer science, and physics results on October 26, stating that the Yang-Mills proof was completed on September 9 and its Lean formalization was completed on October 16, but the proof has only been seen by five physicists selected by OpenAI (led by 2004 Nobel Prize in Physics laureate David Gross). AGMAI is affiliated with the Institute for Advanced Study in Princeton, noted that the problem is one of the Millennium Prize Problems, and cited its October 25 statement opposing AI companies selecting the first reviewers themselves.

    AGMAI, composed of nine mathematicians, called on OpenAI to immediately publish the natural-language and Lean versions of its claimed proofs of Yang-Mills theory, quantum chromodynamics, and the completeness of the Standard Model. OpenAI announced three mathematics, computer science, and physics results on October 26, stating that the Yang-Mills proof was completed on September 9 and its Lean formalization was completed on October 16, but the proof has only been seen by five physicists selected

    Matched fieldsBody

  3. CNET

    Behind the PHP Critical Vulnerability Warning: Aging Web Infrastructure and Insufficient Maintenance Resources

    A team using OpenAI models discovered two major vulnerabilities in PHP, and a new version of PHP was subsequently released with calls for site operators to update; some European government websites briefly went offline due to the updates. The article notes that the PHP Foundation, which coordinates PHP security issues, has only one full-time employee, and Executive Director Elizabeth Barron said PHP is severely underfunded; a Network Solutions survey of 121 small-business site owners showed that 45% had never heard of PHP, and 71% did not know whether their own websites used PHP. Cloudflare deployed new Web Application Firewall protections and launched a PHP vulnerability bounty contest, with rewards ranging from $100 to $10,000.

    A team using OpenAI models discovered two major vulnerabilities in PHP, and a new version of PHP was subsequently released with calls for site operators to update; some European government websites briefly went offline due to the updates. The article notes that the PHP Foundation, which coordinates PHP security issues, has only one full-time employee, and Executive Director Elizabeth Barron said PHP is severely underfunded; a Network Solutions survey of 121 small-business site owners showed that

    Matched fieldsBody

  4. Ai2 BlogSelected

    Ai2 Releases "Old Ideas, Novel Problems" Study: LLMs Are Unreliable at Judging the Novelty of Research Ideas

    Ai2 released the "Old Ideas, Novel Problems" study and a companion benchmark, testing the reliability of six models—GPT-5.1, GPT-5.2, GPT-5.4, Claude Sonnet 4.5, Claude Opus 4.5, and Claude Opus 4.6—at judging the novelty of research ideas. The results show that small changes to the evaluation setup produce drastic differences: after switching GPT-5.4 to a simpler prompt on the Human+Generated data, its accuracy dropped from 93.5% to 40.9%, below chance level. The study also found that retrieval and additional reasoning do not reliably improve judgment quality; two purpose-built novelty evaluation systems performed worse than a simple Claude Opus 4.6 prompt baseline and cost more.

    Ai2 released the "Old Ideas, Novel Problems" study and a companion benchmark, testing the reliability of six models—GPT-5.1, GPT-5.2, GPT-5.4, Claude Sonnet 4.5, Claude Opus 4.5, and Claude Opus 4.6—at judging the novelty of research ideas. The results show that small changes to the evaluation setup produce drastic differences: after switching GPT-5.4 to a simpler prompt on the Human+Generated data, its accuracy dropped from 93.5% to 40.9%, below chance level. The study also found that retrieval

    Matched fieldsBody

  5. Electronic Technology Application

    AMD Plans to Invest $1 Billion in Meta and Deepen Strategic Cooperation

    AMD announced a deep strategic partnership with Meta and will invest $1 billion in Meta's equity offering. AMD Helios rack-scale solutions have completed their first installations at Meta and entered testing, AMD EPYC processors provide compute power for Meta's Muse AI agents, and AMD also provides Day-0 support for Muse Spark Open and Muse Glimmer.

    Matched fieldsBody

  6. BBC ChineseSelected

    Anthropic Publishes IPO Prospectus, Disclosing Five Key Pieces of Information

    Anthropic has published the 335-page prospectus required for a U.S. stock market listing, with the market expecting its listing valuation could reach $2 trillion or more. The document shows the company lost $80.7 billion in the first half of this year, twice its full-year loss for 2025, while revenue over the same period was $16.2 billion; its business is highly dependent on a small number of major customers, with just five enterprise clients contributing a quarter of its business. The document also lists the catastrophic or existential risks that advanced AI may bring, and says AI is expected to deliver benefits in fields such as healthcare, education and power grids.

    Anthropic has published the 335-page prospectus required for a U.S. stock market listing, with the market expecting its listing valuation could reach $2 trillion or more. The document shows the company lost $80.7 billion in the first half of this year, twice its full-year loss for 2025, while revenue over the same period was $16.2 billion; its business is highly dependent on a small number of major customers, with just five enterprise clients contributing a quarter of its business. The document

    Matched fieldsBody

  7. Cognition Model / Devin Blog

    Cognition Releases FrontierCode 2.0 Coding Benchmark: Opus 5.5 Scores Only 45%

    Cognition launches the FrontierCode 2.0 coding benchmark to assess whether the code produced by models can actually be merged; even the highest-scoring Opus 5.5 scores only 45%, showing the benchmark is far from saturated. Compared with version 1.1, reference solutions modify on average 67% more files and 89% more lines of code, the codebase size is 25% larger, task-covered repositories increase by 55%, and blocking scoring criteria increase by 43%. DeepSeek V4.1 Flash drops from 43.9% to 19.3%, and Kimi K3 drops from 44.2% to 17.7%; open-source models, especially Western open-source models, still have significant room for improvement.

    Cognition launches the FrontierCode 2.0 coding benchmark to assess whether the code produced by models can actually be merged; even the highest-scoring Opus 5.5 scores only 45%, showing the benchmark is far from saturated. Compared with version 1.1, reference solutions modify on average 67% more files and 89% more lines of code, the codebase size is 25% larger, task-covered repositories increase by 55%, and blocking scoring criteria increase by 43%. DeepSeek V4.1 Flash drops from 43.9% to 19.3%,

    Matched fieldsBody

  8. Codex:GitHub Releases

    OpenAI Codex 0.165.0 Released: Adds Google Cloud Vertex AI Provider and…

    OpenAI Codex 0.165.0 adds a built-in Google Cloud Vertex AI provider (configured via model_provider = "gcp") and adds GPT-6.1 Terra to the model catalog. This version also enables memory v2 by default and supports importing external agent memory, while allowing reasoning effort to be adjusted during conversations by default. The session selector adds repository filtering, and the agent command center supports grouping by directory.

    OpenAI Codex 0.165.0 adds a built-in Google Cloud Vertex AI provider (configured via model provider = "gcp") and adds GPT-6.1 Terra to the model catalog. This version also enables memory v2 by default and supports importing external agent memory, while allowing reasoning effort to be adjusted during conversations by default. The session selector adds repository filtering, and the agent command center supports grouping by directory.

    Matched fieldsBody

  9. NVIDIA Developer · Generative AI

    NVIDIA Explains How to Fine-Tune Nemotron 3.5 Lightning with the Nemotron-Personas Dataset

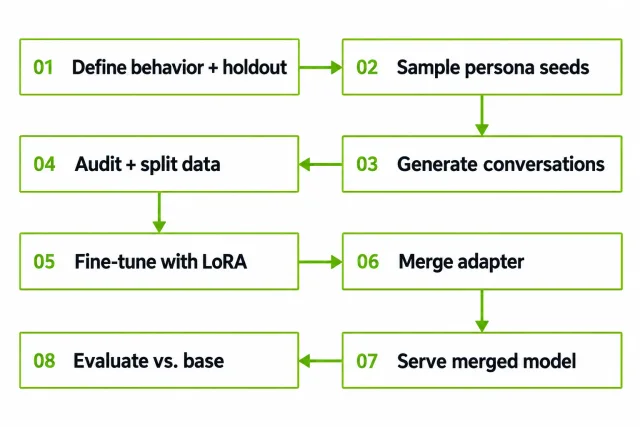
    NVIDIA has released the Nemotron-Personas France and Belgium datasets and provided a complete post-training workflow for fine-tuning Nemotron 3.5 Lightning with them. The workflow includes defining behavior contracts, generating synthetic conversations with personas, fine-tuning with LoRA on NVIDIA NeMo, merging adapters, and then comparing and evaluating item by item against the base model on a frozen test set. The France dataset was built in collaboration with Pleias, and the Belgium dataset involved Pleias and KU Leuven; the Nemotron repository provides reusable steps and agent skills for data generation, training, and evaluation.

    Flowchart showing eight stages: define target behavior and a holdout set, sample personas, generate conversations, audit and split data, fine-tune with LoRA, merge the adapter, serve the adapted model, and evaluate it against the base model.

    NVIDIA has released the Nemotron-Personas France and Belgium datasets and provided a complete post-training workflow for fine-tuning Nemotron 3.5 Lightning with them. The workflow includes defining behavior contracts, generating synthetic conversations with personas, fine-tuning with LoRA on NVIDIA NeMo, merging adapters, and then comparing and evaluating item by item against the base model on a frozen test set. The France dataset was built in collaboration with Pleias, and the Belgium dataset i

    Matched fieldsBody

  10. Hugging FaceSelected

    Liquid AI Releases the LFM3 Series of Models, Including 1.7B Text, Vision, Audio, and Omni Versions

    Liquid AI has released the LFM3 series of open-weight models, all branched from LFM3-1.7B-Base, covering text, vision, audio, Omni, and the d1 decision model. LFM3-1.7B-Base adopts a three-hybrid-layer architecture, is pretrained on 22T tokens, and in the mid-training stage over the final 3.5T tokens incorporates more agent trajectories and tool-calling data, with the context window extended to 256K tokens. The company says LFM3-1.7B is about 25% faster than LFM2-1.2B at an 8K context, and scores 38.42 versus 3.02 on WebArena-Verified; LFM3-VL-2B's average score across 62 vision benchmarks rises from 57.6 to 71.4. All models are available for download on Hugging Face, along with a single-GPU fine-tuning notebook.

    Liquid AI has released the LFM3 series of open-weight models, all branched from LFM3-1.7B-Base, covering text, vision, audio, Omni, and the d1 decision model. LFM3-1.7B-Base adopts a three-hybrid-layer architecture, is pretrained on 22T tokens, and in the mid-training stage over the final 3.5T tokens incorporates more agent trajectories and tool-calling data, with the context window extended to 256K tokens. The company says LFM3-1.7B is about 25% faster than LFM2-1.2B at an 8K context, and score

    Matched fieldsBody

  11. Latent SpaceSelected

    Anthropic's Engineering and Product Leads Discuss the Opus 5.5 Release and Claude's Agent Architecture

    In a Latent Space podcast interview, Anthropic engineering lead Katelyn Lesse and product lead Angela Jiang discussed the Opus 5.5 release, covering adjustments to the model's writing style, pricing based on intelligence per dollar, and API changes such as requiring thinking blocks to be retained across turns to prevent distillation. The interview also described Claude Managed Agents' approach of separating sessions and the harness from the sandbox that executes code, with credentials mounted separately through a proxy so that a sandbox failure does not take down the entire session; Dreaming, meanwhile, is implemented as one managed agent inspecting another agent's history and writing back to memory. The team said that as safety work for model releases has grown heavier, recent efforts have shifted more toward safety, with progress on features such as skills and memory slowing relatively.

    In a Latent Space podcast interview, Anthropic engineering lead Katelyn Lesse and product lead Angela Jiang discussed the Opus 5.5 release, covering adjustments to the model's writing style, pricing based on intelligence per dollar, and API changes such as requiring thinking blocks to be retained across turns to prevent distillation. The interview also described Claude Managed Agents' approach of separating sessions and the harness from the sandbox that executes code, with credentials mounted se

    Matched fieldsBody

  12. Google DeepMindSelected

    Google DeepMind releases world model Genie 4, supporting native audio and real-time interaction

    Google DeepMind has released the world model Genie 4, which can generate interactive worlds in real time and, for the first time, natively generate ambient sound and character dialogue. The model builds on capabilities from the Gemini series; Gemini 3.8 Flash breaks down goals in a loop and checks frames to maintain causal coherence across multi-step events, and Gemini 4 Argon has also been used for joint simulation tasks with Gemini Robotics. The company says it remains an early experimental model: over long runs, object permanence and complex physical interactions still drift, all generated content carries a SynthID watermark, and it is currently available in preview to trusted testers first.

    Google DeepMind has released the world model Genie 4, which can generate interactive worlds in real time and, for the first time, natively generate ambient sound and character dialogue. The model builds on capabilities from the Gemini series; Gemini 3.8 Flash breaks down goals in a loop and checks frames to maintain causal coherence across multi-step events, and Gemini 4 Argon has also been used for joint simulation tasks with Gemini Robotics. The company says it remains an early experimental mo

    Matched fieldsBody

  13. AWS Machine Learning

    Fixing evaluation bias to select a better model on Amazon Bedrock

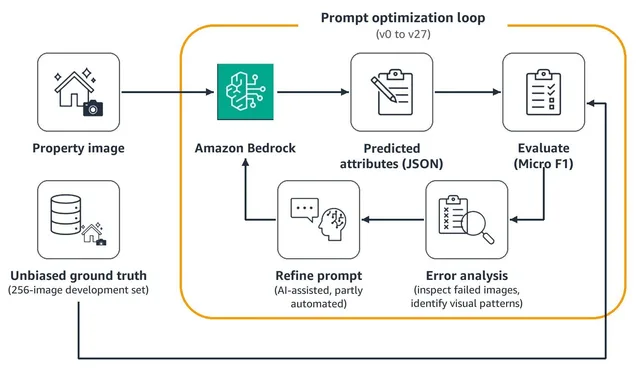
    Property Finder found that 96.8% of its evaluation labels came directly from predictions of an existing vision-language model rather than human verification, causing any alternative model to be structurally disadvantaged in comparisons. The team re-annotated 356 UAE images by hand and switched to multi-label classification, then iterated and optimized prompts from v0 to v27 to select a model on Amazon Bedrock, ultimately achieving higher accuracy and an 86% cost reduction.

    Diagram of the prompt optimization loop: a property image goes to Amazon Bedrock, the predicted attributes are scored with Micro F1 against the expert-annotated development set, error analysis informs the next prompt version, and the loop repeats from v0 to v27.

    Matched fieldsBody

Tuesday

  1. The Guardian Technology

    Anthropic Files for IPO, Valuation Reportedly Exceeds $1.5 Trillion

    Anthropic filed for an IPO in the United States on Monday, with investors and analysts valuing the company at more than $1.5 trillion. The prospectus shows its revenue grew from $41 million in 2023 to $4.585 billion in 2025, reaching $16.286 billion in the first half of 2026, while its net loss over the same period was $80 billion, mainly due to a one-time charge of $72.4 billion.

    Matched fieldsBody

  2. Browser Use

    What to Do When Headless Browsers Are Blocked by Cloudflare: Which Solutions Work (2026)

    Stealth Bench V2, released by Browser Use, shows that headless Chrome without a proxy passes only 3% of visits, headed Chrome with a US proxy reaches 14%, and Browser Use Cloud reaches 90.5%. Cloudflare identifies automation through navigator.webdriver, TLS and request header fingerprints, IP reputation, and cookie and behavioral signals; stealth plugins alone cannot change TLS and IP. Browser Use Cloud is priced at $0.02 per browser hour plus $5/GB for proxies, and its official documentation states that access to all sites is not guaranteed.

    Stealth Bench V2, released by Browser Use, shows that headless Chrome without a proxy passes only 3% of visits, headed Chrome with a US proxy reaches 14%, and Browser Use Cloud reaches 90.5%. Cloudflare identifies automation through navigator.webdriver, TLS and request header fingerprints, IP reputation, and cookie and behavioral signals; stealth plugins alone cannot change TLS and IP. Browser Use Cloud is priced at $0.02 per browser hour plus $5/GB for proxies, and its official documentation st

    Matched fieldsBody

  3. Replit Blog

    Replit Cloud Agents are now available to Pro and Enterprise users…

    Replit announced that Cloud Agents are now available to all Pro and Enterprise customers. Non-engineers can describe changes in natural language, and the agent locates the code, runs the application in a cloud sandbox to verify it, and submits a PR or MR with screenshots and video to GitHub or GitLab. Teams can configure a shared environment once, and review feedback can be turned into skill updates that require engineer approval; the feature is in early access. The Slack integration is now available to all customers, and Microsoft Teams support is coming soon.

    Anyone can now bring their ideas into the company codebase — cover image

    Replit announced that Cloud Agents are now available to all Pro and Enterprise customers. Non-engineers can describe changes in natural language, and the agent locates the code, runs the application in a cloud sandbox to verify it, and submits a PR or MR with screenshots and video to GitHub or GitLab. Teams can configure a shared environment once, and review feedback can be turned into skill updates that require engineer approval; the feature is in early access. The Slack integration is now avai

    Matched fieldsBody

  4. a16z:News

    a16z Long Read: Databricks and the Enterprise in the Agent Era

    a16z partners Ben Horowitz and Michael McGuiness wrote the article, using Databricks' four generations of technological evolution—from Spark and Lakehouse to Lakebase and agents—as a thread to discuss how agents are changing enterprises. The article states that Databricks has surpassed $7 billion in annualized revenue, up 80% year over year, at a valuation of $190 billion, with more than 17 million databases launched by agents every day. The authors argue that enterprises need an agent-facing system of record that captures definitions, permissions, and evaluation results, and believe that in the future more people's work will shift toward specifying tasks, delegating execution, and checking results.

    a16z partners Ben Horowitz and Michael McGuiness wrote the article, using Databricks' four generations of technological evolution—from Spark and Lakehouse to Lakebase and agents—as a thread to discuss how agents are changing enterprises. The article states that Databricks has surpassed $7 billion in annualized revenue, up 80% year over year, at a valuation of $190 billion, with more than 17 million databases launched by agents every day. The authors argue that enterprises need an agent-facing sy

    Matched fieldsBody

  5. Google Developers Blog

    Google A2UI Introduces Swappable Inference Formats, Express Cuts Latency by Up to 3x

    Google A2UI adds swappable inference formats, among which A2UI Express, as the new default format, can reduce latency by up to 3x and cut the tokens needed to generate comparable UIs by up to 3x; when combined with decision models such as Jev for layout decisions, latency reductions can reach up to 80x. Express is now available in the Python agent SDK (a2ui-agent-sdk 0.9.0), the TypeScript SDK (@a2ui/agent), and the Dart SDK (a2ui_agent 0.0.1-wip004); developers can switch formats with a single parameter when creating a generator.

    00-header-1600x900 (1)

    Google A2UI adds swappable inference formats, among which A2UI Express, as the new default format, can reduce latency by up to 3x and cut the tokens needed to generate comparable UIs by up to 3x; when combined with decision models such as Jev for layout decisions, latency reductions can reach up to 80x. Express is now available in the Python agent SDK (a2ui-agent-sdk 0.9.0), the TypeScript SDK (@a2ui/agent), and the Dart SDK (a2ui agent 0.0.1-wip004); developers can switch formats with a single

    Matched fieldsBody

  6. Claude BlogSelected

    Anthropic Launches Claude for Financial Advisors Connectors and Skills Suite

    Anthropic has released Claude for Financial Advisors, connecting data from custodians, asset management and wealthtech platforms into Claude, and providing skills tailored to financial advisors' daily work. The suite includes connectors such as Addepar, BlackRock, Charles Schwab, Envestnet, FactSet, Orion and Wealthbox, as well as skills for meeting preparation, portfolio rebalancing review, post-meeting notes and follow-up, and compliance and AI policy checks; regulated steps such as investment advice and client communication still require human review. The advisor plugin is available starting today, and the official recommendation is for registered investment advisors to use the Enterprise plan with audit logs.

    Anthropic has released Claude for Financial Advisors, connecting data from custodians, asset management and wealthtech platforms into Claude, and providing skills tailored to financial advisors' daily work. The suite includes connectors such as Addepar, BlackRock, Charles Schwab, Envestnet, FactSet, Orion and Wealthbox, as well as skills for meeting preparation, portfolio rebalancing review, post-meeting notes and follow-up, and compliance and AI policy checks; regulated steps such as investment

    Matched fieldsBody

  7. Claude Blog

    How to manage Claude Code costs on Google Cloud and prove ROI

    Based on a recent webinar with Google Cloud, Anthropic presents a three-lever framework—control, track, prove—for managing Claude Code costs on Google Cloud and measuring return on investment. The Claude apps gateway supports setting daily/weekly/monthly spending limits by user, IdP group, or organization, alerts within the CLI when usage reaches 75% and 95%, and returns 429 once the cap is hit. On the Google Cloud side, native capabilities include per-project billing, budget alerts, Spend caps (preview), BigQuery export, and quotas.

    Based on a recent webinar with Google Cloud, Anthropic presents a three-lever framework—control, track, prove—for managing Claude Code costs on Google Cloud and measuring return on investment. The Claude apps gateway supports setting daily/weekly/monthly spending limits by user, IdP group, or organization, alerts within the CLI when usage reaches 75% and 95%, and returns 429 once the cap is hit. On the Google Cloud side, native capabilities include per-project billing, budget alerts, Spend caps

    Matched fieldsBody