←Search results

By relevance · Total 2750 results Clear search

Thursday

  1. LMSYS Blog

    LMSYS uses Miles to train a SWE agent on MI355X, SWE-bench Verified…

    LMSYS used Miles, SGLang, Megatron-LM, and Harbor to perform fully asynchronous agent reinforcement learning on Qwen3-30B-A3B-Instruct on AMD Instinct MI355X, raising pass@1 from 7.3% to 27.5% on a 100-task stratified subset of SWE-bench Verified. Training was conducted in two stages: first SFT on approximately 4,000 public trajectories from Open-SWE-Traces, then GRPO on approximately 1,350 SWE-smith tasks. After fixing the model and RL recipe, scaling inference from 1 node to 3 8-GPU nodes, switching to E2B cloud sandboxes, and removing the concurrency limit increased rollout throughput from approximately 860 to approximately 3,480 trajectories/hour; limiting trajectory length on the same 8-GPU node reduced single-step training time from 850 seconds to 284 seconds.
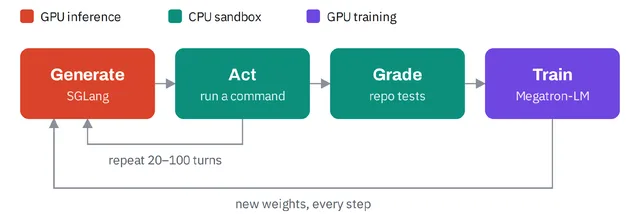
    Agentic RL loop: SGLang generates actions, a CPU sandbox executes and grades them, and Megatron-LM trains on the resulting trajectories.

    LMSYS used Miles, SGLang, Megatron-LM, and Harbor to perform fully asynchronous agent reinforcement learning on Qwen3-30B-A3B-Instruct on AMD Instinct MI355X, raising pass@1 from 7.3% to 27.5% on a 100-task stratified subset of SWE-bench Verified. Training was conducted in two stages: first SFT on approximately 4,000 public trajectories from Open-SWE-Traces, then GRPO on approximately 1,350 SWE-smith tasks. After fixing the model and RL recipe, scaling inference from 1 node to 3 8-GPU nodes, swi

    Matched fieldsBody
  2. The Verge AI

    Report says Texas data center expansion could erase decades of air quality improvements

    A report by the Houston Advanced Research Center (HARC) says that if all planned data centers in Texas are connected to the grid and powered under the expected grid structure, fine particulate pollution from the power sector will more than triple within five years, reaching the highest level since 2006; haze-forming NOx emissions will increase by 136%, approaching 2004 levels; and carbon dioxide emissions will be 90% higher than in 2025. The report models three data center energy consumption forecasts and notes that if data centers are paired with self-built renewable energy, NOx emissions could be as much as 10 times lower, but if gas-fired generation is built on-site to avoid grid interconnection queues, pollution could instead be the highest. Texas currently ranks first in the U.S. data center market with 26 GW of under-construction and existing capacity.

    A report by the Houston Advanced Research Center (HARC) says that if all planned data centers in Texas are connected to the grid and powered under the expected grid structure, fine particulate pollution from the power sector will more than triple within five years, reaching the highest level since 2006; haze-forming NOx emissions will increase by 136%, approaching 2004 levels; and carbon dioxide emissions will be 90% higher than in 2025. The report models three data center energy consumption for

    Matched fieldsBody

  3. Claude Code:GitHub Releases

    Claude Code v2.1.307 released

    Claude Code v2.1.307 adds the `/claude-api api-version` command, which can migrate Claude API code to API version `2026-10-21`, and adds a `claude_code.safety_event` OpenTelemetry event for each tool call that is blocked, prompted, or returned by permission rules, auto mode, safety checks, hooks, or the sandbox. This version also fixes the issue where alias models such as `opus[1m]` reported model-not-found when `CLAUDE_CODE_DISABLE_1M_CONTEXT` was set, as well as the issue where MCP servers in `claude -p` falsely reported "authentication required" when the macOS keychain was locked.

    Claude Code v2.1.307 adds the /claude-api api-version command, which can migrate Claude API code to API version 2026-10-21 , and adds a claude code.safety event OpenTelemetry event for each tool call that is blocked, prompted, or returned by permission rules, auto mode, safety checks, hooks, or the sandbox. This version also fixes the issue where alias models such as opus[1m] reported model-not-found when CLAUDE CODE DISABLE 1M CONTEXT was set, as well as the issue where MCP servers in claude -p

    Matched fieldsBody

  4. TechCrunch AI

    Meta says its AI app Muse has over 10 million users, with shopping among the main uses

    Meta said at its third-quarter earnings call that its AI app Muse now has more than 10 million users, with about 25% of registered users using it daily. Zuckerberg said that among active users who shop using the Muse agent, more than a quarter spend an average of over $200 per transaction, and that Muse enables agentic shopping through a Plaid connector. He also said Muse has achieved product-market fit, and that the next step is to scale up, grow revenue, and optimize compute costs, with cost efficiency expected to improve more than 10-fold over the next year.

    Meta said at its third-quarter earnings call that its AI app Muse now has more than 10 million users, with about 25% of registered users using it daily. Zuckerberg said that among active users who shop using the Muse agent, more than a quarter spend an average of over $200 per transaction, and that Muse enables agentic shopping through a Plaid connector. He also said Muse has achieved product-market fit, and that the next step is to scale up, grow revenue, and optimize compute costs, with cost e

    Matched fieldsBody

  5. Unite.AISelected

    Anthropic opens Claude Duet research preview to Pro and Max users in the US

    On October 21, 2026, Anthropic opened the Claude Duet research preview. Built on Claude Opus 5.5, the app turns Claude into a proactive agent that can proactively surface to-dos, continue executing tasks after the user leaves, and confirm before acting on the user's behalf. Access is available through a waitlist, starting with Pro and Max users in the US, and is offered via standalone iOS and Android apps and the claude.ai entry point. During the preview period it is included in the Pro and Max plans and is subject to the same usage limits. The app can call on more than 6,000 connectors and plugins in the Claude Marketplace; user approval is required before sending messages, making payments, signing documents, or deleting content, while securities trading and transfers between accounts are not permitted even with approval.

    On October 21, 2026, Anthropic opened the Claude Duet research preview. Built on Claude Opus 5.5, the app turns Claude into a proactive agent that can proactively surface to-dos, continue executing tasks after the user leaves, and confirm before acting on the user's behalf. Access is available through a waitlist, starting with Pro and Max users in the US, and is offered via standalone iOS and Android apps and the claude.ai entry point. During the preview period it is included in the Pro and Max

    Matched fieldsBody

  6. TechCrunch AI

    One-year-old AI lab Flapping Airplanes raises $1 billion Series A at a $6 billion valuation

    One-year-old AI lab Flapping Airplanes announced it has raised a $1 billion Series A co-led by Index and Lux, reportedly at a $6 billion valuation. This comes just nine months after its $180 million seed round at a $150 million valuation, quadrupling its valuation. The founding team says its megakernel framework can complete training, inference, and game running in a single kernel, with the goal of enabling models to complete training with less data.

    Matched fieldsBody

  7. AWS Machine Learning

    How U.S. Hunger Uses Amazon Quick to Connect Leadership with Data

    The U.S. nonprofit organization U.S. Hunger uses Amazon Quick to let leadership directly explore organizational data and share KPI definitions and financial documents through Quick Spaces; 17 colleagues currently have access. Its data comes from its own platform Impact Manager, refreshed nightly at 2 AM ET from SQL Server into the in-memory engine SPICE. The organization has delivered more than 250 million meals in total, growing about 500% over four years while staff headcount grew only 15–20%.

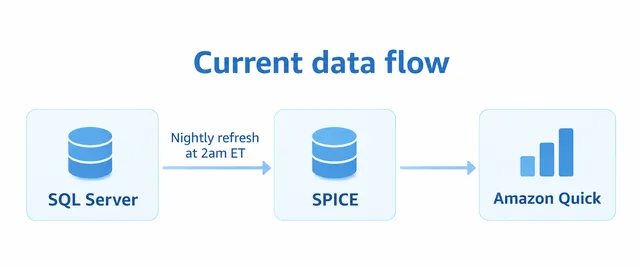
    Current architecture: SQL Server data refreshes into SPICE at 2 AM ET each night for analysis in Amazon Quick.

    Matched fieldsBody

  8. cnBeta

    GM injects AI into OnStar: from in-vehicle call center to intelligent assistant platform

    General Motors has unveiled the new OnStar AI Assistant, which will debut on the 2027 Cadillac Lyriq, and plans to launch a new version of the OnStar mobile app in 2027, replacing OnStar Guardian and the separate apps for each brand. The assistant is developed in-house by GM, with the goal of transforming OnStar from an accident-assistance call center into a connected intelligent platform that can proactively offer suggestions. Vehicle cameras will also be integrated with OnStar, enabling real-time viewing of the surroundings outside the car and automatic recording of video of unusual events.

    General Motors has unveiled the new OnStar AI Assistant, which will debut on the 2027 Cadillac Lyriq, and plans to launch a new version of the OnStar mobile app in 2027, replacing OnStar Guardian and the separate apps for each brand. The assistant is developed in-house by GM, with the goal of transforming OnStar from an accident-assistance call center into a connected intelligent platform that can proactively offer suggestions. Vehicle cameras will also be integrated with OnStar, enabling real-t

    Matched fieldsBody

  9. Hugging FaceSelected

    NVIDIA Releases Kumo Relational Relational Foundation Model, Predicts Without Training

    NVIDIA has released Kumo Relational, a pretrained relational foundation model that can make predictions directly on enterprise databases in a single forward pass, without task-specific training, feature engineering, or table flattening. Across 41 tasks on 15 databases—RelBench V1/V2, SAP SALT, and 4DBInfer—it outperforms supervised relational deep learning models and gradient-boosted tree pipelines built with expert feature engineering, achieving an 8% higher MRR than the AutoGluon ensemble on SAP SALT. The model is available through NVIDIA's open-source GPU-native structured-data-models library or NVIDIA NIM, and supports databases with 500B+ rows.

    NVIDIA has released Kumo Relational, a pretrained relational foundation model that can make predictions directly on enterprise databases in a single forward pass, without task-specific training, feature engineering, or table flattening. Across 41 tasks on 15 databases—RelBench V1/V2, SAP SALT, and 4DBInfer—it outperforms supervised relational deep learning models and gradient-boosted tree pipelines built with expert feature engineering, achieving an 8% higher MRR than the AutoGluon ensemble on S

    Matched fieldsBody

  10. Unite.AI

    Three High School Students Launch MyDaye AI to Turn Busy Schedules into Daily Plans

    Three high school students, Avi Rao, Hansen Wilson, and Holt Wilson, launched the conversational planning platform MyDaye AI on October 21 to help students consolidate scattered schedules—coursework, sports, part-time jobs, and more—into actionable daily plans. The platform can extract assignments, exams, and deadlines from uploaded syllabi, supports iCal and ICS calendar subscriptions, and has integrated with Canvas Calendar and Blackbaud Calendar. All student features are currently free, the app is available on iPhone, and an Android version is coming soon.

    Three high school students, Avi Rao, Hansen Wilson, and Holt Wilson, launched the conversational planning platform MyDaye AI on October 21 to help students consolidate scattered schedules—coursework, sports, part-time jobs, and more—into actionable daily plans. The platform can extract assignments, exams, and deadlines from uploaded syllabi, supports iCal and ICS calendar subscriptions, and has integrated with Canvas Calendar and Blackbaud Calendar. All student features are currently free, the a

    Matched fieldsBody

  11. SiliconANGLE

    Era4 ties financial sovereignty to UK AI infrastructure

    Era4, through self-built energy, UK-based AI facilities and its own hardware, argues for giving the UK more control over the AI technology stack and keeping related revenue within the domestic economy. Its Chesterfield facility uses liquid-cooled Nvidia B300 systems supplied by HPE and runs HPE Private Cloud AI; the company also plans to build AI infrastructure on about 20% of a 230-acre former steelworks site in Newport, Wales.

    Matched fieldsBody

  12. Pragmatic Engineer

    Will Larson on the revised rules of engineering management: How AI is changing engineering management and the engineer-to-CTO path

    Imprint CTO Will Larson discussed on a podcast how AI and shifting industry expectations are reshaping engineering management, the career ladder, and the growth path from engineer to CTO, and advised middle managers to return to frontline management and relearn technical skills. Drawing on his experience at Digg, Yahoo, Stripe, Uber, Carta, and Calm, he discussed cases such as the Digg v4 rewrite and how Yahoo's server approval process spawned a "black market," as well as how AI is bringing technical decision-making power back to management.

    Imprint CTO Will Larson discussed on a podcast how AI and shifting industry expectations are reshaping engineering management, the career ladder, and the growth path from engineer to CTO, and advised middle managers to return to frontline management and relearn technical skills. Drawing on his experience at Digg, Yahoo, Stripe, Uber, Carta, and Calm, he discussed cases such as the Digg v4 rewrite and how Yahoo's server approval process spawned a "black market," as well as how AI is bringing tech

    Matched fieldsBody

  13. Hugging Face

    Profiling TorchNeuron (Part 1): System-Level Performance Profiling on AWS Trainium

    AWS has released Part 1 of the TorchNeuron profiling guide, explaining how to use NeuronConfig and NeuronProfiler to collect system-level traces on AWS Trainium and view device timelines through Neuron Explorer. Taking RMSNorm as an example, a naive PyTorch implementation takes a total of 2.355 ms on the Neuron device, while the fused torch.rms_norm requires only 403.3 μs.

    AWS has released Part 1 of the TorchNeuron profiling guide, explaining how to use NeuronConfig and NeuronProfiler to collect system-level traces on AWS Trainium and view device timelines through Neuron Explorer. Taking RMSNorm as an example, a naive PyTorch implementation takes a total of 2.355 ms on the Neuron device, while the fused torch.rms norm requires only 403.3 μs.

    Matched fieldsBody

Wednesday

  1. ElevenLabs Blog

    How to integrate the ElevenLabs text-to-speech API into an app

    ElevenLabs has published a tutorial on how to integrate the text-to-speech API into an app using Python and TypeScript: create an API key, install the ElevenLabs SDK, send text to the TTS endpoint and specify a voice and model, then play the returned audio. The example uses the eleven_v4 model, and the low-latency Eleven Flash v2.5 is also available; the Voice Library offers more than 17,500 voices, and output defaults to mp3 but can be switched to ulaw or pcm.

    How to integrate TTS into your application with ElevenLabs

    ElevenLabs has published a tutorial on how to integrate the text-to-speech API into an app using Python and TypeScript: create an API key, install the ElevenLabs SDK, send text to the TTS endpoint and specify a voice and model, then play the returned audio. The example uses the eleven v4 model, and the low-latency Eleven Flash v2.5 is also available; the Voice Library offers more than 17,500 voices, and output defaults to mp3 but can be switched to ulaw or pcm.

    Matched fieldsBody

  2. Claude Blog

    Anthropic Opens Claude Duet Research Preview: An Agentic App That Can Proactively Execute Tasks

    Anthropic has opened the Claude Duet research preview, an agentic app built on Claude Opus 5.5 that can proactively advance tasks. It is now available on iOS, Android, and claude.ai for Pro and Max users in the United States, who must join a waitlist. Every morning it pushes a cross-app highlights briefing, and it can continuously execute tasks in the background; it requires user approval before sending messages, making payments, signing documents, or deleting, and securities trading and transfers between accounts are not permitted even with approval. Claude Duet can invoke more than 6,000 connectors and plugins in the Claude Marketplace, and it follows the credential-handling approach of Claude Managed Agents, never directly touching users' passwords or login tokens.

    Anthropic has opened the Claude Duet research preview, an agentic app built on Claude Opus 5.5 that can proactively advance tasks. It is now available on iOS, Android, and claude.ai for Pro and Max users in the United States, who must join a waitlist. Every morning it pushes a cross-app highlights briefing, and it can continuously execute tasks in the background; it requires user approval before sending messages, making payments, signing documents, or deleting, and securities trading and transfe

    Matched fieldsBody

  3. Fortune AI

    Gartner says AI infrastructure will need $8.5 trillion in revenue by 2030, with a gap of nearly $4.9 trillion

    Gartner estimates that data center owners will need to generate a cumulative $8.5 trillion in revenue by 2030 to cover announced capital expenditures and financing costs and achieve a 12% return on investment, but over the same period, enterprise and consumer AI revenue attributable to these data centers will not exceed $3.6 trillion, leaving a gap of about $4.9 trillion. Gartner expects AI infrastructure spending to approach $1 trillion in 2026, with another $6 trillion invested from 2027 to 2030. If the current pace continues, more than $3.5 trillion in AI infrastructure spending could face impairment by 2030. Gartner also predicts that by 2030, cost pressures and the lack of differentiated business models will force more than 80% of neocloud providers to cease independent operations.

    Gartner estimates that data center owners will need to generate a cumulative $8.5 trillion in revenue by 2030 to cover announced capital expenditures and financing costs and achieve a 12% return on investment, but over the same period, enterprise and consumer AI revenue attributable to these data centers will not exceed $3.6 trillion, leaving a gap of about $4.9 trillion. Gartner expects AI infrastructure spending to approach $1 trillion in 2026, with another $6 trillion invested from 2027 to 20

    Matched fieldsBody

  4. Unite.AI

    Interview with XBP Global CEO Andrej Jonovic: How Agentic AI Lands in Mission-Critical Processes

    In the interview, XBP Global CEO Andrej Jonovic said the company is applying agentic AI in regulated environments such as healthcare, the public sector, and financial services, using adaptive process orchestration, retaining deterministic rules engines where precision and compliance are required, and introducing replaceable enterprise-grade open-weight models. He cited a global airline fleet maintenance lifecycle project as an example, explaining that maintenance records are vectorized and stored in a private vector database within the customer's private cloud. High-risk decisions are adjudicated by domain experts, and the adjudication results flow back into the system.

    In the interview, XBP Global CEO Andrej Jonovic said the company is applying agentic AI in regulated environments such as healthcare, the public sector, and financial services, using adaptive process orchestration, retaining deterministic rules engines where precision and compliance are required, and introducing replaceable enterprise-grade open-weight models. He cited a global airline fleet maintenance lifecycle project as an example, explaining that maintenance records are vectorized and store

    Matched fieldsBody

  5. SiliconANGLE

    Legal AI company Legora completes $550 million Series E funding at an $8.8 billion valuation

    Stockholm-based legal AI startup Legora announced the completion of $550 million in late-stage funding at a post-money valuation of $8.8 billion, led by Atreides Management, with new investors including Baron Capital, Capital Group, Fidelity, and J.P. Morgan participating, and existing investors Accel, Benchmark, and Bessemer all following on. After this round, the company has raised a cumulative $866 million, with ARR now exceeding $200 million, having grown from $1 million to $100 million in under 18 months. Legora provides legal AI agents and currently serves more than 140,000 legal professionals across 80 markets and over 2,400 law firms and corporate legal teams; the funds will be used for expansion in North America, Europe, and Asia-Pacific, and to increase investment in its agentic legal operating system aOS.

    Stockholm-based legal AI startup Legora announced the completion of $550 million in late-stage funding at a post-money valuation of $8.8 billion, led by Atreides Management, with new investors including Baron Capital, Capital Group, Fidelity, and J.P. Morgan participating, and existing investors Accel, Benchmark, and Bessemer all following on. After this round, the company has raised a cumulative $866 million, with ARR now exceeding $200 million, having grown from $1 million to $100 million in u

    Matched fieldsBody

Tuesday

  1. Fireworks AI

    Fireworks Offers Free Training of Muse Glimmer 30B: Using SFT to Predict Kalshi Market Outcomes

    Fireworks AI announced that Muse Glimmer 30B can be trained with SFT for free until November 30, and released a complete recipe for a prediction experiment using historical Kalshi market data. The fine-tuned Glimmer achieved 58.3% accuracy on unseen topics, 11.2 percentage points higher than Jev's 47.1%; in a historical backtest, a hypothetical $1,000 grew to $1,071 after accounting for simulated fees, while both base Glimmer and Jev lost money. Training used LoRA adapters and a K-way cross-entropy loss, ran through the training data only once, and separately used a calibration set to fit a temperature parameter for each question category.

    Fireworks AI announced that Muse Glimmer 30B can be trained with SFT for free until November 30, and released a complete recipe for a prediction experiment using historical Kalshi market data. The fine-tuned Glimmer achieved 58.3% accuracy on unseen topics, 11.2 percentage points higher than Jev's 47.1%; in a historical backtest, a hypothetical $1,000 grew to $1,071 after accounting for simulated fees, while both base Glimmer and Jev lost money. Training used LoRA adapters and a K-way cross-entr

    Matched fieldsBody

  2. Fireworks AI

    Fireworks Free Weights Club: Training Muse Glimmer to Beat Jev on Predictions

    Fireworks AI launches the Free Weights Club, offering free SFT training for Muse Glimmer 30B until November 30. The fine-tuned tuned Glimmer achieves 58.3% prediction accuracy on unseen topics, 11.2 percentage points higher than Jev's 47.1%; in a historical backtest, after deducting simulated trading fees, a hypothetical $1,000 grew to $1,071, while both Jev and base Glimmer posted losses. In a separate synthetic benchmark, Fireworks' System One serving stack delivered median server throughput 2-3x faster than standard BF16 chat completions.

    Fireworks AI launches the Free Weights Club, offering free SFT training for Muse Glimmer 30B until November 30. The fine-tuned tuned Glimmer achieves 58.3% prediction accuracy on unseen topics, 11.2 percentage points higher than Jev's 47.1%; in a historical backtest, after deducting simulated trading fees, a hypothetical $1,000 grew to $1,071, while both Jev and base Glimmer posted losses. In a separate synthetic benchmark, Fireworks' System One serving stack delivered median server throughput 2

    Matched fieldsBody