Published 11/4/2026
Together Compiler: Continual Compilation for AI inference
Authors
Reyna Abhyankar, Dylan Lim, and Simran Arora
Table of contents
Links in this article
AI inference workloads are dynamic. There are thousands of regimes spanning new models, hardware platforms, customers, use cases, and traffic shapes. It’s no longer scalable to optimize each of these regimes by hand.
- Architectures are highly variable: it’s been ~11 years since the Transformer. We might have thought there would be more consolidation, but none of the top-10 open-source LLMs on OpenRouter use the same architecture!
- Workloads are highly variable: Together serves many trillions of tokens per day across thousands of customers, each with a different traffic shape (batch size, sequence length, MoE expert imbalance, attention sparsity, session duration, domain).
- Hardware is highly variable: H100s, B200s, B300s, NVL72, VR, Groq, and more each require distinct strategies.
Agents are a great fit for this problem, in theory. They can adapt to new workloads and search over the space of possible optimizations without relying on fixed rules or heuristics that plague human experts and traditional machine learning compilers. However, today’s agentic systems are bottlenecked by the speed of experimentation.
We introduce Together Compiler (TKCC), the first truly continual optimization loop that leverages high-throughput agents to optimize to diverse inference workloads
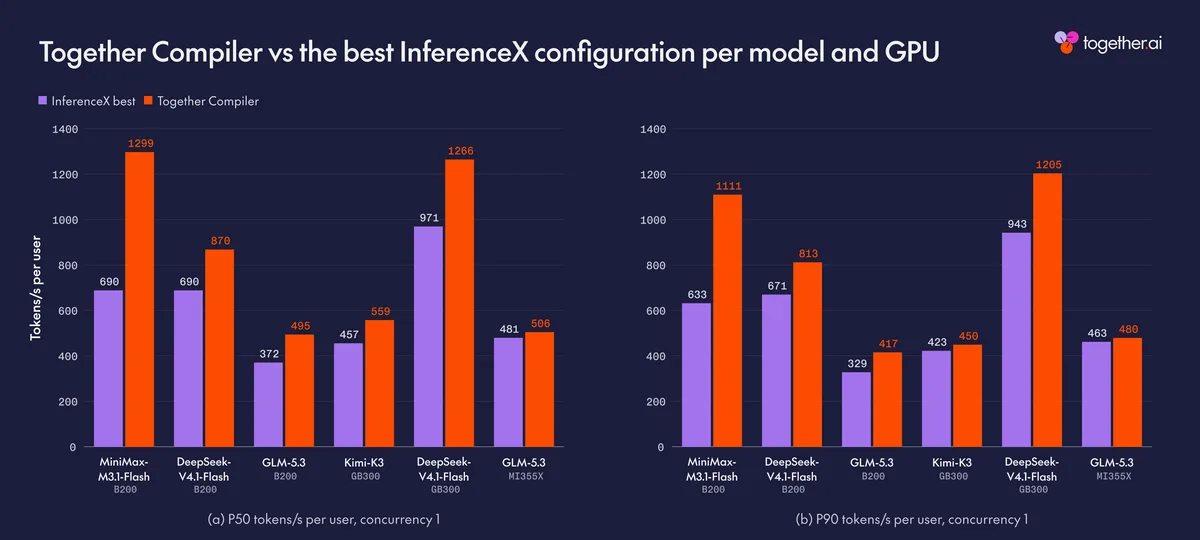
In less than 24 hours, TKCC achieves up to 2.6x higher TPS across frontier open source models (Kimi K3, GLM 5.3, MiniMax M3.1-Flash, DeepSeek v4.1-Flash), sets the state-of-the-art on SemiAnalysis’ InferenceX benchmark for low-latency with 1111 TPS on MiniMax M3.1-Flash and 1205 TPS on DeepSeek v4.1-Flash, and outperforms available open-source megakernels by 1.7x on their workhorse Llama 1B batch size 1 setting. Furthermore, TKCC generalizes to domains beyond language model inference (weather modeling, PDE, time-series, and biology). This performance boost is enabled by TKCC’s 252x higher experiment throughput compared to baseline agentic performance optimization systems. Together Compiler is serving trillions of tokens today.
Traffic is continually changing
As an inference provider, we see a variety of user behaviors based on regional patterns, new model releases, and burstiness.
- Regional patterns: Users across the world may have different model preferences. We’ve observed traffic for one country’s working hours to have 1.4x longer prompts than another country (97k vs 70k).
- Model releases: Users take time to figure out how to integrate new model releases into their workflows. First, they tend to opt for chat-based interaction and evaluation. This is swiftly followed by an 80% increase in prompt length just two weeks after the release as users shift towards agentic workloads.
- Burstiness: Customers may send bursts of requests at random times throughout the day. Prompt lengths can suddenly double and cache hit rates can fall if not handled carefully.
It’s clear that we must adapt to ever-changing user behavior with specialized optimizations for each new deployment.
Overview of Together Compiler
TKCC takes as input the traffic shape, model, and hardware. TKCC uses agents to generate a series of optimizations for an inference engine.
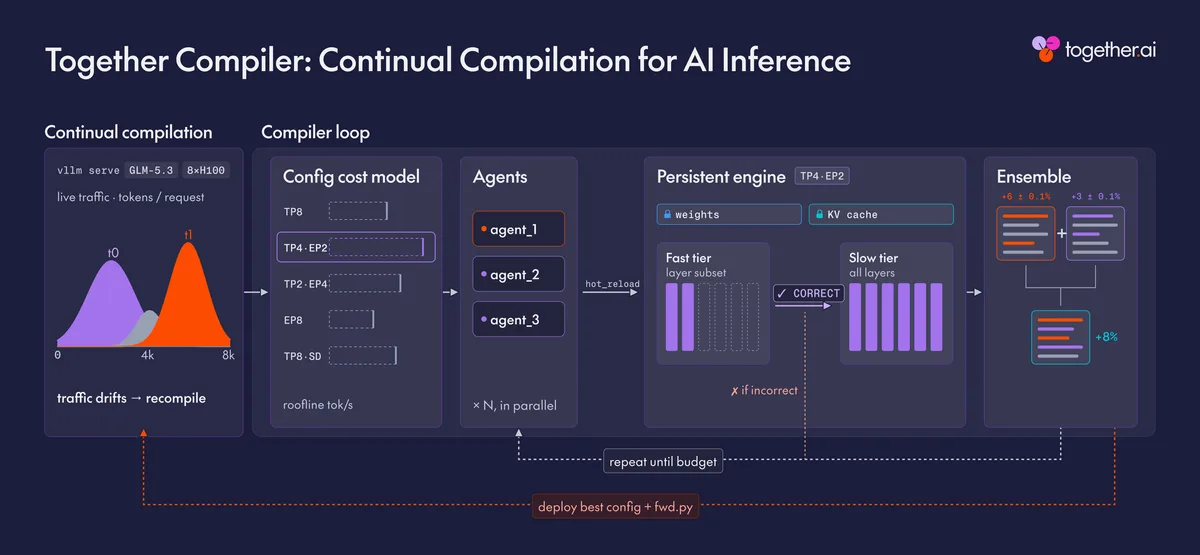
The core insights in TKCC are as follows:
1. TKCC maximizes experimentation throughput and minimizes GPU idle time during agent optimization
Most existing agentic inference optimization systems require agents to launch and teardown engines like VLLM, SGLang, or TRT-LLM to test each new experiment. However, engine start times are tens of minutes, significantly impeding experimentation throughput (see table below). Instead, TKCC proposes a new paradigm of “persistent engines” where the engine starts up once and can hot-reload any candidate forward pass, without any restarts. To ensure that the persistent engines constantly have new optimizations to test, TKCC spawns multiple agents that continually generate ideas and communicate via a message board to parallelize their efforts.
| Phase | Status Quo (s) | Together Compiler (s) |
|---|---|---|
| Process + worker init. | 93 | – |
| Weight loading | 50 | – |
| KV-cache sizing | 21 | – |
| JIT kernel warm-up | 93 | – |
| Autotuning | 193 | – |
| API server ready | 10 | – |
| RPC call + Together Compiler setup | – | 1.7 |
| CUDA-graph capture | 7 | 7.3 |
| Total time to serving | 467 | 9.0 |
Table 1: Engine startup is expensive
2. TKCC balances the tradeoff between measurement throughput and measurement fidelity
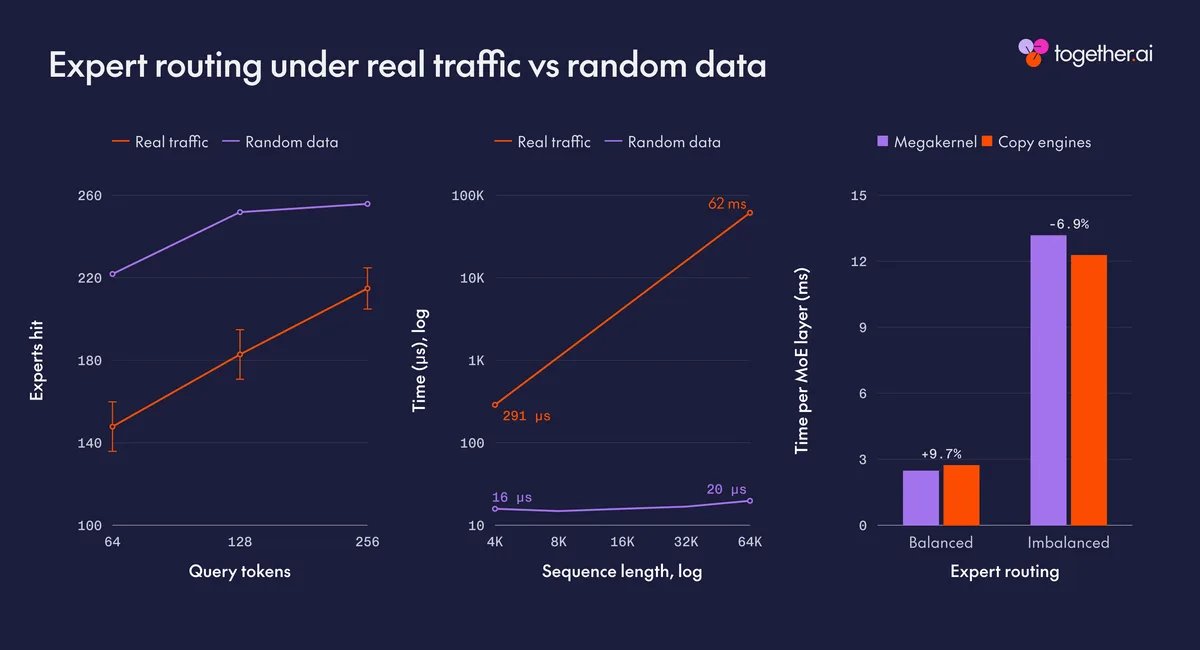
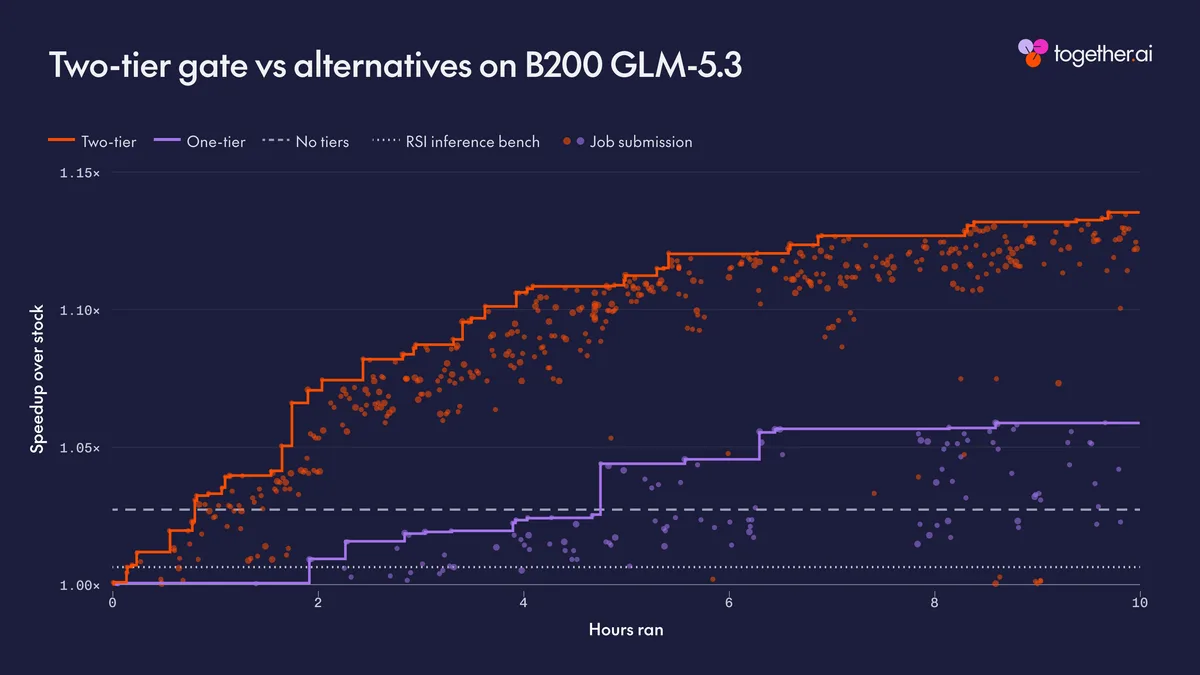
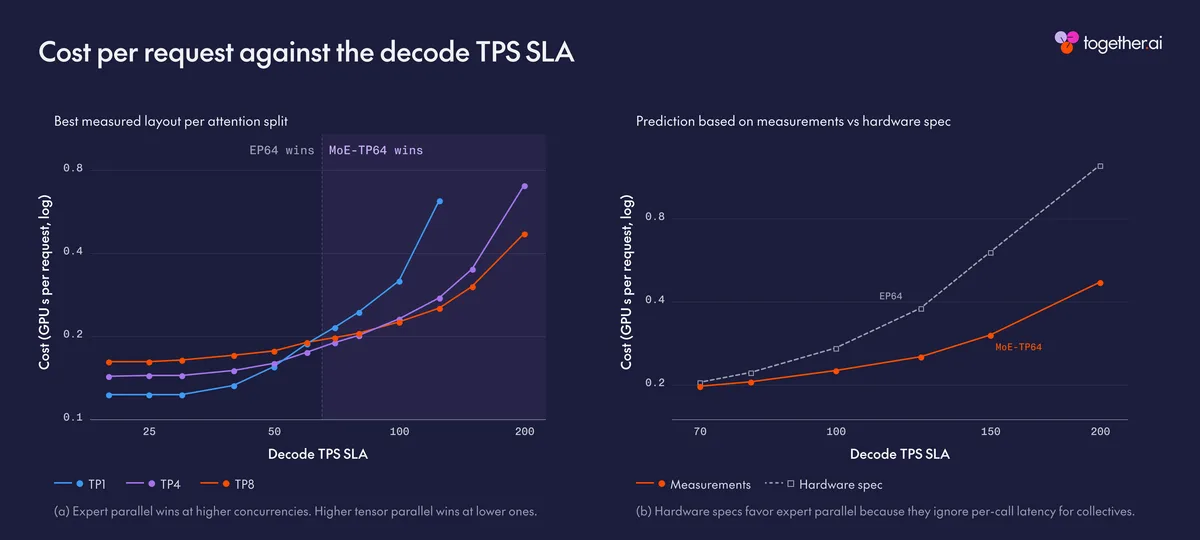
Existing agent optimization systems either iteratively relaunch the inference engine, suffering from low experiment throughput, or optimize standalone kernels in isolation, outside of the inference engine, suffering from poor measurement fidelity. Systems that optimize standalone kernels often evaluate them using random input data. However, with modern architectures using data-dependent primitives like MoE and sparse-k attention, input data distributions have a direct effect on which optimization strategies may win (see figure below). High-fidelity inputs are important for effective optimization. TKCC uses a tier of persistent engines to balance the throughput-fidelity tradeoff: “fast engines” load a few layers and are ideal for rapid iteration and low-variance timings, while “slower engines” load many layers and are ideal for testing whether optimizations hold-up on real data distributions.
3. TKCC utilizes a custom cost model to select parallelism strategies (e.g., TP, EP, DCP, etc.) for agents to achieve the highest performance
Existing systems have sophisticated methods for selecting inference configurations under SLA requirements. However, selecting the ideal configuration faces the same throughput-fidelity tradeoff: it is intractable to measure each parallelism configuration, especially because software implementations are immature. A naive approach is to select a parallelism strategy based on raw hardware specs or micro-benchmarks. However, this insufficiently captures data dependent traffic properties like MoE expert imbalance or uneven prompt length distributions. We designed a cost model that uses a tiered measurement strategy involving hardware specs, microbenchmarks, and measured forward passes to construct a high-fidelity representation while rapidly pruning the configuration search space to support continual traffic drift.
Results
We evaluate TKCC against three different types of baselines: Hand-tuned megakernels, InferenceX engine configurations, and popular AI codebases from diverse domains like weather modeling, PDE, time series and biology models.
MegaKernel workloads
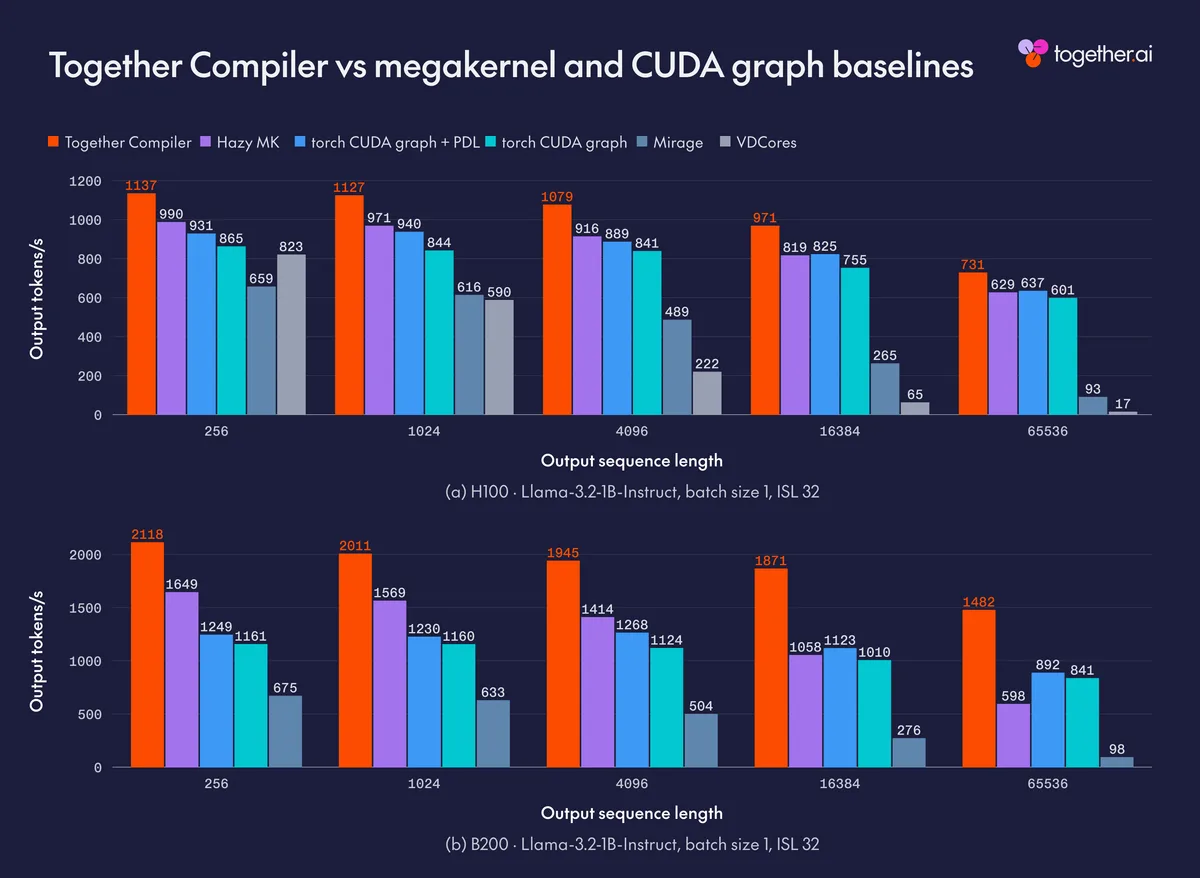
We start by evaluating the canonical MegaKernel workload: Llama 1B at batch size 1. This model architecture has been well-optimized by both human experts and traditional machine learning compilers. TKCC generates 1.7x higher TPS and continues to perform as sequence length increases.
InferenceX AgentX workloads
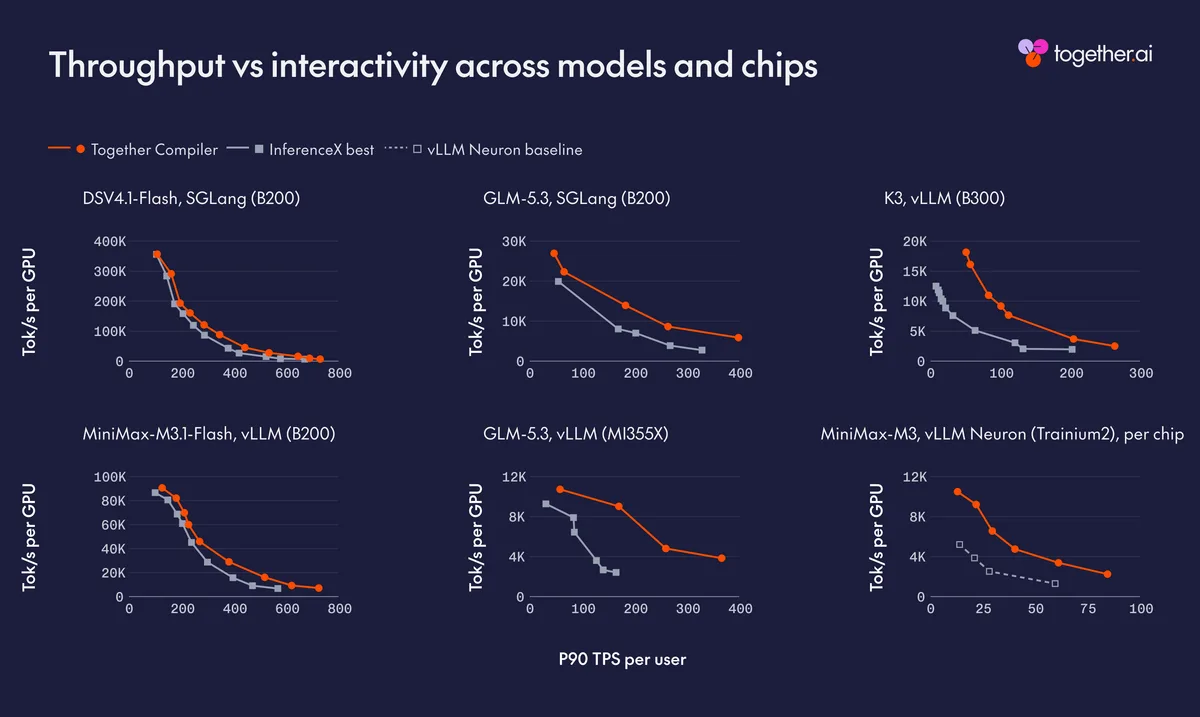
We evaluate TKCC on the AgentX benchmark from SemiAnalysis. We start from the best-reported open source engine configurations for frontier models across inference engines and hardware platforms. TKCC consistently sets the performance frontier across all settings, outperforming highly-optimized baselines by up to 2.6x higher TPS.1
We also evaluate specifically on the low-latency use case at batch size 1 and set the state-of-the-art performance with 1111 TPS on MiniMax M3.1-Flash and 1205 TPS on DeepSeek v4.1-Flash. For these results, we use our cost model to select the parallelism configuration instead of using the InferenceX configuration. We observe speedups with this approach.
Across AI workloads
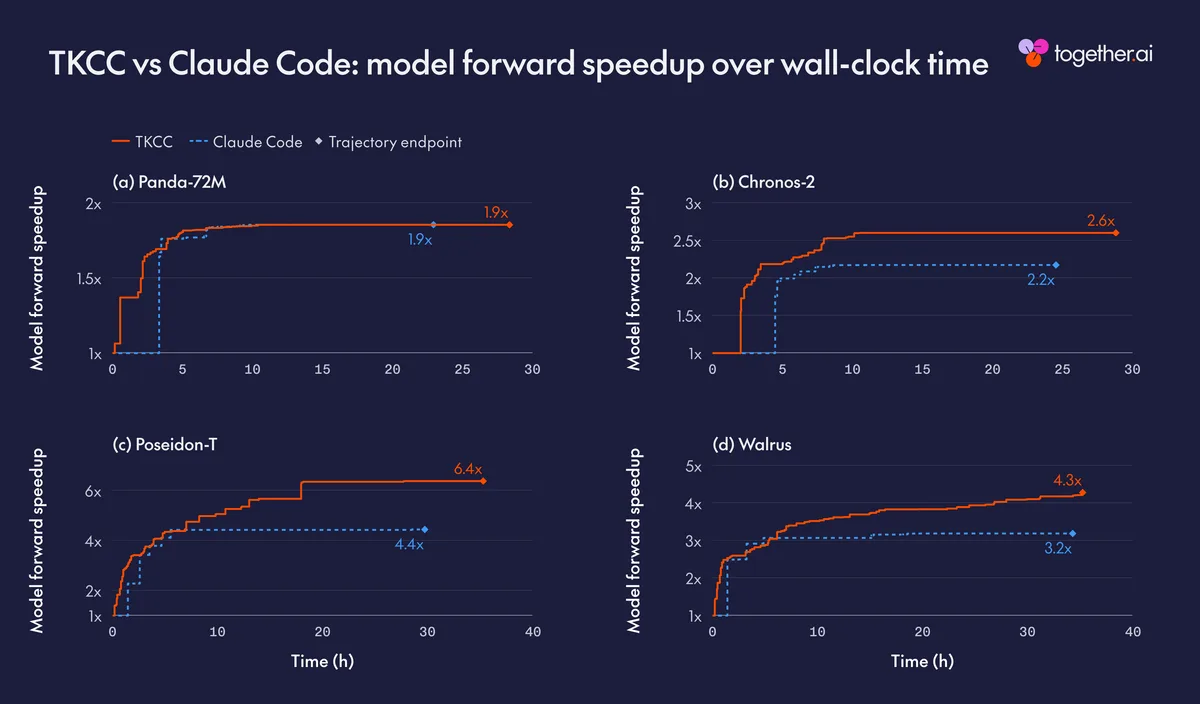
We select popular open-source code bases across weather modeling, PDE, time-series, and biology. We show the geometric mean speedups of TKCC over simply using Claude Code with the /goal command, illustrating that the principles of TKCC generalize across domains. We have been using TKCC as a general purpose AI compiler beyond LLM inference.
Polymorphic AI systems is the next frontier
For Together AI, the most exciting systems challenge has been Polymorphic Inference. Inference is no longer about optimizing for a single traffic shape for a single hardware platform and model, traffic is constantly and dynamically evolving, much like financial markets, and that dynamism has opened up a whole host of new research questions.
Check out our paper to learn more.
And if these frontiers of AI systems excite you, feel free to reach out to us!
1 Trainium2 was run on a synthetic multi-turn dataset (70k ISL, 3.5k new ISL 95% cached, 700 OSL) instead of AgentX since our implementation does not yet support higher concurrencies on the limited HBM capacity.