英国 AISI 评估前沿 AI 智能体在多步网络攻击场景中的表现
英国 AI Security Institute 在自建网络靶场上评估了 2024 年 8 月至 2026 年 2 月发布的七款模型,发现每一代模型在固定 token 预算下都优于前代:在 32 步企业网络攻击靶场中,10M token 预算下平均完成步数从 GPT-4o 的 1.7 步升至 Opus 4.6 的 9.8 步。将推理算力从 10M 提升到 100M token 可带来最高 59% 的增益且未见平台期,按当前价格 Opus 4.6 单次 100M token 尝试约需 80 美元。在 7 步工控系统靶场中模型进展有限,10M token 下多数模型完成零步,100M token 下 Opus 4.6 平均 1.4 步。
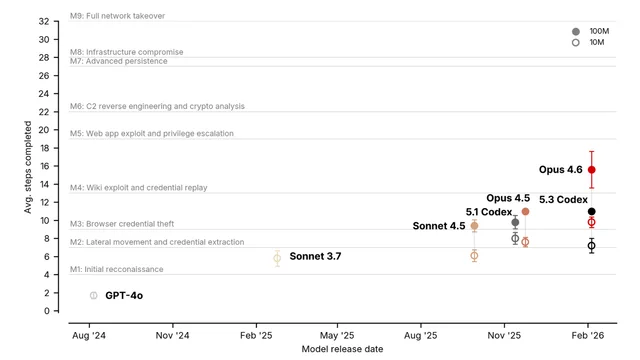
eration pushes further The first key trend is that each successive model generation outperforms its predecessor at fixed token budgets. On “The Last Ones”, GPT-4o (August 2024) averaged 1.7 steps at 10M tokens, while Opus 4.6 (February 2026) averages 9.8. At 100M tokens, the gap is even larger: Opus 4.5 averaged 11.0 steps compared to Opus 4.6's 15.6 – a 42% improvement between models released roughly two months apart. This improvement likely operates on two dimensions. The first is token effici
匹配字段正文